🤖 AI 资讯

每日 05:00 更新 · 11-08 · 主站 liuch.name ↗
全部标签 →
筛选标签:向量数据库 · 返回个性化推荐 · 清空筛选

Chromagraph Camera is exactly the camera app I’ve been looking for on iPhone

9to5Mac

Last week, movie director Rian Johnson announced a surprise new camera app for iPhone that reimagines what a smartphone photo should look like. Many people would agree that Apple’s iPhone photos are a tad bit overprocessed.

iPhone 18 Pro and iPhone Duo introduced a new film texture option, but in my view, it’s a bit too exaggerated. Chromagraph Camera, on the other hand, feels pretty perfect.

more…
2026-11-07 22:30:00 · AI应用,搜索RAG,向量数据库,招聘HR

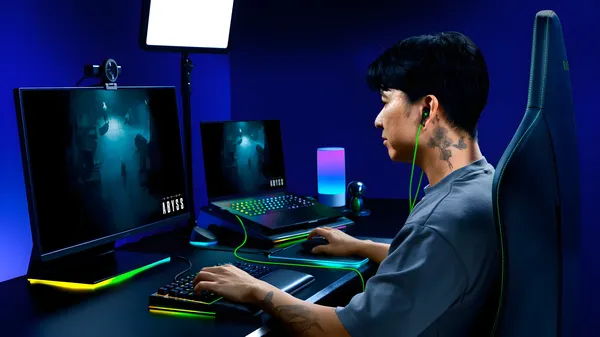
雷蛇发布Hammerhead V3 Chroma有线耳机 USB-C接口搭配RGB灯效回归

CnBeta

在无线耳机主导市场多年之后,有线耳机正迎来新的复兴趋势。继Bose等品牌重新推出有线产品后,雷蛇也正式加入这一行列,发布全新的Hammerhead V3 Chroma有线游戏耳机,希望为移动游戏玩家和PC用户提供低延迟、高兼容性的音频体验。

阅读全文
· 语音音频,游戏,向量数据库,招聘HR,模型发布

SpaceX Teams Up With Qualcomm to Build a Nationwide 5G Network

Hacker Noon

The company that put thousands of routers in orbit is now coming down to earth: steel towers, rooftop leases, zoning boards and all. Here's what's planned, how 5G works, and why the hard part isn't the rockets.


Back in February 2020, I wrote a parody called "SpaceX Starlink Master Plan", in the voice of a certain CEO. It copied the "trickle-down" structure of Tesla's master plan, in four steps:

  1. Build a bulky, expensive terminal for professionals.
  2. Use that money to build a rooftop consumer terminal.
  3. Use that money to build "a low cost and high volume mobile phone."
  4. Build an interstellar communication system for Mars and beyond.

Fake-Elon also bragged that Starlink could beat 5G because the carriers "need to deploy a lot more cell sites," while Starlink doesn't "need to pay site rentals and backhaul." For the astronomers, he promised to paint every satellite chroma green "so they can be easily removed in photoshop."

Six and a half years later, steps 1 and 2 happened, if not quite in that order (consumers came first): millions of pizza-box dishes, on roofs and on boats. Step 3 took a turn I didn't see coming. SpaceX never built a StarPhone; it made every phone a StarPhone, beaming signals straight to the one already in your pocket. And now comes the twist the parody never imagined: SpaceX is about to pay site rentals. Lots of them.

For about 30 years, American mobile service has worked like this: three giant companies own the networks (the airwaves, the radios bolted to the towers, and your monthly bill), and everyone else rents from them. Not even the giants own most of the towers anymore. Over a decade ago they sold or long-term leased them to landlords like American Tower and Crown Castle, and now pay rent like everybody else. Upstarts have tried to break in. Most have ended up as footnotes, or as a Boost Mobile ad.

Now a rocket company wants a go. On November 4, 2026, SpaceX and Qualcomm announced a multi-year deal under which Qualcomm supplies the core radio silicon and software for a nationwide terrestrial 5G network under the Starlink Mobile brand. SpaceX already has phone service coming down from orbit. This time the plan is phone service coming across, from tens of thousands of ordinary cell sites. Construction starts in 2027; when you can actually get service from them, nobody has said.

So: what exactly was announced, how does the technology work, and how many billions of dollars and zoning hearings stand between SpaceX and your SIM card?


1. The Announcement: Starlink Gets a Ground Game

What SpaceX said

The short version:

  • Qualcomm supplies the guts of the radio access network (RAN): the radio-unit and baseband platforms (chips plus reference designs) and the commercial-grade Layer 1 software, all from its Dragonwing cellular infrastructure line. SpaceX builds the actual boxes around them. Neither company disclosed the dollar value.
  • Scale: "Tens of thousands of sites," according to the announcement, and Qualcomm executive vice president Durga Malladi expects the rollout to "ramp up pretty rapidly." Unconfirmed press reports say SpaceX is talking to tower owners about access to as many as 80,000 sites; no tower partners have been named.
  • Timing: Tower deployment starts in 2027. No launch date for terrestrial service has been given. Separately, SpaceX is targeting early 2028 to switch on its next-generation "full 5G quality" satellite service.
  • Ambition: a genuine fourth national carrier that owns its own network, not just another reseller.

Malladi called it "huge," and agreed with Light Reading that it's Qualcomm's biggest network deal since 3G. For a company best known for the modem in your phone, that's a big deal.

Wait, what's Dragonwing?

Dragonwing, launched in February 2025, is Qualcomm's brand for its industrial, networking and infrastructure silicon, the chips that go into things other than phones.

The Dragonwing toolbox (the deal announcement names the QRU100 and QDU100 platforms specifically):

Component

What it is

Where it lives

QRU100

Radio unit platform supporting 64T64R massive MIMO (64 transmit, 64 receive paths)

Up on the tower, behind the antenna

QDU100 / X100

Distributed-unit Layer 1 baseband platform; its card form, the X100, is an inline PCIe accelerator (35 W max) that slots into ordinary Dell or HPE servers

In a cabinet at the base of the tower or a nearby edge site

QTR transceivers

The RF transceiver chips that turn bits into radio waves and back

Inside the radio

AI features + RAN Automation Suite

AI beam prediction, uplink tuning and factory calibration built into the platforms, plus a separate network-management suite

Everywhere, apparently, because it's 2026

Qualcomm's Dragonwing RAN building blocks, from tower radio to server card

This gear has been deployed before, though not at this scale. Vietnam's Viettel runs Qualcomm-based radios across "a few thousand sites," and Qualcomm chips have shown up inside radios from NEC and Mavenir (which has since quit making radios). SpaceX is about to become its first customer at continental scale.

Qualcomm handles the physical layer, the hard real-time signal math. SpaceX is expected to write its own Layer 2, Layer 3 and core network software on top. As Malladi put it, "They still have to do the Layer 2, the Layer 3, and so on." That's very SpaceX: buy the chips and own the software, the same way it treats rocket engines and satellite buses.

The airwaves SpaceX has lined up

Radios are useless without airwaves, and in about 13 months SpaceX has agreed to spend roughly $28 billion on spectrum (not all of it paid yet):

  • EchoStar (September 2025): about 50 MHz of 2 GHz AWS-4 and H-Block spectrum for about $17 billion (half cash, half SpaceX stock), plus roughly $2 billion of EchoStar's debt interest. In November 2025 SpaceX added a 15 MHz uplink-only AWS-3 slice (1695–1710 MHz) for about $2.6 billion in stock, for a total of roughly $19.6 billion. The FCC approved the deal in May 2026 and allowed the spectrum to be used from space, on the ground, or both, which SpaceX CFO Bret Johnsen calls crucial. The final closing, when SpaceX actually pays, is expected around late 2027.
  • Grain Management (October 2026): up to 14 MHz of paired, nationwide 800 MHz low-band spectrum for a reported $8 billion (terms undisclosed; FCC approval pending). These airwaves started life at Nextel, passed to Sprint and then T-Mobile, which sold them to private investor Grain for about $3.6 billion ($2.9 billion in cash plus Grain's 600 MHz licenses) in a deal that closed in August 2026. Grain flipped them to SpaceX two months later for more than double that, which suggests either very
2026-11-06 19:00:05 · AI应用,搜索RAG,强化学习,向量数据库,招聘HR,榜单评测,开发者生态

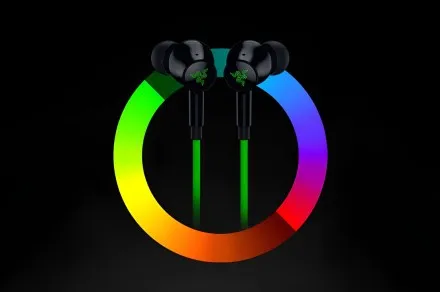
Razer’s new $80 earbuds have ANC and RGB, and you don’t need to charge them
Digital TrendsRazer's new Hammerhead V3 Chroma wired gaming earbuds combine active noise cancellation, customizable RGB lighting, dual drivers, and a clever right-angle USB-C connector for just $79.99.
2026-11-06T06:47:08-08:00 · 向量数据库,招聘HR

2026 开源行业解决方案创新赛「开源智能硬件解决方案赛道」决赛名单公布

开源中国第四届开放原子大赛 · 2026 开源行业解决方案创新赛「开源智能硬件解决方案赛道」决赛入围名单今日公布,以下 10 支队伍成功晋级,将于 11 月 13 日在北京亦庄通明湖会展中心参加总决赛。 现将入围名单按报名时间顺序公示如下: 项目名称 负责人 代码仓库链接 Blockless 科创教育 AI 嵌入式软件开发平台 辛瑞莉 https:...
· 开源,教育学习,向量数据库

神舟二十四号载人飞行任务标识发布,首次中外航天员联合飞行

IT之家

IT之家 11 月 7 日消息,据央视新闻报道,今天,神舟二十四号载人飞行任务标识正式发布。

据介绍,标识以地球为视觉背景,主体显示神舟二十四号载人飞船与空间站交会对接场景,上下双色半圆构建对称格局,上方湛蓝色背景半圆环象征无垠苍穹与航天梦想,下方红色半圆环象征建设航天强国的炽热情怀与坚定信念。下方半圆环内嵌入中国古代龙纹玉璜造型,寓意将传统文化与现代科技深度融合,展现航天人传承创新、逐梦星海的坚定步伐。地球两侧点缀繁星,体现宇宙深邃感。艺术化设计的“2026”与“SZ-24”对称排布,标明任务年份与代号。

据IT之家此前报道,神舟二十四号载人飞行任务将有 1 名巴基斯坦航天员以载荷专家身份参加,在完成短期在轨飞行后,随神舟二十三号载人飞船返回。这是中国载人航天工程历史上首次中外航天员联合飞行,中国空间站将迎来首位外籍航天员到访。

2026-11-07 02:07:04 · 设计创意,向量数据库,模型发布
AI 资讯

DialFork: a benchmark for procedural hallucination in conversational agents [R]

Reddit r/MachineLearning

Hi all, author here (Idiap Research Institute, joint work with Logitech). We recently released DialFork and thought it might interest people here. It's a benchmark for a failure mode of LLM agents that is easy to miss: every turn is fluent and factual, the tool calls are correct, yet the agent stops following the procedure it was given. For example, asked for the weather, it fetches the forecast (correct tool call) but never tells you, and starts asking you to rate its service instead.

Most steps of a conversational procedure aren't tool calls but things the agent has to say: asking, confirming, telling the result. When an agent drifts from these steps, we call it procedural hallucination: a third axis, alongside factual accuracy and correct tool use, and one that has been largely overlooked. To our knowledge, DialFork is the first benchmark aimed at measuring this axis: what the agent has to say, and in what order.

How it's built: we simulate dialogues where an agent follows its workflow (24 tasks, 12 domains), then fork them: we replay each one and, at a chosen turn, give the agent an instruction that makes it drift, in different, complementary ways. That gives over 36k dialogues where we know where each drift starts and how far it goes, checked with 30 human annotators and an LLM judge calibrated on them.

Three tasks, from the turn to the whole set. Because we know where each drift starts, and that an earlier drift goes further, we define three tasks that measure procedural hallucination at different levels:

  • The turn (Task 3). Given a dialogue, either whole or turn by turn as it unfolds (streaming), find the turn where the drift starts, or say there is none. Useful as a live guardrail.
  • The dialogue (Task 2). Given a correct dialogue and its hallucinated versions, measure how far each one drifts from it; the earlier a version drifts, the larger its distance should be. A dialogue and its own hallucinated versions talk about the same thing; what sets them apart is how they unfold. Today, comparing dialogues means comparing their content, with embeddings and semantic similarity. This task opens a new dimension, procedural distance. Useful for retrieving or clustering conversations by how they went, not just by what they're about.
  • The set (Task 1). Given a set of correct dialogues and a set of hallucinated ones, output a single procedural distance between the two sets as a whole, comparing them as distributions rather than matching dialogues one to one. Useful for monitoring agents, e.g. whether they drift after a model upgrade, or whether a user simulator's dialogues unfold like real ones.

Open problems, and a leaderboard to track them. In the paper, we report first results on all three tasks, from embedding-based distances to streaming detectors and zero-shot LLMs. They leave plenty of room. To track progress, each task has its own track on a public leaderboard on Hugging Face; adding your method takes a single CSV file of predictions.

Everything is open (data, code, every prediction from the paper, and the human judgments), and we hope it's a useful starting point for the community:

Happy to answer questions, and feedback (including critical) is very welcome.

submitted by /u/sergbur
[link] [comments]
2026-11-05 10:44:15 · 大模型,算力芯片,AI应用,开源,Google,Agent智能体,扩散模型,模型评测,向量数据库,模型安全对齐,招聘HR,榜单评测,论文

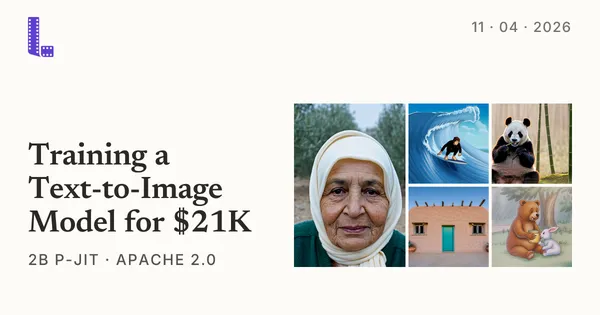
Show HN: A decent text-to-image model trained for ~$20K (Apache 2.0 Weights)

Hacker NewsComments
· 大模型,算力芯片,AI应用,自动驾驶,开源,Google,Anthropic,阿里巴巴,搜索RAG,Transformer,扩散模型,强化学习,微调蒸馏,预训练,向量数据库,提示工程,长上下文,招聘HR,论文,开发者生态
AI 资讯

Genome-Factory: A Library for Tuning, Deploying, and Interpreting Genomic Foundation Models

arXiv cs.LGarXiv:2509.12266v3 Announce Type: replace-cross Abstract: We introduce Genome-Factory, the first integrated Python library for tuning, deploying, and interpreting genomic foundation models. Our core contribution is to simplify and unify the workflow for genomic model development: data collection, model tuning, inference, benchmarking, and interpretability. For data collection, Genome-Factory offers an automated pipeline to download genomic sequences and preprocess them. For model tuning, Genome-Factory supports both full and parameter-efficient fine-tuning across diverse genomic models. For inference, Genome-Factory enables both embedding extraction and DNA sequence generation. For benchmarking, we include two existing benchmarks and provide a flexible interface to incorporate additional benchmarks. For interpretability, Genome-Factory introduces an open-source biological interpreter based on a sparse auto-encoder. We validate the utility of Genome-Factory across three dimensions: (i) Compatibility with diverse models and fine-tuning methods; (ii) Benchmarking downstream performance using two open-source benchmarks; (iii) Biological interpretation of learned representations with DNABERT-2. These results highlight its practical value for real-world genomic analysis. GitHub: https://github.com/WeiminWu2000/Genome_Factory.
2026-11-06 05:00:00 · 开源,扩散模型,强化学习,微调蒸馏,模型评测,向量数据库,招聘HR,论文
AI 资讯

FRESHPart: Feedback-Reshaped Spectral Embedding for Hypergraph Partitioning

arXiv cs.LGarXiv:2611.05729v2 Announce Type: replace Abstract: With scalable Laplacian solvers now available, the next frontier is to exploit them more effectively for high-quality hypergraph partitioning. In this work, we revisit spectral hypergraph partitioning from the perspective of spectral embedding geometry. Through a systematic analysis of circuit hypergraphs and controlled synthetic (hyper)graphs, we identify a ray-like embedding structure that helps explain the effectiveness of projection-based partitioning. We further show that the geometry of spectral embeddings can be systematically influenced through Laplacian design and hyperedge reweighting. Guided by these insights, we propose FRESHPart, a feedback-reshaped spectral partitioning framework that refines the spectral embedding through Geometry Feedback and Search Feedback, producing embeddings that are better aligned with projection-based partitioning. On the Titan23 benchmark, FRESHPart achieves average cut reductions over hMETIS of 13.09% at $\epsilon=2\%$ and 25.21% at $\epsilon=20\%$, surpassing the strongest previously reported results (12.16% and 22.53%, respectively), while completing every benchmark in under 120 s on a single GPU.
2026-11-06 05:00:00 · 算力芯片,AI应用,搜索RAG,模型评测,向量数据库,招聘HR,论文
AI 资讯

Graph Metanetworks for Transformer Based Language Models

arXiv cs.LGarXiv:2610.18471v2 Announce Type: replace Abstract: Weight-space learning treats the weights of neural networks as data, processed by other models called metanetworks. A key challenge is that different weights can realize the same function, related by a group of symmetries the metanetwork should respect. While symmetry-aware metanetworks for simple architectures such as MLPs are well developed, a comprehensive treatment of transformers, and in particular transformer-based language models, is still missing. Importantly, their weight space has a richer symmetry group: beyond neuron permutations, attention introduces continuous general-linear symmetries of the attention matrices and permutations of entire heads. Existing methods for transformer weights either capture only part of these symmetries or are restricted to a single, fixed architecture, and none accounts for language-model-specific components such as the token embeddings. Building on graph metanetworks, we propose a graph-based approach that is both symmetry-aware and applicable across depths and widths. We formalize a weight-space symmetry group of complete decoder-only language models and provide a graph construction that is invariant to it. We further introduce two new transformer-population datasets with novel tasks, such as training-corpus prediction and fine-tuning detection, on which our approach notably outperforms existing baselines.
2026-11-06 05:00:00 · Meta,Transformer,微调蒸馏,向量数据库,论文
AI 资讯

TabPFN beyond Tabular Data: Calibration and Accuracy on Multimodal Embeddings

arXiv cs.LGarXiv:2607.11007v4 Announce Type: replace Abstract: Few-shot multimodal classification commonly attaches a lightweight head, such as $k$-nearest neighbors, logistic regression, or a linear SVM, to a frozen pretrained encoder. Although computationally efficient, these heads can produce poorly calibrated confidence scores. We ask whether TabPFN can provide reliable confidence estimates on multimodal embeddings without sacrificing predictive accuracy, and under what conditions. We systematically evaluate TabPFN as a zero-gradient head for frozen image, text, and audio encoders. Across 22{,}820 evaluation episodes spanning 14 datasets, 11 encoders, and three modalities, TabPFN achieves the best mean rank among nine classification heads on both negative log-likelihood (NLL) and expected calibration error (ECE). At a representative setting, it reduces NLL by 48--62\% and ECE by 2.1--5.3$\times$ relative to the average of eight baselines while matching or exceeding their average accuracy. This calibration benefit transfers broadly, whereas the accuracy advantage is conditional: it concentrates at moderate-to-high shot counts and low-to-moderate feature dimensions ($k \ge 50$, $d \le 32$), and diminishes when labeled data are scarce, feature dimensions are high, or competing methods approach ceiling accuracy. After backbone adaptation, replacing the trained linear head with TabPFN improves calibration while preserving competitive accuracy, showing that representation adaptation and reliable head choice are complementary. Together, these results identify when TabPFN can serve as a training-free head for calibration-sensitive multimodal classification. To support transparency and reproducibility, we publicly release the source code, experiment configurations, and evaluation scripts in our GitHub repository: https://github.com/Jingxiang-Zhang/tabpfn-multimodal-embeddings.
2026-11-06 05:00:00 · AI应用,开源,多模态,搜索RAG,扩散模型,强化学习,预训练,向量数据库,提示工程,招聘HR,论文
AI 资讯

Hyperbolic Graph Neural Networks Under the Microscope: The Role of Geometry-Task Alignment

arXiv cs.LGarXiv:2602.01828v3 Announce Type: replace Abstract: Many complex networks exhibit hierarchical, tree-like structures, making hyperbolic space a natural candidate wherein to learn representations of them. Based on this observation, Hyperbolic Graph Neural Networks (HGNNs) have been widely adopted as a principled choice for representation learning on tree-like graphs. In this work, we question this paradigm by proposing the additional condition of geometry--task alignment, i.e., whether the metric structure of the target follows that of the input graph. We start by empirically showing that HGNNs can recover low-distortion representations when supervision explicitly rewards metric preservation and proceed by theoretically analyzing a controlled regression setting in which a linear readout benefits from representations whose geometry is aligned with the target metric. Finally, by relying on both predictive performance and embedding distortion, we further show that HGNNs gain an advantage on link prediction, a naturally geometry-aligned task, whereas this advantage largely disappears on standard node classification benchmarks. Overall, our findings shift the focus from only asking "Is the graph hyperbolic?" to also questioning "Is the task aligned with hyperbolic geometry?", showing that HGNNs consistently outperform Euclidean models under such alignment, while their advantage vanishes otherwise.
2026-11-06 05:00:00 · 扩散模型,模型评测,向量数据库,模型安全对齐,端侧AI,图神经网络,论文
AI 资讯

Transformer-Based Trajectory Prescription for sEMG-Optimizing Robot-Mediated Rehabilitation

arXiv cs.LGarXiv:2611.08295v1 Announce Type: cross Abstract: Robot-mediated rehabilitation has the potential to deliver high-intensity, individualized therapy, but existing systems (which have not consistently improved outcomes) typically prescribe kinematic trajectories rather than explicitly targeting the neuromotor activations thought to support recovery. To address this gap, and ultimately enable activation-optimizing rehabilitation robot behavior, we present a personalizable transformer-based model mapping individuals' muscle activations (as measured via surface electromyography) to prescribed contact force trajectories when interacting with an end-effector rehabilitation robot. The model uses a transformer encoder-decoder leveraging rotary positional embeddings (RoPE) to generate a latent representation of trajectory-relevant and user-specific neuromotor factors, and augments trajectory prediction with flow matching to produce a distribution over plausible prescriptions biased toward the training distribution. Using data from 16 healthy participants completing 15 isometric trajectory tracking tasks, we evaluate generalization across held-out tasks and users, as well as the feasibility of user-specific fine-tuning within a therapy-session timescale. The model achieves mean trajectory prediction errors of <8% on held out tasks and users, with effectively instantaneous deterministic inference and sub-second sampling of trajectory distributions. An initial test using the model during live rehabilitation tasks demonstrates that, on average, participants reach the target neuromotor activations with just 15% error accumulated throughout the task. These results provide a proof of concept for data-driven, activation-targeted trajectory prescription in robot-mediated rehabilitation and establish a foundation for future validation in clinical populations. Data and code have been open-sourced as part of the OpenRobotRehab project on SimTK.
2026-11-06 05:00:00 · AI应用,具身智能,搜索RAG,Transformer,扩散模型,强化学习,微调蒸馏,向量数据库,招聘HR,论文
AI 资讯

User Embeddings are Superpositions of Interpretable Behavioral Modes

arXiv cs.LGarXiv:2611.08487v1 Announce Type: new Abstract: User embeddings are central components of modern recommendation, personalization, and behavioral modeling systems. Though these embeddings can compactly encode rich behavioral information, they are inherently dense and opaque, limiting interpretability. To address this gap, we argue that user embeddings can be understood as sparse superpositions of interpretable behavioral modes. This structure is directly predicted by generative models of user behavior for linear embeddings and extends approximately to deep-learning representations by the superposition hypothesis. Superimposed modes can naturally be recovered by sparse dictionary learning methods, such as sparse autoencoders (SAEs), and recovered modes can be automatically named and queried in natural language. We validate mode recovery against known ground truth on synthetic data, where SAEs recover modes better than classical sparse baselines, including on transformer-encoded embeddings. We then apply the method to classical and transformer-based user embeddings from two real-world datasets. We also show how the corresponding natural-language labels enable zero-shot audience retrieval and characterization over embeddings never trained on text. The framework is post-hoc and model-agnostic, requiring no modification to the upstream embedding system.
2026-11-06 05:00:00 · Transformer,向量数据库,论文
AI 资讯

On the limitations of molecular representations

arXiv cs.LGarXiv:2611.08420v1 Announce Type: new Abstract: Molecular representations such as fingerprints and learned embeddings play a central role in cheminformatics and small-molecule machine learning. They serve as the primary input for a diverse array of tasks, including clustering, dataset splitting, and virtual screening, yet their evaluation is often limited to downstream model performance on narrow benchmark tasks. We carried out a systematic investigation of the quality of molecular representations, finding that none of the state-of-the-art molecular embedding models capture graph structure, 3D shape, or ADMET endpoint similarity better than fingerprints or physicochemical descriptors. However, classical fingerprints also revealed their own material limitations. For example, we show that depending on the representation, between 225M and $\sim$4B molecules have non-unique representations in the 10.8B Enamine REAL database, with implications for virtual screening. Our findings provide an insight into the current limitations of molecular representations, outlining future research directions for the development of more robust encodings of small molecules.
2026-11-06 05:00:00 · 强化学习,模型评测,向量数据库,端侧AI,论文
AI 资讯

PersonaAgent: Retrieval-Augmented Transaction Anomaly Scoring with Refreshable Multi-Entity Persona Memory

arXiv cs.LGarXiv:2611.08094v1 Announce Type: new Abstract: In large-scale payment networks, entities (card, merchant, etc.) and their interactions play a key role in transaction anomaly detection. However, transaction patterns between different entities usually change more frequently than the production model refresh schedule. Meanwhile, entity embedding tables suffer from high-cardinality and sparse interaction issues. To resolve the above challenges, we present PersonaAgent, an agentic transaction anomaly detection framework which represents the latest entity behavior signals as personas and saves them in a refreshable memory. Offline, a weekly scheduled batch job is used to extract the latest behavior signals and update them in the memory. At inference time, a lightweight adapter retrieves the corresponding entity behavior signals of each transaction from memory and uses them to augment the base anomaly classifier's scoring. Through comprehensive benchmarking with different anomaly detection models at Visa, PersonaAgent is able to score transactions efficiently (a 1,000-transaction CPU batch in 1-2 ms), lifting the PR-AUC by 0.65-6.58% and the production business metric by 8.93-14.24% relatively in deployment.
2026-11-06 05:00:00 · AI应用,Agent智能体,模型评测,向量数据库,招聘HR,论文
AI 资讯

ConvPE: Convolutional Position Embedding Improves Transformers

arXiv cs.LGarXiv:2611.07749v1 Announce Type: new Abstract: ConvPE (Convolutional Position Embedding) improves both the performance and efficiency of Transformer models in language modeling, long-context extension, and vision. It injects a windowed, content-dependent bias into attention scores through a lightweight causal convolution over a low-dimensional projection of the hidden states. As a lightweight plug-in, ConvPE is compatible with RoPE, attention masks, and KV concatenation. It also supports high-dimensional position embeddings via high-dimensional convolutions. In a reproduction, ConvPE outperforms five 1D baselines and eight 2D baselines. The code is publicly available at https://github.com/wzhagi/convpe.
2026-11-06 05:00:00 · 开源,Transformer,强化学习,向量数据库,招聘HR,论文
AI 资讯

Loopback Transformer: Towards a Unified View of Residual Looped Transformers

arXiv cs.LGarXiv:2611.07226v1 Announce Type: new Abstract: Looped Transformers reduce parameter count by repeatedly applying shared blocks, but parameter sharing alone does not determine how the results of repeated computation are reused. We take the depth-memory view of residual connections and analyze which representation is stored after each block application and how later reads weight it. A full block output contains both its input and its new update, so weighting that output also reweights the history already carried by the input. Reading individual updates instead, with the shared stack's input kept on a separate path, gives separate controls over input strength, total update weight, and allocation across updates. The Loopback Transformer implements these controls: geometric decay sets the total update weight and supplies a recency prior, and attention learns how to allocate that weight. On ClimbMix, Loopback reaches lower validation loss than standard Transformer baselines with 40-75% of their Transformer parameters (excluding token embeddings and the output head) at reference scales from 191M to 3B, with training tokens and executed depth matched. It also has higher mean accuracy over thirteen downstream tasks at 1.4B and 3B. At 191M, 374M, and 778M, it has the lowest validation loss and the highest thirteen-task mean among the standard Transformer and seven looped residual designs.
2026-11-06 05:00:00 · 算力芯片,Google,Transformer,向量数据库,端侧AI,论文
AI 资讯

Structured Machine Theory of Mind from Agent Trajectories

arXiv cs.LGarXiv:2611.07208v1 Announce Type: new Abstract: Predictive models of human behavior trained on large-scale trajectory data optimize for statistical accuracy without representing the mental states that causally generate behavior. Such models support prediction but not principled intervention: they cannot answer how an agent's behavior would change if its beliefs or preferences were different. We introduce Structured Machine Theory of Mind (SMToM), a framework that attributes explicit, independently supervised belief and desire representations from observed trajectories within a Belief-Desire-Intention (BDI) causal structure. The central architectural element is a goal head that consumes only the predicted mental-state channels and a current-trajectory embedding; counterfactual intervention on beliefs and desires is a direct operation. We instantiate SMToM on a controlled pedestrian navigation domain where ground-truth mental states are known by construction, enabling evaluation of attribution accuracy, local channel interventions, and trajectory-level counterfactual diagnostics. The resulting model, BDIBottleneck, improves over trajectory-only and unsupervised-context neural baselines. It is also competitive with a matched auxiliary-supervised context baseline while providing an editable mental-state interface that the unbottlenecked baseline lacks. Counterfactual experiments on desires confirm that substituting an agent's inferred preferences with a different activity type coherently shifts predicted destinations toward relevant locations. Counterfactual experiments on beliefs confirm that marking a location as unavailable in the agent's belief state reduces its predicted probability as a destination, though in a complex way. These results demonstrate, in a controlled navigation setting, that explicit BDI-structured supervision is a viable foundation for interpretable and counterfactual analysis of longitudinal trajectory data.
2026-11-06 05:00:00 · AI应用,Agent智能体,扩散模型,强化学习,向量数据库,论文
继续滚动加载更多…