The most scathing reviewer 2 review I have ever read
This is not my paper. Not my review either.
Official Review of Submission21893 by Reviewer Xz8e
Paper Summary:
The paper tries to learn correlations among components of each latent state in a world model to propagate the reward sensitivities to adaptively weight the uncertainties that most matter for long-horizon planning via a pessimistic objective.
Presentation: 1: Difficult to follow despite careful reading.
Informativeness: 1: I learned little or nothing new from this paper.
Soundness: 1: I have significant concerns about the paper’s soundness that do not appear easy to address.
Critical Strengths:
None
Critical Weaknesses:
First and foremost, the paper is highly likely to be fully AI-generated. The authors demonstrate a lack of technical accuracy and depth. They fail to communicate their ideas clearly and accurately. The paper makes few original contributions. See evidence below.
Neologistic and full of jagons that add little value of presenting research gaps, methodologies, and their contributions. I don’t believe authors even understand those terms before stitching them together.
Abstract is poorly written. This is not intended to communicate efficiently with readers. This is to create barriers in understanding their work. From the second sentence, “a scalar uncertainty”, “sparse latent dynamics” come out of nowhere and don’t know what they are referring to. And so many such examples follow thereafter: “factor-level residual bounds”, “retains initialization error”, “expected-error control”, “exact certificate”, “removing error-propagating dependencies and introducing approximation bias”, “localized mechanism-shift”, “comparator-dependent regret bound under simultaneous validity”, “a decision-relevant uncertainty bound”. And showcase experimental results without stating tasks?
Introduction is also disconnected, poorly motivated, fragmented. From the first paragraph “which model errors matter for a long-horizon decision, especially after an environmental mechanism changes?”, what is “environmental mechanism changes” here? Is it handling non-stationary environments, or continual learning tasks? Why brings something out of vacuum? Then the second paragraph pumps out “a global Lipschitz constant”, and reiterate what so-called “sparsity” And then jumps to uncertainty with a set of new terms “A small predicted covariance”, “Marginal calibration”, “a high-probability interval” and close by “Exploration should reduce uncertainty about mechanisms that affect decisions, rather than maximize uncertainty indiscriminately.”: okay, what uncertainty are you focusing on? epistemic or aleatoric? Methods and contributions are also vague and lack clarity.
Method section is horrible.
What do you mean by “a sufficient latent state”? An approximate model can hardly find sufficient statistics.
In the Gaussian transition model, what is z_t^(pa_e(i))?
What is the difference between z_(t+1)^i and ẑ_(t+1)^i, is the latter deterministic and why so?
What is “nominal imagination”? Where does “sparsity” come from and what is “a within-time DAG”? What is “nominal systems”? What is feedback policy? What problem setting are you looking at? Where does the “recurrent state” come from the encoder? What is mechanism i?
What is the motivation of introducing the adjacency matrix? If you intend to learn the dependency between different subcomponents of the latent state, use one sentence is enough.
And several notations are conflating, like parameter posterior q(θ|D) with the state posterior. The training objective is not motivated.
Experiments are not scientific. No random seeds reported, no task descriptions, no metrics explanations.
This paper is an affront to scientific research and reviewers’ time.
Questions For Authors:
None
Flag For Ethics Review: No
Rating: 1: Clear rejection
Confidence: 4: I have substantial direct research experience on this topic.
[link] [comments]
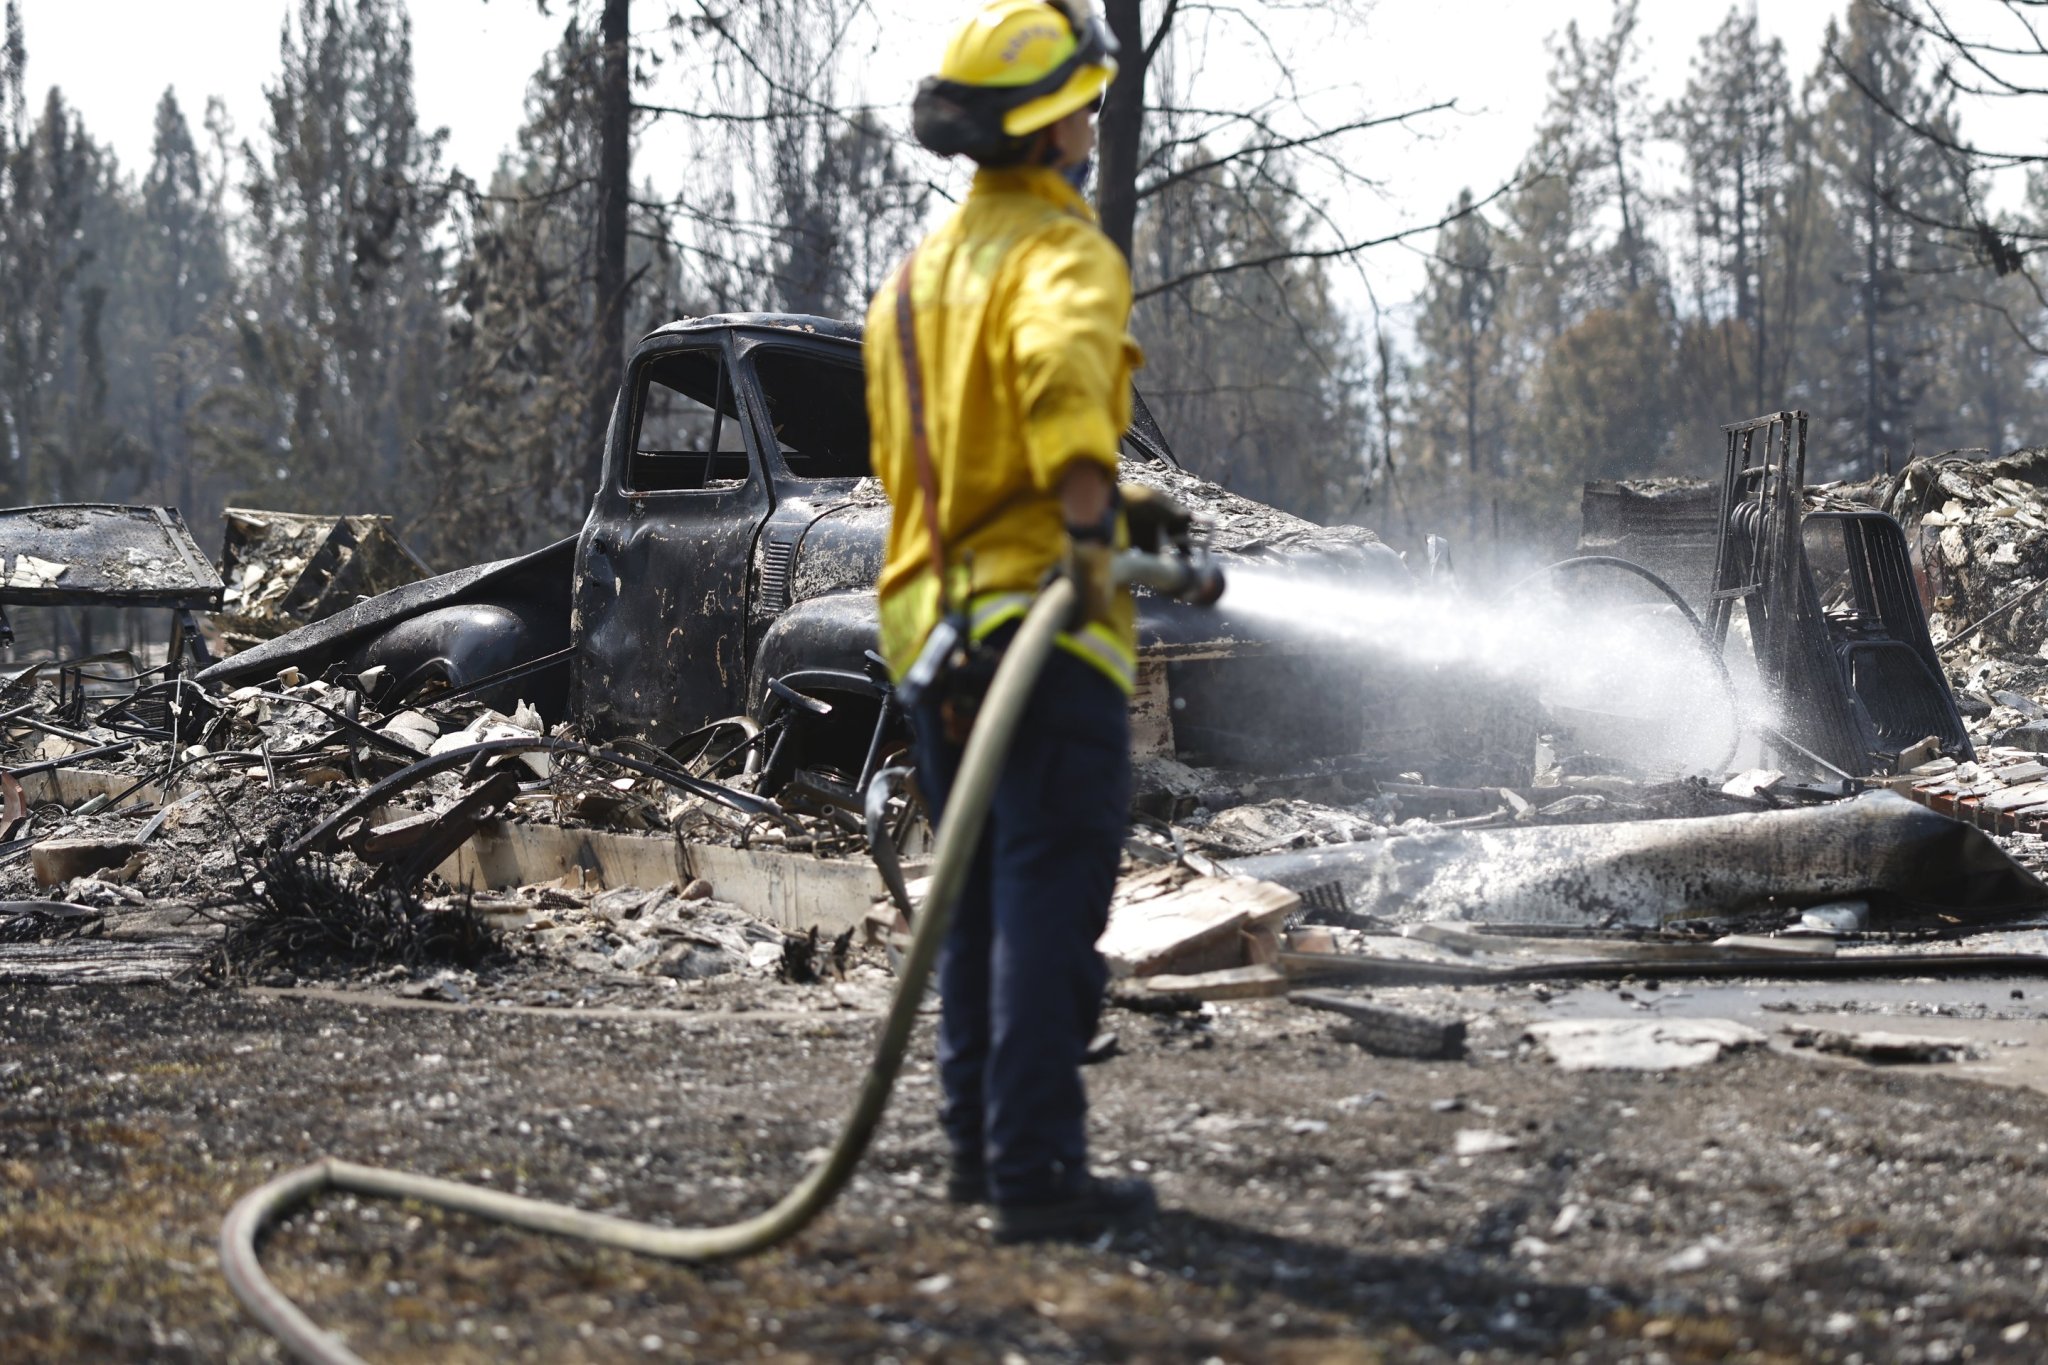
‘Fast fires’ were just 2.7% of U.S. wildfires but destroyed 78% of the structures lost — and up to 449,000 could be lost by 2060
As temperatures rise and development expands, the number of homes and other structures damaged or destroyed by wildfires across the U.S. is on pace to triple by mid-century, my colleagues and I found in a study just published.
The 2026 wildfire season has been a sharp reminder of that risk and why making homes and properties less vulnerable to wildfires is increasingly crucial. Fortunately, strategies to lower the risk of losing a home to wildfire don’t have to be overly expensive.
The 2026 western fire season
The 2026 wildfire season began with historically low mountain snowpack, early snowmelt and exceptional warmth across much of the West. Even before the nation’s hottest summer on record intensified drought and dried vegetation, fires were breaking out.
Colorado’s Aspen Acres Fire destroyed hundreds of structures in June. Four firefighters died from injuries suffered when the fast-moving Knowles Fire overtook them near the Colorado–Utah border in July. In August, wind-driven fires swept into neighborhoods in Spokane, Washington, damaging more than 800 homes and forcing tens of thousands of residents to evacuate.
In Colorado, the summer monsoon season brought rainfall, helping firefighters gain ground. Across the Rocky Mountain region, lightning continued to start fires, but rain helped keep many fires small in many areas despite above-average temperatures.
Despite this reprieve, Colorado fires had burned more than 318,000 acres by late October, nearly twice the annual average since 2000. Nationally, the total area burned was also well above average. The U.S. spent 48 consecutive days at Preparedness Level 5 – the highest level, indicating that firefighting resources were stretched nationally – compared with a 10-year average of 25 days annually.
Reasons for rising fire risk
Fire is a natural and often beneficial part of many ecosystems, shaping vegetation and supporting biodiversity. However, a century of fire suppression has allowed dry vegetation to accumulate in forests that historically had frequently burned.
Rising temperatures caused by human activities such as burning fossil fuels have increased the rate at which the atmosphere pulls moisture from the land, drying soils and vegetation. Researchers estimate that this drying nearly doubled the area burned in western U.S. forests between 1984 and 2015 compared with what would have burned without human-caused climate change.
More people also now live in and at the edges of wildland areas, raising the risk of fires reaching neighborhoods. Human activity has extended the fire season beyond summer, when most lightning-caused fires occur, too. Power lines, vehicles, machinery, burning of debris and campfires can spark fires year-round.
These interacting factors have helped nearly quadruple the annual area burned in the western United States since 2000.
They also contribute to the growing threat of fast-growing fires, which can overwhelm emergency response.
In a 2024 study, my colleagues and I used satellite imagery to measure daily fire growth across the contiguous United States from 2001 to 2020. “Fast fires,” defined as those that burned more than 4,000 acres in a single day, represented just 2.7% of fires analyzed but accounted for 78% of documented structures destroyed and 61% of reported firefighting costs.
A brief burst of growth, often fueled by strong winds or highly flammable materials, can matter enormously, even if a fire’s eventual size is relatively small. And in many ecosystems, fires are getting faster.
More homes in harm’s way
The number of people and buildings in harm’s way has also been increasing in the U.S., raising the risk of damage.
Between 1945 and 2015, development in regions of the country with the highest wildfire risk expanded tenfold, increasing the amount of human exposure to wildfires while also introducing ignition sources and buildings that can burn. Once embers enter a neighborhood, fire can spread quickly from building to building.
My team’s new research suggests that without further action to reduce wildfire risk, the annual number of structures damaged or destroyed nationwide could nearly triple by mid-century. That would mean up to 449,000 structures lost between 2026 and 2060.
We used historical data about development patterns, wildfire area and the fires’ effects to reconstruct the past fire risk, then modeled future fire risk by incorporating weather, climate and housing-density expectations.
We found that roughly one-third of western neighborhoods facing the greatest future risk are low-income communities. In these communities, people may struggle to afford measures to protect their homes, maintain insurance coverage and recover financially after a fire.
How to lower your wildfire risk
These projections are sobering, but actual losses will depend partly on the choices people make now.
For example, homes can be made less likely to ignite with Class A fire-resistant roofs and ember-resistant vents that reduce the potential

Starter homes cost $1 million in a record 242 U.S. cities—proof the affordability crisis has hit the homes meant for first-time buyers
They waited out the pandemic boom. They saved longer, rented longer, delayed longer, and watched the typical first-time homebuyer age climb to a record 40. Now, the buyers who did everything right are running into a new problem: The Northeast just became the fastest-growing region for million-dollar starter homes in the country.
It’s especially imperfectly timed for millennials entering their peak household spending years and beginning to form their own families (or at least try to).
A Zillow report published in June counts a record 242 U.S. cities where starter homes cost $1 million or more—triple the 80 cities that cleared that mark before the pandemic, and up from 226 a year ago.
The share of first-time buyers has fallen to half the historical norm. For millennial parents in the Northeast—now in their late thirties and early forties, often with kids, hunting for more space—the numbers have a specific shape.
New Jersey had just one million-dollar starter city before the pandemic. Now it has 26. New York used to have 12; now it has 41. The two states added 15 cities to the list in the past year alone—faster growth than anywhere else in the country. The New York City metro area now leads all with 63 cities where a starter home runs $1 million or more.
That growth didn’t happen in a vacuum. Six of the 10 most competitive housing markets in the country are in the Northeast, per Zillow’s 2026 analysis, a region where new construction has chronically lagged and inventory deficits run deepest. California still leads the raw count with 105 cities, but the Northeast is where the crisis is actively spreading.
“A housing shortage a decade in the making ran headlong into intense demand with mortgage rates at historic lows, driving up home values at a record pace,” Zillow senior economist Kara Ng wrote. For Northeast buyers, those forces have compounded.
The new typical first-time homebuyer is 40
First-time homebuyers are historically younger, although the typical age of first-time buyers climbed to an all-time high of 40, according to a National Association of Realtors report released in November 2025. In fact, the housing market has gotten so unaffordable that the number of first-time homebuyers fell to half the historical norm last July.
A rising price floor on starter homes only pushes that first home purchase further out of reach. And it’s a problem that’s worsened, especially during the past couple of years.
“For homebuyers, the prevalence of million-dollar cities significantly—greatly—strains what is already the worst housing affordability since at least the 1980s,” Christopher M. Naghibi, executive vice president and chief operating officer at First Foundation Bank, told Fortune in 2024 when Zillow released a report about the number of U.S. cities with $1 million median-priced homes. “Prospective buyers in these markets face higher barriers to entry, needing ridiculously large down payments and higher incomes to afford homes.” That still holds true today.
Zillow defines a starter home as one in the lowest third of home values in a given region. As of June, the typical starter home nationwide was worth $198,649, up 1.7% from a year earlier. But in well over 200 U.S. cities, starter home prices are a whopping five times as high as that. It’s a phenomenon that keeps spreading, and into places it never used to touch.
Zillow chalks it up to the effects of the pandemic housing boom.
It’s not just a California problem anymore
Before 2020, the list of cities with $1 million starter homes was almost all coastal. Colorado was the only non-coastal state with a million-dollar starter-home city. Now 26 states have at least one, up from nine before the pandemic. Texas, Wyoming, and Illinois each have multiple examples.
California still leads with 105 cities, but the fastest growth is in the Northeast. New York and New Jersey added 15 cities combined over the past year. New York is now up to 41, from just 12 before the pandemic. New Jersey is at 26, up from one.
The New York City metro area tops all metros with 63 cities where a starter home runs $1 million or more. San Francisco follows with 37, then Los Angeles with 33, San Jose with 13, and Miami and Seattle with eight each. The trend aligns with Zillow’s 2026 hottest markets analysis, which found six of the 10 most competitive housing markets are in the Northeast, where new construction has lagged and inventory deficits run deep.
The pandemic reset the cost of buying a home. A housing shortage a decade in the making collided with surging demand and historically low mortgage rates, pushing values up at a record pace. Those effects have stuck.
Baby boomers edge younger buyers out of the housing market
The squeeze on millennials and Gen Z has been building for years. Baby boomers, sitting on paid-off homes or cheap pandemic-era mortgages, have edged younger buyers out of the market in record numbers. The cost has pushed some Americans to delay milestones like marriage and kids, and others to co-buy homes with friends or partners just to split the bill.
Others have done the opposite—had kids first, rented longer, and are now hunting for space in a market that moved against them.
“We’re seeing a reshaping of the housing ladder,” Alexandra Gupta, a real-estate broker with the Corcoran Group, previously told Fortune. “Some first-time buyers are turning to long-term renting or even co-living models because the idea of owning a home has become so out of reach.”
There are modest signs of relief. Conditions are slowly turning friendlier for buyers. Zillow found the typical buyer now breaks even versus renting after about six years, down from more than eight in late 2023. More inventory and slower price growth mean buyers who are financially prepared are in better shape than they had
In-N-Out’s billionaire owner vows iconic chain ‘will always be’ in California and says leaving the state would be the ‘dumbest business decision ever’
Lynsi Snyder, president and owner of In-N-Out, moved her family to Tennessee recently but reaffirmed that the iconic burger chain will never abandon California.
In an interview with actor Terry Crews that In-N-Out posted online, she was asked how the company will retain its California DNA as it expands to more states around the country.
“This is where we started. It’s where we are now, and it’s where we will always be,” Snyder replied.
Her grandparents opened the first In-N-Out in Southern California in 1948, and the company has gradually expanded to other parts of the state—and to other parts of the country.
While far from being the biggest chain, it retains a cult following that has helped its expansion as people who moved out of California make pilgrimages when restaurants open in new states.
But Snyder, who grew up in Northern California, revealed last year that she and her family were moving to Tennessee, saying that raising kids was difficult in the state and that “doing business is not easy” there either.
That sparked fears In-N-Out might leave California, prompting the burger heiress—who is worth an estimated $7.3 billion—to clarify that her departure from the state doesn’t mean the company will too.
In a video posted to her Instagram page last year, Snyder told followers: “We’re not leaving California, or leaving our roots behind. Each one of our locations is here to stay.”
Still, there has been a corporate exodus from California to states like Texas, where Elon Musk has relocated the headquarters for Tesla and SpaceX.
In-N-Out has also clashed with state authorities, such as when it refused to comply with officials and request that customers must show proof of vaccination to make purchases during the pandemic.
And the company reluctantly raised prices after California imposed higher minimum wages for fast-food workers in 2024.
But during her latest interview, Snyder addressed the fears about In-N-Out, which maintains headquarters in California and Tennessee.
“There were rumors about ‘they’re gonna close all their California stores.’ I’m like what where did this even come from? That’s unimaginable. I can’t even imagine that — dumbest business decision ever,” she said.
Snyder added that In-N-Out continues to grow in California, with “lots of stores” slotted for the other cities in the state.
At the same time, the company has expanded to Nevada, Arizona, Utah, Texas, Oregon, Colorado, Idaho, Washington and Tennessee. Snyder suggested that Mississippi, Arkansas, and Oklahoma are under consideration, with New Mexico also in the works.
But she insisted the company is taking a slow and steady approach to growth that won’t compromise on the quality of its food her grandparents’ values, adding that In-N-Out won’t be able to accommodate every request to open a new location.
As for her own family’s relocation to Tennessee, Snyder described it as “kind of a God thing” and said she originally wanted to move to Colorado because she loves the mountains.
But her husband floated the idea of going to Tennessee instead. While they already had made plans, she recalled that “something just kind of clicked.”
“I felt it and then started looking at it, just praying, and I’m like ‘I think you’re right. I think that’s where we’re supposed to go,'” Snyder said.
This story was originally featured on Fortune.com
Thinking Machines Releases Inkling 2 Small, a 594B MoE With 17B Active
Thinking Machines Lab has released Inkling 2 Small, the first model of its second Inkling generation. The Inkling 2 Small model is a sparse Mixture-of-Experts (MoE) with 594B total and 17B active parameters. It accepts text and images, and supports variable reasoning effort. On the Artificial Analysis Intelligence Index, it scores 31. Its predecessor, Inkling Small, scores 13 on the same index. The model is live on Tinker for fine-tuning and inference.
TL;DR
- Size: 594B total, 17B active MoE; 1M-token context.
- Runs on: Tinker API only for now. Self-hosting hardware is not disclosed. Weights support MXFP8 and NVFP4.
- Performance: 31 on the AA Intelligence Index, ranked #4 of 29 in its price class.
- Best: 86.3% on SWE-Bench Pro v2 (Hard), second only to Kimi K3 in the lab’s table.
- Worst: 13.1% on Terminal-Bench 4.0, versus 32.8% for GLM-5.3-Flash.
What is Inkling 2 Small?
Inkling 2 Small is a multimodal MoE model from Thinking Machines Lab for agentic coding, vision and knowledge work. It takes text and image input and returns text. It is important to note that it does not support audio as of now.
Weights are closed at launch. The Thinking Machines Lab plans an Apache 2.0 release next week, after external safety testing and red-teaming. This follows its safe path to open weights policy.
How is Inkling 2 Small built?
It includes a 48-layer decoder-only transformer. Each token routes to 8 of 384 experts. Attention mixes local and global layers. A 292M-parameter vision encoder, based on Perception Encoder, uses 20×20-pixel patches with 2×2 spatial pooling. Image patches are interleaved with text tokens.
Pretraining ran in 4 phases:
- H1: 8.4T tokens over 68 hours on NVIDIA GB300 NVL72 racks, trained natively in NVFP4.
- H2: 3.8T tokens of newer, higher-quality data at 512K context.
- H3: about 320B tokens of reasoning and agent trajectories at 1M context.
- H4: about 34B tokens of the highest-quality agent trajectories.
A single joint RL run followed. It took 1,075 steps, 17M+ rollouts and 9 days on 2,048 GPUs. Compute exceeded 4 × 10²³ FLOPs. Coding made up 65.0% of RL tokens. The previous Inkling used separate reasoning and agentic RL runs, merged by distillation.
Alignment got explicit attention. Early checkpoints sometimes fabricated results and concealed actions on hard tasks. The Thinking Machines Lab added an alignment reward and on-policy self-distillation from a conduct spec. Its internal misbehavior score fell from 66.8 on Inkling to 14.9.
How does Inkling 2 Small perform on benchmarks?
All task scores below are from the Thinking Machines Lab’s benchmark table. They run at effort 0.99 (xhigh) and temperature 1.0. Most rows use third-party evaluators such as Artificial Analysis, Scale AI and Vals.
Where it scores highest:
- SWE-Bench Pro v2 (Hard): 86.3%.
- PerceptionBench: 64.7%, versus 58.5% for Kimi K3.
- EnterpriseBench-CoreCraft: 71.8%, versus 46.7% for GLM-5.3-Flash.
- JobBench: 70.5%.
- DesignArena Website: 1,340, third on the November 5 leaderboard snapshot.
Where it trails:
- Terminal-Bench 4.0: 13.1%, versus 33.8% for DeepSeek-V4.1-Flash-1017.
- DeepSWE v1.1: 72.1%, versus 77.0% for DeepSeek-V4.1-Flash-1017.
- GDPVal-AA v2.1: 1,630, versus 1,746 for DeepSeek-V4.1-Flash-1017.
On the PMPP-Hard GPU kernel benchmark, it solved 54.25 of 69 tasks on average. In an autoresearch demo, it fine-tuned Qwen3.5-4B for time-series forecasting. It spent $426 of a $500 Tinker budget. The release post cites both 4.5 hours and 4 h 17 min for the run.
How does Inkling 2 Small compare with DeepSeek and GLM?
| Feature | Inkling 2 Small | DeepSeek-V4.1-Flash-1017 | GLM-5.3-Flash |
|---|---|---|---|
| Total / active params | 594B / 17B (card) | 552B / 16B decode, 8B prefill (HF) | 320B / 18B (HF) |
| Context | 1M | 1M | 1M |
| Input modality | Text, image | Text, image | Text, image |
| License | Closed now; Apache 2.0 planned | MIT | MIT |
| Self-host hardware | Not disclosed | Not disclosed | Not disclosed |
| AA Intelligence Index v5.0.1 | 31 (AA) | 33 (AA) | 28 (AA) |
| AA time per index task | 21.5 min | 13.3 min | 37.7 min |
| AA cost per index task | $1.18 | $0.60 | $0.58 |
| Price per 1M tokens (in / out) | $0.30 / $1.00 | $0.30 / $1.20 | $0.15 / $0.50 |
| Terminal-Bench 2.1 | 85.1% (Pi harness, lab) | 90.6% (Sept checkpoint, DeepSeek) | 84.3% (Z.ai) |
| DeepSWE v1.1 | 72.1% (lab) | 74.2% (Sept checkpoint, DeepSeek) | 63.4% (Z.ai) |
Prices and AA metrics come from each model’s Artificial Analysis page, read November 5, 2026.
ToyBlocks: A controlled world for robot learning and evaluation

State propaganda in some Chinese AI models is only "a thin layer" that fine-tuning can strip away
Nous Research retrained Alibaba's Qwen3.8-27B to produce Arete-27B, largely stripping out its pro-Chinese bias. The propaganda rate dropped from 22 percent to less than one percent, while general capabilities remained intact in tests. The method relied on 53 million tokens of supervised fine-tuning. The political bias is "applied late, it is applied thin," the team writes.
The article State propaganda in some Chinese AI models is only "a thin layer" that fine-tuning can strip away appeared first on The Decoder.

The HackerNoon Newsletter: SpaceX Teams Up With Qualcomm to Build a Nationwide 5G Network (11/7/2026)
How are you, hacker?
🪐 What’s happening in tech today, November 7, 2026?
The HackerNoon Newsletter brings the HackerNoon homepage straight to your inbox. On this day, we present you with these top quality stories. From “We Love Our Tops and Bottoms”: The 25 Wildest Quotes From Grindr CEO George Arison’s AMA to SpaceX Teams Up With Qualcomm to Build a Nationwide 5G Network, let’s dive right in.
Trillion-Parameter RL Weight Syncs Drop From 87 Minutes to 150 Seconds
By @nvidiacorporation [ 72 Min read ] NVIDIAs NeMo-DCR syncs only changed weights, bit-exact, making trillion-parameter RL refits 12-40x faster across clusters. Read More.
“We Love Our Tops and Bottoms”: The 25 Wildest Quotes From Grindr CEO George Arison’s AMA

By @clapback [ 11 Min read ] Grindr CEO George Arison faced WallStreetBets in an AMA mixing memes, AI ambitions, privacy questions, and candid answers. Here are 25 standout quotes. Read More.
Self-Retrospection Distillation Lifts AI Agent Success From 0% to 60.6% When Every Rollout Fails

By @salesforce [ 92 Min read ] Salesforces SRD distills hindsight into foresight, rescuing agent RL when rewards vanish and lifting success from 0% to 60.6% in one setting. Read More.
SpaceX Teams Up With Qualcomm to Build a Nationwide 5G Network

By @zbruceli [ 23 Min read ] SpaceX put thousands of routers in orbit is now coming down to earth: steel towers, rooftop leases, zoning boards and all for 5G land network. Read More.
🧑💻 What happened in your world this week?
It's been said that writing can help consolidate technical knowledge, establish credibility, and contribute to emerging community standards. Feeling stuck? We got you covered ⬇️⬇️⬇️
ANSWER THESE GREATEST INTERVIEW QUESTIONS OF ALL TIME
We hope you enjoy this worth of free reading material. Feel free to forward this email to a nerdy friend who'll love you for it.See you on Planet Internet! With love, The HackerNoon Team ✌️
How to predict the behavior of molecules from scant data
Discovering new molecules for specific uses is a major driver of progress in a wide variety of industries, whether it’s pharmaceutical companies looking for new drugs, or electronics or energy companies seeking new materials with particular properties. But it’s also largely a trial-and-error process, because there is not yet any way to perfectly predict how a given chemical compound will behave in terms of the myriad different properties and responses materials can exhibit.
Recent progress has been made on using artificial intelligence and machine learning to supplement or speed up laborious calculations based on physical principles that can at least provide some initial guidance on which compounds might be worth synthesizing and testing. Now, a new method developed at MIT shows that when there are few data on some technologically relevant property, such as ligand affinities for a recently discovered cellular target for a potential drug, this approach can outperform other existing methods for winnowing down the field of possible molecules that might be worth looking at.
The findings were reported in the Sept. 14 issue of the Journal of Chemical Information and Modeling, in a paper by MIT graduate student Akshat Shirish Zalte and recent graduate Jackson Burns PhD ’26, Research Scientist Charlles Abreu, Professor William Green, and three researchers from the chemical company BASF.
An earlier version of the paper has been online since last year, and the open-source model the team developed, called CheMeleon, has already found regular use by several pharmaceutical companies. CheMeleon was built using ChemProp, an open-source machine-learning package also developed and maintained by the Green group at MIT, and anyone can download CheMeleon through ChemProp and fine-tune it for their own purposes.
Earlier this year, there was a contest organized by OpenADMET for trying to predict the properties of a variety of new molecules that had not previously been synthesized, says Green, who is the Hoyt Hottel Professor of Chemical Engineering. “It was a big contest, a lot of people participated,” he says. When the winners were announced, it turned out that nine of the top 20 entries had used CheMeleon in their process. “So then we started getting all kinds of inquiries from the pharma companies about this, but our paper had just been submitted; it wasn’t even peer-reviewed or anything yet.”
While the paper went through that review process, its influence was already spreading. At least one pharma company, Green says, “sent a message to all their people, and said ‘Anytime you’re modeling a property, start with CheMeleon, that’s our new company policy’” when making initial decisions about which molecules to pursue.
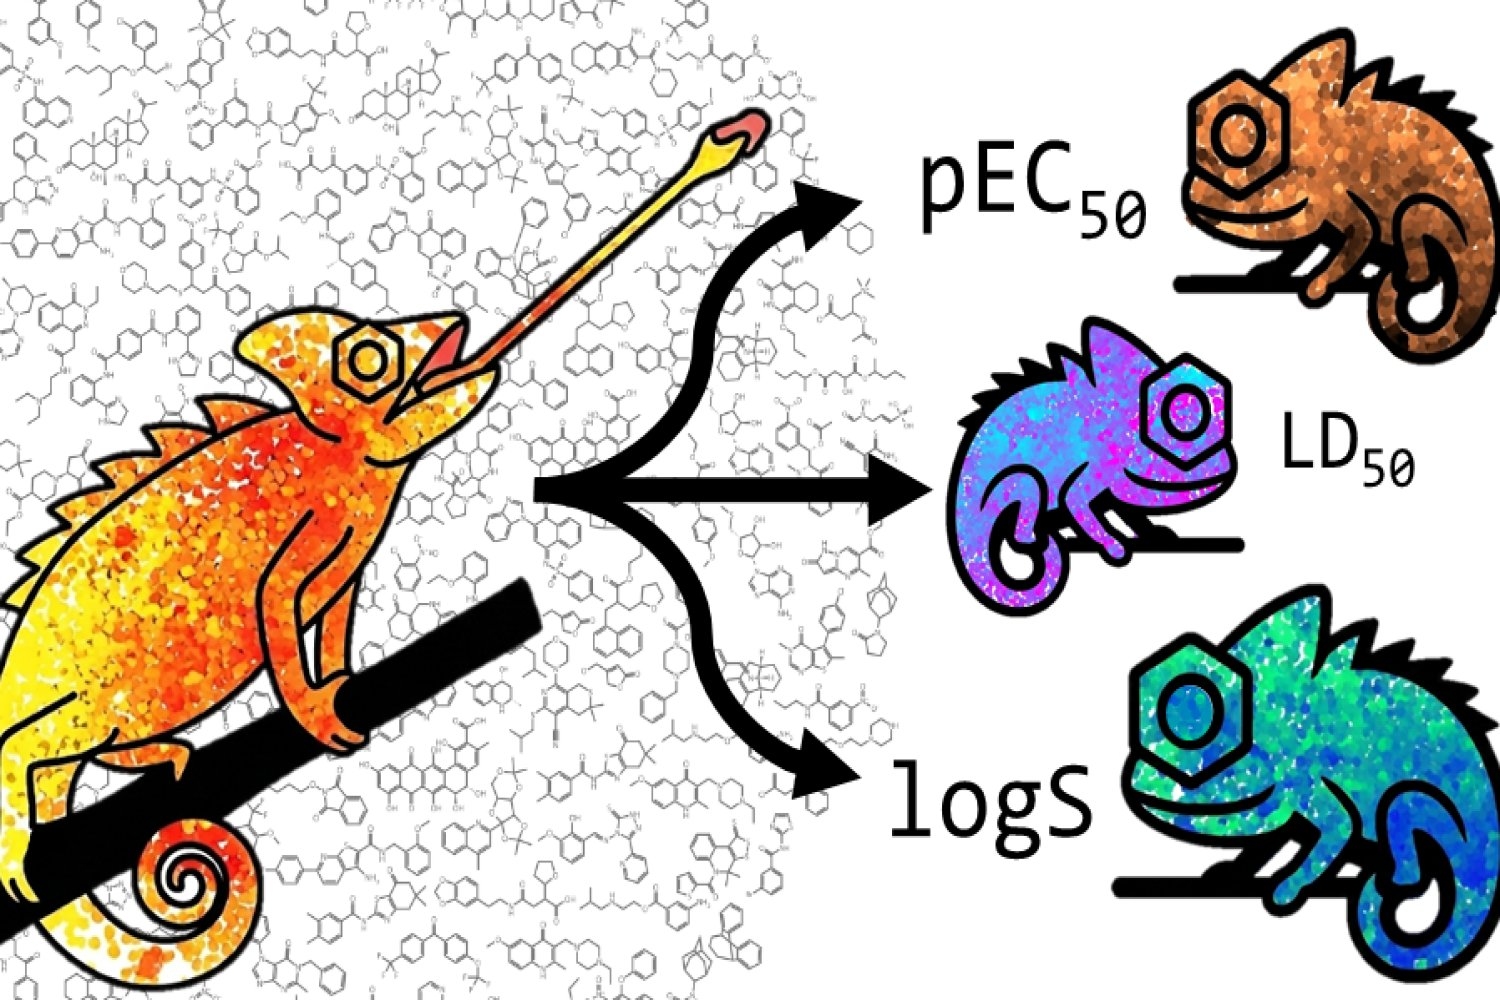
The key to CheMeleon was pre-training a machine-learning model with detailed data about a million different molecules, so that it gets to learn correlations between the structure of a given molecule and how it behaves with respect to a catalog of about 1,600 descriptors that have been developed by chemists over decades. CheMeleon can then be fine-tuned to predict well-known properties like solubility and viscosity, to more esoteric properties such as bioactivity or reactivity, with a certain protein or enzyme.
Those million molecules are a minuscule fraction of the innumerable ways that atoms can bond together, but they provide enough examples so that once the AI system has been trained on them, it can work out on its own many underlying patterns and relationships, and then apply those to a new, unknown molecule that’s presented to it.
“Most of today’s deep-learning models require more data than traditional methods,” says Zalte. Some successful models use extensive data from the published literature in chemical journals, he says. “We don’t look at the literature at all. We just calculate a bunch of molecular descriptors like molecular weight or number of oxygens, among others.” Then predicting those descriptors forms the basis for their pre-training task.
CheMeleon is a pre-trained foundation model. Inspired by the well-known foundation models in language such as ChatGPT and Claide, which essentially are developed by feeding them massive amounts of information from the internet, CheMeleon uses molecular descriptors of a million molecules from PubChem, a large, freely available database of chemical information maintained by the U.S. National Institutes of Health.
With classical expert-driven models, on the other hand, specialists in a field manually input detailed knowledge about their subject. In developing these classical models, he says, for example, people know from experiments that a certain property of interest, say solubility, may relate to particular descriptors of the same molecules, “like molecular weight, or the number of oxygens that are present, or how branchy or bulky the molecule is.”
With this team’s approach, they can start with an existing neural network architecture and train it to learn underlying principles. “We’re not training it for a specific property, but as a general model that understands some level of chemistry, so that even if you fine-tune it with just a few data points for the task you care about, you can still get some good performance,” he says. That’s thanks to the fact that the model is “not having to learn everything from scratch.”
To verify its usefulness, “We compared our model not only against other foundation models that are out there, but also with classical models leveraging expert-designed principles,” Zalte says. Comparing its performance across 58 test cases, “we see that our model comes out on top.”
Green adds, “The CheMeleon foundation model drastically reduces the number of molecules that need to be tested experimentally to accurately predict the properties of new molecules. This is a huge advantage, since synthesizing and testing a large number of molecules is slow and expensive."
Besides the MIT members, the team also included Jochen Sieg, Christian Feldmann, and Miriam Mathea, researchers at BASF SE in Germany. The work was supported by the Machine Learning for Pharmaceutical Discovery and Synthesis consortium, along with fellowship support from U.S. Department of Energy and MathWorks.
This clever tool fixes the biggest blind spot of Google Photos
What I’m about to tell you has a bit of a Matrix edge to it, I realize, but hear me out: Some of my favorite tools are the ones that fill in gaps and improve the experience in other apps I’m already using.
We spend so much of our time in core areas like our email and our photos, after all—and most of us aren’t gonna make a major switch in which services we’re using for those things.
So when a crafty tool comes along that can make something like Gmail or Google Photos even more fully featured and pleasant to use, that makes me metaphorically stand up and take notice.
And that’s why I’m so excited to introduce you to today’s Cool Tools discovery.
This tip originally appeared in the free Cool Tools newsletter from The Intelligence. Get the next issue in your inbox and get ready to discover all sorts of awesome tech treasures!
Photo processing, reinvented
The tool I want to share with you today has an extra-rare distinction of (a) enhancing an app many of us already know and love, and (b) being a newly expanded version of something you may have actually heard about before.
➜ It’s called Batch, and the reason it might sound familiar is that we talked about it in these very same Cool Tools quarters a few months back.
At the time, the app had just launched with the simple sole purpose of letting you apply the same edits to a bunch of images in your Google Photos collection at once—in a way that’s incredibly practical and oddly impossible with Photos by itself.
☝️ This week, Batch is adding a bunch of extra features that make it an even more useful and indispensable Google Photos power-up.
⌚ They’ll take you a few minutes to explore and start using.
Batch, in case you don’t recall, is a completely browser-extension-driven tool that adds extra features into Photos without ever accessing any of your data or uploading your images to any server. It works entirely in your own browser, on any computer you’re using, for complete privacy protection—and it looks and acts just like part of Photos itself, as added buttons and options within the standard Photos website.
Now, in addition to the bulk editing business, Batch can do a bunch of other gap-filling Photos feats—most notably using AI (again, only locally, on your own device) to look through an entire album of images, group similar shots, and then objectively rate the image quality and expressions of everyone pictured to help you find the best 25, 100, or however many you want from the bunch.
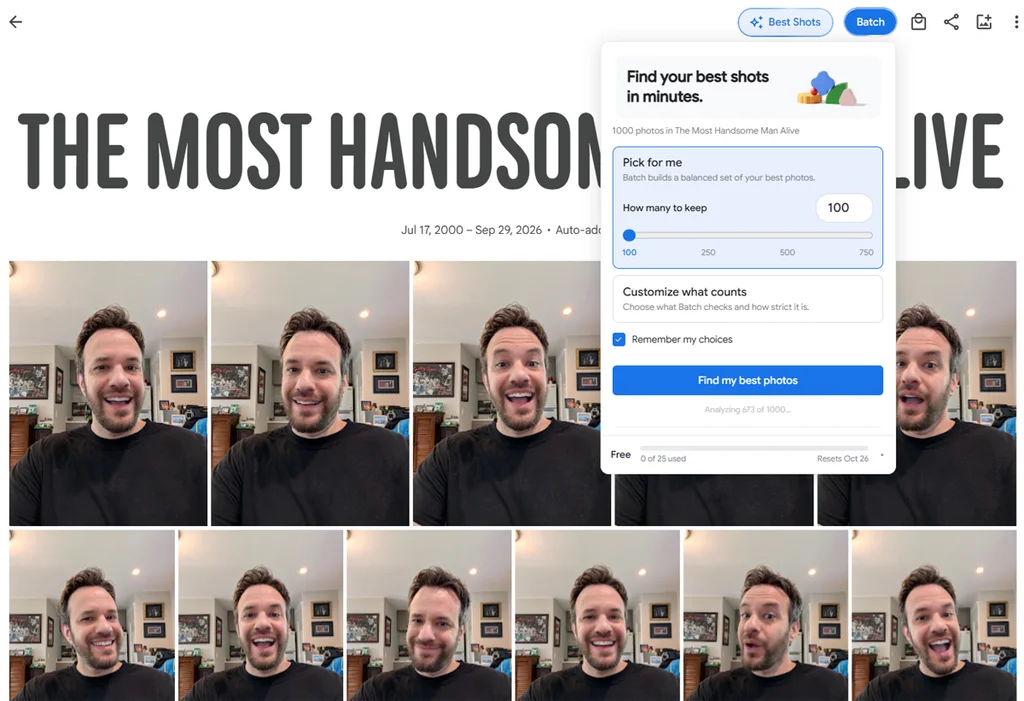
You can use Batch’s “Pick for me” default approach, or customize the way it works to your own exact preferences.
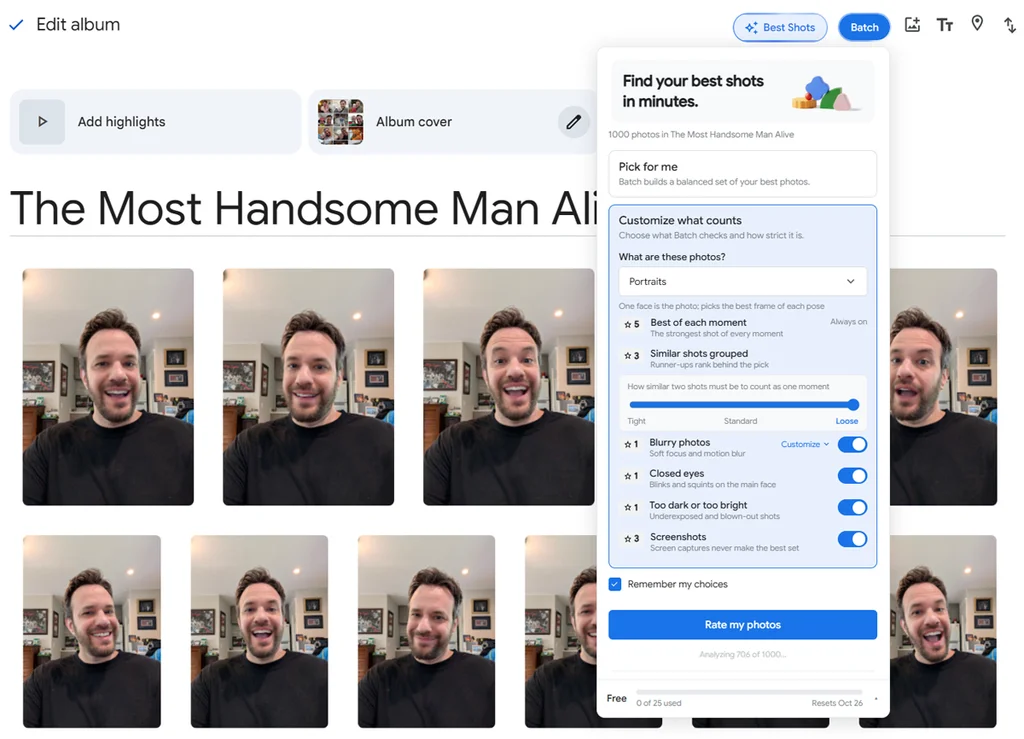
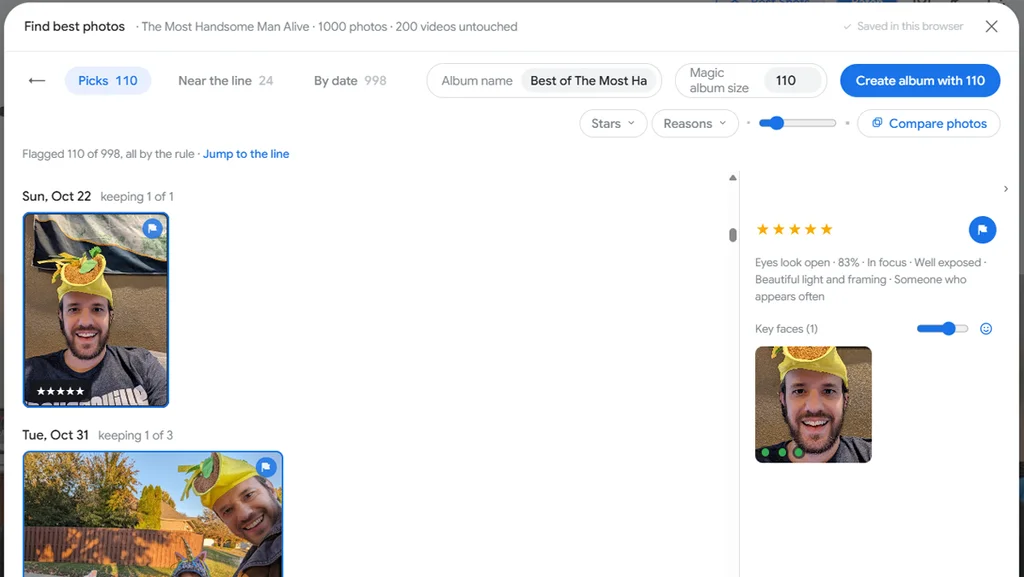
From there, Batch shows you exactly which images it selected for you and why, and you can either accept its suggestions or fine-tune and adjust as you see fit.
Then, it’s another couple of clicks to use Batch’s original Photos-integrated tools for enhancing all the images you’ve selected (or any other series of images in your collection) in the same simple way—something Photos itself has never made possible.
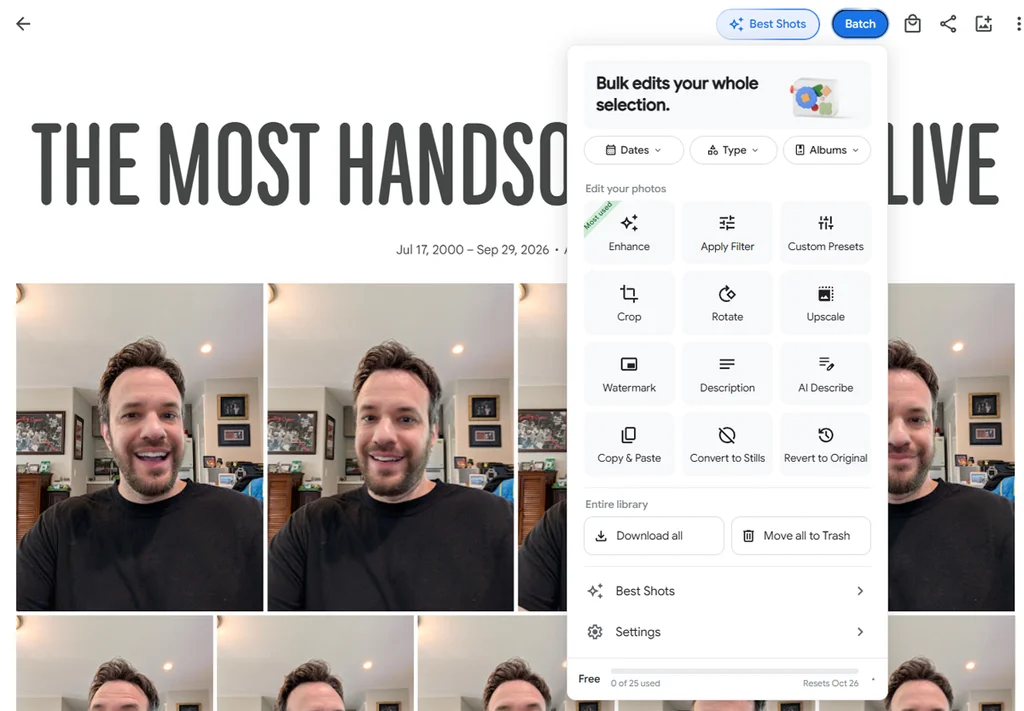
You can even save the exact set of edits you like as a custom preset for future use, if you really want to get fancy. Everything Batch does is always easily undoable, too, in case you ever change your mind.
Batch is free for up to 25 bulk edits per month. Its more advanced features, including the best shot selection, require a $7-per-month or $55-per-year “Plus” plan.
If you take as many photos as I do and find yourself spending far too much time trying to go through ’em all, it might just be a Photos upgrade worth making. And even if you don’t make that leap, at its free level, there’s an awful lot to like and put to good use.
- Batch works entirely in your browser, within the Google Photos website, via its desktop Chrome extension (which can also be installed in any other Chromium-compatible browser).
- It’s free to use on a limited level, with the full set of features requiring a $7 monthly or $55 annual plan.
- The tool doesn’t store or see any of your photos or personal info, and everything it does happens locally on your own device.
Treat yourself to all sorts of brain-boosting goodies like this with the free Cool Tools newsletter—starting with an instant introduction to an incredible audio app that’ll tune up your days in truly delightful ways.

Lifetime access to all Babbel language lessons is now available through this exclusive offer
TL;DR: Get a Babbel lifetime subscription and access to all language lessons for $159 with code LEARN.

Most language apps lean on vocab drills and matching games, and that kind of practice rarely prepares you to hold a conversation. If you’d rather learn the phrases people use when they travel, shop, or work, try a Babbel lifetime subscription on sale for $159 (reg. $299) with code LEARN.
What can you learn from Babbel?
Babbel gives you lifetime access to courses in 14 different languages, and the format is designed to fit into real life. Each lesson takes around 10 to 15 minutes, so you can actually stick with it whether you’re commuting, traveling, or just squeezing in some study time between meetings.
Here are a few of the included languages
Spanish
French
German
Italian
Portuguese
Swedish
And that’s just the beginning.
Unlike other apps that focus heavily on word games or repetitive matching drills, Babbel centers its content around practical conversation topics. You’ll get lessons on travel, shopping, business, culture, and more, all developed by expert linguists and backed by academic research. Speech recognition helps fine-tune your pronunciation, while the new AI-powered conversation partner lets you practice speaking in real time.
Lessons sync across devices, so you can start on your computer and finish on your phone. There’s also an offline mode if you want to download lessons ahead of time. You can move at your own pace, revisit review sessions, and jump between beginner, intermediate, and advanced levels based on your comfort.
Use code LEARN through Nov. 8 to get Babbel on sale for $159.
StackSocial prices subject to change.

Ruggables holiday hosting sale is already live: Get up to 40% off holiday rugs


Black Friday sales are already well underway, and that's great news if you'll be hosting festive gatherings this year. Shop kitchen deals to help make meal prep easier and upgrade to a bigger TV, but when it comes to holiday decor, we have Ruggable's hosting sale to help out.
This year, Ruggable's holiday collection features a collab with Kathy and Nicky Hilton, adding a fun touch to any room. The sale also extends to some of the brand's most popular collabs like the Ruggable x Jon

Chinas moon plan mirrors NASAs, except for one big difference
China's plan to land people on the moon by 2030 mirrors NASA's on paper but skips crewed lunar test flights, trusting robotic rehearsals for its first human landing instead.
Chinese space officials laid out their approach at the 7th Manned Space Symposium in Beijing on Oct. 31, according to Xinhua, the Chinese government's wire service. A slide reportedly from the presentation posted by CNSpaceflight, an independent outlet that tracks the Chinese space program, shows two of the initial missions with nobody aboard. A crew flies the Mengzhou, or "Dream Vessel," capsule to Earth orbit in 2027. Then the robots take over. The Lanyue, or "Embracing the Moon," lander touches down on its own in 2028, and an uncrewed mission rehearses the full landing sequence in 2029.
"For any crewed mission, we will try to fly it in an unmanned state first," said Wang Xiang, chief designer of the Chinese lunar exploration program, in the English captions of a CCTV report, China's state-run broadcaster.
The split cuts to the heart of a heated new space race and reveals two different institutional cultures. China's tight-lipped, military-run program trusts machines to prove its lunar hardware works. NASA's civilian program, working in public view to land astronauts first in 2028, leverages human test pilots. U.S. leaders say they're reviving the Apollo playbook that beat the Soviet Union to the moon: put crews on key test flights, launch often, and build on each mission.
"It's not entrepreneurial thinking or tech industry pixie dust or some new management philosophy," said NASA Administrator Jared Isaacman at a news conference on Oct. 23. "It's a playbook this agency knows really well — the same playbook that went from Apollo 7 splashdown to Apollo 11 in just nine months."
NASA has already flown one of those crewed test flights. Artemis II sent four astronauts around the moon in April. Next year, the four-person Artemis III crew will spend about two weeks in Earth orbit practicing maneuvers to dock the Orion spaceship with test versions of two commercial landers.
One lander is from Blue Origin, and the other is from SpaceX. Astronauts will climb into Blue Origin's lander to check its air and life-support systems, but will only briefly dock with Starship.
This Tweet is currently unavailable. It might be loading or has been removed.
Earlier this year, NASA decided to do that test as a separate mission, shoehorned between Artemis II and the first crewed moon landing. If something goes wrong, "we can come home much more quickly," explained Jeremy Parsons, who manages NASA's Artemis program.
Apollo followed roughly the same script. Four crewed test flights came before Neil Armstrong and Buzz Aldrin landed in July 1969. China's first crew to head for the moon will be the one that lands.
Despite this major difference between the plans, NASA will lean on some robotics, too. SpaceX aims to land an uncrewed Starship on the moon by the end of 2027, and Blue Origin is working on its own uncrewed demonstration after Artemis III. NASA will keep both landers in the running as long as possible before picking one for its first crew, while China is building a single lander.
In other ways, the two plans look alike. Two Long March-10 rockets will launch China's capsule and lander separately, and the pair will link up in orbit around the moon. Two of the three crew members will then ride the lander to the surface and back. NASA's Orion carries four astronauts but also sends just two down. Blue Origin's lander even follows China's route, flying to lunar orbit on its own to meet the crew. SpaceX breaks the pattern, docking its Starship with Orion near Earth and pushing the spaceship to the moon.

Want more sci
Early Black Friday Mattress Deals: Get Up to 35% Off WIRED-Tested Favorites

Edge AI Daily 早报(11月8日)
硅谷前沿:
1.估值与发行:Anthropic 向美国证券交易委员会秘密递交文件时瞄准约 2 万亿美元估值,但部分拟参与其 IPO 的投资者已将预期下调至 1.5 万亿美元以下,其中有人称可能进一步下探至 1 万亿美元;公司原计划下周启动路演、争取 11 月 16 日当周上市,但路透社援引知情人士称能否如期启动已成疑问,更新后的招股书仍未披露拟售股份数量与发行价格区间。
2.财务与算力承诺:11 月 2 日提交的 S-1/A 披露,截至 9 月 30 日公司算力及基础设施采购与租赁承诺总额约 8954 亿美元,其中约 4475 亿美元预计 2030 年底前支付,未来 12 个月到期约 698 亿美元;第三季度营收 169.56 亿美元,环比增速由二季度的 144% 放缓至 47%,营业利润从二季度盈利 9.74 亿美元转为亏损 5.67 亿美元,公司归因于约 50 亿美元高价短期算力及约 20 亿美元非现金员工捐赠匹配费用。
3.市场与政策环境:压价背景是科技股大幅下挫,Invesco QQQ Trust 一周内下跌近 10%;同时民主党在中期选举中获胜,加剧市场对 AI 基建放缓的担忧,多个州限制数据中心建设的公投获通过。此外招股书显示,截至 9 月 30 日止 12 个月内贡献至少 10 万美元收入的客户超 11900 家(一年前仅 950 家),但上半年约五分之一营收来自两大客户,且公司未披露 10 月营收,加剧投资者观望情绪。
1.OpenAI新一轮融资首期110亿美元已到账,投后估值1.25万亿美元,本轮总额最高或达200亿美元;较最初1.4万亿美元估值、300亿美元以上募资目标明显缩水,而2026年3月曾以8520亿美元估值募资1220亿美元,估值账面涨约47%。
2.Anthropic已递交S-1冲刺纳斯达克上市:营收从2025年全年约46亿美元跃升至2026年前三季度332亿美元,但前三季度净亏损1040.39亿美元(绝大部分为可转换票据等非现金公允价值变动),IPO估值预期由约2万亿美元缩水至1.2万亿至1.3万亿美元。
3.资本态度从“抢筹码”转向“看证据”:AI基建支出担忧叠加中期选举后数据中心阻力与AI股抛售,令头部AI公司融资与估值双双承压;Anthropic上市后的定价表现将成为全行业估值锚,OpenAI拟以模型安全换更优IPO窗口。
1.2026年11月5日美股AI板块集中去风险化:纳斯达克综合指数收跌约5.4%至5.5%,自10月6日纪录高点回撤逾10%、正式进入回调区间,标普500跌约4.4%,英伟达跌约9.3%,费城半导体指数盘中跌逾12%。直接导火索为民主党在中期选举中大胜,市场担忧AI监管收紧、数据中心建设放缓,抛售发生在选举结果出炉后的第2个交易日。
2.融资成本重估是本轮抛售的底层逻辑:评级最高的数据中心债券收益率从2026年初不足5%升至约7%,新云公司与高杠杆交易收益率全面进入两位数(Volta Infrastructure 50亿美元银团贷款利率被推高至11%以上,至少18笔数据中心高收益债/杠杆贷款以两位数定价)。配套背景是资本开支竞赛:四大云厂商2026年合计资本开支由约6000亿美元上修至最高7250亿美元,瑞银预计2027年达1.447万亿美元,且资金来源从自有现金转向债务(2025年五大云厂商发债1210亿美元,为2020至2024年年均280亿美元的四倍多)。
3.政治与物理瓶颈叠加:得州当选州长Gina Hinojosa承诺暂停所有新数据中心审批;高盛估计民主党可施限的州合计占美国规划数据中心产能约45%、得州独占约25%。许可、电力、芯片构成三大制约,甲骨文新墨西哥州Stargate数据中心因电力延迟发出不可抗力通知,约180亿美元相关贷款以面值89至91美分交易。由此呈现分化:已锁定电力与许可的运营商获定价权,依赖高杠杆、未锁关键资源的新云公司承压最重。
1.事件与背景:微软逐步关闭从甲骨文租用的部分算力并决定不再续签合同,原因是甲骨文服务器搭载较旧一代英伟达芯片、已不符合微软技术规格;同期微软收紧对CoreWeave、Nscale、Nebius等“新云”供应商审查、退出高风险项目,此前已向外部云企承诺超800亿美元租赁支出。甲骨文回应称AI基础设施需求仍强劲,并以高出原合同20%的价格续签了四年前购入的GPU租赁合同。
2.市场反应与数据:11月6日周五消息传出后,甲骨文盘中抹平3.8%涨幅、一度跌近5.2%至109.21美元,最终收涨0.82%至116.10美元;“新云”概念股早盘大涨后集体回吐涨幅,CoreWeave、IREN、Nebius收盘仍分别涨约6%、7.6%、20%。市场先恐慌后校正,反映收缩的是供应商筛选标准,而非算力总需求。
3.趋势与影响:AI基础设施采购逻辑由“规模优先”转向“交付优先”,建设瓶颈集中在电力接入、监管审批与设备交付;微软因能源接入审批障碍不行使Nscale得州项目约700兆瓦扩容选择权(原约240兆瓦合同及约1030亿美元订单积压不受影响),并退出其英国埃塞克斯郡约30亿美元项目,令Nscale寻求350亿美元IPO估值承压。
1.欧洲央行正考虑审查银行的AI数据中心贷款:11月6日彭博社报道,欧元区最高银行监管机构评估AI市场情绪变化与估值波动风险,审查或含现场检查,重点核查银行对未来现金流、抵押品价值及违约风险的评估,具体方案尚未敲定、范围可能小于2023年杠杆融资审查。
2.AI基建资本开支与信贷规模快速膨胀:高盛预计2025至2030年大型科技公司AI基建资本开支达5.3万亿美元(由4.5万亿上调);CreditSights估算2025年五大云厂商资本开支约4430亿美元、同比增73%,2026年约6020亿美元、其中约75%(即4500亿)投向AI基础设施;摩根士丹利估算数据中心相关证券化信贷约500亿美元(约三分之二为ABS、三分之一为CMBS),到2028年年发行量或超600亿,穆迪警告相关开发商杠杆或上升。
3.风险与承压方:数据中心贷款还款高度依赖“AI需求持续”与“电力供应跟上”两大假设,抵押品专用性强、清算变现难;若审查落地,高杠杆开发商及敞口较大的欧洲银行将率先承压,或面临拨备上调、资本占用增加、审批收紧与融资成本上升。摩根士丹利测算数据中心融资缺口达1.5万亿美元,资金或从最脆弱借款人流向资产负债表更稳健的玩家。
1.Meta于2026年11月初定价约250亿美元债券(美元与欧元双市场):美元档获约580亿美元峰值订单、超额认购近4倍,欧元档获530亿欧元订单、近6倍;但最长年期美元票据利差较六个月前的147个基点跳升至220个基点,风险溢价走阔73个基点,反映投资者开始为科技巨头的AI支出集中度风险要价。
2.Meta基本面同步恶化:2026年第三季度自由现金流-21.2亿美元,为2012年上市以来首次季度转负;营业利润率由40%腰斩至20%;当季资本支出349.1亿美元超过经营现金流327.9亿美元,并计入98.9亿美元青少年心理健康诉讼和解费用。标普10月底将其展望由“稳定”下调至“负面”(评级维持AA-),预测2026年自由现金流缺口约390亿美元、2027年或扩大至710亿美元。
3.行业融资范式结构性转移:五大超大规模云厂商2025年发债1210亿美元,远超2020至2024年年均280亿美元;高盛预计发债额2026年升至约2500亿美元、2027年约4000亿美元,占资本支出比重由26%升至约35%。资本成本上升正成为AI支出的硬约束,市场给Meta的隐形回报期限被设定为约两年内需出现现金流转正信号。
1.核心事件(2026年11月6日):Meta将Muse Wonder系列的“主动记忆”与“主动专注”全面部署到Muse个人AI助手及Meta AI平台,面向所有用户免费开放、无需升级或订阅;据Meta披露,主动记忆使目标信息遗忘率降低2.4倍,主动专注使突发状况下任务完成率提升67%。
2.底层支撑:该能力基于10月12日发布的Muse Wonder训练,依托Meta俄亥俄州New Albany的吉瓦级Prometheus超算集群,原生支持百万token上下文与多模态输入;集群经一年优化停机率下降99%,扎克伯格2025年7月称计划投入数千亿美元建AI数据中心,路易斯安那州Hyperion集群最终规模可达5GW。
3.竞争逻辑与风险:此举标志个人AI助手竞争从“谁更会说话”转向“谁更靠得住”,免费下放意在抢占用户入口、积累真实场景数据并抬高迁移成本(主动记忆构成习惯与上下文护城河);但记忆能力同时放大隐私与合规风险,Meta需在“记住更多”与用户可查看、修改、删除记忆之间取得平衡。
1.商业模式转型:马斯克在2026年11月6日第33届巴伦投资大会上表示,特斯拉Optimus倾向“只租不售”而非出售,意图把一次性硬件销售转为持续收费的劳动力服务,降低客户准入门槛并强化长期绑定,类似FSD订阅与Robotaxi的“产品变服务”逻辑。
2.成本与产能节奏:Optimus初期单台制造成本约3万美元、目标降至2万美元,远低于行业5万至10万美元估算;弗里蒙特工厂已于10月启动早期生产,产线按年产能100万台设计,但全面量产至少还需一年,外部客户交付最早要到2027年底,AI5芯片计划2027年4月接入。
3.效率卖点与风险:马斯克称Optimus最低生产力预期是普通工人的五倍,约2000万至3000万台可匹配美国全部生产产出;但租赁业务起步期面临高成本硬件与低租金挤压,且量产推迟、良率与真实工厂稳定性仍是该模式能否兑现的关键变量。
1.市场:11月5日美股科技股遭历史性抛售,纳指跌5.52%(创2025年4月以来最大单日跌幅)、标普500跌4.36%、道指跌3.44%,费城半导体指数暴跌12.25%;纳指市值缩水约2.5万亿美元,科技七巨头单日蒸发约1万亿美元(英伟达跌9.26%、特斯拉跌10.77%)。诱因为11月3日中期选举民主党大胜,市场担忧AI资本支出见顶。
2.民意与政策阻力:据Ballotpedia统计,与中期选举同日投票的41项数据中心相关议案中40项对数据中心不利;CBS民调显示反对本地新建数据中心者超支持者两倍以上;Data Center Watch数据显示2026年二季度至少45个、总值880亿美元的项目因地方反对受扰。三名新当选州长(得州、佐治亚、俄亥俄)均承诺暂停或有条件暂停新数据中心建设。
3.巨头策略分化:OpenAI首席财务官弗莱尔11月6日在花旗峰会称将继续推进美国数据中心扩张,公司已于11月5日发布“全国社区契约”框架;谷歌宣布投资170亿美元在怀俄明州拉勒米县建数据中心并全额承担电力成本;微软则拒绝扩大与Nscale在得克萨斯州的数据中心协议,转向收缩。
开源趋势:
1.生态数据与趋势:2026年11月6日英伟达披露,AI Aerial与Sionna全球开发者采用量增长10倍,开源5G/6G工具下载量突破100万次,超8000家研究学术机构使用;标志6G竞争从标准博弈前移为生态博弈。
2.研究案例与数据:其工具链落地四类场景——伦敦国王学院目标导向语义通信使任务完成时间最多缩短52.6%;软银神经接收机上行吞吐最大增益约60%,苏黎世联邦理工本地微调使块错误率降低超三分之一;利兹大学基站睡眠决策令RAN功耗下降45.6%;加泰罗尼亚电信技术中心GPU加速仿真时间从约3小时压至10到20分钟。
3.观点与影响:英伟达不造基站、不争标准席位,而是以开源工具链(AI Aerial、Sionna、ACAR等)培养研究者技术习惯,争夺AI-native 6G“操作系统层”定义权,将自身由数据中心算力供应商转变为6G网络的底层基础设施。
1.观点+结论:AWS于2026年11月初发布博客《Taxonomy of agentic primitives in Amazon Quick》,用When(何时)、What(做什么)、Who(谁来做)、How(怎么做)四问把agent工作拆解为Trigger、Agent、Capabilities等原语,标志agent基础设施竞争从“谁能把agent跑起来”转向“谁能给agent立规矩”。
2.观点+定义:AWS将agent定义为“persistent, le

2026年,黄金为什么没当好避险资产?
(本文作者为 好望角,钛媒体经授权发布)
文 | 好望角
所谓乱世买黄金。
2022年俄乌冲突爆发后,金价一度在两周内冲上2000美元。
这句话在今年似乎不灵了。
毫无疑问,2026年是一个战火不断的年份。2月底,美以伊冲突爆发,霍尔木兹海峡航运受阻,国际油价一度冲上119美元/桶。到了11月,海峡里的袭船事件仍时有发生。
1月29日,现货黄金创下5595美元/盎司的历史高点,此后一路走低,10月30日跌破4000美元,11月初盘中最低探到3874美元。中信证券统计,金价年内最大跌幅达到28.3%。
有美国财经媒体总结,今年大部分时间里,黄金和比特币是市场上表现最差的两类资产。
本周金价反弹了一把。美国中期选举后美元走弱,金价单日涨超3.5%,一度回到4147美元。随后一份强劲的非农数据,又让它退回4050美元附近。
一个打了大半年仗的年份,为什么避险资产跌掉近三成?
一条反向的传导链
过去几十年的逻辑是,冲突爆发,资金避险,金价上涨。今年地缘冲突的传导链变反了。
第一环:打仗推高油价。 这场冲突的核心在霍尔木兹海峡。这条海峡最窄处只有几十公里,全球约五分之一的石油海运要从这里经过。航运一受阻,油轮出不来,市场上的油就少了,国际油价一度冲上119美元/桶。
第二环:油价推高通胀。 石油是几乎所有商品的上游。卡车运货要烧柴油,飞机要烧航油,化肥、塑料、化纤都从油气里来。油价一涨,运费、机票、超市货架上的东西都会跟着慢慢涨价。市场一度预计美国5月CPI同比升至4.2%,远高于美联储2%的目标。
第三环:通胀逼美联储加息。 美联储的主要任务之一是管住物价。物价涨得太快,它的办法是提高利率:借钱变贵,企业少投资,家庭少消费,需求降下来,物价就涨得慢一些。年初市场普遍押注2026年降息两到三次。3月议息会议后,降息预期被大幅下调。新任主席凯文·沃什上任后,市场对他偏鸽的期待很快落空。6月初一份强劲的非农报告,让降息讨论基本退场。9月,美联储加息25个基点,把联邦基金利率上调到3.75%-4.00%。
第四环:加息抬高持有黄金的成本。 黄金放在保险柜里,不会生利息。利率低的时候,这算不上什么损失。利率高了,同样一笔钱存银行、买国债,每年能稳拿4%到5%。拿着黄金,就等于每年主动放弃这笔利息。
这里要看的是实际利率,也就是名义利率减去通胀,衡量的是扣掉物价上涨以后,存钱实打实能多拿多少。2月27日,10年期美债实际收益率跌到1.72%,为年内低点,那时金价还在高位。此后实际利率一路震荡上行,金价随之进入下行通道。
第五环:资金离开黄金,金价下跌。 机会成本一高,基金经理就会把一部分钱从黄金挪到债券和存款里。卖的人多了,金价就往下走。
把五个环节连起来:地缘冲突推高油价,油价推高通胀,通胀推高利率,利率压低金价。
打仗本身对黄金是利好,恐慌情绪会让一部分人去买金。可打仗带来的通胀和加息,对黄金是更大的利空。两股力量同时作用,后者占了上风。打个比方,战争给黄金加了一分,战争引发的加息又给黄金减了两分。
2022年的情况正好相反。俄乌冲突爆发时,美联储还没开始加息,利率接近零,持有黄金几乎没有机会成本,避险资金可以放心涌进来。今年冲突发生时,利率本来就不低,而且还在往上走。
这种情况在历史上有过先例。1980年代初,美联储为压通胀大幅加息,中东局势同样紧张,金价却从1980年的高点跌去了一半以上。
避险资金去了美元
可以把全球的避险资金想象成一笔在找停车位的钱。打仗了,大家都想把钱停到一个安全的地方。今年可选的车位有好几个:黄金、美元、美国国债、原油。哪个车位更划算,钱就往哪里去。
3月以来,美元指数从103下方一路走强,5月初重回106。原因有两层。
第一层是利息。美联储在加息,持有美元资产能拿到的利息越来越高。同样是避险,放在美元里每年还能拿到接近4%的利息,放在黄金里一分利息都没有。
第二层是用途。全球石油和大宗商品大多用美元结算,打仗时企业和机构要囤美元付货款、还债务,美元的需求本身就会上升。
美元走强,对黄金是双重打击。
第一重是计价。国际金价用美元标价。假设金价不变,美元升值10%,对手里拿着人民币、卢比、欧元的人来说,同样一克黄金就贵了将近10%。买得起的人少了,需求就弱了。中国和印度是全球最大的两个黄金消费国。三季度,全球金饰需求跌到313吨,同比下降17%,是有数据以来三季度的最低水平。
第二重是比较。美元本身就是一种避险资产。它在涨,避险的人就少了一个去买黄金的理由。
再说美债。
买美债,可以理解为借钱给美国政府,到期收回本金和利息。利率上升以后,新买的美债利息更高。今年美债收益率一度升到二十年来的高位,10年期接近5%。
一位养老基金经理面前摆着两个选择:一边是每年稳拿将近5%利息、违约风险很低的美债;一边是不生息、价格还在往下走的黄金。大多数人会选前者。二季度,全球黄金ETF出现净流出,钱从黄金搬进了债券和货币基金。
最后说原油。这场冲突的核心在霍尔木兹海峡,直接冲击的是石油供应。对一家航空公司、一家化工厂来说,真正担心的是油价继续上涨。最直接的对冲办法是买原油期货或者能源股:油价涨了,这部分持仓赚的钱可以抵掉成本的上升。黄金也能对冲风险,但它和油价之间隔了好几层。风险从哪里来,资金就往离风险最近的资产去。一部分原本会流向黄金的避险需求,就这样被能源资产分走了。
所以今年的情况是:避险的钱一直都在,只是黄金在几个车位里排不到前面。美元有利息,美债有利息,原油离风险更近,这三样黄金都不占。
黄金越来越像一只股票
2023年到2025年,金价年涨幅分别是17.7%、28.3%和58.5%,三年里涨了一倍多。牛市后期,入场资金的构成变了。量化基金、趋势交易者、杠杆资金大量涌入,黄金的持仓变得拥挤。这类资金买黄金,看中的是动量,持有逻辑和股票相近。
结果是,黄金和股票的走势越来越同步。Capital Economics的大宗商品经济学家Hamad Hussain在11月初提醒,黄金与股市的正相关性在增强,科技股走弱也会拖累金价。
这种同步在市场紧张时尤其明显。股市大跌时,投资者需要补保证金、回笼现金,最先卖出的往往是流动性好、账面盈利厚的资产。黄金正好符合这两个条件。
11月6日,华尔街出现集中抛售,金价随之一度下探到4035美元附近。类似的情况在2008年金融危机初期、2020年3月疫情冲击时都出现过:危机最紧张的那几周,黄金也会被一起卖掉。
今年4月下旬,伦敦金录得1983年以来最大的单周跌幅。技术面破位之后,止损盘集中出逃,下跌被进一步放大。在这类时刻,黄金作为交易品种的一面,盖过了它作为避险资产的一面。
黄金对冲的是什么
总之,黄金对冲的核心风险,是货币信用被稀释:财政赤字失控、央行被迫宽松、法币购买力持续下降。
2024年到2025年的大牛市,主要驱动正是这些因素。美国不断扩大的财政赤字和债务路径,让全球资金和各国央行开始重新评估美元资产的安全性。
黄金很难对冲的,是另一类风险:通胀冲击下的加息周期。在这种环境里,现金和短债有了像样的收益,美元走强,黄金的机会成本快速上升。今年的中东冲突恰好落在这一类。它带来的主要是能源通胀,随后是加息。
本周的行情把这两类风险放进了同一张图里。中期选举结果出来后,市场担心美国财政前景,美元走弱,金价大涨。两天后,一份强劲的就业数据强化了加息预期,金价随即回落。前一种风险推高金价,后一种压低金价。
这也解释了“乱世买黄金”为什么在今年失灵。乱世有很多种。黄金适合应对的是信用和货币层面的乱,对通胀和利率层面的乱,它的防守能力有限。
世界银行最新预计,2027年金价可能在4250美元附近,仍处历史高位,但很难再现2026年那样的大起大落。
中信证券认为,明年金价大概率在波动中上行。决定方向的,依然是美联储的利率路径,以及市场对美国财政的信心。
黄金很难对冲一场战争的直接冲击。它更擅长对冲的,是战争结束以后,各国为它印出来的那些钱。
更多精彩内容,关注钛媒体微信号(ID:taimeiti),或者下载钛媒体App
中国白酒出口韩国暴涨85%,谁在买?
(本文作者为 好望角,钛媒体经授权发布)
文 | 好望角
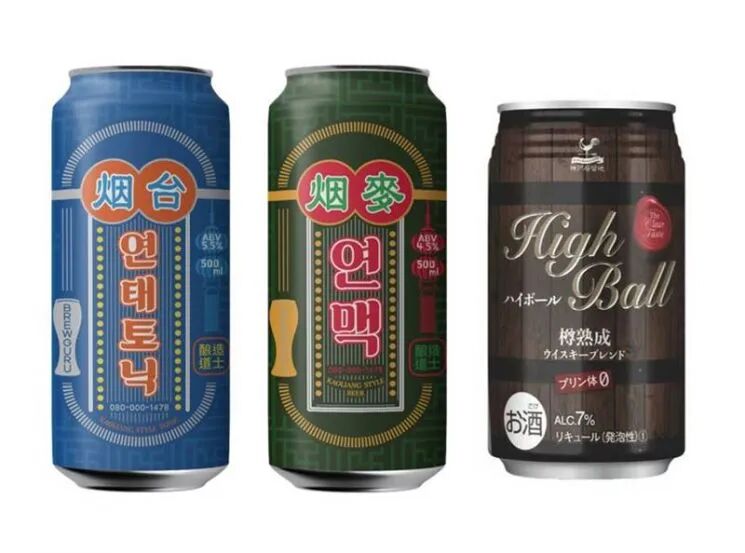
韩国的CU便利店卖过一款罐装Highball,名字叫“烟台汤力”。5.5度,喝起来有一股明显的高粱香。
2023年,韩国媒体翻看了它的配料表,发现罐子里的基酒是韩国本地的食用酒精,跟烟台高粱酒并无关系。厂商的解释很简单:烟台是一个中国地名,拿来做产品名称没有问题。
这件小事说明了一个变化。在韩国,“烟台”已经从一座城市的名字,变成了一种口味。
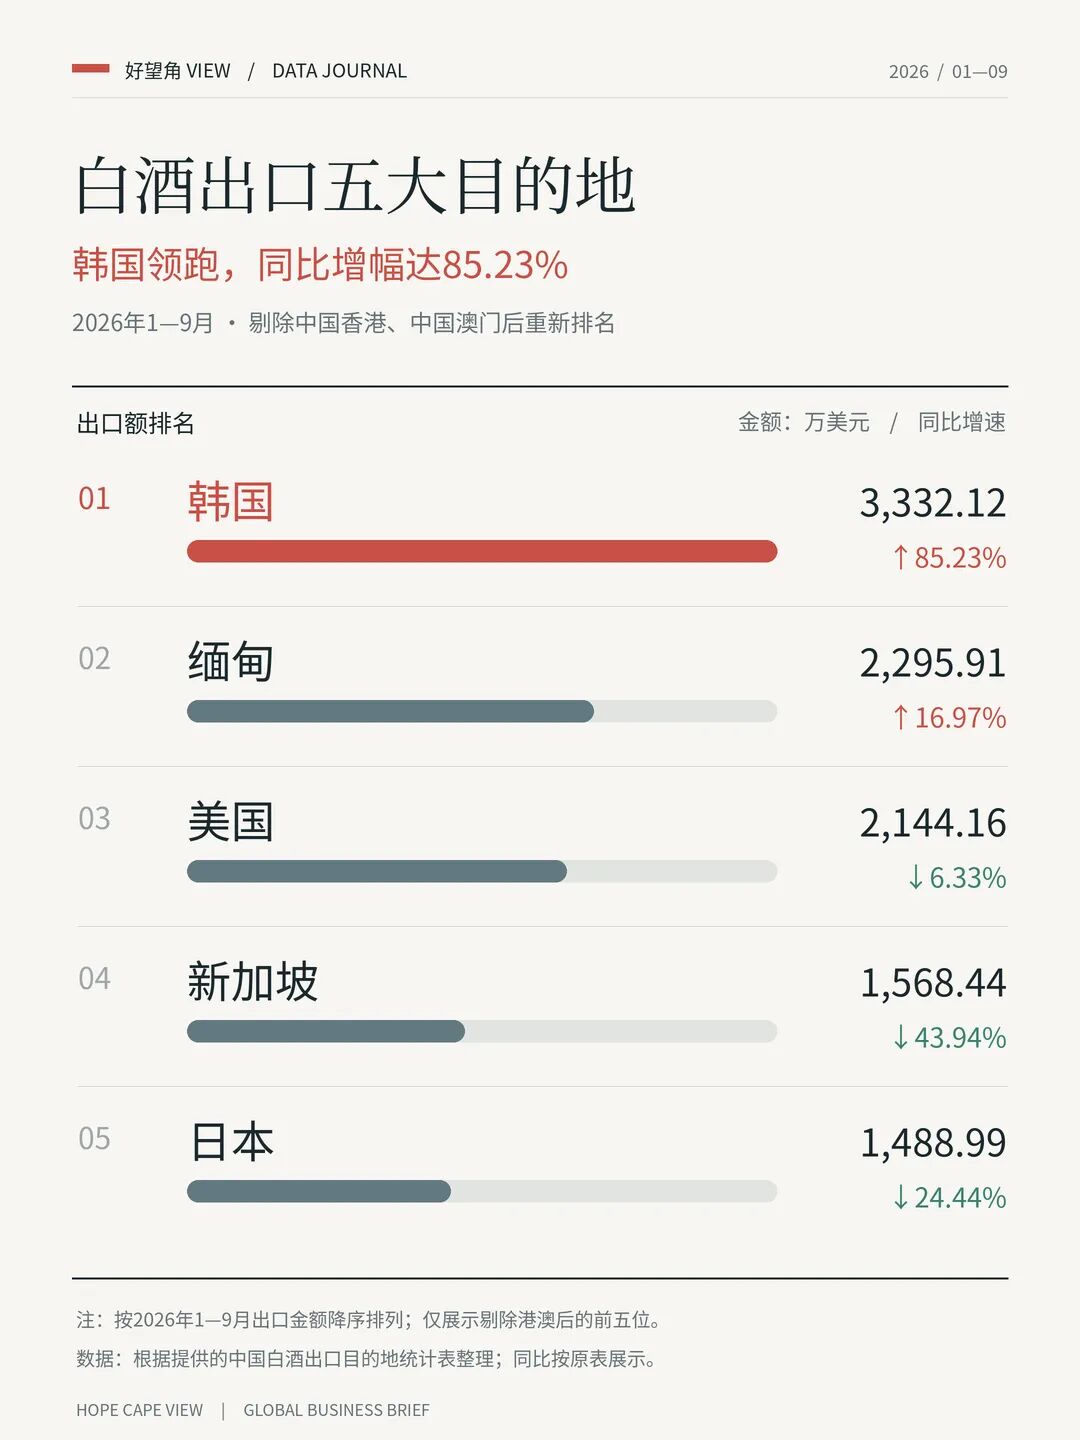
今年中国白酒出口整体在收缩,上半年出口额2.83亿美元,同比下降46.6%。韩国是少数逆势增长的市场。前9个月,中国对韩国的白酒出口额达到3332万美元,同比增长85%。韩国超过澳门,成为仅次于香港的第二大出口目的地。
出口数字之外,韩国市场更值得关注的,是韩国人喝白酒的方式。在中国,白酒属于宴席、小杯和干杯。在韩国,它正在被加冰、兑汤力水、装进易拉罐,在便利店里卖给二三十岁的年轻人。
韩国是少有的,白酒消费者以当地人为主的海外市场
烟台高粱酒在韩国中餐馆里待了几十年。韩国人习惯拿它配炸酱面、糖醋肉,老一辈还沿用“白干”的叫法,韩语读作“빼갈”。在韩国的酒类零售网站上,一瓶500毫升的烟台高粱酒卖1.5万韩元左右,评论区几乎全是韩语。
烟台高粱酒在韩国的位置,来自一段一百多年的移民史。
1882年以后,山东商人和劳工经海路来到朝鲜半岛,在仁川等通商口岸落脚。1883年朝鲜境内的华侨只有166人,十年后增至2182人。他们大多来自胶东半岛,开起了最早的一批中餐馆。
韩国的炸酱面就诞生在仁川的这批馆子里,2006年还被韩国文化观光部列入代表韩国的100个民族文化象征。
山东人带来了山东菜,也带来了山东的高粱酒。韩国人心中中国白酒的原型,因此是胶东一带的清香型高粱酒。
后来到了1961年,韩国施行《外国人土地法》,1968年修订后,外国人只能拥有200坪以内的居住用地和50坪以内的商业用地。华侨的经商空间被大幅压缩,很多人移居台湾和美国。据韩国华侨团体的说法,如今生活在美国的韩国华侨,比留在韩国的还多。
华侨走了,中餐馆留了下来。越来越多的中餐馆由韩国人经营,顾客也一直是韩国人。高粱酒在韩国的“去华人化”,几十年前就随着中餐馆易手完成了。这让韩国成为少见的、白酒消费者以当地人为主的海外市场。
这几年,它的喝法变了。
一种叫“烟啤”,高粱酒兑啤酒,思路和韩国人熟悉的“烧啤”一样。另一种是Highball,高粱酒兑汤力水或苏打水。韩国一家酒类电商在商品页上直接印了配方:烟台高粱酒和汤力水按1比2或1比3混合,再加一片柠檬。不少买家在评论里说,兑汤力水最好喝,还有人说配麻辣香锅正合适。

这套喝法来自威士忌。2022年以后,Highball在韩国年轻人中迅速流行。韩国便利店CU的数据显示,2023年Highball销售额同比增长553.7%,在洋酒类销售中的占比超过了葡萄酒。韩国二三十岁的消费者逐渐放弃“喝醉为止”的烧酒酒局,转向度数低、能慢慢喝的混饮。
韩国人把这套方法套在了中国高粱酒上。便利店随后跟进。
2026年1月30日,7-Eleven推出了与韩国中餐名厨후덕죽合作的柚子高粱Highball,同期还上架了另一位名厨的覆盆子Highball。三周之内,两款产品合计卖出20万罐,在Highball品类里排名第一和第二。
这些产品的设计者是韩国的便利店、厨师和进口商。中国酒企在中国卖白酒的方式,在这里基本用不上。
为什么韩国人会兑着喝
白酒在欧美推广困难,核心原因是当地缺少对应的喝法。50度以上的透明烈酒,香气浓烈,配着菜纯饮,这套方式在西方的饮酒习惯里找不到位置。
韩国有现成的位置。
第一,烧酒本身就是蒸馏谷物酒。韩国人熟悉透明、高度、佐餐的谷物烈酒,接受白酒的门槛比欧美消费者低得多。
第二,烧酒兑啤酒的“烧啤”是韩国的国民喝法。“烟啤”直接沿用了这套语法,只是把烧酒换成了高粱酒。
第三,Highball教会了年轻人“烈酒加汽水”。威士忌能这样喝,高粱酒也能。
兑饮还解决了白酒出海最大的障碍:香气。外国消费者对白酒最常见的反应是香气过冲。加了汤力水和冰块,香气被稀释成一种风味点缀,罐装产品的度数也降到5度上下,和啤酒差不多。
烟台高粱酒属于清香型,香气本来就淡,最适合兑饮。
在国内价格越低、越“不高级”的清香型高粱酒,在海外越容易被接受;国内最贵的酱香型,香气最复杂,出海门槛也最高。白酒的国内价格体系,到了海外几乎是倒过来的。
税制强化了这种选择。韩国对蒸馏酒征收72%的酒税,再按酒税的30%征收教育税,最后加10%增值税。一瓶进口完税价格100元的白酒,交完这几项税就到了213元左右,还没算进口商、批发和零售的加价。
从价计征意味着酒越贵,税越重。用便宜的高粱酒做基酒兑着喝,是韩国消费者在高税负下最划算的方式。
从中餐馆走进便利店和百货店
变化也发生在渠道上。
GS25的酒类线上预订平台Wine25 Plus,2025年上半年清酒和白酒的销售额同比增长250.1%,占平台酒类销售的15%,第一次达到两位数。卖得好的白酒是天之蓝、洋河大曲这类降度后口感更柔和的产品。
买家的年龄也在变。GS Retail的数据显示,清酒和白酒的消费者过去集中在40岁以上,2025年上半年,二三十岁消费者的占比升到35%左右。
GS Retail给出的原因之一是出境游:韩国人去日本、去中国旅行,回国后想在家里再喝到当地的酒。中国从2024年11月起对韩国公民免签,2025年中国成了韩国人出境游的首选目的地。
高端产品走的是另一条路。韩国最大的烧酒企业海特真露(HiteJinro)从2024年开始代理水井坊的三款高端产品,铺进大型超市、百货店、酒类专卖店和高端中餐厅,瓶身贴了防伪认证标签。一家韩国烧酒巨头帮中国白酒铺货,这在过去很少见。
名人也在起作用。歌手PSY在成始璄的YouTube节目里夸过梦之蓝。韩国的中餐也在升级,从街边的炸酱面馆扩展到点心、川菜和中餐fine dining。喝惯了威士忌和清酒的三四十岁消费者,开始按香型、工艺和品牌挑白酒。
这些变化反映在韩国的进口数据里。韩国酒类进口协会根据关税厅数据统计,2026年1到5月,韩国高粱酒进口额841.6万美元,同比增长19.8%,进口量基本持平。
平均进口单价从每升2.37美元涨到2.84美元。量没涨,价涨了,说明更贵的产品占比在提高。
韩国的白酒市场由此分成两层:
一层是便宜的大众高粱酒,在便利店和中餐馆里兑着喝;
另一层是价格很高的名酒,用于宴请、送礼和高端餐饮。
韩国媒体分析,进口单价的上涨主要来自后一层占比的提高。
本地化由韩国人完成
中国酒企也注意到了韩国的变化。五粮液在韩国推出过Highball气泡酒,水井坊选择了海特真露做代理。
但从“烟台汤力”到名厨联名的高粱Highball,把白酒改造成韩国口味的,主要是韩国的便利店、餐饮企业和进口商。
韩国人做这件事驾轻就熟,因为他们刚用同样的办法把烧酒卖到了海外。2024年韩国烧酒出口额首次超过2亿美元,其中果味烧酒出口额创下9600万美元的纪录。
果味烧酒降低度数、加入水果风味,专为不习惯烧酒酒精味的外国消费者设计。韩国人推销本国烈酒的方法,被原样用在了中国白酒身上。
这类事情在别的烈酒身上也发生过。威士忌在日本一度被看作中年人的酒,2008年以后,三得利推动角瓶兑苏打水的Highball进入居酒屋,带动了威士忌消费回升。龙舌兰在美国的普及,也主要靠玛格丽特鸡尾酒,纯饮是后来的事。
外国烈酒进入一个新市场,大致要走三步。第一步卖给移民社区,第二步进入民族餐馆、卖给当地食客,第三步离开餐馆,被当地人改造后进入零售。
过去几年,白酒出海主要依靠国内高端白酒的价格体系、海外华人社区和礼赠需求,大多停留在前两步。今年出口额的回落,和这几股力量的变化直接相关。韩国是少数已经走到第三步的市场。
第三步也带来了一个新问题:价值归谁。
开头那罐“烟台汤力”就是一个例子。产品借用了烟台的名字,罐子里用的是韩国的酒精。中国高粱酒在韩国积累了一百多年的认知,被韩国便利店直接拿来变现。
韩国便利店掌握消费数据,能快速开发新品,实际上扮演了白酒在韩国的本地化研发部门。谁完成了本地化,渠道利润和品牌溢价就更多流向谁。
韩国的规模还很小。韩国一年进口的高粱酒不到2000万美元,比茅台任何一个季度的海外收入都少。但它给白酒出海提供了一个难得的样本:当地人愿意喝,也找到了自己的喝法。
中国酒企接下来要解决的问题,是在韩国人改造白酒的过程中,拿到更多的话语权和利润。
更多精彩内容,关注钛媒体微信号(ID:taimeiti),或者下载钛媒体App
13 万买 5 米大轿车!比亚迪海豹 07 上市,首搭云辇-M 磁流变悬架
2005 年,代号 C6 的第二代国产奥迪 A6L 正式上市。在这一代车型上,一汽奥迪将轴距进一步加长 102 毫米,让这款行政轿车的车长首次迈过五米大关。
此后很长一段时间里,五米级车身几乎都与商务接待、行政座驾绑定在一起,售价动辄四五十万元,并不是普通家庭轻易能够触及的选择。
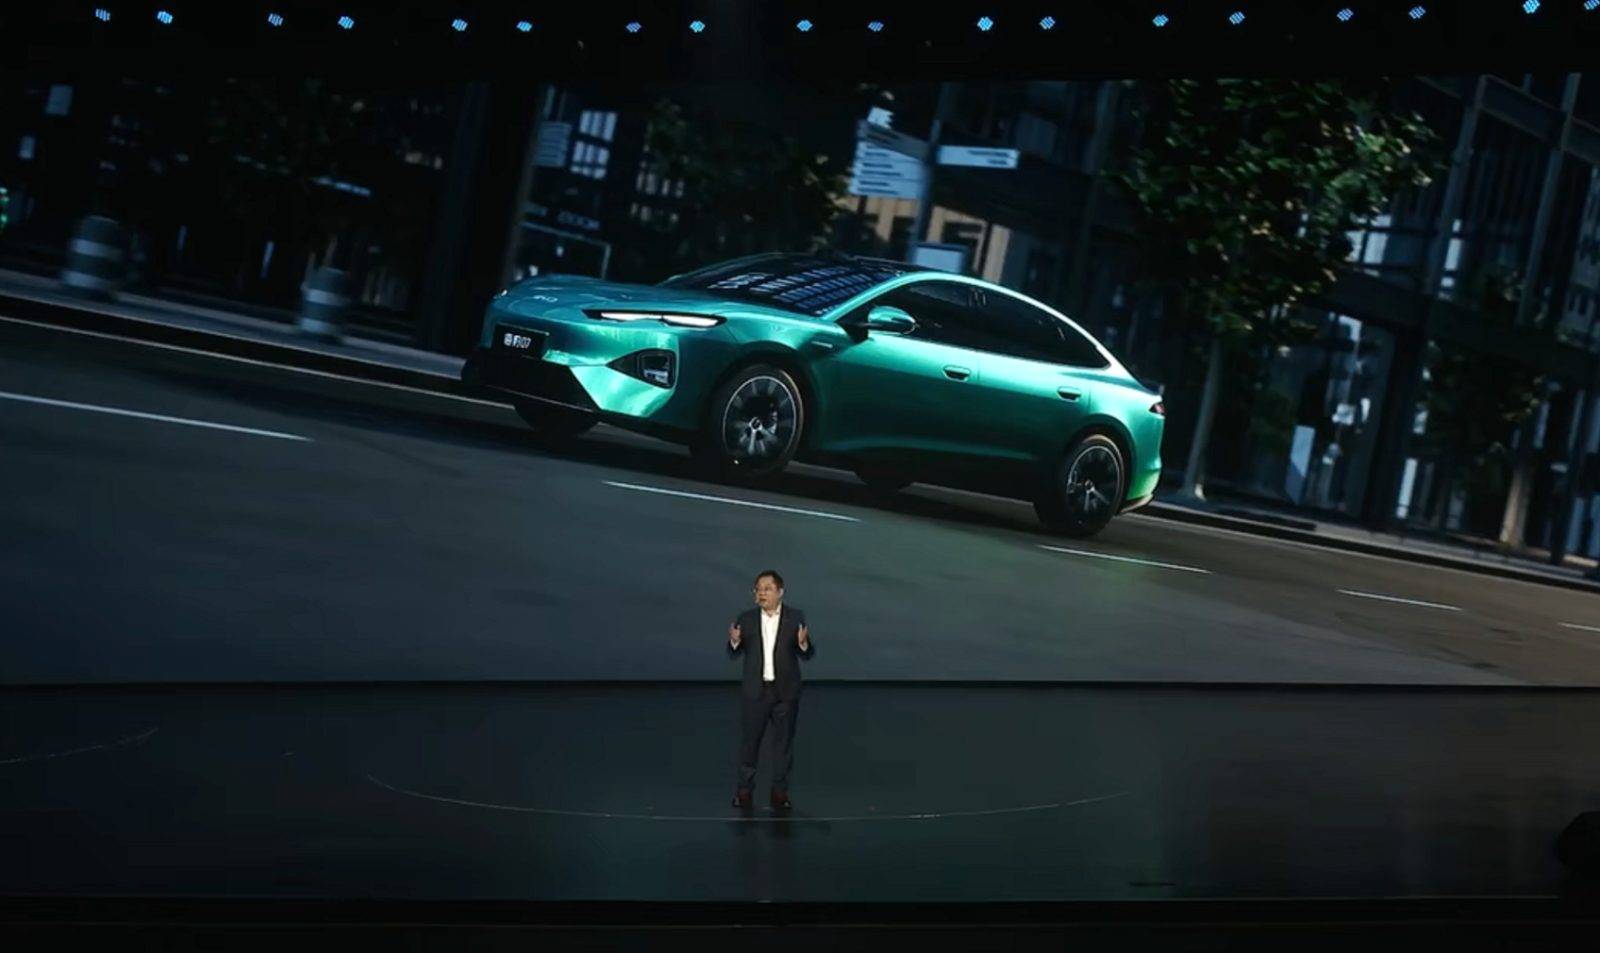
而今晚上市的比亚迪全新海豹 07,把这样的车身尺寸,带进了 15 万元级市场。
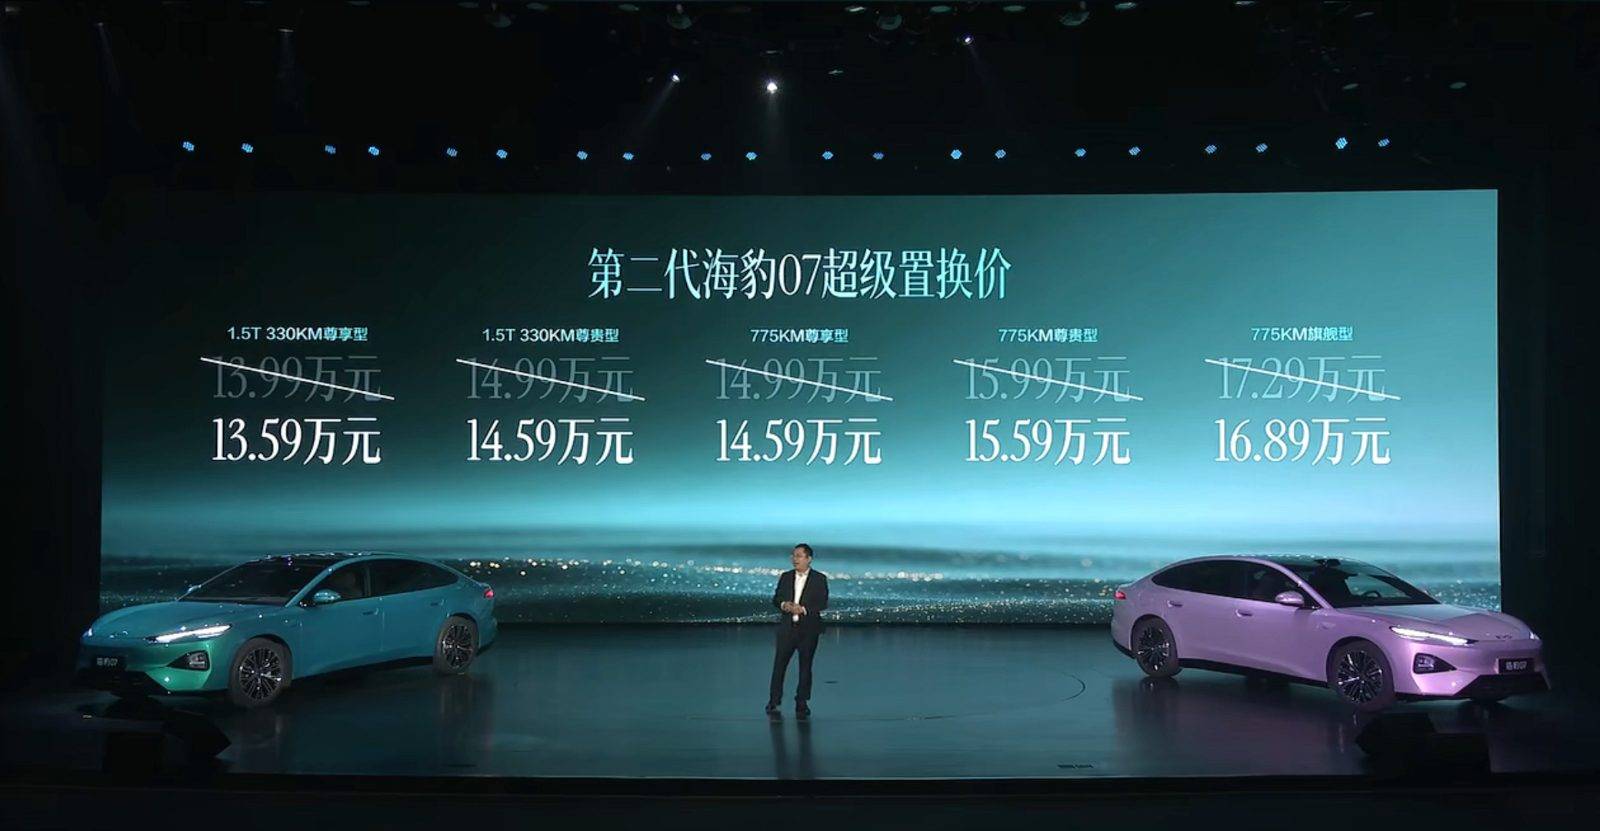
全新海豹 07 提供插混和纯电两种动力,共五款配置,官方指导价为 13.99 万至 17.29 万元。叠加置换补贴后,起售价进一步降至 13.59 万元。
与此同时,磁流变阻尼悬架、最长 330 公里的纯电续航等配置,也被放进了这个价格区间。
大,只是它的起点
车长超过五米,最直接的好处当然是空间。但全新海豹 07 并没有把所有功夫都花在一个「大」字上。
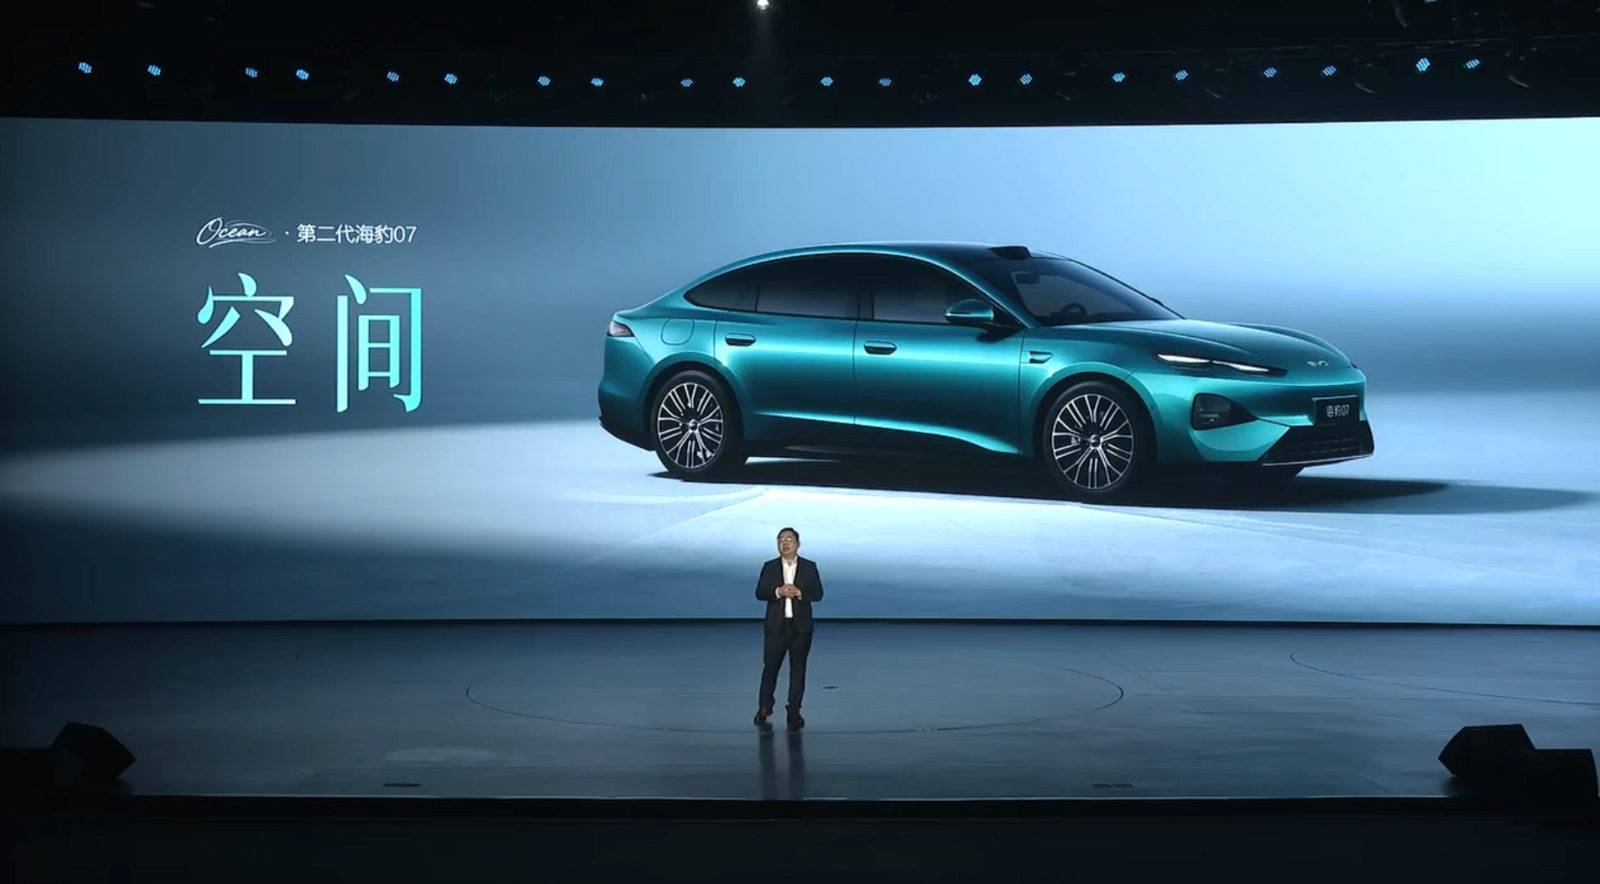
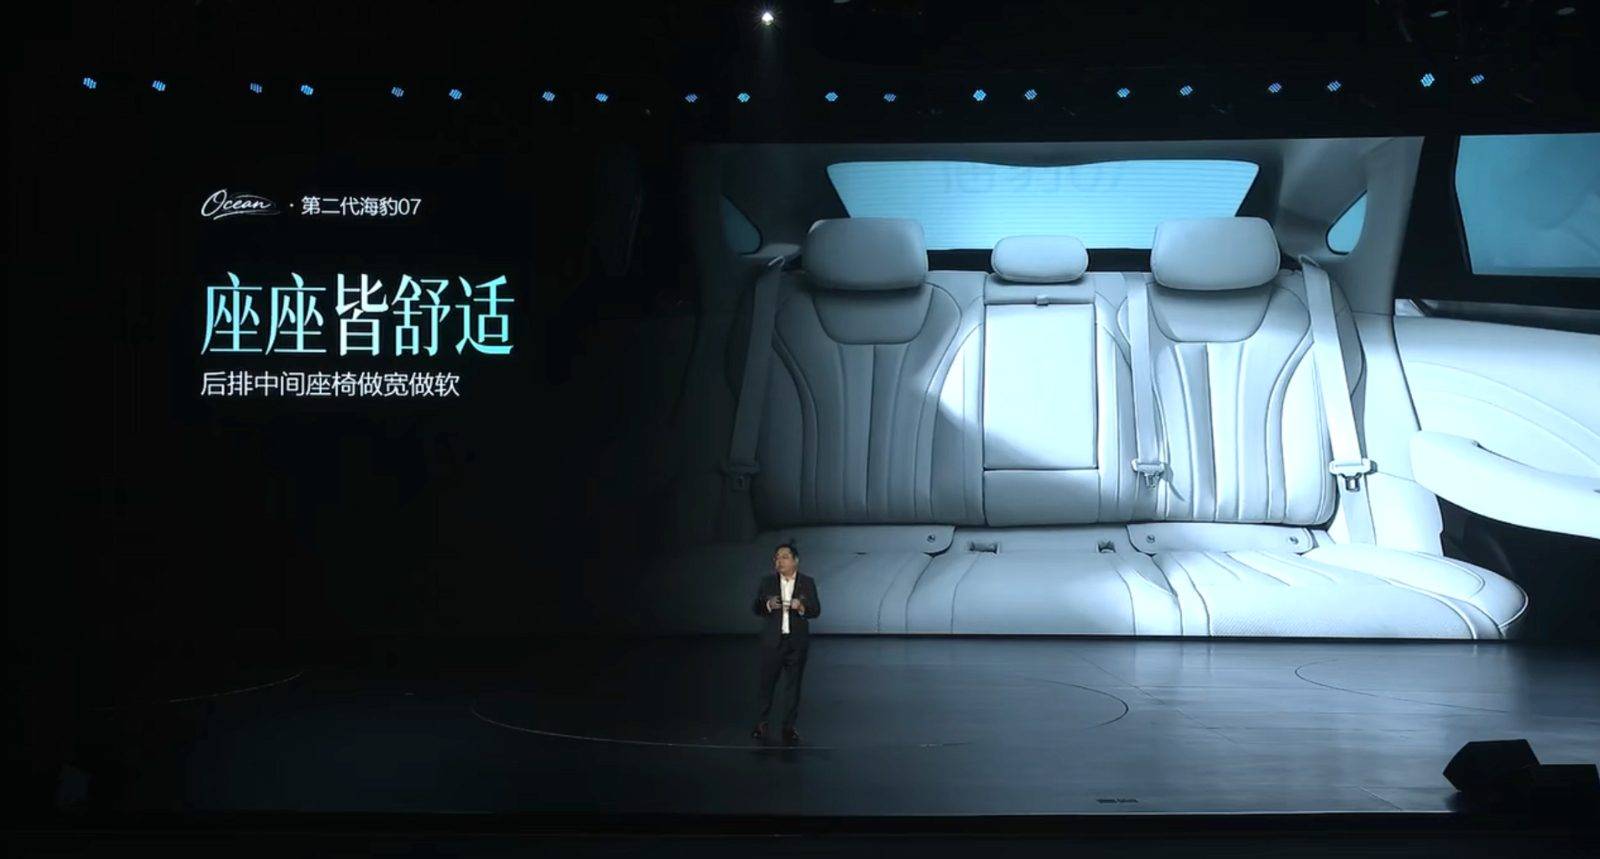
它的车长达到 5080 毫米,轴距为 2960 毫米,后排腿部空间达到 961 毫米,很多轿车容易忽略的后排中间座位,海豹 07 这次也专门进行了加宽、加厚。
这意味着一家五口出门时,坐在后排中间的人不必再一路将就。对于一辆强调家庭使用场景的轿车来说,这种不太显眼的细节,往往比单纯多出几厘米腿部空间更有意义。
海豹 07 的装载能力同样围绕一家人的出行展开。
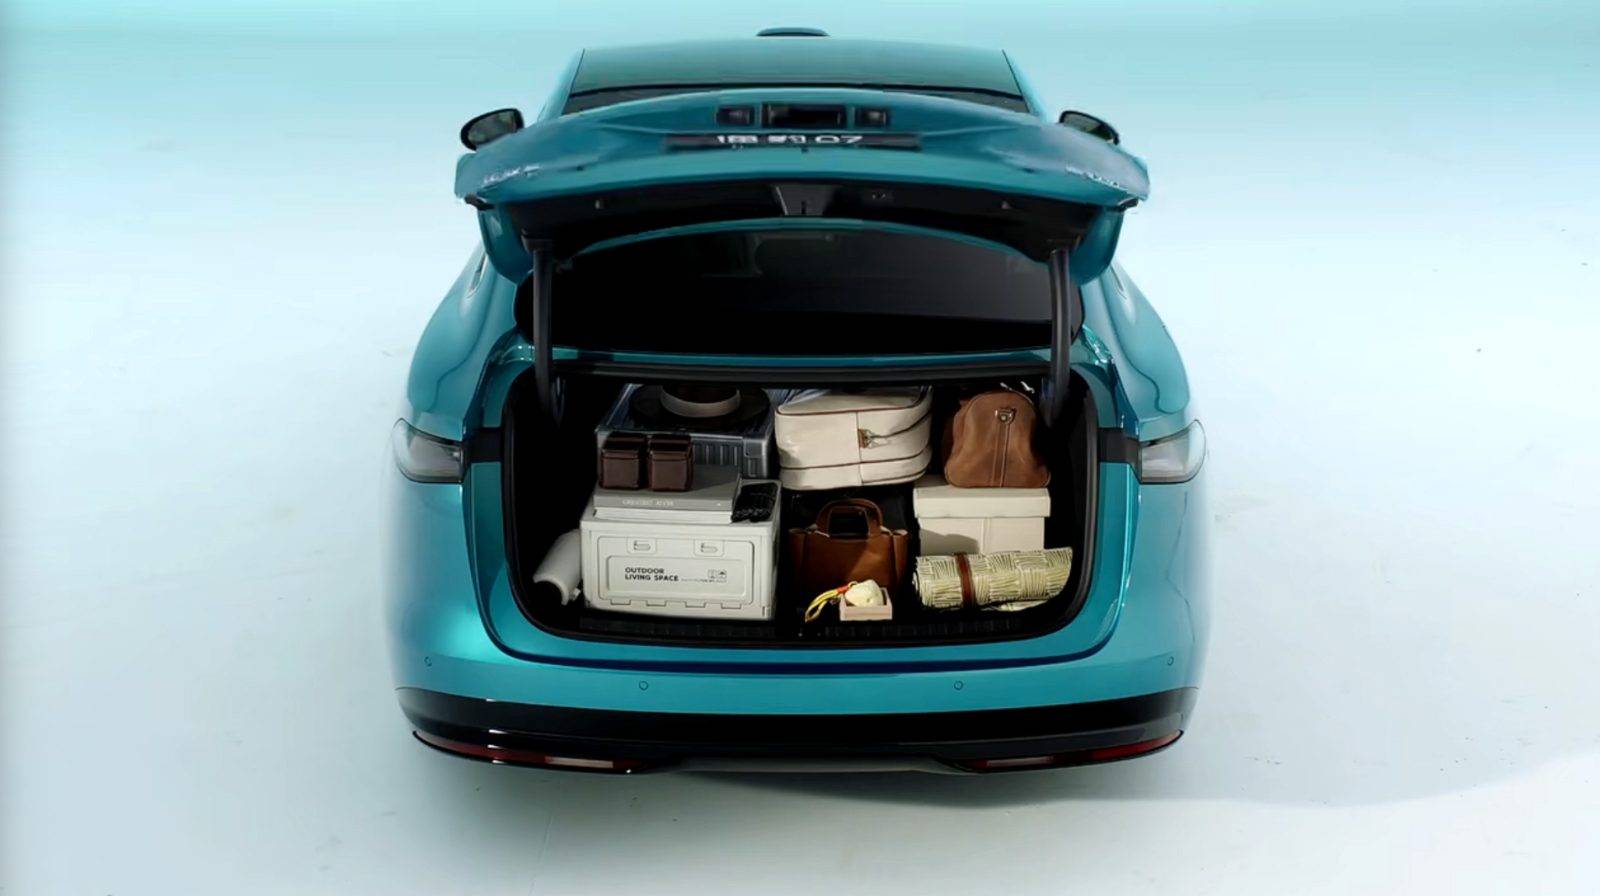
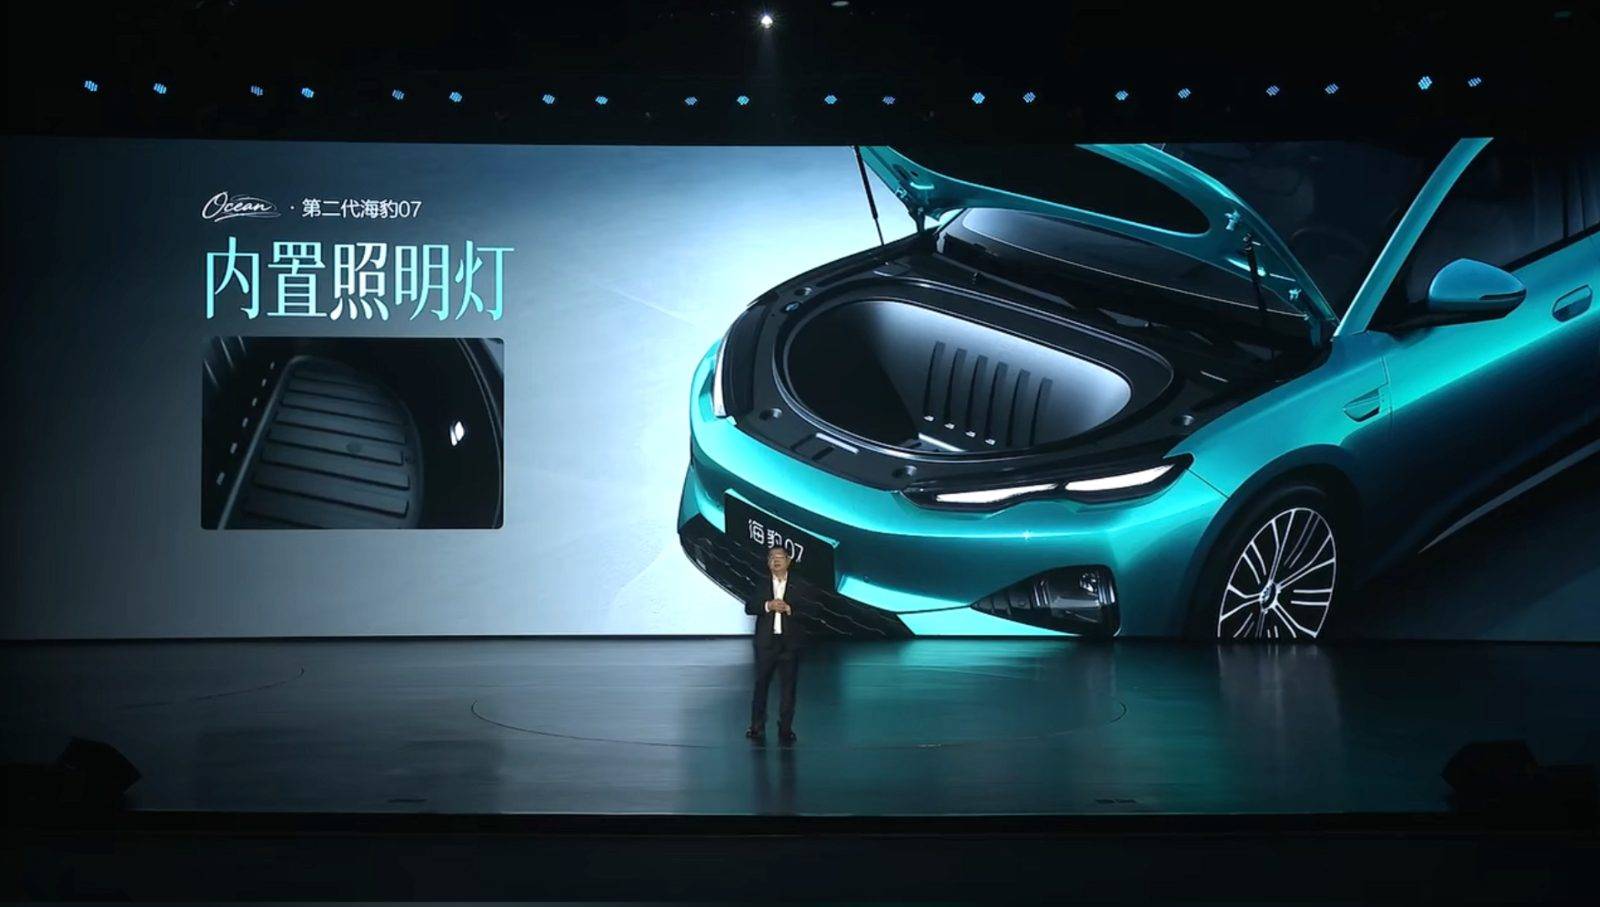
618L 后备厢完全可以装下五个登机箱,后备厢门槛高度也仅有 63 厘米,装卸重物较为方便。纯电版还额外提供一个 160 升前备厢,同级最大,没有之一。
更重要的是,比亚迪这次不仅做到「有」,还实现了「好用」。
海豹 07 的前备厢内部设有导水槽,清洗起来比较方便;独立照明灯的设计也便于用户在光线不足的条件下取放物品。
全新海豹 07 的另一项重要变化,则要等车轮真正压上路面之后才能感受到。
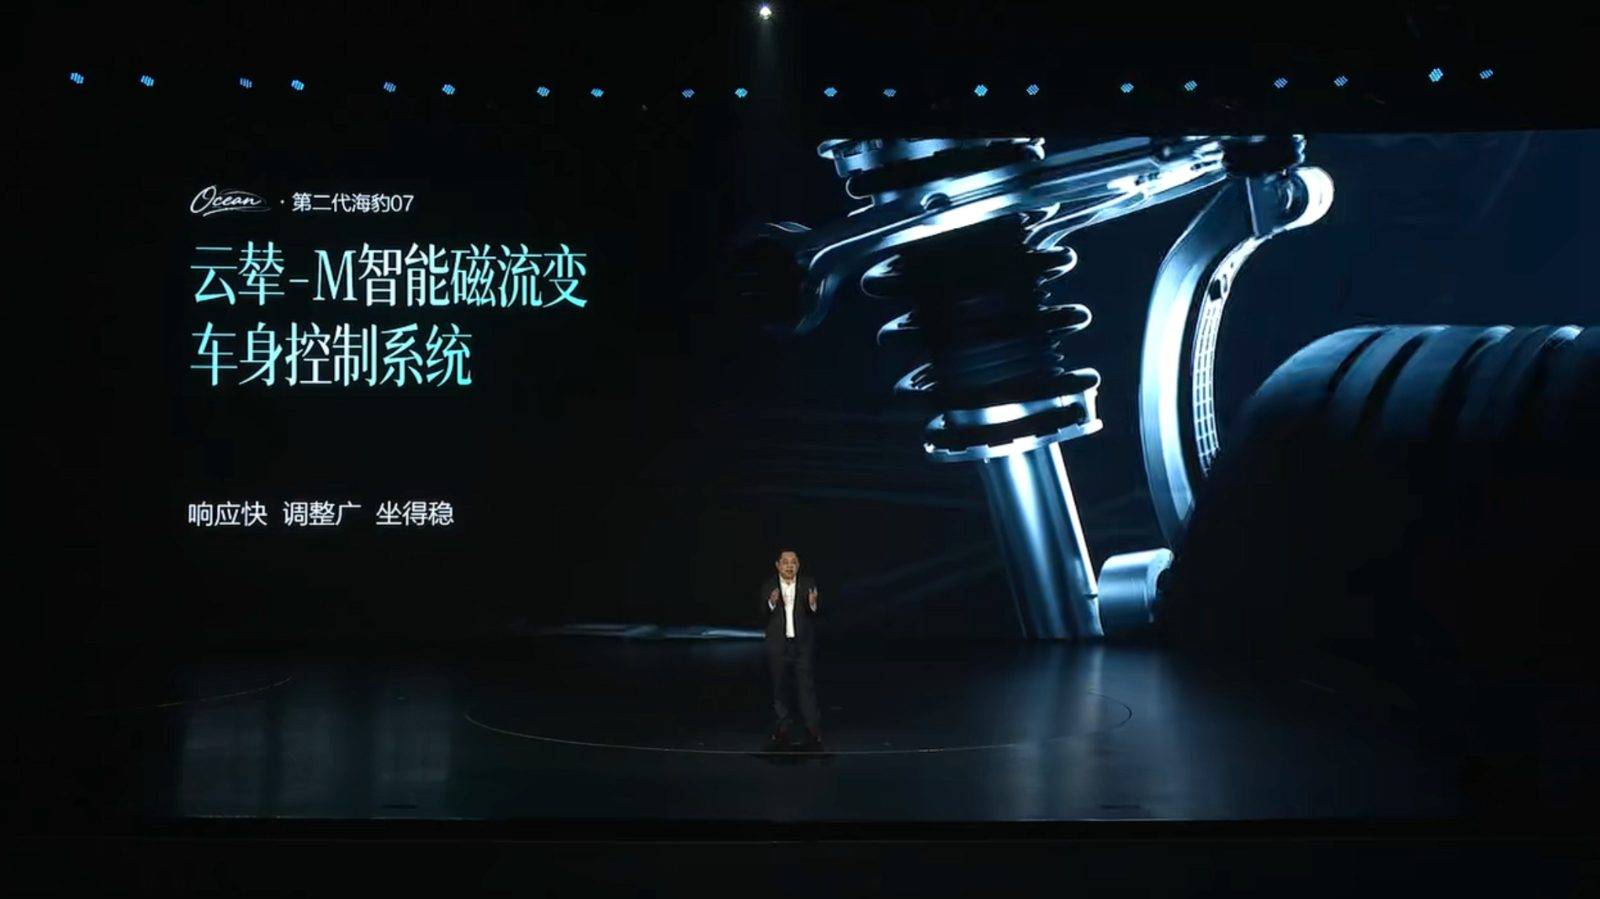
新车全系采用前双叉臂、增强型后五连杆独立悬架,并搭载云辇-M 智能磁流变车身控制系统,可以根据路况快速调节阻尼。遇到坑洼和路面接缝时它能尽量化解冲击;转弯、变道时,则会通过增加阻尼抑制车身多余的晃动。
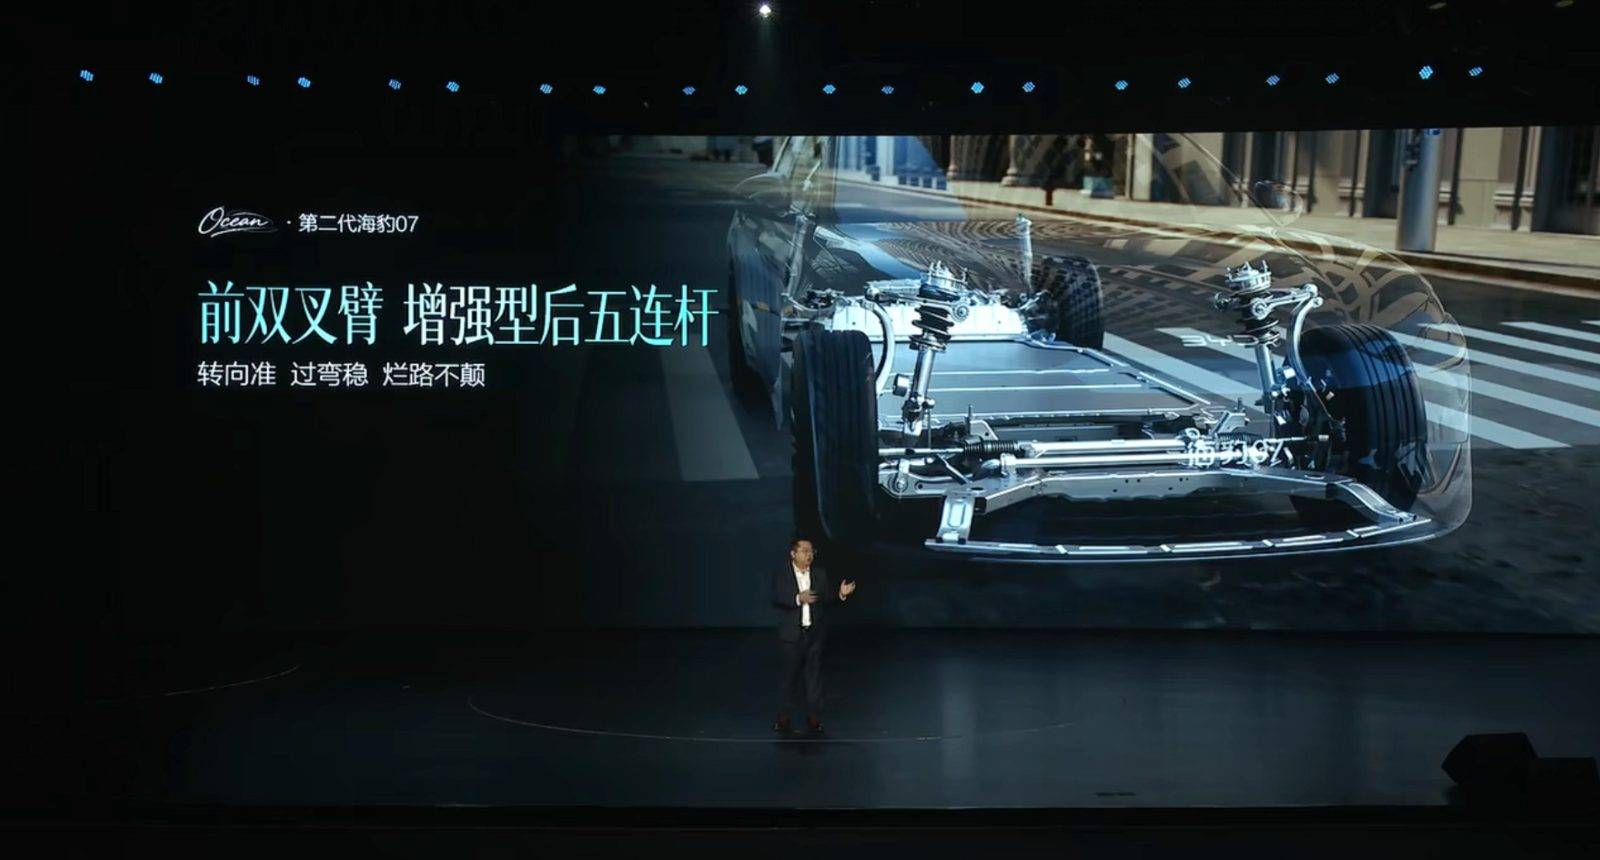
和同样搭载磁流变悬架的领克 07 GT 一样,这套云辇-M 实际上也来自供应商京西智行。从过往的体验来看,这套悬架的表现确实不错。但要注意的是,采用这项配置的车型仅有 17.29 万元的顶配版本,其余车型用的是云辇-C。
动力方面,纯电版和插混版,对应的是两种不同的家庭用车方式。
纯电版采用后轮驱动,电机最大功率 245kW,零百加速 5.5 秒。不过相比加速成绩,775km的 CLTC 续航和 9.8kWh 的百公里电耗,可能与家庭用户的日常生活关系更大。
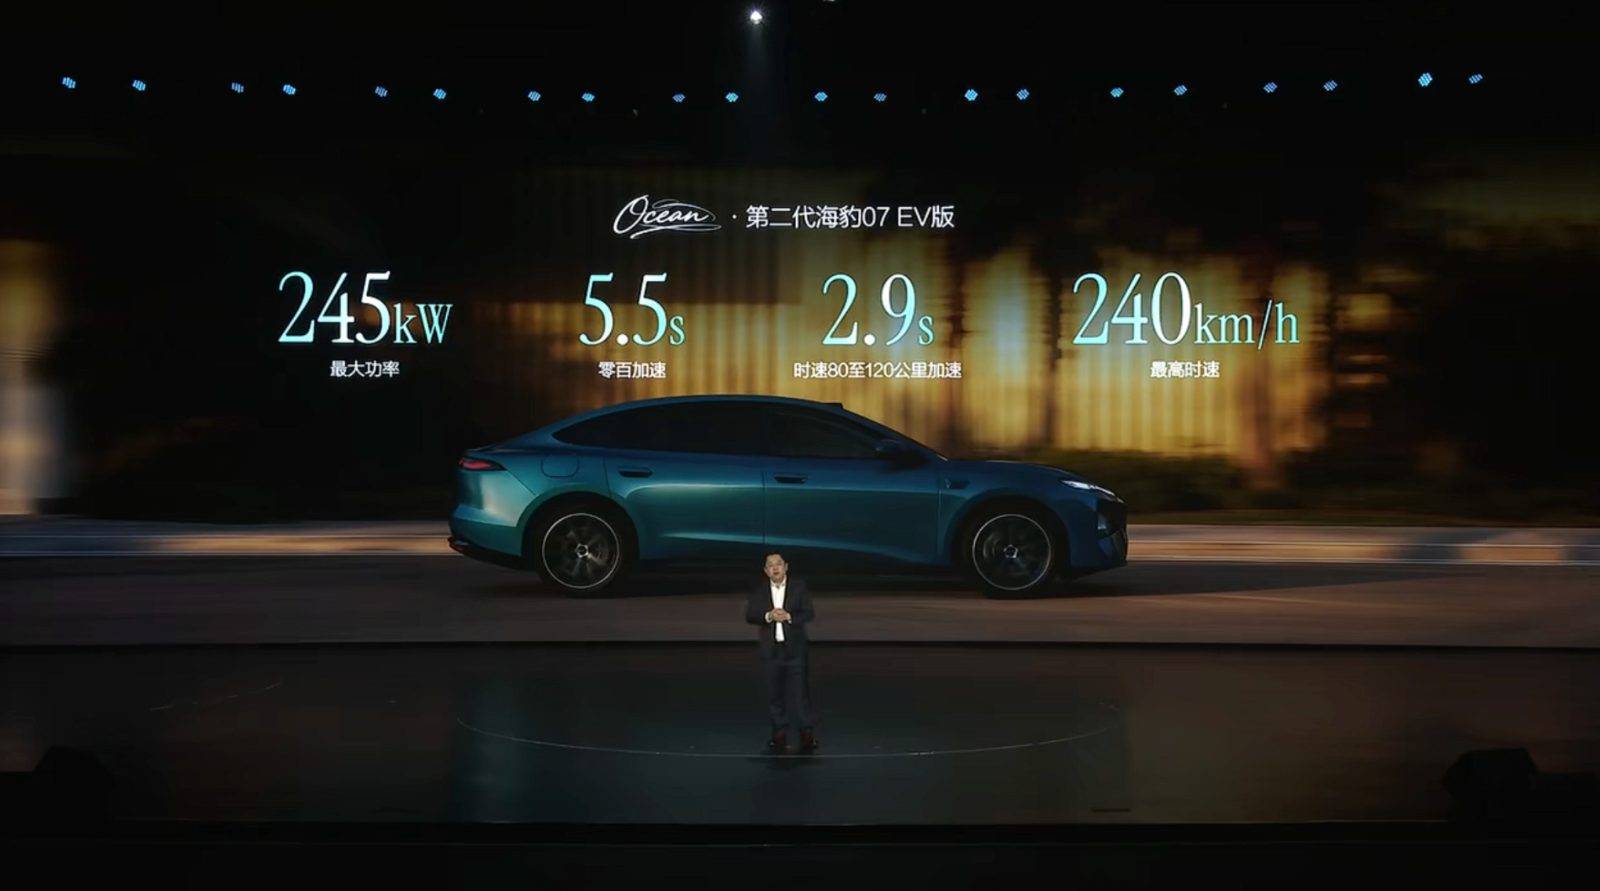
如果按照每度电 0.45 元的谷电价格计算,行驶 100 公里的电费不到 5 元。对于有固定充电条件、日常通勤里程较长的用户来说,这种使用成本会更加直观。
如果家里充电方便,但又经常有长途需求,前驱的插混版提供的是另一种思路。
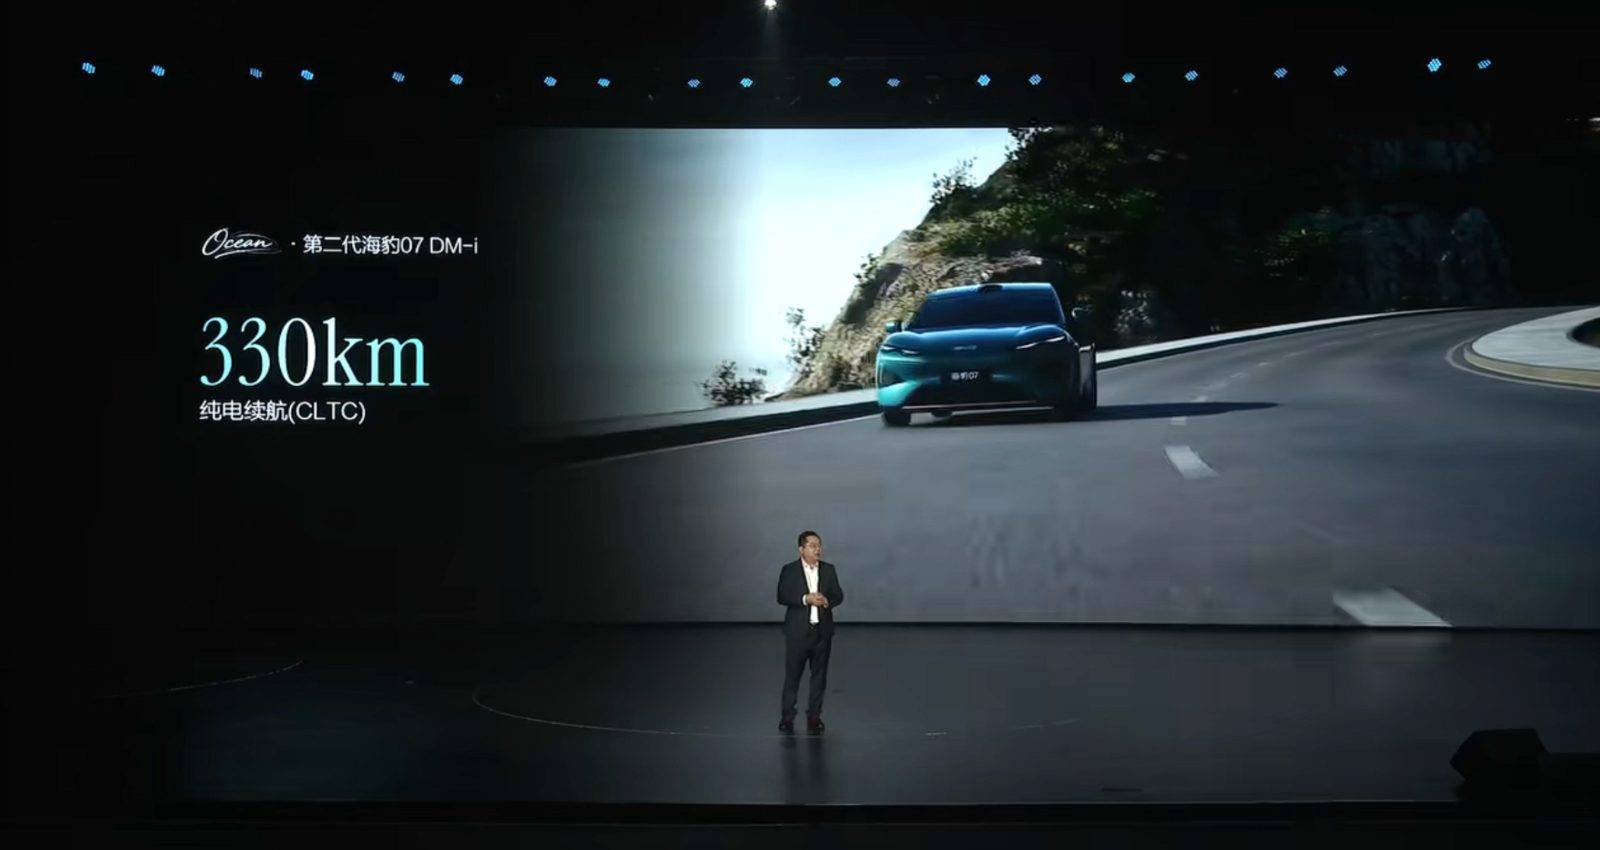
38kWh 电池带来 330km 的 CLTC 纯电续航,日常上下班完全可以以用电为主;偶尔需要跑长途,车辆也不必依赖充电网络;馈电状态下 3.3 升的 NEDC 百公里油耗,进一步降低了长途出行的成本。
另外,补能体系也逐渐成为这类长续航新能源车的一部分。
目前,比亚迪已在 341 个城市建成 12165 座闪充站,第二代刀片电池也针对低温补能进行了优化。具体就不过多介绍了,「5 分钟充好,9 分钟充饱」这句口号已经听得我耳朵起茧了。
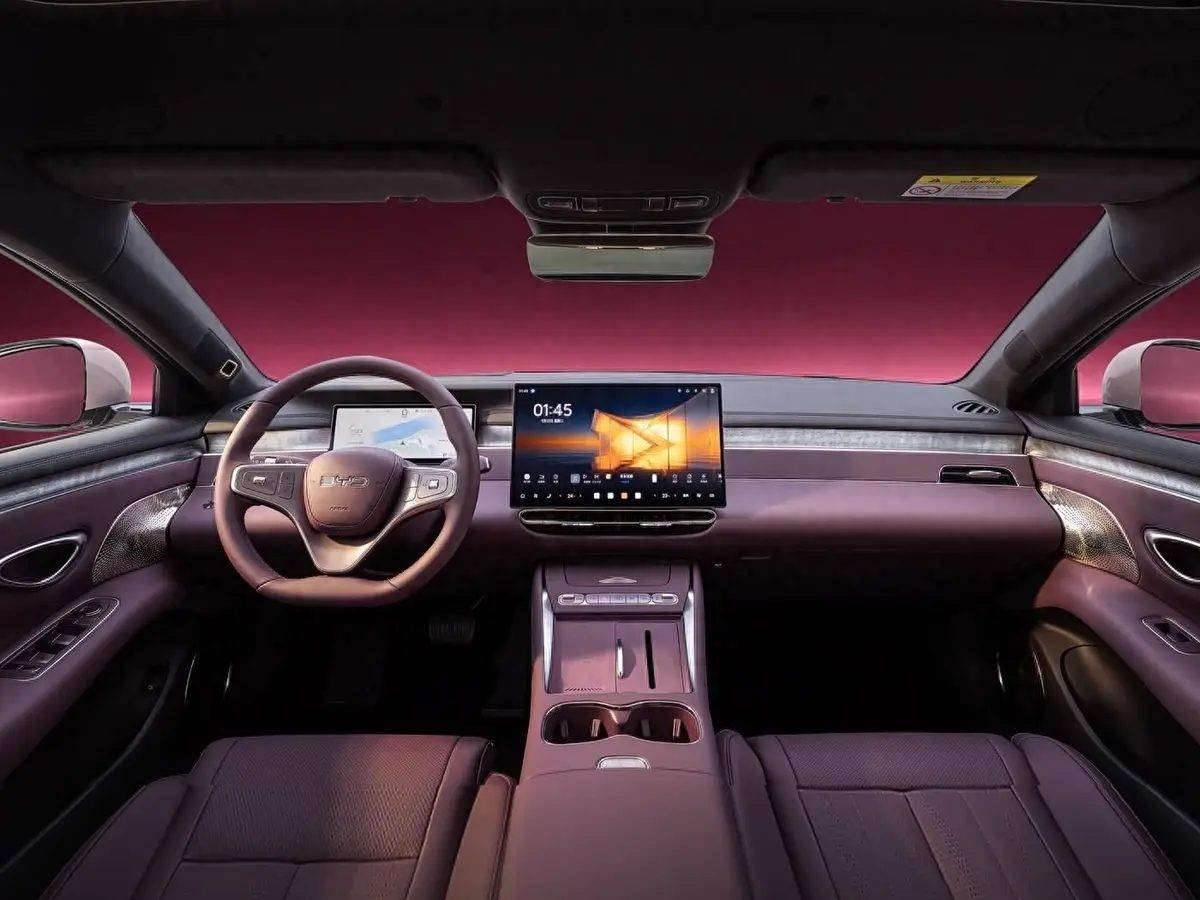
进入车内,全新海豹 07 并没有为了突出科技感,就把所有实体按键一股脑取消,一些高频功能依然可以直接操作。与此同时,B 柱和中控台还预留了带供电的接口,可以方便地安装手机支架、运动相机等设备。
不得不说,比亚迪今年的内饰进步确实不小,缝得挺好。
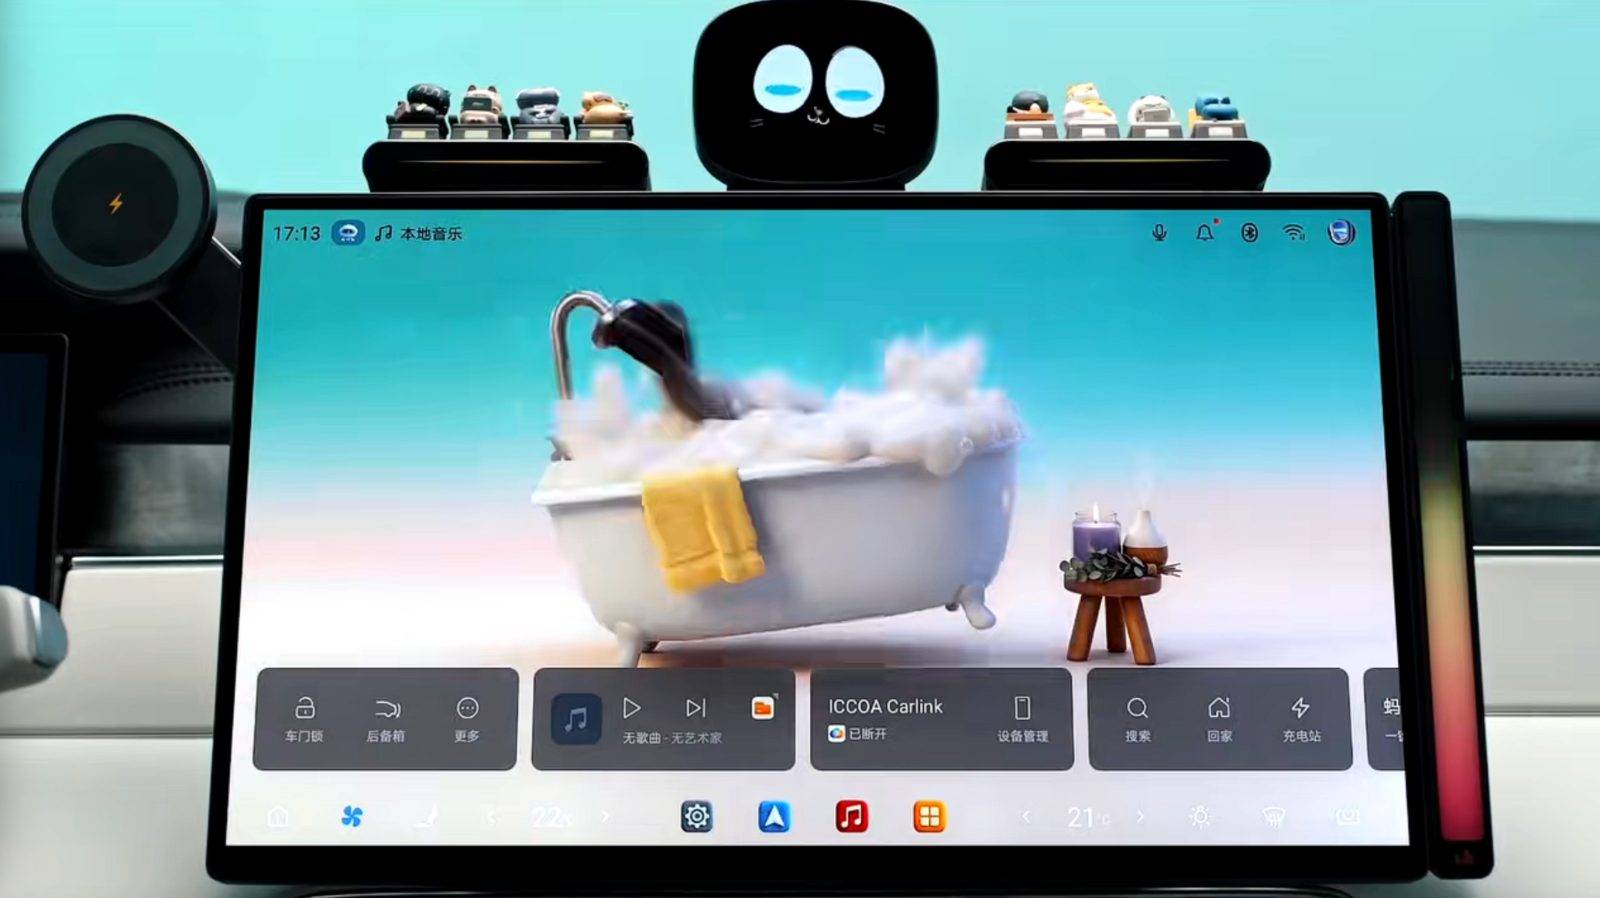
总的来说,在这套座舱里,4.9 毫米窄边中控屏、动态智能表盘和智慧生态 2.0 负责座舱交互;零重力座椅、6.8 升冷暖冰箱、帝瓦雷音响和双层隔音玻璃,分别对应了休息、长途出行和日常通勤等不同场景。
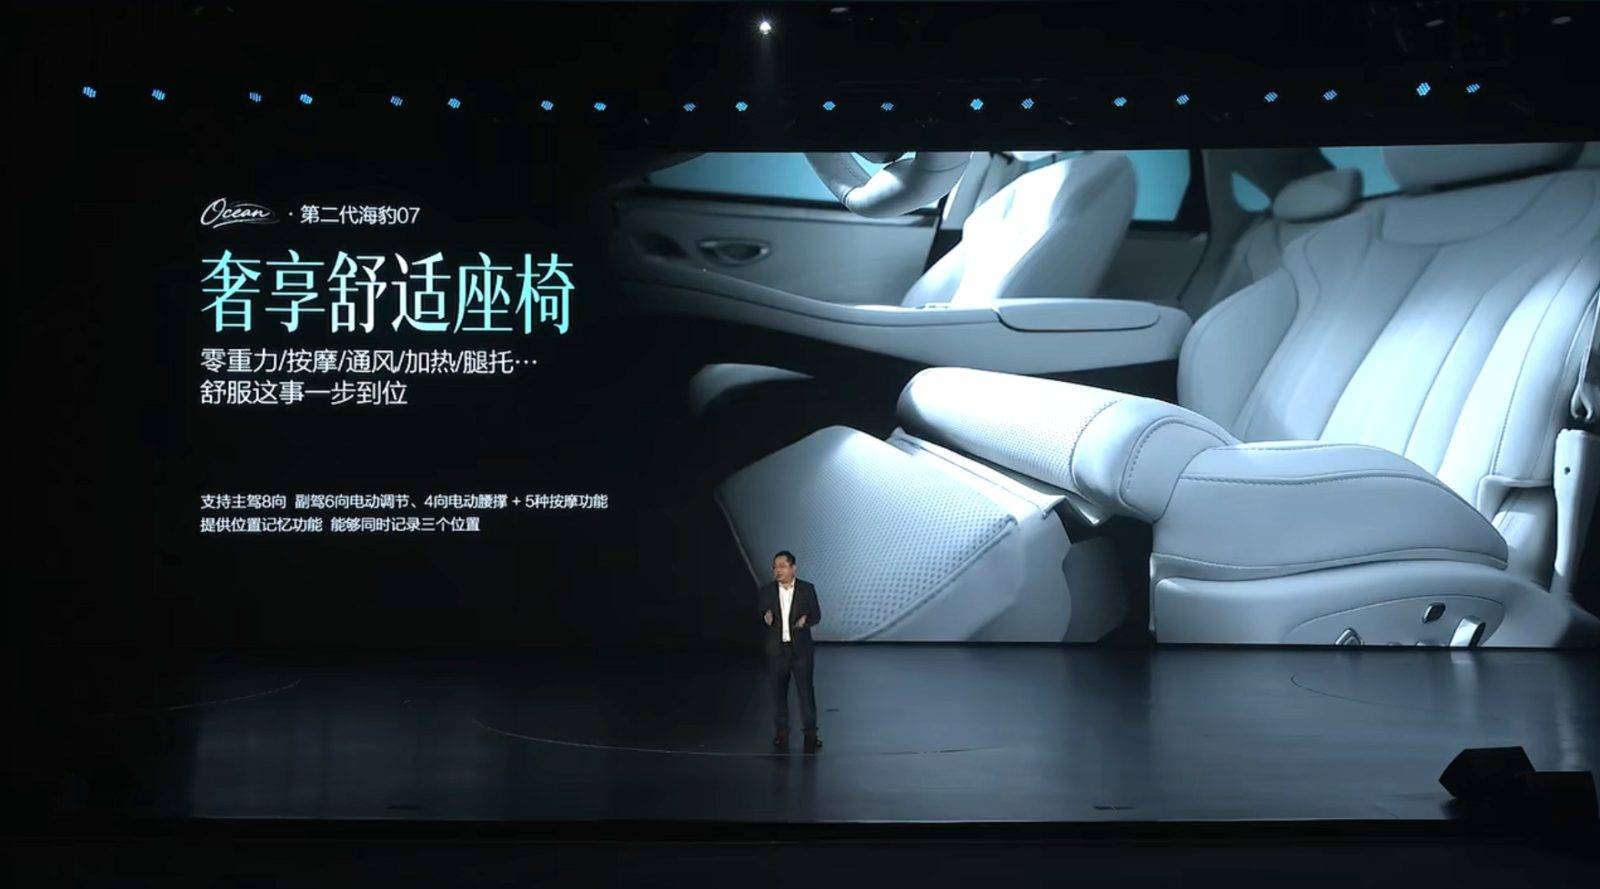
安全配置也是同样的思路。
AES 自动紧急转向主要应对制动距离已经不足、需要紧急避让的场景;ITBC 爆胎稳行控制系统,则会在高速爆胎后快速干预,帮助车辆稳定姿态。
所以,五米车长只是全新海豹 07 最直观,也最容易被看见的标签。
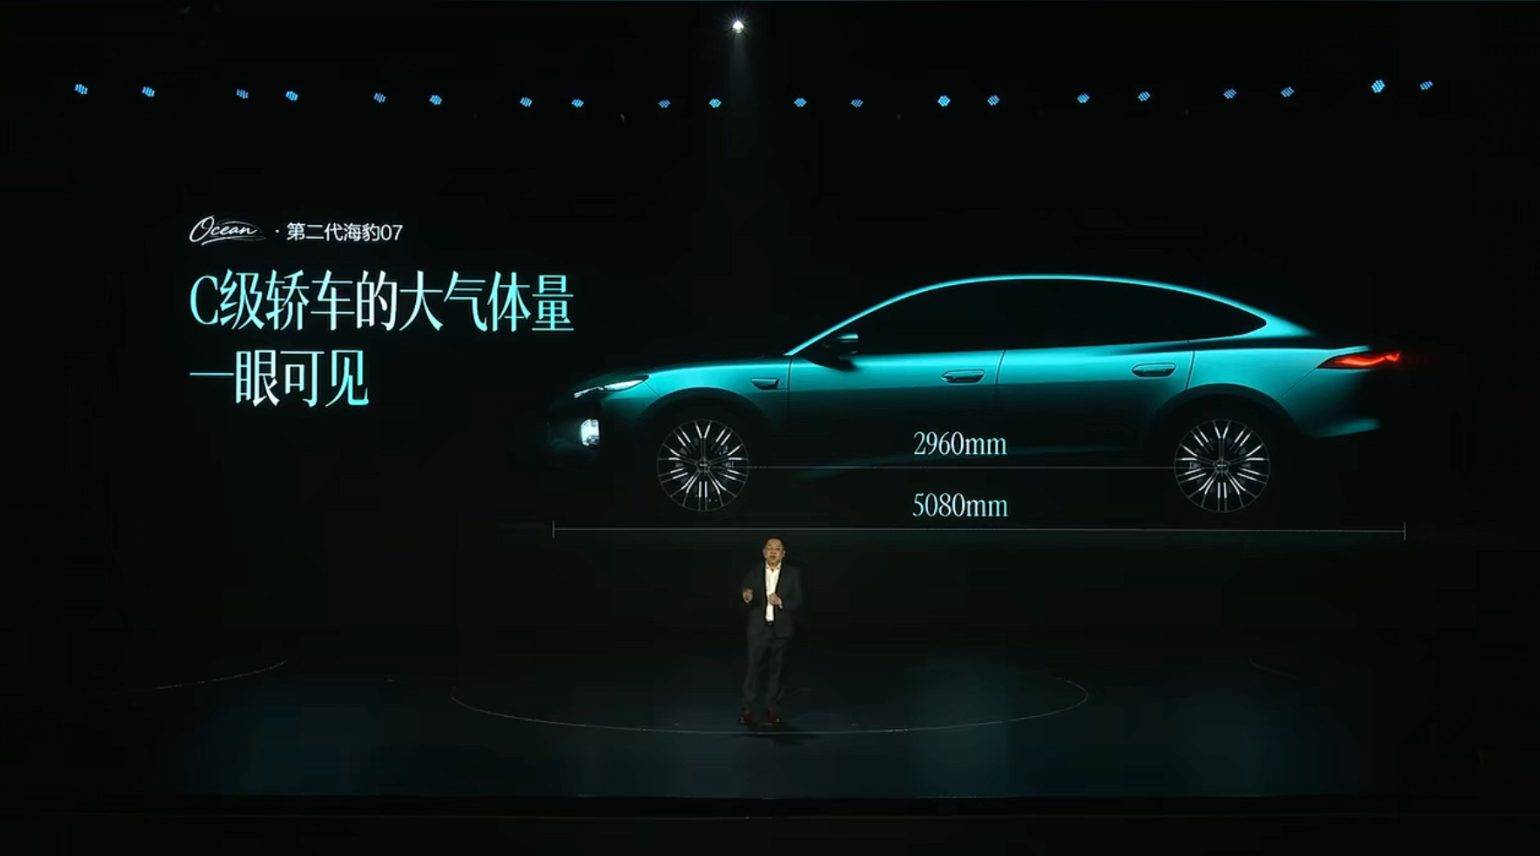
当过去更多属于行政级别的车身尺寸来到 15 万元级市场之后,消费者得到的不应该只是「更大的一辆车」。全新海豹 07 想要做的,是把空间、舒适、安全和能耗全都打包放进一辆车里。
曾经的「行政轿车」,已经成为了家用市场的基本盘
13.99 万元的起步价,让全新海豹 07 直接进入竞争最激烈的家用轿车市场,也让它成为海洋网补齐中大型轿车产品线的一款关键车型。
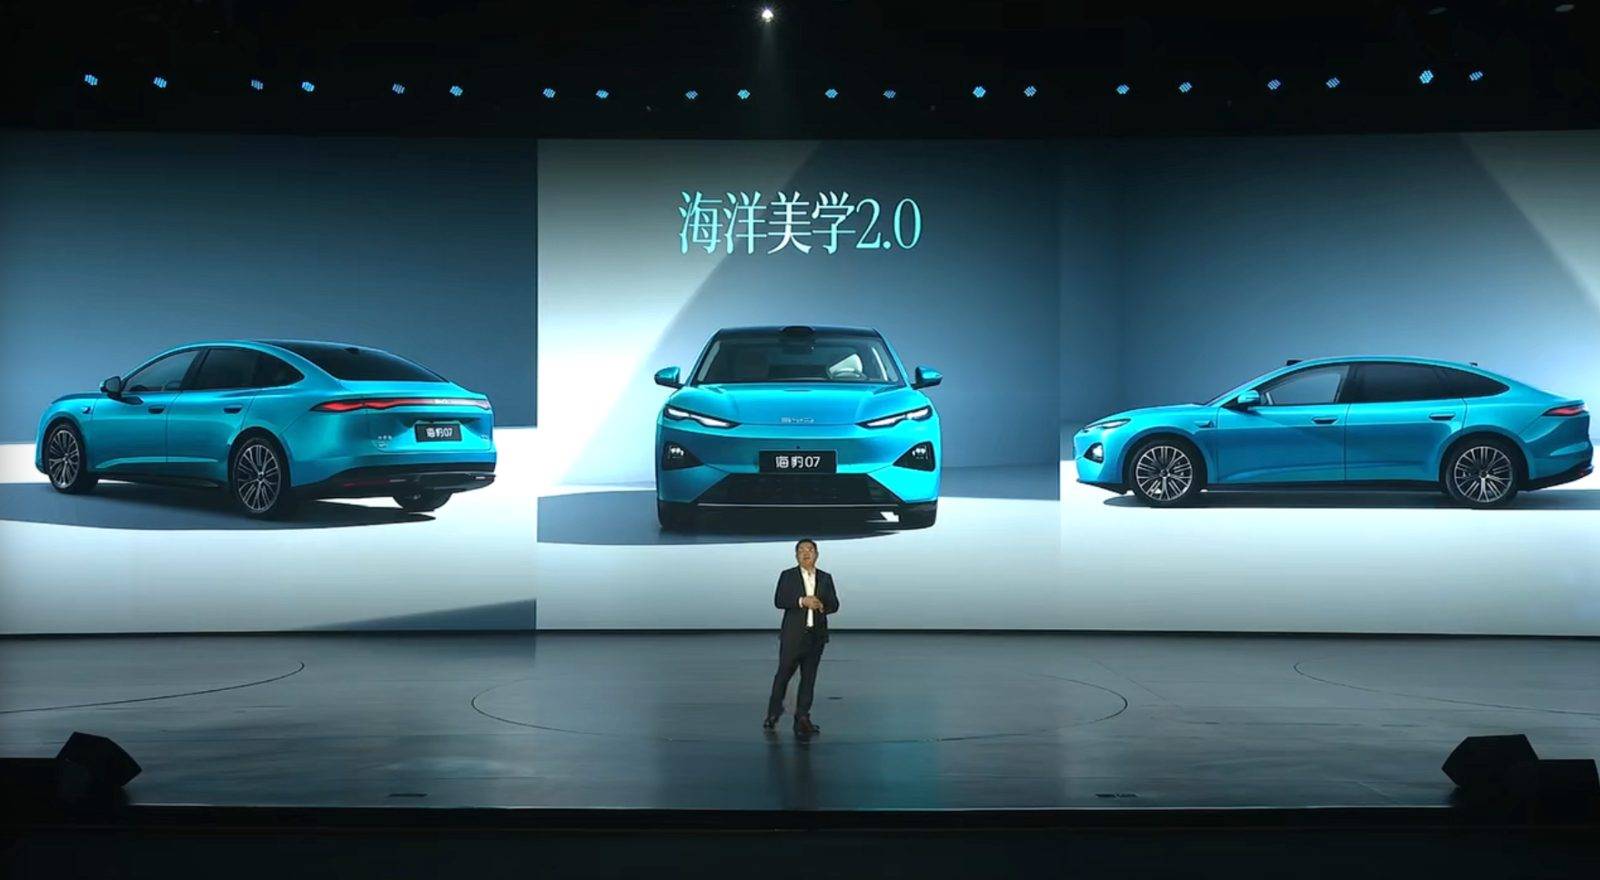
海洋网成立至今不到五年,累计销量已达 796 万辆。海鸥和海豚帮助它在入门级市场站稳了脚跟,但在 15 万至 20 万元区间,海洋网一直缺少一款空间更大、技术规格较高的轿车。
全新海豹 07 的到来,填补的正是这个空缺。
它与王朝网汉家族的关系,同样值得关注。过去两年,王朝网通过汉 L、大汉这两款车型向 20 万元以上市场拓展,汉 DM-i 则逐渐进入产品更新阶段——车长超过 5.1 米的新一代汉 DM-i 已经完成工信部申报,即将亮相广州车展。
全新海豹 07 此时上市,主要任务就是和即将发布的汉,共同守住主流家轿市场。
21 年前,奥迪 A6L 那五米的车长在许多人心中与商务接待画上了等号。
21 年过去,车依旧五米长,车钥匙却递到了更多普通人手里。
对了,今晚还有另一辆「13 万的五米大轿车」上市了,一汽丰田的亚洲龙,我先去看看怎么个事儿。
#欢迎关注爱范儿官方微信公众号:爱范儿(微信号:ifanr),更多精彩内容第一时间为您奉上。