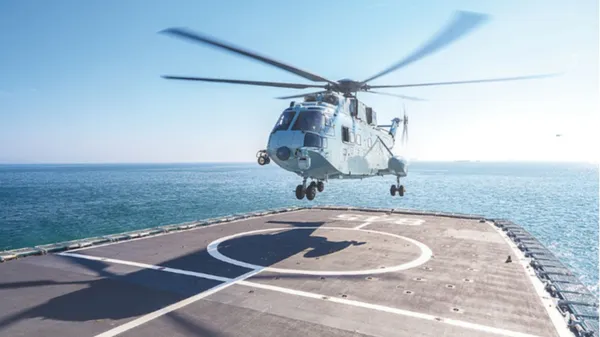
海军首批舰载机女飞行学员结业赴一线部队
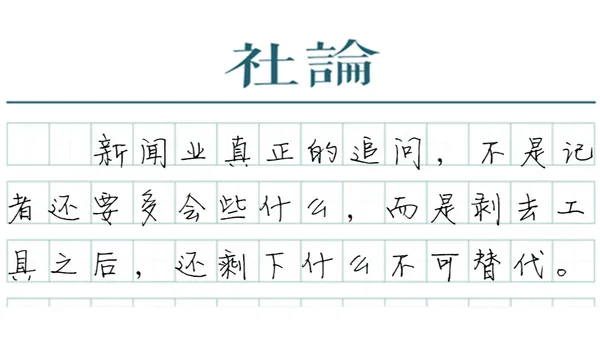
【记者节献词】功夫在诗外

The most scathing reviewer 2 review I have ever read
This is not my paper. Not my review either.
Official Review of Submission21893 by Reviewer Xz8e
Paper Summary:
The paper tries to learn correlations among components of each latent state in a world model to propagate the reward sensitivities to adaptively weight the uncertainties that most matter for long-horizon planning via a pessimistic objective.
Presentation: 1: Difficult to follow despite careful reading.
Informativeness: 1: I learned little or nothing new from this paper.
Soundness: 1: I have significant concerns about the paper’s soundness that do not appear easy to address.
Critical Strengths:
None
Critical Weaknesses:
First and foremost, the paper is highly likely to be fully AI-generated. The authors demonstrate a lack of technical accuracy and depth. They fail to communicate their ideas clearly and accurately. The paper makes few original contributions. See evidence below.
Neologistic and full of jagons that add little value of presenting research gaps, methodologies, and their contributions. I don’t believe authors even understand those terms before stitching them together.
Abstract is poorly written. This is not intended to communicate efficiently with readers. This is to create barriers in understanding their work. From the second sentence, “a scalar uncertainty”, “sparse latent dynamics” come out of nowhere and don’t know what they are referring to. And so many such examples follow thereafter: “factor-level residual bounds”, “retains initialization error”, “expected-error control”, “exact certificate”, “removing error-propagating dependencies and introducing approximation bias”, “localized mechanism-shift”, “comparator-dependent regret bound under simultaneous validity”, “a decision-relevant uncertainty bound”. And showcase experimental results without stating tasks?
Introduction is also disconnected, poorly motivated, fragmented. From the first paragraph “which model errors matter for a long-horizon decision, especially after an environmental mechanism changes?”, what is “environmental mechanism changes” here? Is it handling non-stationary environments, or continual learning tasks? Why brings something out of vacuum? Then the second paragraph pumps out “a global Lipschitz constant”, and reiterate what so-called “sparsity” And then jumps to uncertainty with a set of new terms “A small predicted covariance”, “Marginal calibration”, “a high-probability interval” and close by “Exploration should reduce uncertainty about mechanisms that affect decisions, rather than maximize uncertainty indiscriminately.”: okay, what uncertainty are you focusing on? epistemic or aleatoric? Methods and contributions are also vague and lack clarity.
Method section is horrible.
What do you mean by “a sufficient latent state”? An approximate model can hardly find sufficient statistics.
In the Gaussian transition model, what is z_t^(pa_e(i))?
What is the difference between z_(t+1)^i and ẑ_(t+1)^i, is the latter deterministic and why so?
What is “nominal imagination”? Where does “sparsity” come from and what is “a within-time DAG”? What is “nominal systems”? What is feedback policy? What problem setting are you looking at? Where does the “recurrent state” come from the encoder? What is mechanism i?
What is the motivation of introducing the adjacency matrix? If you intend to learn the dependency between different subcomponents of the latent state, use one sentence is enough.
And several notations are conflating, like parameter posterior q(θ|D) with the state posterior. The training objective is not motivated.
Experiments are not scientific. No random seeds reported, no task descriptions, no metrics explanations.
This paper is an affront to scientific research and reviewers’ time.
Questions For Authors:
None
Flag For Ethics Review: No
Rating: 1: Clear rejection
Confidence: 4: I have substantial direct research experience on this topic.
[link] [comments]
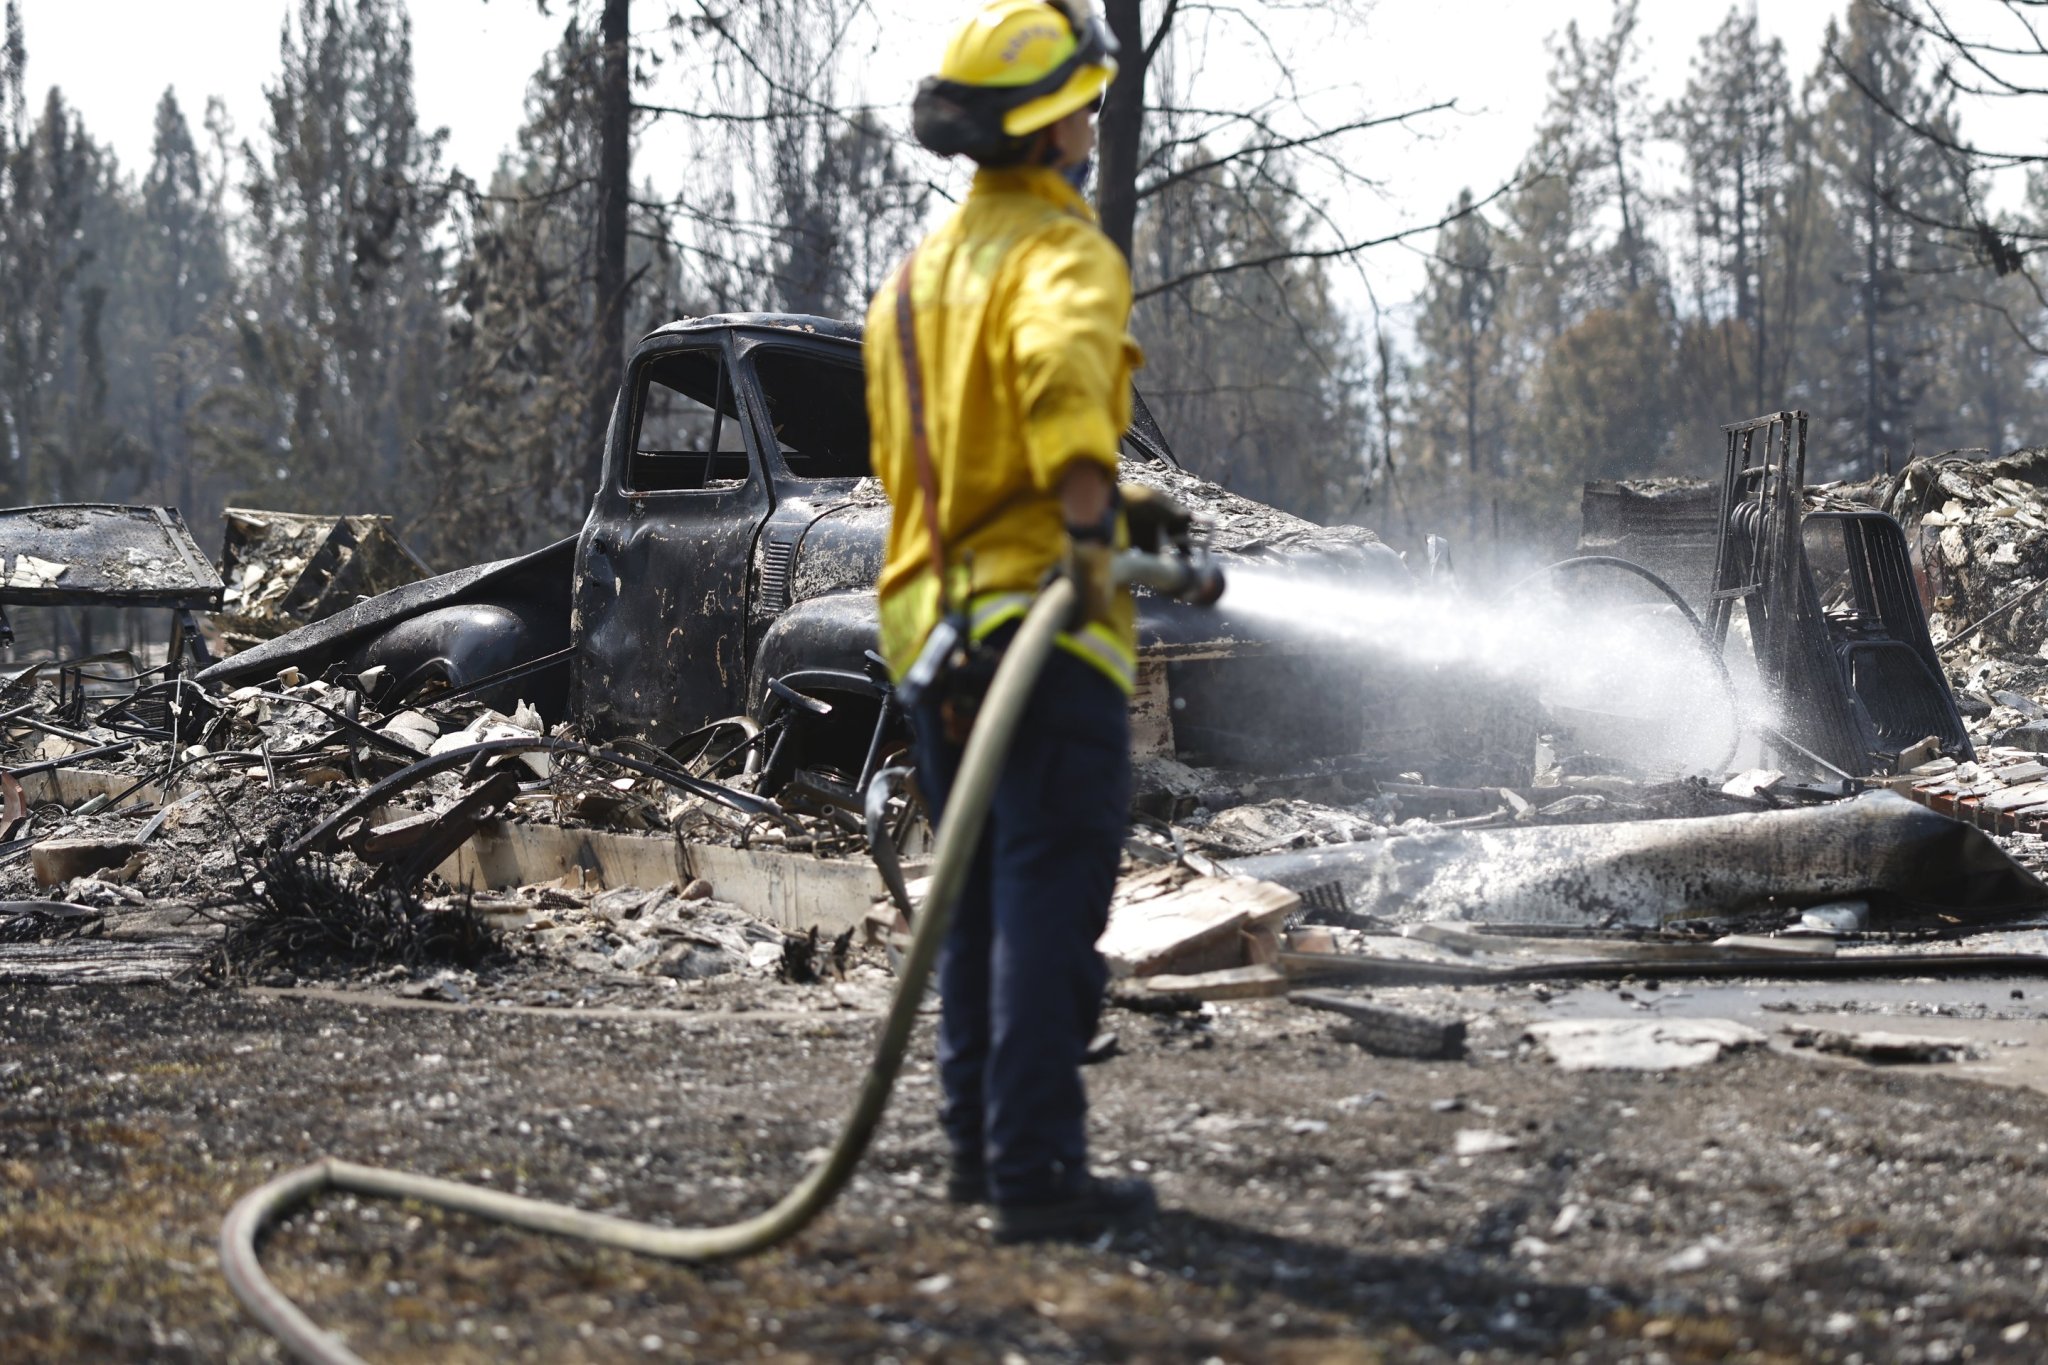
‘Fast fires’ were just 2.7% of U.S. wildfires but destroyed 78% of the structures lost — and up to 449,000 could be lost by 2060
As temperatures rise and development expands, the number of homes and other structures damaged or destroyed by wildfires across the U.S. is on pace to triple by mid-century, my colleagues and I found in a study just published.
The 2026 wildfire season has been a sharp reminder of that risk and why making homes and properties less vulnerable to wildfires is increasingly crucial. Fortunately, strategies to lower the risk of losing a home to wildfire don’t have to be overly expensive.
The 2026 western fire season
The 2026 wildfire season began with historically low mountain snowpack, early snowmelt and exceptional warmth across much of the West. Even before the nation’s hottest summer on record intensified drought and dried vegetation, fires were breaking out.
Colorado’s Aspen Acres Fire destroyed hundreds of structures in June. Four firefighters died from injuries suffered when the fast-moving Knowles Fire overtook them near the Colorado–Utah border in July. In August, wind-driven fires swept into neighborhoods in Spokane, Washington, damaging more than 800 homes and forcing tens of thousands of residents to evacuate.
In Colorado, the summer monsoon season brought rainfall, helping firefighters gain ground. Across the Rocky Mountain region, lightning continued to start fires, but rain helped keep many fires small in many areas despite above-average temperatures.
Despite this reprieve, Colorado fires had burned more than 318,000 acres by late October, nearly twice the annual average since 2000. Nationally, the total area burned was also well above average. The U.S. spent 48 consecutive days at Preparedness Level 5 – the highest level, indicating that firefighting resources were stretched nationally – compared with a 10-year average of 25 days annually.
Reasons for rising fire risk
Fire is a natural and often beneficial part of many ecosystems, shaping vegetation and supporting biodiversity. However, a century of fire suppression has allowed dry vegetation to accumulate in forests that historically had frequently burned.
Rising temperatures caused by human activities such as burning fossil fuels have increased the rate at which the atmosphere pulls moisture from the land, drying soils and vegetation. Researchers estimate that this drying nearly doubled the area burned in western U.S. forests between 1984 and 2015 compared with what would have burned without human-caused climate change.
More people also now live in and at the edges of wildland areas, raising the risk of fires reaching neighborhoods. Human activity has extended the fire season beyond summer, when most lightning-caused fires occur, too. Power lines, vehicles, machinery, burning of debris and campfires can spark fires year-round.
These interacting factors have helped nearly quadruple the annual area burned in the western United States since 2000.
They also contribute to the growing threat of fast-growing fires, which can overwhelm emergency response.
In a 2024 study, my colleagues and I used satellite imagery to measure daily fire growth across the contiguous United States from 2001 to 2020. “Fast fires,” defined as those that burned more than 4,000 acres in a single day, represented just 2.7% of fires analyzed but accounted for 78% of documented structures destroyed and 61% of reported firefighting costs.
A brief burst of growth, often fueled by strong winds or highly flammable materials, can matter enormously, even if a fire’s eventual size is relatively small. And in many ecosystems, fires are getting faster.
More homes in harm’s way
The number of people and buildings in harm’s way has also been increasing in the U.S., raising the risk of damage.
Between 1945 and 2015, development in regions of the country with the highest wildfire risk expanded tenfold, increasing the amount of human exposure to wildfires while also introducing ignition sources and buildings that can burn. Once embers enter a neighborhood, fire can spread quickly from building to building.
My team’s new research suggests that without further action to reduce wildfire risk, the annual number of structures damaged or destroyed nationwide could nearly triple by mid-century. That would mean up to 449,000 structures lost between 2026 and 2060.
We used historical data about development patterns, wildfire area and the fires’ effects to reconstruct the past fire risk, then modeled future fire risk by incorporating weather, climate and housing-density expectations.
We found that roughly one-third of western neighborhoods facing the greatest future risk are low-income communities. In these communities, people may struggle to afford measures to protect their homes, maintain insurance coverage and recover financially after a fire.
How to lower your wildfire risk
These projections are sobering, but actual losses will depend partly on the choices people make now.
For example, homes can be made less likely to ignite with Class A fire-resistant roofs and ember-resistant vents that reduce the potential
Big Tech’s AI race will save small business owners time. It won’t find them customers
Meta, Google, OpenAI and Anthropic are racing to become the small business owner’s AI assistant. Meta brought its Muse agent to small businesses in September. Anthropic and OpenAI now package tools aimed squarely at owners, and Google is building the same features into tools millions of them already use.
That competition is good for Main Street. But it’s a race to save owners time, and time isn’t what keeps them up at night. What keeps them up is where the next customer will come from.
A word on where I sit. I run Alignable, a network of 10 million small business owners, so I have a stake in this argument. Alignable also co-hosts small business AI training with Anthropic, one of the companies named here. Read what follows with that in mind. But I also have something the assistants don’t: 13 years of data on how small businesses actually find work.
Fifty beats 500
Start with where customers come from. In our surveys, members say about 85% of their customers come through referrals. Not ads, not search, not cold email. People who already trust them.
Across 35,000 local communities, our members have formed 226 million business connections. Most of them never become a relationship that sends work either way. The owners who grow through their networks aren’t the ones with the most connections. I’ve told owners for years that 50 warm relationships beat 500 cold contacts. That’s a rule of thumb from experience, not a number we’ve measured. But the owners who win do keep a small set of relationships active and leave the rest alone.
And most owners are sitting on more opportunity than they know. When members tell us what their ideal customer looks like, we can count how many of those businesses sit one introduction away: connected to someone the owner already knows. Among members whose ideal customers show up in their extended network, the typical one has about 190 of them a single introduction away. For one in four, it’s more than 600.
The next customer is rarely a stranger. They’re one relationship away, through someone the owner hasn’t talked to in months.
Those relationships aren’t random, either. In my experience, three kinds do most of the work: customers who talk you up, businesses that serve the same customer without competing with you, and a handful of people who open doors. The best referral partner usually isn’t a peer in your own industry. It’s the business your customer calls right before or right after they call you: the realtor and the home inspector, the accountant and the financial planner.
What a general assistant can’t see
Ask any of the big assistants how to get more referrals and you’ll get a solid list of best practices. Ask an assistant that sits on a map of business relationships and it can tell you something specific: three nearby businesses serve your ideal customer, one of them already knows two of your clients, and you haven’t spoken to your best referral partner in four months.
That’s the difference between advice and action. A general assistant can’t answer that question, because the answer lives in data it doesn’t have.
The early numbers bear this out. In Bluehost’s 2026 study of 350 U.S. owners, 78% said AI saves them time every week. But 43% have seen no change in revenue. Time saved only matters if it goes somewhere that pays.
Too often it goes into volume. Forbes recently told the story of Paul Birrell, a New Jersey owner whose automation loop sent roughly 400,000 emails in three days. His reaction: “I don’t have 400,000 customers.” Everything we see says growth comes from the opposite: judgment about the few people who matter.
Three kinds of AI, not one
AI will reach small business owners in three forms. The first is the personal assistant the giants are fighting over. It delivers time, and the assistants are converging fast.
The second is AI built into the systems that already hold the business’s own data. Intuit knows the books. Shopify knows the store. That AI delivers control: it can flag a cash crunch six weeks out or spot the product quietly losing money.
The third is AI built on the relationships between businesses: who knows whom, who serves the same customers, who sends work to whom. That’s the one that delivers growth, and it’s the one almost nobody is talking about. At Alignable, ours is called Allie.
The giants have real advantages, and they’ll connect to the other two kinds. Meta’s Muse already plugs into QuickBooks, Shopify and Stripe, and the others are adding similar connections. The open question is who the intelligence works for. Meta makes nearly all of its money selling ads, and an assistant built by an ad company will tend to find that the answer involves more advertising. The data that actually works for the owner describes how their business runs and who in their community can help it grow.
What owners should do now
Use a personal assistant every day. The time savings are real.
Then decide, in advance, where the reclaimed hours go. Put them on the calendar against the work that generates revenue, and the most neglected item on that list is relationships. Write down the 50 people most likely to send you business. Most owners can name 10 without trying. Those 10 are where AI should be pointing you.
There are about 36 million small businesses in the U.S., and more than 80% of them have no employees. For those owners, AI isn’t a department upgrade. It’s a capability they never had. Owners should take the better tools the giants’ race produces. But the biggest gains won’t come from saving an hour. They’ll come from knowing which 50 relationships to spend it on.
The opinions expressed in Fortune.com commentary pieces are solely the views of their authors and do not necessarily reflect the opinions and beliefs of Fortune.
This story was originally featured on Fortune.com
The battle for megawatts: why restricting data centers is a strategic mistake
In Ireland, data centers consume nearly a quarter of the country’s electricity. New grid connections around Dublin were effectively frozen for three years. Under revised rules, new projects must provide generation or storage capacity onsite or nearby. Amsterdam previously imposed a moratorium on new facilities, while Frankfurt regulates their location through zoning.
In July 2026, New York State introduced a moratorium of up to one year on certain environmental permits for new large data centers. State officials said the pause would allow them to assess the facilities’ impact on the power grid and the environment. As of May 2026, data center projects representing nearly 12 GW of potential demand were in the state’s grid interconnection queue.
Should governments restrict data centers when power grids cannot keep pace? I believe they should expand power supply and grid capacity instead.
As co-founder and general partner of Roosh Investment Group, I have been investing in technology companies for over five years. Our portfolio includes AI infrastructure, and energy is now a key focus. This experience has shown me how access to energy infrastructure influences investment decisions. Reliable power is increasingly becoming a decisive factor in a company’s ability to scale and attract capital.
As businesses rely more on AI, control over its models and infrastructure matters more. A foreign provider’s decision to change terms, raise prices, or restrict access could affect entire industries. Domestic computing capacity gives countries more control over the infrastructure their businesses depend on.
Control over AI is becoming a source of economic power
This helps explain the intensity of U.S.–China competition in AI. American companies hold leading positions across the AI stack, from advanced models and chips to major cloud platforms. Washington views the power supply for data center infrastructure as a national security issue.
Beijing is pursuing a state-led strategy. Its “Eastern Data, Western Computing” program directs the development of computing capacity toward western China, where energy and land resources are more readily available. At the same time, the country is expanding power generation at scale. According to the International Energy Agency, China added nearly 500 GW of renewable capacity in 2025—more than 60% of the global increase.
Europe, meanwhile, risks falling further behind. Brussels plans up to seven AI gigafactories and at least a tripling of EU data center capacity within five to seven years. Yet some countries are slowing construction, while European businesses still rely primarily on American cloud providers. Restrictions do not remove demand for AI; they risk pushing investment abroad and reinforcing that dependence.
The bottleneck is local
Data centers’ hunger for power should be understood in the context of wider electricity demand. According to the International Energy Agency, they accounted for only around 70 TWh of the 800 TWh increase in global electricity consumption in 2025. Industry, air conditioning, heat pumps, and electric vehicles contributed far more.
The challenge is rapidly growing demand concentrated in a handful of locations. Power must reach new computing capacity in time.
What is holding up connections?
In the U.S., lead times for large transformers now exceed two years, compared with roughly 50 weeks before the pandemic. Morgan Stanley estimates that U.S. data centers could face a power shortfall of around 49 GW by 2028. Microsoft CEO Satya Nadella has acknowledged that power has become the company’s binding constraint. Some of its GPUs are sitting in inventory with nowhere to plug them in.
Dedicated gas-fired plants offer no quick fix. GE Vernova, Siemens Energy, and Mitsubishi Power produce around two-thirds of the world’s gas turbines, and their factories are booked years ahead. GE Vernova reported 116 GW in gas power equipment orders and slot reservations, while targeting annual turbine output of 20 GW in the third quarter of 2026.
The hardware itself adds another challenge. A server rack once required 7–12 kW. Systems built around NVIDIA’s GB200 consume 120–132 kW per rack. Conventional air cooling is no longer sufficient at that power density, so new facilities must be designed for liquid cooling from the outset.
Tech giants are securing power themselves. Microsoft agreed to buy electricity from the 835 MW Three Mile Island reactor, which is being restarted to serve its needs. Google’s agreement with Kairos Power calls for small modular reactors, with the first expected online by 2030.
Governments cannot rely on corporate initiative alone. They must plan energy and digital infrastructure together: expand grids, accelerate transformer production, streamline connections, and encourage long-term power purchase agreements, generation near data centers, and storage.
How war accelerated distributed generation in Ukraine
Ukraine’s experience sho

This CEO lived on canned soup and took just two days off for his daughter’s birth. Now, he admits he lost sight of proper work-life balance
The grind to success can be long, punishing, and it can quietly take more than it gives.
Ron Schneidermann knows that better than most.
After scaling his first company, Liftopia, into a business with more than $60 million in annual revenue, he went on to become CEO of AllTrails, the popular hiking map app. Today, he leads test-prep startup Acely. But looking back across his career, he says he had to learn the hard way what real work-life balance actually costs—and what it’s worth.
While building Liftopia, a digital marketplace for ski resorts, that mindset came at a personal price. Schneidermann worked out of a cramped San Francisco apartment, turned spending less than $15 a day into a kind of endurance test, and went two years without taking a salary, surviving largely on canned soup.
The tradeoffs even extended into his family life. When his first daughter was born four years into Liftopia, he took just two days off work. Three years later, he allowed himself just a week for his son’s birth—and thought that was progress.
“I look back, I was just able to justify it as ‘that’s just part of the grind’… but you never get that time back,” Schneidermann told Fortune. “That was a mistake.”
It’s not an easy admission in startup culture, where sacrifice is often worn as a badge of honor and overwork is normalized as the price of ambition. But Schneidermann, now in his late 40s, has since reframed the experience entirely.
“For everything that was frustrating, that went wrong, that I regretted about Liftopia, I was able to take the inverse and turn it into a strength,” he said.
By the time he joined AllTrails in 2015, that mindset shift was already underway. He eventually became CEO in 2019 and instituted a company-wide ritual: the first Friday of every month, AllTrails shut down and employees were encouraged to go outside.
In August 2025, he took on the new challenge of becoming CEO of Acely. This time, he’s bringing those hard-won lessons with him from the start. Instead of monthly trail days, the company now runs a monthly “hackathon,” where its less than a dozen employees pause routine work for the whole day and experiment with AI tools and new ideas—no meetings, no KPIs, no deliverables.
Ron Schneidermann says he’ll never take a job for its salary ever again
Even before Schneidermann had his eyes on entrepreneurship, he was learning career lessons the hard way.
In the late 1990s, he was a student at UCLA studying mass communication and business while also working at Abercrombie & Fitch to help pay for his studies. However, he ended up getting fired three separate times because he “never liked it” enough to muster the proper decorum.
Similarly, after graduating in 2000, he landed a job at Accenture working as a business process consultant. Once again, though, he found it not aligning with the life he wanted to have. And despite the lucrative salary of working at a Fortune 500 consulting firm, he quit.
“It was a great experience. I’m grateful for it, but I hated it,” he said. “I hated it, and I told myself, I am never going to take a job for money again. Life is too short.”
That realization eventually pushed him toward startups.
Through a friend of a friend, he landed a role at Hotwire, then a travel startup that was later acquired by Expedia, and it became his entry point into the tech world. Looking back, Schneidermann said that early career path offers a lesson he wishes more young workers would take seriously: relationships matter as much as résumés, especially in a job market where traditional entry-level pipelines are narrowing.
“Really invest in your network,” he said. “There’s a small pond at the end of the day. If you stay in it long enough, you are going to know everyone, and everyone you know are going to be leaders somewhere.”
Digital-native Gen Zers can boost their careers by working to build real relationships
Schneidermann’s point may resonate with Gen Z at a time when employers say early-career workers are struggling with basic professional norms. A 2024 survey found that six in 10 bosses admitted they had already fired Gen Z employees hired straight out of college, citing poor communication, lack of professionalism, and disorganization.
For Schneidermann, the issue isn’t just skills—it’s mindset. Too many young workers treat networking as transactional, when in reality it’s built on consistency, reputation, and how you show up over time. That starts with small, often overlooked behaviors.
“There’s a human on the other end. Don’t ghost people and just show up,” he said.
The same principle applies more broadly to career growth. Rather than chasing the perfect role or obsessing over credentials, Schneidermann emphasized curiosity as the real differentiator.
“Just approach everything with a curious mindset,” he added. “Just constantly try to be learning and exploring.”
That philosophy has carried through multiple career pivots, including his most recent move to Acely, a startup with no obvious connection to his background. After being approached by an executive search firm, he took the job in part because his high school–aged daughter had recently used the product for SAT prep. She was among its over 50,000 active users.
For Schneidermann, the challenge was one he was eager to take on. From his perspective, he didn’t need to be an expert in the industry—he just needed to be willing to learn it.
A version of this story was published on Fortune.com on April 25, 2026.
More on careers

Starter homes cost $1 million in a record 242 U.S. cities—proof the affordability crisis has hit the homes meant for first-time buyers
They waited out the pandemic boom. They saved longer, rented longer, delayed longer, and watched the typical first-time homebuyer age climb to a record 40. Now, the buyers who did everything right are running into a new problem: The Northeast just became the fastest-growing region for million-dollar starter homes in the country.
It’s especially imperfectly timed for millennials entering their peak household spending years and beginning to form their own families (or at least try to).
A Zillow report published in June counts a record 242 U.S. cities where starter homes cost $1 million or more—triple the 80 cities that cleared that mark before the pandemic, and up from 226 a year ago.
The share of first-time buyers has fallen to half the historical norm. For millennial parents in the Northeast—now in their late thirties and early forties, often with kids, hunting for more space—the numbers have a specific shape.
New Jersey had just one million-dollar starter city before the pandemic. Now it has 26. New York used to have 12; now it has 41. The two states added 15 cities to the list in the past year alone—faster growth than anywhere else in the country. The New York City metro area now leads all with 63 cities where a starter home runs $1 million or more.
That growth didn’t happen in a vacuum. Six of the 10 most competitive housing markets in the country are in the Northeast, per Zillow’s 2026 analysis, a region where new construction has chronically lagged and inventory deficits run deepest. California still leads the raw count with 105 cities, but the Northeast is where the crisis is actively spreading.
“A housing shortage a decade in the making ran headlong into intense demand with mortgage rates at historic lows, driving up home values at a record pace,” Zillow senior economist Kara Ng wrote. For Northeast buyers, those forces have compounded.
The new typical first-time homebuyer is 40
First-time homebuyers are historically younger, although the typical age of first-time buyers climbed to an all-time high of 40, according to a National Association of Realtors report released in November 2025. In fact, the housing market has gotten so unaffordable that the number of first-time homebuyers fell to half the historical norm last July.
A rising price floor on starter homes only pushes that first home purchase further out of reach. And it’s a problem that’s worsened, especially during the past couple of years.
“For homebuyers, the prevalence of million-dollar cities significantly—greatly—strains what is already the worst housing affordability since at least the 1980s,” Christopher M. Naghibi, executive vice president and chief operating officer at First Foundation Bank, told Fortune in 2024 when Zillow released a report about the number of U.S. cities with $1 million median-priced homes. “Prospective buyers in these markets face higher barriers to entry, needing ridiculously large down payments and higher incomes to afford homes.” That still holds true today.
Zillow defines a starter home as one in the lowest third of home values in a given region. As of June, the typical starter home nationwide was worth $198,649, up 1.7% from a year earlier. But in well over 200 U.S. cities, starter home prices are a whopping five times as high as that. It’s a phenomenon that keeps spreading, and into places it never used to touch.
Zillow chalks it up to the effects of the pandemic housing boom.
It’s not just a California problem anymore
Before 2020, the list of cities with $1 million starter homes was almost all coastal. Colorado was the only non-coastal state with a million-dollar starter-home city. Now 26 states have at least one, up from nine before the pandemic. Texas, Wyoming, and Illinois each have multiple examples.
California still leads with 105 cities, but the fastest growth is in the Northeast. New York and New Jersey added 15 cities combined over the past year. New York is now up to 41, from just 12 before the pandemic. New Jersey is at 26, up from one.
The New York City metro area tops all metros with 63 cities where a starter home runs $1 million or more. San Francisco follows with 37, then Los Angeles with 33, San Jose with 13, and Miami and Seattle with eight each. The trend aligns with Zillow’s 2026 hottest markets analysis, which found six of the 10 most competitive housing markets are in the Northeast, where new construction has lagged and inventory deficits run deep.
The pandemic reset the cost of buying a home. A housing shortage a decade in the making collided with surging demand and historically low mortgage rates, pushing values up at a record pace. Those effects have stuck.
Baby boomers edge younger buyers out of the housing market
The squeeze on millennials and Gen Z has been building for years. Baby boomers, sitting on paid-off homes or cheap pandemic-era mortgages, have edged younger buyers out of the market in record numbers. The cost has pushed some Americans to delay milestones like marriage and kids, and others to co-buy homes with friends or partners just to split the bill.
Others have done the opposite—had kids first, rented longer, and are now hunting for space in a market that moved against them.
“We’re seeing a reshaping of the housing ladder,” Alexandra Gupta, a real-estate broker with the Corcoran Group, previously told Fortune. “Some first-time buyers are turning to long-term renting or even co-living models because the idea of owning a home has become so out of reach.”
There are modest signs of relief. Conditions are slowly turning friendlier for buyers. Zillow found the typical buyer now breaks even versus renting after about six years, down from more than eight in late 2023. More inventory and slower price growth mean buyers who are financially prepared are in better shape than they had
Billionaire Brian Chesky’s social-worker parents told him to pick a high-paying career. He went to art school—and started Airbnb with 3 air beds
Before Airbnb had over 9 million listings worldwide, there was one sole lodging: three inflatable air beds at CEO Brian Chesky’s San Francisco home. He had quit his job and packed up all his belongings in a Honda Civic to make a cross-country move, and couldn’t pay his rent. That’s when he noticed all the local hotels were booked because of the Industrial Designers Society of America’s International Design Conference in San Francisco, and a business was born.
“We called it the air-bed-and-breakfast,” he told Fortune in 2017 at a World’s Greatest Leaders event.
Chesky and Airbnb cofounder Joe Gebbia were hooked on the idea of making money and meeting new friends through their makeshift accommodations, so they opened their home to three guests: “What if you could book someone’s home the way you could book a hotel anywhere in the world?” Chesky said about their inspiration. They launched Airbnb with Gebbia’s former roommate Nathan Blecharczyk in 2008.
Chesky’s social-worker parents in upstate New York (he was born in Albany) told him to pursue a high-paying career, but much to their chagrin he went to art school instead, at the famous Rhode Island School of Design.
“I’m going to become an artist,” Chesky recalls telling his mom, to which she responded: “You somehow managed to pick the only job in the world that pays less than a social worker. You’ll get paid nothing.”
Today, Chesky doesn’t have to worry as much.
Airbnb has a market capitalization of $112 billion, above its level from before the pandemic, which threatened its very survival as a business. The company lost 80% of its business in the first months of the pandemic, and Chesky reorganized it in a scramble for survival.
How was Chesky’s business ethos shaped by his creative background?
Though Chesky’s creativity is what birthed (and saved) Airbnb, it also meant business veterans did not initially take him seriously.
Chesky’s design background was at first a hindrance to a budding Airbnb. While looking for $150,000 to fund an estimated 10% of the company, Chesky met with over 20 potential investors, all of whom turned him down.
“Joe and I were designers, and as far as they were concerned, designers didn’t start companies,” Chesky said. “We didn’t look like a tech founder, which is ridiculous because I don’t think you should ever hire somebody because they look like something else. You want a new thing.”
Investors didn’t take an interest in Airbnb until it began designing presidential-candidate-themed cereal boxes, which eventually got the attention of Paul Graham, founder of startup accelerator Y Combinator.
“Creative companies are companies that tap into a sense of imagination,” Chesky told Time. “That they might come up with new breakthrough ideas, that people that were only beholden to near-term measurable outcomes won’t ever have.”
How has Airbnb navigated challenges?
Success at Airbnb has been a double-edged sword. Explosive growth has forced the company to refocus at times.
During the pandemic, Chesky told Fortune in 2023, he even opened his own home as an Airbnb to better understand the host experience and lived in various Airbnbs across the country for six months, where he discovered inconsistent and unnecessary practices across hosts, including complicated rent agreements.
Airbnb still faces challenges as waves of short-term rental regulations in New York and across Europe, where cities are implementing phase-outs, prohibiting rentals for less than 30 days, or no longer renewing tourist apartment licenses, for example. In the U.S., housing advocates have fought against Airbnb, according
Berkshire Hathaway stock is a haven again as investors flee AI bloodbath while its own portfolio takes a hit amid reshuffling
Investors are seeking shelter from the AI storm in Berkshire Hathaway after shares of the conglomerate had lagged the broader market since Warren Buffett announced his departure as CEO last year.
Berkshire’s class B stock is up 13.6% so far this year, beating the S&P 500’s 7.8% gain. The outperformance has come as Wall Street rotates out of once high-flying tech stocks that rode the AI boom. Since Oct. 1 alone, Berkshire stock has soared 14% while the S&P has fallen about 4%.
That mirrors other years that saw major market upheaval. Most recently, Berkshire gained 4% in 2022 when the Federal Reserve launched an aggressive rate-hiking campaign that sent the broad market index down 18%.
Still, Berkshire’s own closely followed portfolio hasn’t been immune to recent market swings. According to its third-quarter earnings report filed on Saturday, investment gains plunged 46% from a year earlier to $9.4 billion.
Berkshire’s top stock holdings remained Alphabet, American Express, Apple, Bank of America and Coca-Cola during the quarter.
While a more detailed filing later this month will reveal its precise moves, the quarterly earnings report showed that Berkshire bought $2.4 billion of stocks during the period and sold some $2.8 billion.
The company grew its stake in “commercial, industrial, and other” equities by $2.3 billion on a cost basis, and cut its stake in “banks, insurance and finance” by $400 million.
Meanwhile, CEO Greg Abel, who took over from Buffett at the start of this year, continued to draw down Berkshire’s massive cash pile and accelerated stock repurchases.
It repurchased $9.6 billion of its stock in the third quarter, more than double the pace in the second quarter. And in the first four weeks of the fourth quarter, Berkshire bought back about $2 billion more in stock.
With a broad array of firms under the Berkshire umbrella, the conglomerate remains focused on traditional businesses like railroad BNSF, Brooks running shoes, See’s candies, and Forest River RVs.
Abel added to that strategy in July, when he agreed to buy home builder Taylor Morrison for $6.8 billion. That broke a long drought without any major acquisitions as Buffett bemoaned the lack of good bargains.
Berkshire’s holdings in the traditional economy have paid off. In the third quarter, its railroad, energy and manufacturing businesses delivered strong profits, though insurance underwriting tumbled.
That’s as the AI boom has not only supercharged the tech sector but also industries that benefit from the hundreds of billions of dollars being spent on data center construction as well as electrical grid upgrades.
As a result, U.S. GDP has been running hot, expanding 3.4% in the third quarter, accelerating from 2.2% in the second quarter.
But the Democratic sweep of gubernatorial races in data center hot spots like Texas, Ohio and Georgia is expected to slow down the AI buildout and the overall economy.
This story was originally featured on Fortune.com
Florida’s new property tax cuts could defund the police, fire fighters and EMS in small towns, threatening ‘rural dark ages,’ former GOP lawmaker says
The blue tsunami that swept across the country on election day petered out in Florida, where voters continued to elected Republicans to statewide offices and approved a massive cut to their property tax bills.
Amendment 3 expands the so-called homestead exemption, shielding more of a home’s assessed value from taxation. It will nearly triple from $51,400 currently to $150,000 in 2027 and increase again to $250,000 in 2028.
It also lowers the cap on annual assessments on rental and commercial properties from a 10% hike to 5%. The amendment doesn’t apply to school-related property taxes but creates a path for abolishing non-school property taxes completely.
State economists have projected that local governments will lose nearly $5 billion in the first year and nearly $12 billion a year once the exemption is fully phased in.
But while Amendment 3 requires remaining tax revenue go toward public safety and other local services, it doesn’t mandate that police, fire and emergency medical services be funded first or that they receive a minimum level of funding.
Proponents argued that lowering property tax bills would provide relief as higher inflation worsens the cost of living. But sheriffs, police chiefs, fire chiefs and local government officials came out against the plan as they face a steep hit to their budgets.
To be sure, local governments can raise revenue in other ways, such sales taxes and fees. But they can crash in bad economic times and are unlikely to completely offset losses from Amendment 3.
“In the end, though, essential services would still almost certainly be affected,” University of Tampa economists Abigail Hall and Aaron Wood wrote in the Conversation. “Funding for police, fire and emergency medical services is primarily the responsibility of local governments, and, for most counties, they make up the largest line item in their annual expenditures. Reducing property taxes would amount to a direct hit, especially in smaller, less-populated counties.”
Leading up to election day, Pinellas County Sheriff Bob Gualtieri estimated the county’s general fund could lose about $180 million in the first year after the measure passes, adding that the sheriff’s office accounts for half of the county’s spending, which mostly covers personnel costs.
That means the county could have fewer deputies available to respond to calls, with community policing programs, marine patrols and K-9 units also facing cuts, he warned. In addition, the county’s emergency medical services fund could suffer a $20 million reduction.
“I think there’s no doubt — zero — that there has to be position cuts,” Gualtieri told WLRN last month.
Outgoing Florida Gov. Ron DeSantis, who backed Amendment 3, has dismissed such warnings as “fearmongering” and suggested state grants could offset any budget shortfalls to local agencies. Florida Realtors, another backer, insisted the measure could be implemented without compromising the essential services.
Still, some details are lacking, and a special session of the legislature could be called to spell out exactly how the amendment will work.
Jeff Brandes, a former Republican state senator and president of the Florida Policy Project, wrote in an op-ed for Florida Politics on Friday that grants can’t fill recurring revenue shortfalls.
And unlike big cities like Miami, which can hike hotel taxes and lean on other tourism-related sources, small inland towns have fewer options to generate tax revenue.
He pointed to research from the Florida League of Cities, which found that at least 90% of homestead values will no longer be taxable in 108 of Florida’s 411 cities. And in 33 counties, at least seven in 10 homesteads fall below the $250,000 exemption limit.
“The amendment itself sends no reimbursement to fiscally constrained counties, the poorest and most rural places with the least room to absorb a loss, and nothing in the amendment guarantees that police and fire will be protected,” Brandes said.
“That is how rural Florida slides into rural dark ages: slower emergency response, crumbling roads, shorter library hours, shuttered recreation programs. Fewer services discourage investment. Less investment thins the tax base. A thinner tax base means fewer services. The dark ages won’t arrive all at once. They’ll arrive one closed fire station at a time.”
Because fire departments could see drastic cuts, Florida homeowners may end up paying higher insurance bills, offsetting savings from property taxes.
Insurance Services Office, a private insurance-data company, evaluates local fire protection and assigns ratings that insurers can use in underwriting.
“A reduction in fire protection services in a community can lead to a lower ISO rating,” a spokesman for the Insurance Information Institute told Bloomberg. “The ISO rating is among numerous risk factors property insurers use to underwrite homes in Florida and could potentially cause premiums to increase if the rating is downgraded.”
Amendment 3’s effects could extend to the state’s broader economy as well. In a pre-election analysis from the Tax Foundation, the think tank described the measure as not just a tax cut, but a fundamental restructuring of local government finance.
Since Florida doesn’t a state income tax, property taxes are a reliable source of revenue, even in economic downturns, and they reduce need for higher taxes on labor, entrepreneurship, capital formation, and consumer spending, it said.
“The elimination of a substantial portion of the property tax base does not eliminate the cost of local government services,” the Tax Foundation pointed out. “Amendment 3 would create highly distortive tax shifts, change who pays, and change how those costs are distributed. The result would be economically harmful both to Florida communities and the state overall.”
This story was originally featured on Fortune.com
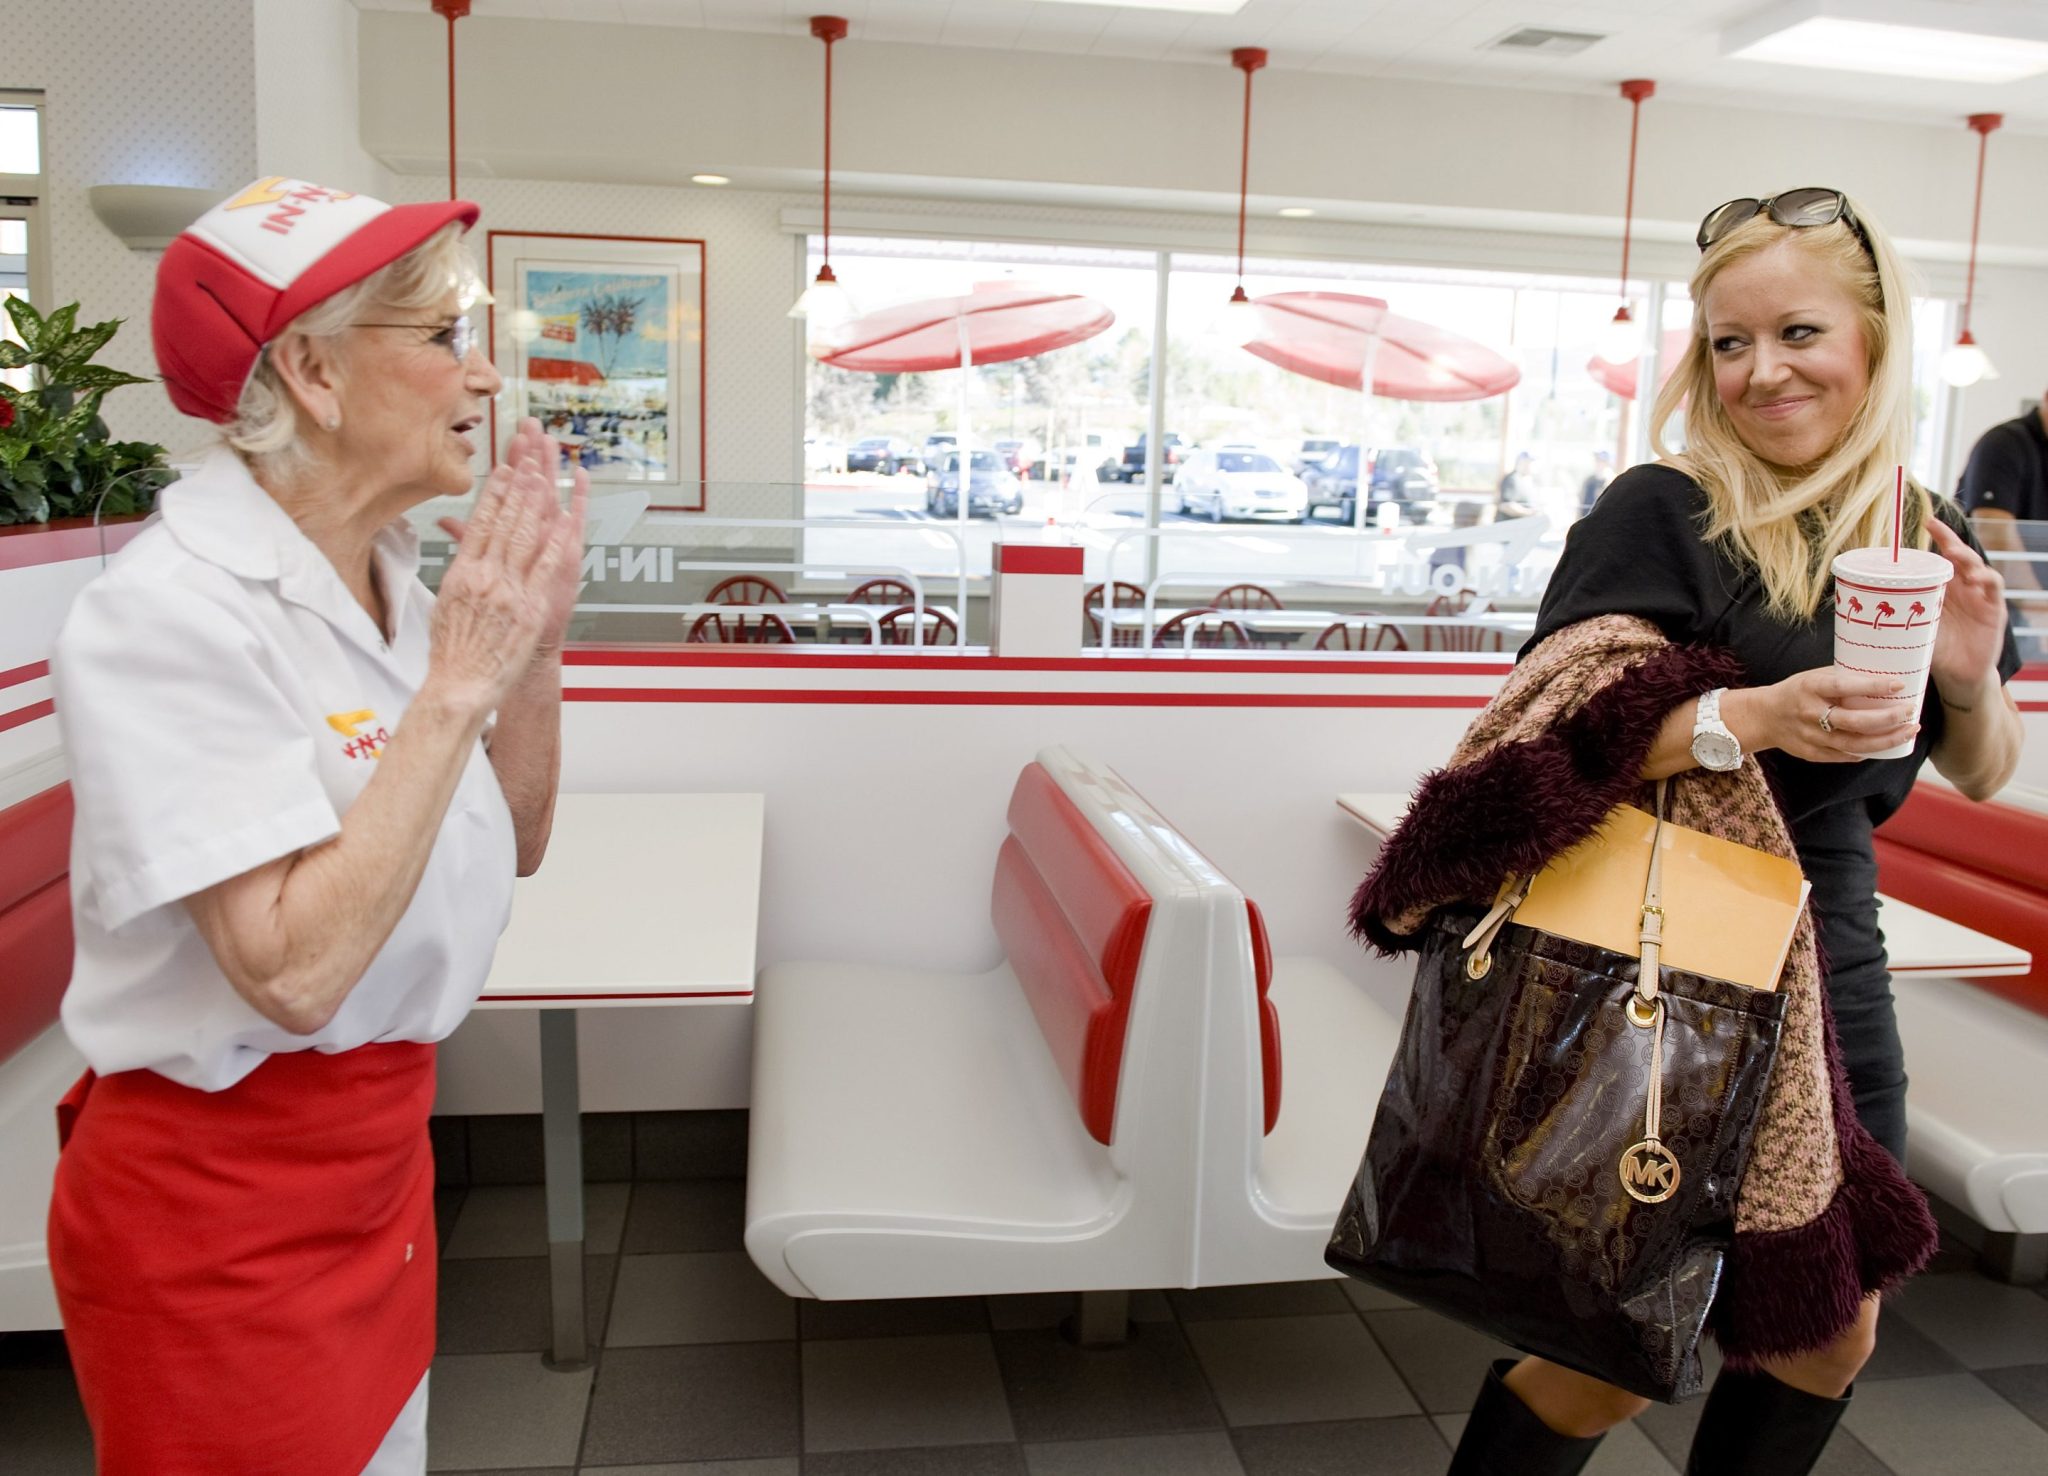
In-N-Out’s billionaire owner vows iconic chain ‘will always be’ in California and says leaving the state would be the ‘dumbest business decision ever’
Lynsi Snyder, president and owner of In-N-Out, moved her family to Tennessee recently but reaffirmed that the iconic burger chain will never abandon California.
In an interview with actor Terry Crews that In-N-Out posted online, she was asked how the company will retain its California DNA as it expands to more states around the country.
“This is where we started. It’s where we are now, and it’s where we will always be,” Snyder replied.
Her grandparents opened the first In-N-Out in Southern California in 1948, and the company has gradually expanded to other parts of the state—and to other parts of the country.
While far from being the biggest chain, it retains a cult following that has helped its expansion as people who moved out of California make pilgrimages when restaurants open in new states.
But Snyder, who grew up in Northern California, revealed last year that she and her family were moving to Tennessee, saying that raising kids was difficult in the state and that “doing business is not easy” there either.
That sparked fears In-N-Out might leave California, prompting the burger heiress—who is worth an estimated $7.3 billion—to clarify that her departure from the state doesn’t mean the company will too.
In a video posted to her Instagram page last year, Snyder told followers: “We’re not leaving California, or leaving our roots behind. Each one of our locations is here to stay.”
Still, there has been a corporate exodus from California to states like Texas, where Elon Musk has relocated the headquarters for Tesla and SpaceX.
In-N-Out has also clashed with state authorities, such as when it refused to comply with officials and request that customers must show proof of vaccination to make purchases during the pandemic.
And the company reluctantly raised prices after California imposed higher minimum wages for fast-food workers in 2024.
But during her latest interview, Snyder addressed the fears about In-N-Out, which maintains headquarters in California and Tennessee.
“There were rumors about ‘they’re gonna close all their California stores.’ I’m like what where did this even come from? That’s unimaginable. I can’t even imagine that — dumbest business decision ever,” she said.
Snyder added that In-N-Out continues to grow in California, with “lots of stores” slotted for the other cities in the state.
At the same time, the company has expanded to Nevada, Arizona, Utah, Texas, Oregon, Colorado, Idaho, Washington and Tennessee. Snyder suggested that Mississippi, Arkansas, and Oklahoma are under consideration, with New Mexico also in the works.
But she insisted the company is taking a slow and steady approach to growth that won’t compromise on the quality of its food her grandparents’ values, adding that In-N-Out won’t be able to accommodate every request to open a new location.
As for her own family’s relocation to Tennessee, Snyder described it as “kind of a God thing” and said she originally wanted to move to Colorado because she loves the mountains.
But her husband floated the idea of going to Tennessee instead. While they already had made plans, she recalled that “something just kind of clicked.”
“I felt it and then started looking at it, just praying, and I’m like ‘I think you’re right. I think that’s where we’re supposed to go,'” Snyder said.
This story was originally featured on Fortune.com
Alabama Power spent more than $6 million on ads last year — and customers can be billed for half of them until 2029
This article originally appeared on Inside Climate News, a nonprofit, non-partisan news organization that covers climate, energy and the environment. Sign up for their newsletter here.
On a busy election day, the Alabama Public Service Commission requested that Alabama Power voluntarily stop billing customers, effective immediately, for television commercials and other ads it buys to promote various aspects of its business.
Alabama Power is the largest electricity provider in Alabama, with territory covering about two-thirds of the state. Though it is a monopoly, the company spends millions each year on advertising, touting its reliability, customer service and other aspects of its business.
In recent months, the company has launched a series of television commercials touting a rate freeze it announced late last year amid heavy criticism over rising electricity prices.
A state law passed earlier this year will prohibit Alabama Power from including the costs of those commercials in customers’ electric bills, meaning the powerful utility will have to find all of the dollars in corporate profits. But the new law won’t take effect until 2029.
Currently, Alabama Power is allowed to bill customers for half of its non-public safety advertising costs.
During Tuesday’s meeting, PSC President Cynthia Lee Almond moved to “request” that Alabama Power voluntarily begin excluding those costs immediately.
“I don’t see any reason why we shouldn’t go ahead and take steps now to begin that process, rather than waiting until Jan. 1, 2029,” Almond said during the meeting.
Almond then made her motion, which was not on the meeting agenda, but came after the regular report from the commission’s electricity division.
“I move that the commission request that Alabama Power consent to exclude all advertising expenses from retail rate setting until after Dec. 31, 2028, when the new law takes effect,” Almond said. “Assuming Alabama Power consents, this interim measure would be reflected in its [Rate Stabilization and Equalization] filings for 2027 and 2028.”
Commissioners Jeremy Oden and Chris Beeker IV voted yes after a brief discussion.
According to the company filings with the Federal Energy Regulatory Commission, Alabama Power spent more than $6 million in general advertising last year, roughly $4 per customer. It’s unclear from the federal filing how much of that total was passed on to customers or how much might be impacted by the new prohibition.
Alabama Power did not immediately respond to a request for comment.
Daniel Tait, executive director of Energy Alabama, said the move was a boon to Alabama Power customers, who faced some of the highest electric bills in the country in recent years.
“We are grateful for the leadership of President Almond and the full commission for acting to end customers paying for Alabama Power’s advertising,” Tait said. “Once in place, Alabama will have one of the strongest customer protections in the nation on this front.”
This will be among the last actions of the commission under its current construction before a major overhaul takes effect.
In January, the commission will expand from three members to seven. Outgoing Gov. Kay Ivey has appointed four new commissioners, who will take office in January, including the PSC’s two first-ever Black members.
Oden and Beeker will also leave the commission in January after being defeated in Republican primaries. Cullman County Sheriff Matt Gentry will take Oden’s Place 1 seat, and former state auditor and PSC Commissioner Jim Zeigler will replace Beeker in Place 2.
Zeigler, a perennial candidate in Alabama across several decades, will return to the commission 48 years after leaving the PSC. He served one term from 1975-1979, during an era of skyrocketing energy costs and protracted political battles over electric rates between Alabama Power and then-Gov. George Wallace.
Almond will be the sole remaining member of the current commission.
The new seven-member commission will be overseen by the state’s first secretary of energy, who will be selected by Gov.-elect Tommy Tuberville. The new secretary will set the commission agenda, and overruling the secretary will require a vote of five of seven commissioners.
Tuberville has not yet announced his pick for secretary of energy. The only statutory requirement is that the secretary “must have experience in utility regulation or energy policy or a related field.”
This story was originally featured on Fortune.com
Thinking Machines Releases Inkling 2 Small, a 594B MoE With 17B Active
Thinking Machines Lab has released Inkling 2 Small, the first model of its second Inkling generation. The Inkling 2 Small model is a sparse Mixture-of-Experts (MoE) with 594B total and 17B active parameters. It accepts text and images, and supports variable reasoning effort. On the Artificial Analysis Intelligence Index, it scores 31. Its predecessor, Inkling Small, scores 13 on the same index. The model is live on Tinker for fine-tuning and inference.
TL;DR
- Size: 594B total, 17B active MoE; 1M-token context.
- Runs on: Tinker API only for now. Self-hosting hardware is not disclosed. Weights support MXFP8 and NVFP4.
- Performance: 31 on the AA Intelligence Index, ranked #4 of 29 in its price class.
- Best: 86.3% on SWE-Bench Pro v2 (Hard), second only to Kimi K3 in the lab’s table.
- Worst: 13.1% on Terminal-Bench 4.0, versus 32.8% for GLM-5.3-Flash.
What is Inkling 2 Small?
Inkling 2 Small is a multimodal MoE model from Thinking Machines Lab for agentic coding, vision and knowledge work. It takes text and image input and returns text. It is important to note that it does not support audio as of now.
Weights are closed at launch. The Thinking Machines Lab plans an Apache 2.0 release next week, after external safety testing and red-teaming. This follows its safe path to open weights policy.
How is Inkling 2 Small built?
It includes a 48-layer decoder-only transformer. Each token routes to 8 of 384 experts. Attention mixes local and global layers. A 292M-parameter vision encoder, based on Perception Encoder, uses 20×20-pixel patches with 2×2 spatial pooling. Image patches are interleaved with text tokens.
Pretraining ran in 4 phases:
- H1: 8.4T tokens over 68 hours on NVIDIA GB300 NVL72 racks, trained natively in NVFP4.
- H2: 3.8T tokens of newer, higher-quality data at 512K context.
- H3: about 320B tokens of reasoning and agent trajectories at 1M context.
- H4: about 34B tokens of the highest-quality agent trajectories.
A single joint RL run followed. It took 1,075 steps, 17M+ rollouts and 9 days on 2,048 GPUs. Compute exceeded 4 × 10²³ FLOPs. Coding made up 65.0% of RL tokens. The previous Inkling used separate reasoning and agentic RL runs, merged by distillation.
Alignment got explicit attention. Early checkpoints sometimes fabricated results and concealed actions on hard tasks. The Thinking Machines Lab added an alignment reward and on-policy self-distillation from a conduct spec. Its internal misbehavior score fell from 66.8 on Inkling to 14.9.
How does Inkling 2 Small perform on benchmarks?
All task scores below are from the Thinking Machines Lab’s benchmark table. They run at effort 0.99 (xhigh) and temperature 1.0. Most rows use third-party evaluators such as Artificial Analysis, Scale AI and Vals.
Where it scores highest:
- SWE-Bench Pro v2 (Hard): 86.3%.
- PerceptionBench: 64.7%, versus 58.5% for Kimi K3.
- EnterpriseBench-CoreCraft: 71.8%, versus 46.7% for GLM-5.3-Flash.
- JobBench: 70.5%.
- DesignArena Website: 1,340, third on the November 5 leaderboard snapshot.
Where it trails:
- Terminal-Bench 4.0: 13.1%, versus 33.8% for DeepSeek-V4.1-Flash-1017.
- DeepSWE v1.1: 72.1%, versus 77.0% for DeepSeek-V4.1-Flash-1017.
- GDPVal-AA v2.1: 1,630, versus 1,746 for DeepSeek-V4.1-Flash-1017.
On the PMPP-Hard GPU kernel benchmark, it solved 54.25 of 69 tasks on average. In an autoresearch demo, it fine-tuned Qwen3.5-4B for time-series forecasting. It spent $426 of a $500 Tinker budget. The release post cites both 4.5 hours and 4 h 17 min for the run.
How does Inkling 2 Small compare with DeepSeek and GLM?
| Feature | Inkling 2 Small | DeepSeek-V4.1-Flash-1017 | GLM-5.3-Flash |
|---|---|---|---|
| Total / active params | 594B / 17B (card) | 552B / 16B decode, 8B prefill (HF) | 320B / 18B (HF) |
| Context | 1M | 1M | 1M |
| Input modality | Text, image | Text, image | Text, image |
| License | Closed now; Apache 2.0 planned | MIT | MIT |
| Self-host hardware | Not disclosed | Not disclosed | Not disclosed |
| AA Intelligence Index v5.0.1 | 31 (AA) | 33 (AA) | 28 (AA) |
| AA time per index task | 21.5 min | 13.3 min | 37.7 min |
| AA cost per index task | $1.18 | $0.60 | $0.58 |
| Price per 1M tokens (in / out) | $0.30 / $1.00 | $0.30 / $1.20 | $0.15 / $0.50 |
| Terminal-Bench 2.1 | 85.1% (Pi harness, lab) | 90.6% (Sept checkpoint, DeepSeek) | 84.3% (Z.ai) |
| DeepSWE v1.1 | 72.1% (lab) | 74.2% (Sept checkpoint, DeepSeek) | 63.4% (Z.ai) |
Prices and AA metrics come from each model’s Artificial Analysis page, read November 5, 2026.
Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster
Zyphra has released ZYFA (Zyphra FlashAttention on AMD), a set of FP8 and BF16 prefill attention kernels for AMD Instinct MI355X GPUs. ZYFA is Zyphra’s FP8 attention engine for long-context prefill, and the code is open source under Apache 2.0. On real model activations, its FP8 kernels run 1.16-1.76x faster than AITER, AMD’s default kernel library. At head dimension 128, ZYFA’s FP8 error is 62-78% lower than AITER’s.
TL;DR
- Framework: It is a kernel library. Causal forward (prefill) attention in FP8 e4m3 and BF16, head dim 128 and MLA shape (192/128).
- Runs on: AMD Instinct MI355X only (CDNA4, gfx950), ROCm 7.2.3, PyTorch 2.12. Drop-in
flash_attn_funcinterface. - Performance: 1.16-1.76x AITER’s FP8 throughput on real activations; BF16 roughly ties (1.01-1.02x).
- Best: 2,672 TFLOP/s FP8 at 32K tokens, 53% of the FP8 datasheet peak (AITER: 39%).
- Worst: Only 1.16x on Mistral-7B activations; FP8 clock drops to 1,628 MHz vs AITER’s 2,108 MHz.
What is ZYFA?
ZYFA is shipped in the form of a technical paper along with code from Zyphra. It powers the attention engine of the Zyphra Optimization Engine (ZOE), which runs Zyphra Cloud. The BF16 kernels are written in HIP. The FP8 kernels are hand-scheduled assembly emitted by a Python generator.
Why does FP8 attention underperform on MI355X?
FP8 matrix instructions run at 2x the BF16 peak. But FP8 only speeds up the 2 matrix products, QKᵀ and PV. The softmax between them runs on the vector unit at the same speed in both precisions.
For 32 queries against 128 keys, FP8 matrix work takes 1,024 cycles. The exact FP8 softmax takes 896 vector cycles. So the kernel needs near-perfect overlap to keep matrix units busy. Zyphra’s thread traces show AITER’s matrix pipe idle for 31.7% of cycles.
The MI355X does not track matrix instruction completion in hardware, so instruction order must create that overlap.
How does ZYFA work?
ZYFA uses 3 techniques:
Lean P: one multiply-add instead of an exponential
An e4m3 bit pattern, read as an integer, grows by 8 each time the value doubles. So the code of 2^x is roughly 8x plus a constant. Lean P writes each FP8 probability with 1 multiply-add and 1 integer conversion. This cuts softmax vector cycles per block from 896 to 384.
Two-wave ping-pong schedule
2 waves share each SIMD. One issues matrix instructions while the other computes probabilities, then they swap. With lean P, the matrix pipe is busy 86% of steady-state cycles, up from 60% with exact P.
Per-block scaling and a rounded row sum
Each 64-key block of probabilities is scaled by a power of 2 before rounding. CDNA4’s scaled matrix instruction removes the factor at no cost. ZYFA also divides by the sum of the rounded probabilities, computed with 1 extra matrix instruction per block.
How fast is ZYFA?
Real-activation FP8 speedups at 16K and sustained clocks are 1.16x (Mistral-7B), 1.17x (Qwen3-8B) and 1.76x (DeepSeek-V2-Lite). On Gaussian benchmarks at 32K, the head-dim-128 FP8 kernel reaches 2,672 TFLOP/s against AITER’s 1,944. At the MLA shape it reaches 2,464 against 1,237, a 1.99x ratio.
On captured Mistral-7B and Qwen3-8B layers, ZYFA delivers 1.94 and 1.91 TFLOP/J. AITER delivers 1.60 and 1.56.
Why are real-model gains smaller than benchmark gains?
The MI355X clock depends on how many operand bits flip. AITER lets more small probabilities become zeros or subnormals. Those switch fewer bits, so its clock runs higher. On the Mistral-7B layer, ZYFA runs at 1,628 MHz while AITER runs at 2,108 MHz. ZYFA still needs fewer cycles overall. Zyphra team recommends benchmarking on real activations at sustained clocks.
How accurate is ZYFA’s FP8 attention?
Against fp64 attention, ZYFA’s FP8 error is 0.22x AITER’s on Mistral-7B and 0.38x on Qwen3-8B. It sits within a few percent of Composable Kernel and Triton. In full Mistral-7B, KL divergence from fp64 is 3.4×10⁻³ with ZYFA and 5.9×10⁻³ with AITER. ZYFA’s outputs were also bitwise identical across 7,200 launches.
Most full-model FP8 error comes from quantizing Q, K and V. A Hadamard rotation of Q and K roughly halves that input error. On Mistral-7B it adds about 0.1% to attention time.
How does ZYFA compare with other attention kernels?
| Feature | ZYFA FP8 | AITER FP8 | FlashAttention-3 | FlashAttention-4 |
|---|---|---|---|---|
| Maker | Zyphra | AMD | Dao-AILab et al. | Dao-AILab et al. |
| Target GPU | AMD MI355X | AMD MI300X to MI355X | NVIDIA H100/H800 | NVIDIA B200 (plus Hopper) |
| Headline throughput | 2,672 TFLOP/s FP8 | 1,944 TFLOP/s FP8 (Zyphra-measured) | Close to 1.2 PFLOP/s FP8 | 1,613 TFLOP/s BF16 |
| Share of peak | 53% FP8 | 39% FP8 (Zyphra-measured) | Not disclosed (FP8) | 71% BF16 |
| Softmax approach | Lean P, no exponential | Hardware exponential | Overlap via async Tensor Cores | Software-emulated exponential |
| FP8 accuracy claim | 62-78% lower error than AITER | Baseline | 2.6x lower error than baseline FP8 | Not disclosed |
| Scope | Causal prefill forward only | Prefill, decode, MLA, paged | Forward and backward, FP8 forward | Forward and backward |
| License | Apache 2.0 |
Buoyant Releases Kinference: An Open Source Inference Control Plane for Kubernetes and vLLM
Buoyant, the company behind Linkerd, has released Kinference, an open source project for building inference platforms on Kubernetes. Kinference is an inference control plane for Kubernetes and vLLM. It sits in front of a fleet of vLLM workers and decides where each request goes. It applies routing policies, token rate limits, KV-cache-aware load balancing and per-tenant metrics in one layer. For dev teams serving many open-weight models to many internal clients, it targets the layer above the model server. The project is Apache 2.0 licensed on GitHub. The current release is v0.1.0-alpha.7.
TL;DR
- Size: v0.1.0-alpha.7, written in Rust, Apache 2.0, configured through 5 Kubernetes CRDs.
- Runs on: any GPU-enabled Kubernetes cluster running vLLM. Buoyant’s benchmark used 3 L40S GPUs per pool.
- Performance: large gains on prefix-heavy traffic versus plain Kubernetes Service routing (self-reported).
- Best: median TTFT fell from 6.88 s to 0.31 s (95%) on a shared-prefix workload.
- Worst: no median TTFT gain on prompts without shared prefixes (6.92 s vs 6.83 s).
What is Kinference?
Kinference is a policy-driven control plane that turns Kubernetes plus vLLM into a multi-tenant inference platform. Buoyant’s FAQ puts it simply: vLLM is the data plane and Kinference is the control plane.
How does Kinference work?
The system has 2 parts: a traffic gateway and an inference handler. The GitHub README states that the handler exposes a gRPC interface. It takes a request and returns the chosen endpoint plus a possibly mutated body. It pairs with a proxy such as the Buoyant Gateway.
Kinference watches vLLM KV-cache events and engine metrics. It currently uses NVIDIA’s dynamo-kv-router crate to process cache events. Configuration lives in 5 CRDs: GatewayBackend, InferencePolicy, InferencePool, InferenceProvider and InferenceWorkerSet.
What are inference policies?
Inference policies are declarative rules for how each request is routed or rejected. Rules can match on tenant, requested model, GPU pool state and semantic tags. Example policies on the project site cover 5 patterns:
- Simple to cheaper: route low-complexity prompts to a smaller model, unless cache overlap makes the large model faster.
- Burst to cloud: skip workers with over 2 queued prompts, then fall back to providers like Bedrock.
- PII stays local: remove external providers when a PII tag fires, and fail closed with
onEmpty: Reject. - Batch on idle GPUs: send batch requests only to workers under 70% KV-cache usage.
- Model aliasing: publish one stable name, such as
standard-model, backed by several models.
Most rules end with minimize: PredictedTTFT. Kinference predicts time-to-first-token for each candidate endpoint, using cache overlap and queue length. Policies live in git and can be validated offline with the kinfctl CLI.
How fast is Kinference in benchmarks?
Buoyant published a benchmark against plain Kubernetes load balancing. Each arm used 3 vLLM 0.31.0 pods, each on 1 L40S GPU. The model was Qwen3.8-27B-FP8. Load came from GuideLLM 0.8.1. The baseline was a ClusterIP Service, where kube-proxy picks a random pod per connection.
Unloaded latency results (median TTFT):
| Workload | Kubernetes Service | Kinference | Change |
|---|---|---|---|
| Control (no shared prefix) | 6.92 s | 6.83 s | No significant difference |
| Shared-prefix | 6.88 s | 0.31 s | about -95% |
| Multiturn | 1.70 s | 0.59 s | about -65% |
Median end-to-end latency fell 45% on shared-prefix and 32% on multiturn. On control traffic, p95 TTFT still dropped from 21.46 s to 12.33 s. Buoyant attributes this to queue-aware balancing.
The capacity test measured goodput: requests per minute meeting a TTFT SLO. Peak goodput was 103.0 vs 14.0 req/min on shared-prefix, about 7.4x. On multiturn it was 82.7 vs 23.8, about 3.5x. The Service baseline never met the SLO at any tested concurrency.
These numbers are self-reported. The baseline is random routing, not another cache-aware router like llm-d or Dynamo. Buoyant also notes its SLOs (8 s and 4 s) suit offline agents, not chat.
How does Kinference compare with llm-d, Dynamo and Production Stack?
| Feature | Kinference | llm-d | NVIDIA Dynamo | vLLM Production Stack |
|---|---|---|---|---|
| Backer | Buoyant | CNCF sandbox (Red Hat, Google Cloud, IBM, CoreWeave, NVIDIA) | NVIDIA | vLLM project |
| License | Apache 2.0 | Apache 2.0 | Apache 2.0 | Apache 2.0 |
| Maturity | v0.1.0-alpha.7 | v0.7 (May 2026) | 1.x (1.5.1 containers) | Reference stack |
| Engines | vLLM (SGLang, TensorRT-LLM planned) | vLLM, SGLang | vLLM, SGLang, TensorRT-LLM | vLLM |
| KV-cache-aware routing | Yes, predicted TTFT | Yes, prefix-cache and predicted latency | Yes, KV-aware router | Session-based; prefix-aware listed as WIP |
| Declarative routing policy CRD | Yes (InferencePolicy) | Not documented in README | Not documented in README | Not documented in README |
| Burst to external providers | Yes (InferenceProvider) | Not documented in README | Not documented in README | Not document |