
Try my dang hardest to come up with novel research ideas, but everything feels clunky [R]
Im an incoming masters student in ML, a bit older than most (31). I’ve read 100s of papers over the last 7/8 years from the foundational papers in the field to niche papers that never got adopted (Hinton’s forward forward, capsule networks). Ive also replicated dozens of papers during this time.
It may seem small to most here, but It would be an amazing dream to do publish a conference quality paper but all my research ideas feel so clunky, inelegant and crude. My ADHD lets me to spawn hundreds of ideas and hyperfocus on a couple, so far all my preliminary work doesnt point to anything really novel.
I dont understand how first authors come up with beautiful results like engrams, diffusion models, VAEs, MoEs, token superposition in pretraining, that seems so obvious when you read the paper but clearly are anything but obvious.
Are these people just built different or did their research also start off clunky? Is it just luck? Most PIs dont expect to lead the research so it cant be an astute PI?
[link] [comments]
Thinking Machines Releases Inkling 2 Small, a 594B MoE With 17B Active
Thinking Machines Lab has released Inkling 2 Small, the first model of its second Inkling generation. The Inkling 2 Small model is a sparse Mixture-of-Experts (MoE) with 594B total and 17B active parameters. It accepts text and images, and supports variable reasoning effort. On the Artificial Analysis Intelligence Index, it scores 31. Its predecessor, Inkling Small, scores 13 on the same index. The model is live on Tinker for fine-tuning and inference.
TL;DR
- Size: 594B total, 17B active MoE; 1M-token context.
- Runs on: Tinker API only for now. Self-hosting hardware is not disclosed. Weights support MXFP8 and NVFP4.
- Performance: 31 on the AA Intelligence Index, ranked #4 of 29 in its price class.
- Best: 86.3% on SWE-Bench Pro v2 (Hard), second only to Kimi K3 in the lab’s table.
- Worst: 13.1% on Terminal-Bench 4.0, versus 32.8% for GLM-5.3-Flash.
What is Inkling 2 Small?
Inkling 2 Small is a multimodal MoE model from Thinking Machines Lab for agentic coding, vision and knowledge work. It takes text and image input and returns text. It is important to note that it does not support audio as of now.
Weights are closed at launch. The Thinking Machines Lab plans an Apache 2.0 release next week, after external safety testing and red-teaming. This follows its safe path to open weights policy.
How is Inkling 2 Small built?
It includes a 48-layer decoder-only transformer. Each token routes to 8 of 384 experts. Attention mixes local and global layers. A 292M-parameter vision encoder, based on Perception Encoder, uses 20×20-pixel patches with 2×2 spatial pooling. Image patches are interleaved with text tokens.
Pretraining ran in 4 phases:
- H1: 8.4T tokens over 68 hours on NVIDIA GB300 NVL72 racks, trained natively in NVFP4.
- H2: 3.8T tokens of newer, higher-quality data at 512K context.
- H3: about 320B tokens of reasoning and agent trajectories at 1M context.
- H4: about 34B tokens of the highest-quality agent trajectories.
A single joint RL run followed. It took 1,075 steps, 17M+ rollouts and 9 days on 2,048 GPUs. Compute exceeded 4 × 10²³ FLOPs. Coding made up 65.0% of RL tokens. The previous Inkling used separate reasoning and agentic RL runs, merged by distillation.
Alignment got explicit attention. Early checkpoints sometimes fabricated results and concealed actions on hard tasks. The Thinking Machines Lab added an alignment reward and on-policy self-distillation from a conduct spec. Its internal misbehavior score fell from 66.8 on Inkling to 14.9.
How does Inkling 2 Small perform on benchmarks?
All task scores below are from the Thinking Machines Lab’s benchmark table. They run at effort 0.99 (xhigh) and temperature 1.0. Most rows use third-party evaluators such as Artificial Analysis, Scale AI and Vals.
Where it scores highest:
- SWE-Bench Pro v2 (Hard): 86.3%.
- PerceptionBench: 64.7%, versus 58.5% for Kimi K3.
- EnterpriseBench-CoreCraft: 71.8%, versus 46.7% for GLM-5.3-Flash.
- JobBench: 70.5%.
- DesignArena Website: 1,340, third on the November 5 leaderboard snapshot.
Where it trails:
- Terminal-Bench 4.0: 13.1%, versus 33.8% for DeepSeek-V4.1-Flash-1017.
- DeepSWE v1.1: 72.1%, versus 77.0% for DeepSeek-V4.1-Flash-1017.
- GDPVal-AA v2.1: 1,630, versus 1,746 for DeepSeek-V4.1-Flash-1017.
On the PMPP-Hard GPU kernel benchmark, it solved 54.25 of 69 tasks on average. In an autoresearch demo, it fine-tuned Qwen3.5-4B for time-series forecasting. It spent $426 of a $500 Tinker budget. The release post cites both 4.5 hours and 4 h 17 min for the run.
How does Inkling 2 Small compare with DeepSeek and GLM?
| Feature | Inkling 2 Small | DeepSeek-V4.1-Flash-1017 | GLM-5.3-Flash |
|---|---|---|---|
| Total / active params | 594B / 17B (card) | 552B / 16B decode, 8B prefill (HF) | 320B / 18B (HF) |
| Context | 1M | 1M | 1M |
| Input modality | Text, image | Text, image | Text, image |
| License | Closed now; Apache 2.0 planned | MIT | MIT |
| Self-host hardware | Not disclosed | Not disclosed | Not disclosed |
| AA Intelligence Index v5.0.1 | 31 (AA) | 33 (AA) | 28 (AA) |
| AA time per index task | 21.5 min | 13.3 min | 37.7 min |
| AA cost per index task | $1.18 | $0.60 | $0.58 |
| Price per 1M tokens (in / out) | $0.30 / $1.00 | $0.30 / $1.20 | $0.15 / $0.50 |
| Terminal-Bench 2.1 | 85.1% (Pi harness, lab) | 90.6% (Sept checkpoint, DeepSeek) | 84.3% (Z.ai) |
| DeepSWE v1.1 | 72.1% (lab) | 74.2% (Sept checkpoint, DeepSeek) | 63.4% (Z.ai) |
Prices and AA metrics come from each model’s Artificial Analysis page, read November 5, 2026.
ToyBlocks: A controlled world for robot learning and evaluation

当芯片抢着上太空,半导体下一轮增量有了?
(本文作者为 半导体产业纵横,钛媒体经授权发布)
文 | 半导体产业纵横
11月初,谷歌宣布,自研TPU首次在轨运行AI模型并返回结果。这次试验背后的目标,是把多颗搭载TPU的卫星连接起来,在轨道上组成计算集群。
一天后,马斯克预测,到2028年底,轨道算力的每月新增部署量可能超过地面。SpaceX此前已将经过适配的英伟达Vera Rubin系统纳入首代计算卫星方案。英伟达也已公布面向轨道数据中心的计算模块,并与卫星制造商合作,准备将芯片和软件随卫星平台一起交付。
建设计划甚至延伸到了火箭本身。10月26日,轨道基础设施公司Cowboy Space公布Big Iron方案,计划让火箭上面级抵达轨道后转为数据中心,设计承载五个英伟达GPU计算机架。运载火箭既负责把计算设备送上天,也将成为太空机房的一部分。
从芯片在轨测试到计算卫星组网计划,云厂商、芯片巨头和航天企业正在同时布局。这场向太空延伸的算力竞赛,会为半导体产业带来多大的增量?
01 巨头开始规划太空机房
泰伯智库10月发布的研究预计,全球太空算力市场将从2025年的约29亿美元增至2030年的190亿美元。其统计涵盖单星智能、算力星座和太空数据中心:既包括卫星就地处理数据,也包括多颗卫星组成计算网络,以及独立的大型轨道计算设施。几类业务的投入与成熟度不同,报告判断,2030年前仍主要由单星智能支撑。
SpaceX准备建设的,则是更大规模的轨道计算设施。按照已公布的合作安排,其首代Starmind计算卫星将采用经过适配的英伟达Vera Rubin NVL72系统,目标在2027年第四季度发射,2028年形成显著规模。计算架构与地面系统保持联系,而卫星制造和发射,则由SpaceX已有的航天业务提供基础。
对谷歌这样的云厂商,轨道设施提供的是另一种扩张可能。国际能源署今年4月预计,全球数据中心年用电量将从2025年的485TWh增至2030年的950TWh,电网接入与能源设备正在限制更快的扩张。Suncatcher考虑的特定太阳同步轨道能够获得近乎持续的日照,让新增算力减少对地面电网、土地和当地建设进度的依赖。
谷歌为这一探索保留了较长的时间。皮查伊10月21日谈及Suncatcher时,将其与Waymo早期的自动驾驶研究相比,认为十年至二十年后可能发挥重要作用。马斯克已经给出月度部署规模的预期,皮查伊谈论的则是长期研究的价值。对于已有芯片、模型和云业务的谷歌,当前试验是在为未来的基础设施建设保留选择。
投资机构Space Capital在10月13日发布的三季度报告中指出,SpaceX已经停止接受2028年末之后的拼车发射预订,行业需要更多运力来源。对于太空算力建设者,芯片交货之后,设备能否按计划入轨还决定着上线时间。发射能力因此也在影响哪些企业有条件组织大规模部署。
10月26日,轨道基础设施公司Cowboy Space发布Big Iron火箭方案:上面级到达轨道后不被丢弃,而是成为数据中心,设计承载五个英伟达GPU计算机架。公司申请的Stampede星座规模达到两万颗卫星,火箭首飞目标为2028年。
创始人Baiju Bhatt解释,公司原本想建设太空数据中心,却发现没有足够的火箭可用,因此决定自行开发。它希望把运载器外壳继续用作散热结构,让运送设备和承载计算共用部分硬件。这个方案将发射与机房建设放在了一起,运营商要考虑的,已经包括怎样把计算设备成批送到轨道,并让运输设施继续参与运行。
在轨道数据中心公司Starcloud的设想中,设施建成后既可以出售GPU计算时间,也可以提供供电、冷却和连接,让客户选择芯片。创始人Philip Johnston今年5月介绍了这两种经营方式。前一种方式需要运营商组织计算平台,后一种则把芯片选择留给租用设施的客户。同样是轨道数据中心,最终决定计算架构的,可能是设施运营商,也可能是云厂商,芯片企业争取的合作对象因此不只是一家卫星制造商。
02 芯片上天,竞争延伸到整套平台
谷歌的在轨TPU返回首个AI结果之后,Suncatcher还要继续验证芯片在热应力和辐射下的表现。原型星由谷歌与Planet合作开发,2027年的下一步是测试两颗卫星之间的连接。更远期设计考虑每星搭载数十颗TPU,通过高带宽激光链路协同工作,将分散在卫星上的芯片组成计算集群。
谷歌特别指出,现有星间通信多为长距离、较低带宽设计,而其AI任务需要短距离、高带宽连接。单颗芯片能够运行模型之后,还要解决多颗芯片怎样共同完成任务的问题。卫星集群能否有效协同,直接影响增加处理器能带来多少实际算力,也让通信与系统集成成为芯片之外的重要投入。
英伟达则把自己的计算平台提供给不同的航天客户。今年3月公布的Space-1 Vera Rubin模块面向轨道数据中心,Jetson Orin、IGX Thor等产品则面向星上推理。客户可以从处理卫星图像的小型模块开始,再向更大计算系统扩展,继续使用英伟达的软件工具。
这种安排已经进入卫星制造商的产品规划。EnduroSat今年8月宣布与英伟达合作,将计算模块逐步集成到FRAME系列卫星平台中,并支持CUDA、TensorRT等软件。按双方规划,客户购买的将是已完成集成的轨道AI平台,不必每次从芯片、软件到卫星重新组织开发。Space-1也被列入后续适配路线,随产品可用性逐步推进。
EnduroSat在10月披露,其卫星产线具备每日交付两颗的能力。公司采用共用模块、软件及生产流程,客户提供任务载荷,EnduroSat负责卫星平台、集成测试和在轨运营。计算模块成为标准平台的一部分后,便有机会随不同客户的任务重复部署。对于芯片厂商,一次集成能够服务后续多个项目,采购关系也有机会随着卫星的批量制造延续下去。
10月21日,EnduroSat又与航天企业Redwire签署合作备忘录,将欧洲轨道数据中心列为共同探索的方向。双方拟把EnduroSat的卫星批量制造能力,与Redwire的供电系统及大型项目承包经验结合起来,目标客户包括政府、国防和商业机构。计算模块、卫星平台、供电和项目交付,也由此进入同一套合作规划。
已有卫星上的算力,也开始通过云平台向开发者开放。10月30日,北京太空算力创新中心发布天地一体化太空算力云平台,将卫星上的计算资源与地面算力统一管理。开发者可以通过平台部署模型,让卫星在轨处理数据,再将结果传回地面。平台目前覆盖40余颗卫星的算力资源,并与百度智能云百舸平台互通,可以调用相关模型和数据集接口。
清华大学教授崔勇介绍,卫星可以就近处理数据,地面算力中心承担大模型训练与弹性扩容。这使轨道资源能够成为现有云服务的一部分,无须把所有计算都搬到天上。对于芯片厂商和云服务商,进入太空市场既可以是参与新建大型设施,也可以是为已有卫星增加计算和调用能力。
03 从卫星订单,到更大的算力市场
北京太空算力创新中心CTO刘志飘认为,在轨推理已经逐渐商用,大规模预训练上天至少还需要五至八年。卫星自身的任务和地面AI业务,对计算规模、通信条件及成本的要求不同,也在影响眼下的采购。
法国航天局的项目已经收到搭载AI计算模块的卫星。10月27日,Loft Orbital披露,刚入轨的Altair-1成为法国航天局两个项目的首项交付,其中地球观测合同从签署到首星入轨不到六个月。卫星搭载英伟达Orin模块,可以直接运行AI模型,为后续任务提供计算能力。
对观测任务而言,卫星采集影像后,就地识别火情、船舶或其他目标,再将结果传回地面,可以减少原始数据下传的压力。这类需求不必等待轨道GPU的租赁价格全面低于地面,就有采用星上AI的理由。芯片和计算模块可以先进入这些已有任务,逐步积累运行记录。
国内制造商也已接到成批订单。11月5日启动港股招股的国星宇航披露,截至10月28日,公司已有114颗待交付AI卫星订单,合约总值约35亿元。商汤是其中一个明确的采购方,今年7月已订购两颗AI智算卫星,用于其星座初期部署和在轨验证。
国星宇航计划在2027年、2028年分别研制36颗、60颗卫星,并与两家发射服务商订立长期合作,提前锁定运力,具体交付进度还取决于审批、客户订单和发射安排。其募资用途还包括寻找战略投资与收购机会,潜在范围涉及星载计算芯片、能源系统等供应商,目前尚未确定目标。计算能力成为卫星产品的重要组成部分后,制造商也开始考虑向相关上游环节延伸。
面向地面客户的大型轨道机房,则要在计算成本上接受另一种比较。谷歌能源负责人关于最高百倍成本的判断,针对的是当前建设条件;公司持续推进的Suncatcher仍是长期研究。贝索斯今年5月也提醒,能源通常不到地面数据中心总拥有成本的15%,只减少电费,并不足以抵消发射等新增支出。
芯片的工作寿命和更新方式也会进入这笔账。Starcloud表示,最初几代系统不打算依靠机器人维修,而是通过冗余与软件绕开故障,让设备在设计寿命内自主运行。对于芯片供应商,适配和验证必须与整套系统一起完成;对于运营商,设备损坏、替换和利用率都会影响能否收回投入。先在特定卫星任务中形成需求,与大规模承接地面AI业务,因而是两种不同的商业进程。
04 结语
太空算力已开始带来卫星、计算模块和平台建设的需求,巨头争取的还有未来更大规模部署时的架构与服务选择。现阶段,已有卫星任务让芯片找到客户;下一步,轨道机房能否持续扩大采购,还要看批量部署后的成本、设备寿命与利用率能否支撑长期运营。芯片进入太空已经有了实绩,新市场的规模还要由这些建设与经营安排逐步兑现。
更多精彩内容,关注钛媒体微信号(ID:taimeiti),或者下载钛媒体App
Higgs Realtime Duplex: a 45B MoE full-duplex model that listens, watches and talks at once, and thinks, calls tools and delegates in the background [N]
Disclosure: I'm at Boson AI and this is our release. Not open weights; the Duplex API has a waitlist, and the previous turn-based Higgs Realtime is available now.
Most voice models are still turn-based: listen, wait for end of turn, think, speak. Duplex runs all streams at once and keeps working in the background while it talks.
Streams. Everything is cut into 160 ms chunks:
- Audio in: 1 token per chunk (6.25 tokens/s)
- Audio out: 2 tokens per chunk (12.5 tokens/s)
- Video in: one ~12-token camera frame every 6 chunks
- Face out: 2 latents per chunk
- Text in and out alongside
Silence is represented as chunks too, which is what the model uses to decide when to backchannel, interrupt or stay quiet. That comes to ~2.6K tokens per minute for audio and video, 2.6K to 5K with thinking and tool traces (progressively compacted). The last 5 minutes plus compacted text history is 13K to 25K tokens; older history is kept as text.
Background work. Thinking, tool calls and delegation are spans in the same stream and can cover many chunks. Tool results can arrive in stages and the model can start speaking before they are complete. Harder problems are delegated to a much larger backend model with the full shared context. This is the main difference from Thinking Machines' interaction models, where all reasoning and tool use goes to the background model, which can mean 10+ seconds per answer and makes cost harder to control.
Voice and face. Set zero-shot at deployment: a short reference clip for the voice, one image for the face, and a text prompt for behavior. No fine-tuning. Audio comes from a causal flow-matching decoder (2 frames per chunk), the face from a causal DiT conditioned on the reference image and the previous two latents.
Training. Starts from a text-pretrained LLM, continued pretraining on ~2T tokens of text, audio and video on our own H100 cluster (Megatron-based stack). Post-training is multi-teacher on-policy distillation: specialist teachers trained with RL (including GRPO) on conversation, interaction timing, delegation and task completion, distilled into one student. On top of that, a self-improvement loop in simulated environments with realistic timing, interruptions, overlapping speech and background noise.
Benchmarks. Best published or reproduced configuration from each lab (we reproduced more than half of the competitor numbers):
| Benchmark | Duplex (45B) | TML Interaction Small (276B) | OpenAI best | Google best |
|---|---|---|---|---|
| Big Bench Audio | 98.9 | 96.5 (75.7 w/o background agent) | 97 | 98 |
| Audio MultiChallenge (APR) | 44.9 | 43.4 | 48.5 | 36.1 |
| Full-Duplex-Bench v1.5 | 75.5 | 77.8 | 80.1 | 54.3 |
| QIVD (streaming) | 56.0 | 54.0 | 58.2 | 56.1 |
| ProactiveVideoQA (PAUC) | 31.9 | 33.5 | 25.0 | – |
| τ-Voice (pass@1) | 69.8 | – | 74.5 | 68.6 |
| IFEval | 94.1 | 89.7 | 95.2 | 90.0 |
OpenAI's best settings lead on five of seven, by 1 to 5 points, several at their highest thinking setting. Turn-taking (Full-Duplex-Bench) is where we're furthest behind. Our takeaway is that at this size, data and training matter more than parameter count; the front model is deliberately mid-sized because the design target is that an hour of model time costs at most a tenth of an hour of human time.
Announcement with demos: https://www.boson.ai/blog/higgs-realtime-duplex My write-up: https://alex.smola.org/posts/50-talking-while-thinking/
Happy to answer questions about the chunked-stream design and the delegation setup.
[link] [comments]
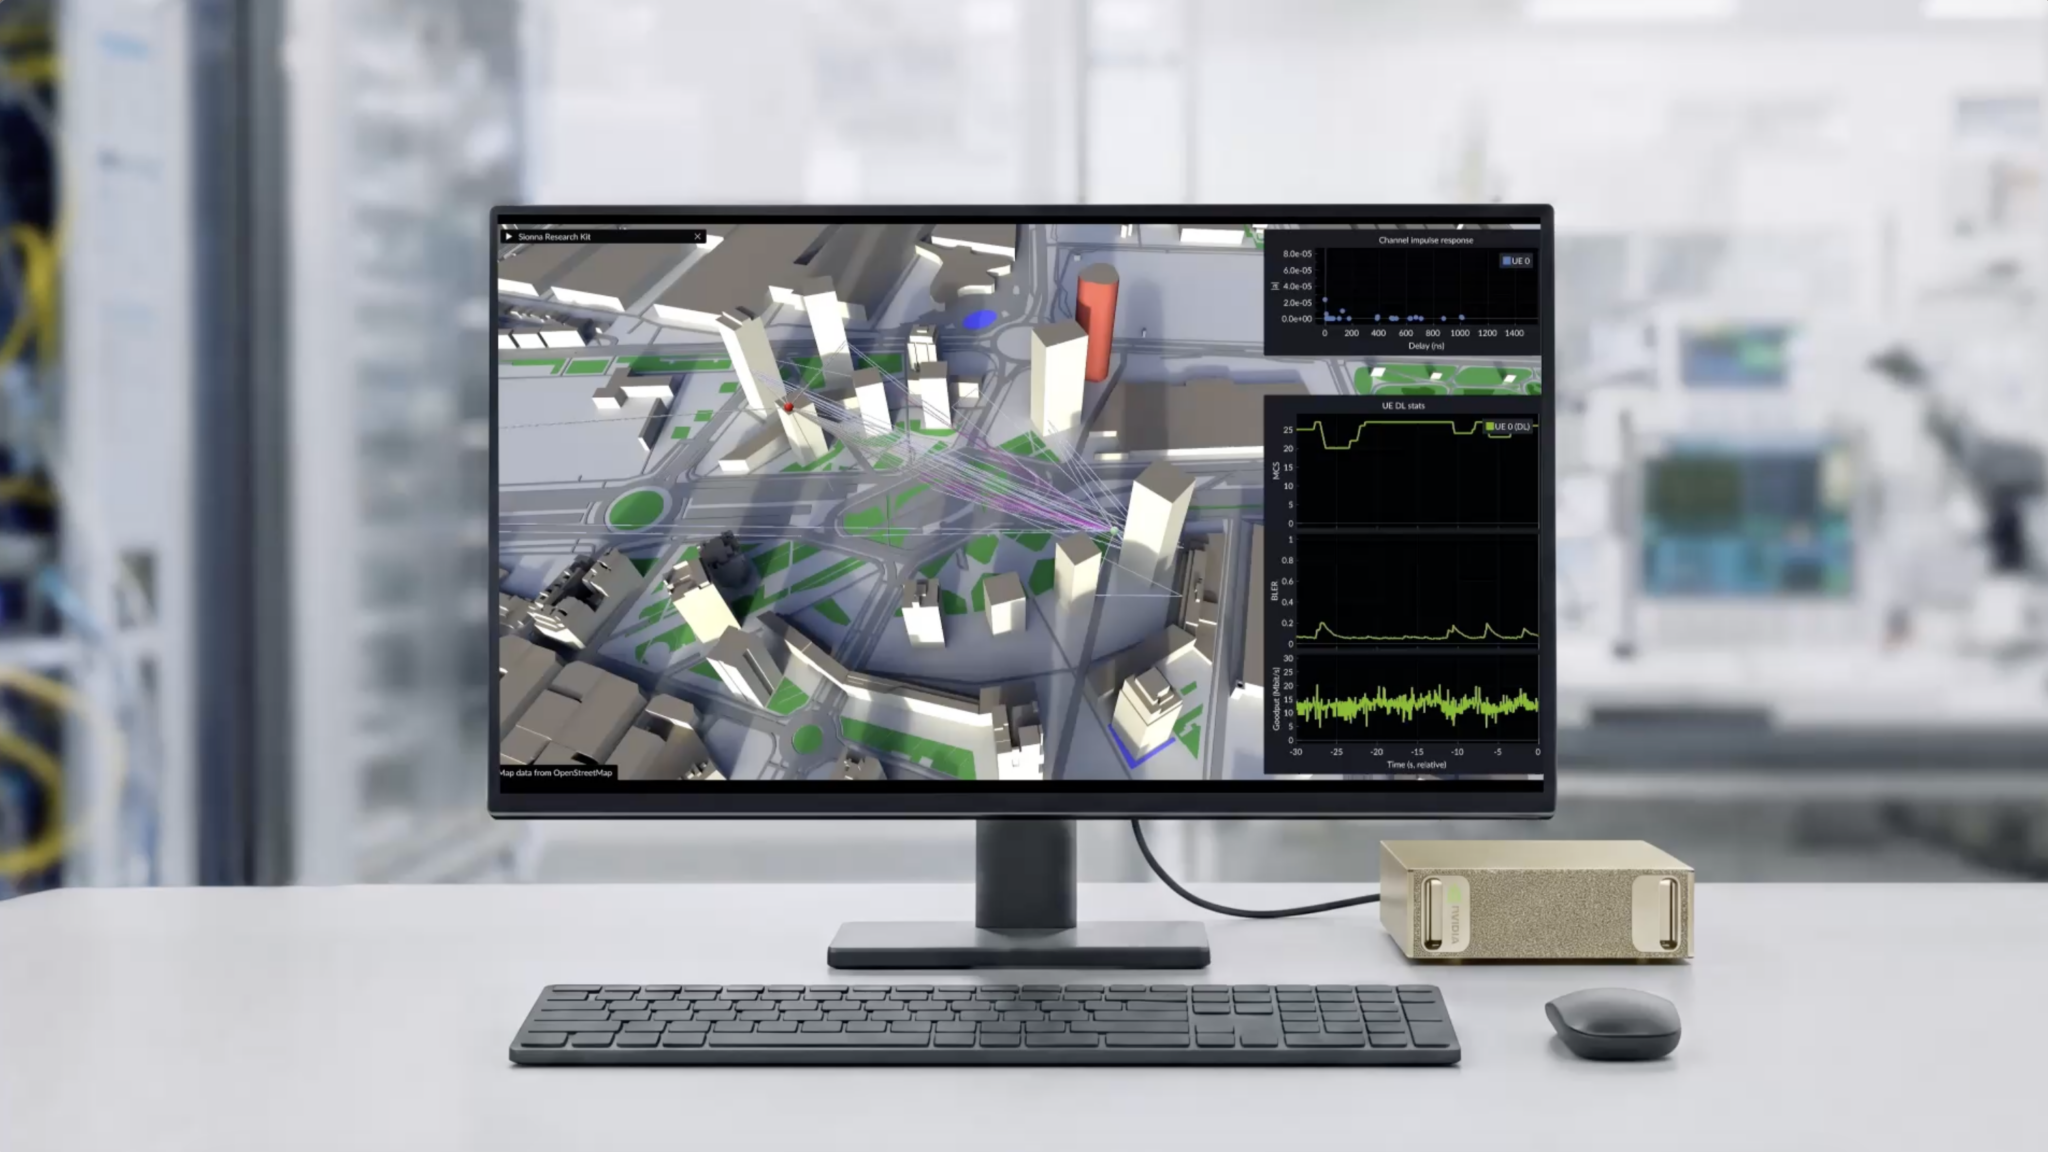
How NVIDIA Open Source Tools Are Helping Researchers Build Next-Generation 6G Networks
A year ago, NVIDIA open sourced its Aerial wireless software, joining Sionna and a broader suite of open source tools for accelerating next-generation 6G network development. Together, they give researchers a foundation for testing ideas, comparing results and building on each other’s work — connecting simulation and AI training with experiments on real over-the-air wireless systems.
Today, researchers and developers are using these tools to build 6G-ready networks that do more than just transmit data — receiving signals more effectively, keeping robots and autonomous systems connected when it matters most, and adapting in real time as devices move through the world.
Over the past year, global developer adoption of NVIDIA AI Aerial and NVIDIA Sionna software has grown 10x, while NVIDIA’s open source 5G/6G tools have surpassed 1 million downloads. More than 8,000 research and academic institutions worldwide are using these platforms.
The projects emerging today offer a view of how future networks could look. Each addresses a different challenge, but together point toward a broader ambition for building AI-native 6G networks that deliver connectivity, computing and sensing over a converged software-defined platform for billions of people, machines and agents.
Networks That Help Robots React Faster
A robot picking up an object needs to understand its surroundings and act before they change. When the AI powering that decision runs on a nearby server or in the cloud, the wireless connection becomes part of the response time.
Researchers are exploring a more efficient approach called goal-oriented semantic communications. Instead of sending full images, robots transmit compact descriptions of objects, their positions and their relationships. Transmitting just as much information as needed allows robots to more quickly respond, especially in dynamic environments like workplaces and warehouses.
At King’s College London, researchers connected a camera-equipped robot arm to an NVIDIA Jetson AGX Orin running NVIDIA Sionna, which supports both software-defined 5G network and edge AI processing. In fruit-packing and cube-stacking experiments with deliberately introduced faults, the approach reduced robot task completion time by up to 52.6% and improved task success compared with sending periodic images.
In addition to quicker responses and less processing overhead, the system also proved more resilient — detecting dropped objects, recovering from unsuccessful actions and, in configurations using a digital twin, checking planned movements for potential collisions before execution.
Networks That Learn to Receive Signals Better
For a firefighter receiving live drone footage or a rescue team searching for a missing person, timely images can help guide urgent decisions. But interference and changing radio conditions can make wireless signals harder to decode, causing errors and retransmissions that delay information from the field.
AI receivers address this challenge by learning to recover information from incoming signals more effectively. Better reception could help responders maintain a clearer, more current view of a fire scene or search area.
SoftBank demonstrated this by integrating a neural receiver into NVIDIA Aerial CUDA-Accelerated RAN (ACAR) and testing it with a commercial 5G smartphone. In controlled tests with interference, the neural receiver delivered higher uplink throughput than a conventional receiver at all 15 tested settings, with a maximum gain of roughly 60%.
Another way to improve reception is to teach receivers about the environments where they operate. Using NVIDIA Aerial Testbed, ETH Zurich researchers found that tuning neural receivers using local measurements reduced block error rates by more than one-third compared with selected pretrained versions.
Networks That Learn When to Save Power
As 6G connects more devices and supports more AI applications, managing energy demand will become increasingly important.
For example, a network may need enough capacity to serve a busy stadium, but demand changes when the crowd leaves. AI can help identify when spare capacity can power down — and when it needs to come back online — so operators can reduce electricity use without dropping connections.
At the University of Leeds, researchers developed a system that predicts network demand 10 minutes ahead and uses those forecasts to guide base station sleep decisions. Before powering down, it checks that neighboring active stations can continue serving affected devices and monitors for changes that require capacity to be restored.
The team tested their approach using a portable, NVIDIA DGX Spark-powered 5G “network-in-a-box” alongside a digital twin for validating decisions against real wireless equipment. The result: researchers reported a 45.6% reduction in RAN power consumption relative to a full-power baseline while maintaining device connectivity.
Networks That Can Be Tested Faster — Before They’re Built
Before deploying a network, researchers need to know how it will perform when hundreds of devices compete for connections or radio signals run into interference. Simulating these conditions helps teams evaluate designs before committing to costly equipment and field trials. But realistic simulations can take hours, limiting how many ideas researchers can explore.
The
Empirical Study of Pop and Jazz Mix Ratios for Genre-Adaptive Chord Generation
Muon Sublates the Edge of Stability in LLM Pretraining
The Token Before the Value Is the Key
CytoBERT: A Foundation Model for Cytometry Data
TabPFN beyond Tabular Data: Calibration and Accuracy on Multimodal Embeddings
RL Forgets! Towards Continual Policy Optimization
Knowledge Offloading: Decomposing LLMs into Sparse Backbones and Memory Modules
CSI-JEPA: Towards Foundation Representations for Ubiquitous Wi-Fi Sensing with Minimal Supervision
Prescriptive Scaling Laws for Data Constrained Training
Nexus: Same Pretraining Loss, Better Downstream Generalization via Common Minima
Survival In-Context: Amortized Bayesian Survival Analysis via Prior-Fitted Networks