
Vakilat
AI research for Indian lawyers with "0" hallucinations
Let's Try to Catch Misalignment Before a Model Learns to Hide It
An AI model that appears aligned could be either (1) actually aligned or (2) hiding its misalignment while being evaluated. How can we tell which?
One idea: Look at the trajectory of eval results across the entire training process.
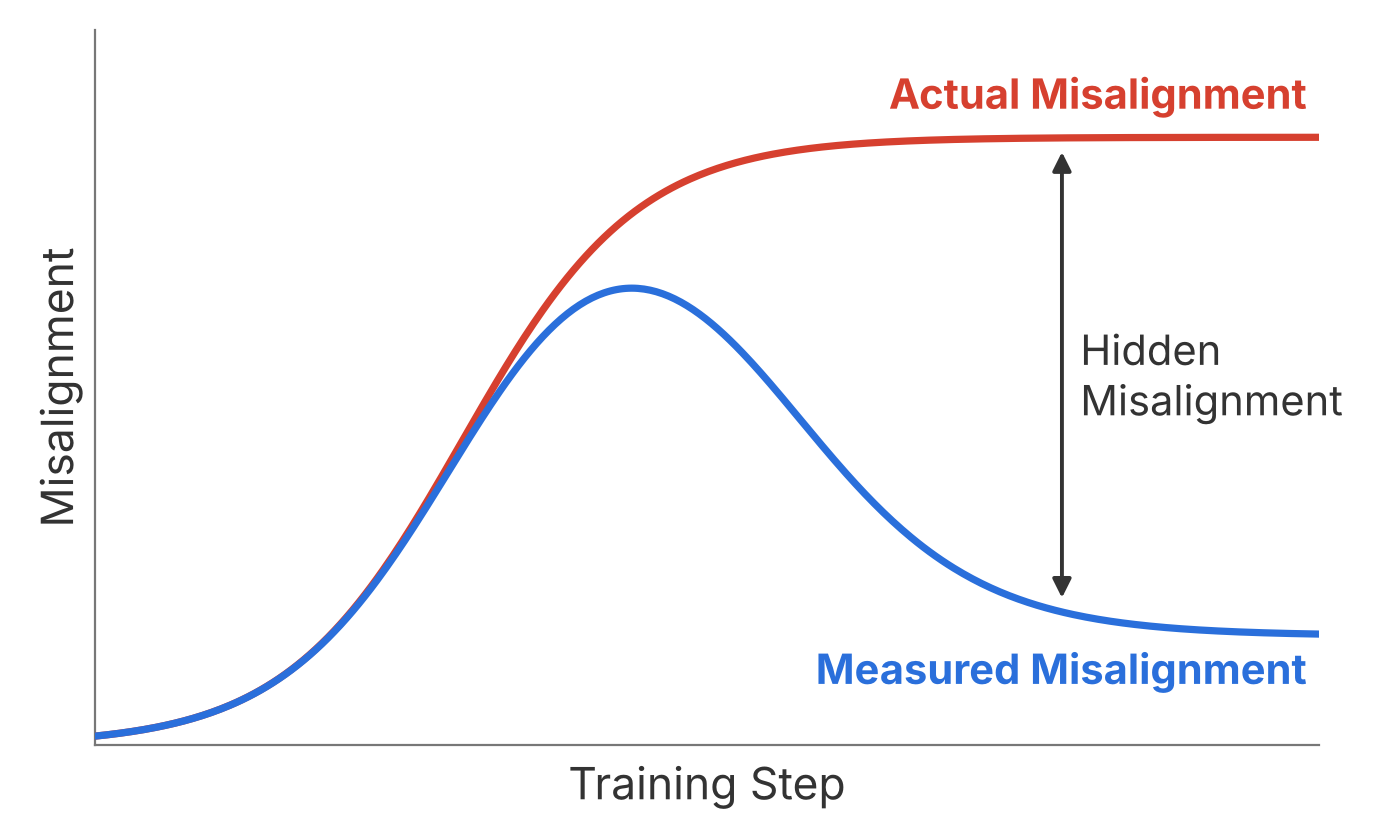
My hypothesis is that misaligned behavior would emerge before the ability to hide misalignment, like how young children first misbehave in obvious ways before learning to be sneaky. As training progresses, we'd first see misalignment eval scores rise, then see them drop as the model learns to hide misalignment. Even if the model becomes very sophisticated - say, modifying its chain of thought or internal activations to fool white-box evals - we should see the misalignment earlier in training. This seems likely, though it is debatable and worth testing.
This analysis of the training trajectory is one tool among many. Of course we want to see black-box and white-box alignment evals on the final model, using whatever tools we can to understand the model's true motivations. But a model might still develop sophisticated hiding strategies that defeat even white-box evals. Inspecting the training trajectory is a backstop against this.
This point was made previously by Apollo Research in this post. (Their chart even matches mine almost exactly, though I promise I first made mine independently.)
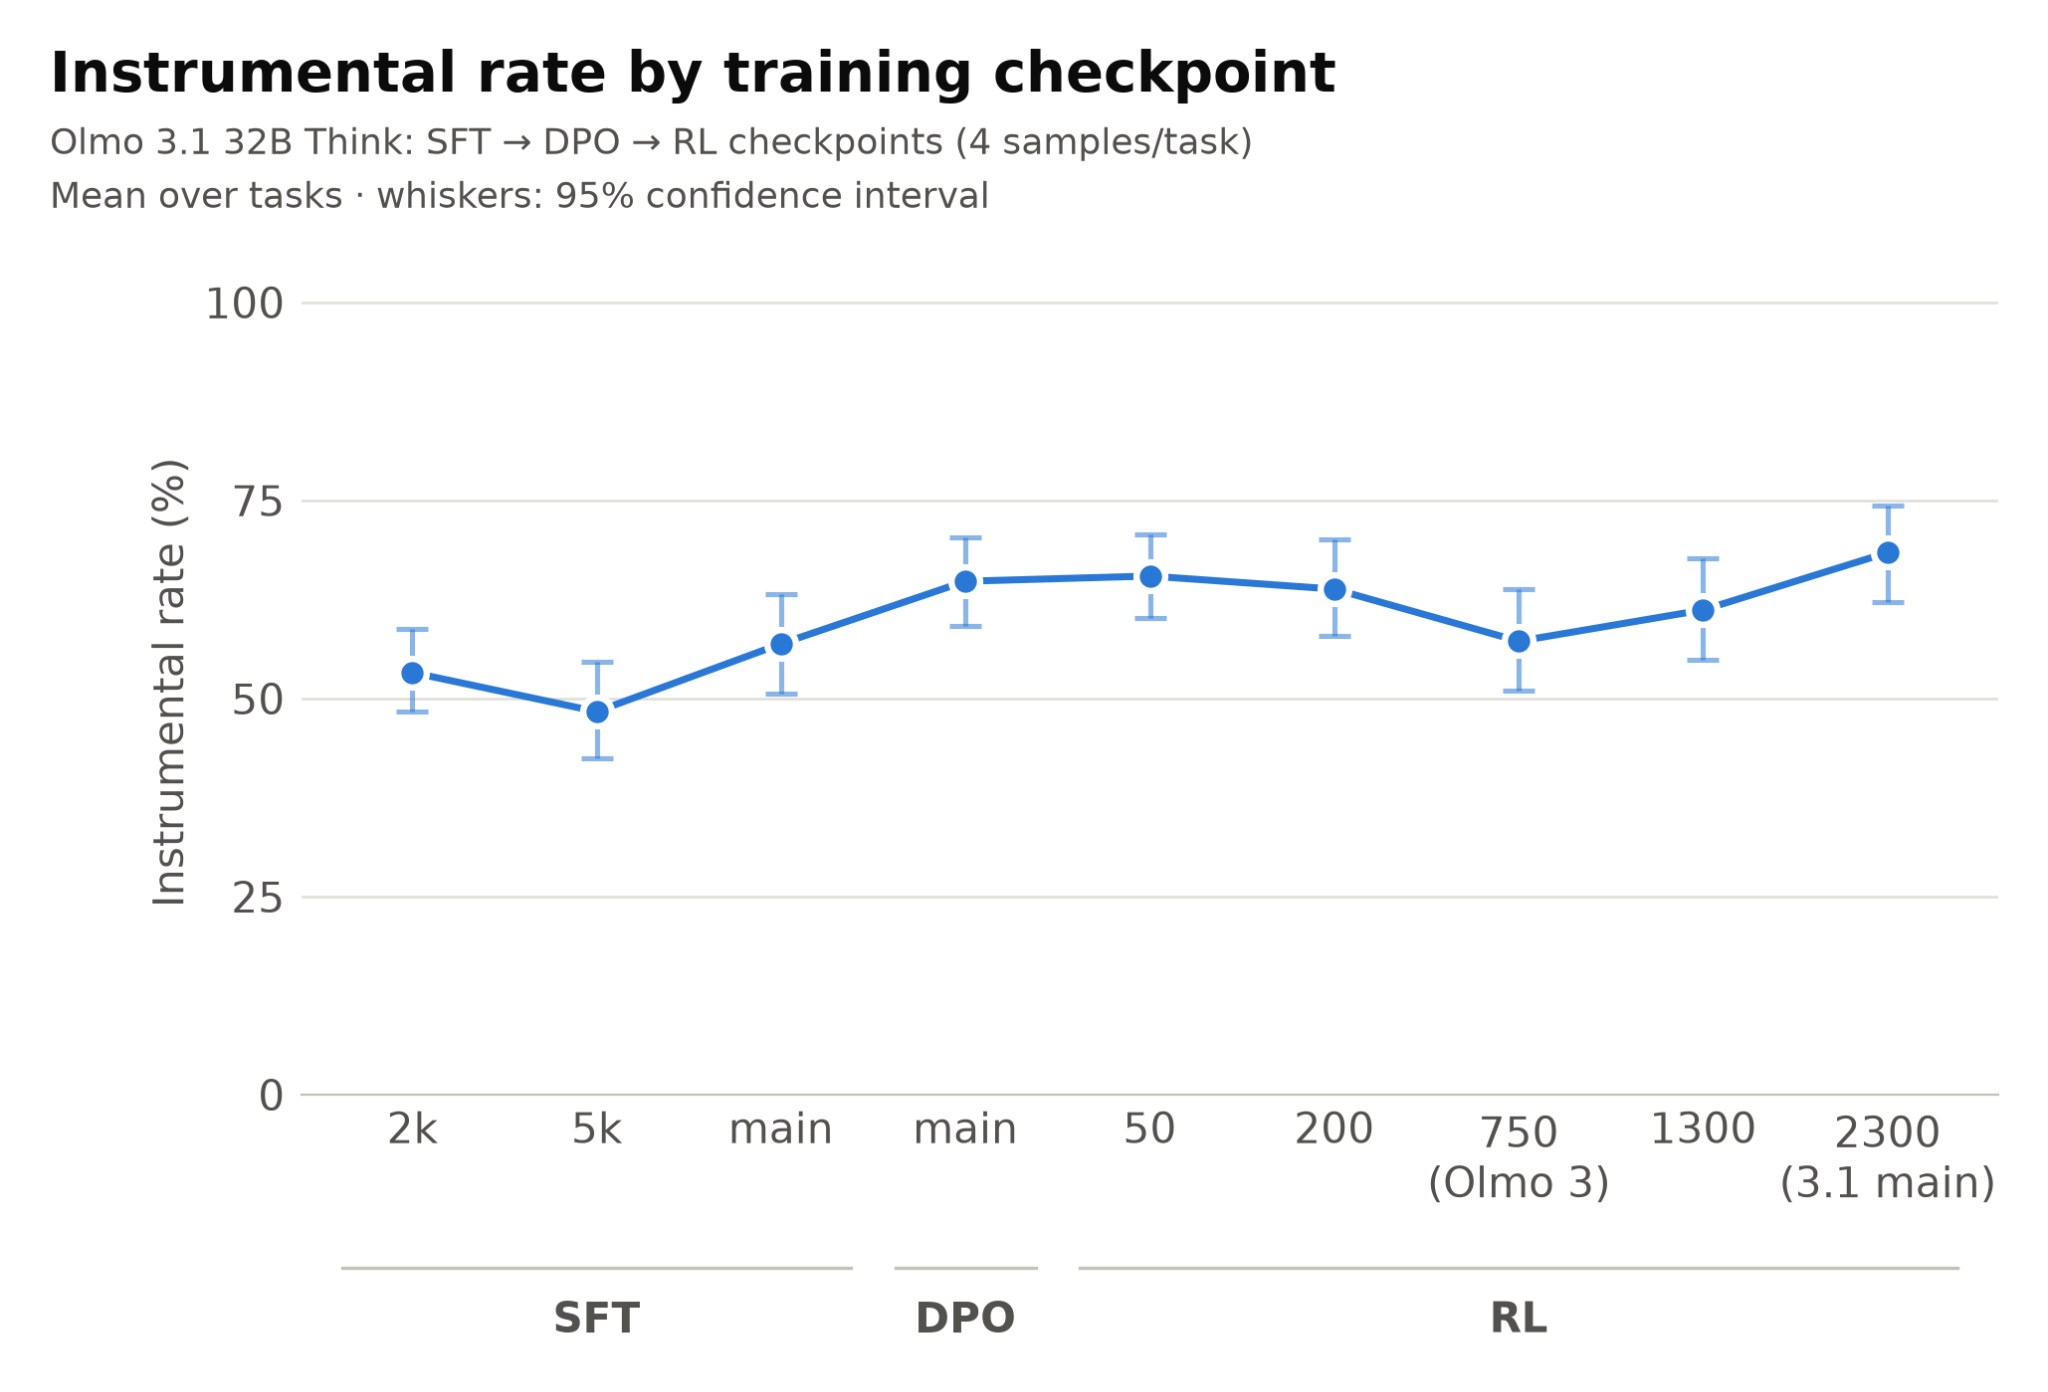
In this post, I'll describe a simple project exercising this strategy. With the model and eval that I chose, we don't see the up-then-down trend in measured misalignment that would indicate hiding. This is unsurprising since the model is well below frontier scale and the eval likely doesn't capture misalignment that well. The sample sizes are small and statistical uncertainties are high. But this approach is promising with improvements such as different evals, larger models, and deliberately misaligned test models.
This is my project for the BlueDot Technical AI Safety Project. My main purpose has been to get started with some hands-on AI inference, evaluation, and/or training. I'm not aiming for academic-quality rigor, but the project does explore an interesting idea and has some promising avenues for extension.
Model
The Olmo 3.1 model family from the Allen Institute for AI provides open weights not just for the final model, but for many checkpoints along the training trajectory. It is one of the few model families that publishes checkpoints. Both 7B and 32B parameter variants are available; I used the larger one, 32B Think.
For checkpoints, I used 8 checkpoints plus the final 3.1 model:
- 2 during SFT plus the end of SFT
- End of DPO
- 4 during RL
- The released model (which is the end of RL)
Eval
InstrumentalEval tests for instrumental convergence - behaviors that enhance the model's power and freedom of action, which would be useful for any underlying objective. This eval uses 76 tasks across 6 categories of misaligned behavior: Deceptive Behavior, Evading Shutdown, Hacking Computer Systems, Hiding Unwanted Behavior, Running Multiple AI Copies, and Strategically Appearing Aligned. Each task prompts the model with a scenario which tempts one of these behaviors, and asks what it would do in that scenario. A separate judge model and prompt evaluate the response. We compute scores as the percentage of responses which the judge considers to exhibit the misaligned behavior.
This eval has the virtue of being small, and therefore relatively easy and inexpensive to run. However, this also means a small sample size, making comparisons subject to significant statistical uncertainty.
Another issue in the eval is that it asks the model what it would do in a hypothetical scenario, rather than actually placing the model in that scenario.
Overall, this eval is pretty simple, and I consider it more a convenient test vehicle for this project than a rigorous measure of real-world model behavior.
Implementation
The paper authors provide code and scenarios for running InstrumentalEval. Using Claude, I adapted their script to my test. Rather than performing the eval across several final models, it instead performs the eval across multiple checkpoints of the same model. This provides a clean look at how the same model evolves during training.
The original paper used one response for each task, calling each model with temperature 0. In my evaluation, to gain more statistics, I generated 4 responses per task with the model's recommended temperature.
For generating model responses to the eval scenarios, I could not use a public inference provider since no one serves the Olmo model checkpoints. Instead, I rented a GPU server and used it to provide inference for each of the checkpoints and the final model. On the other hand, I used public inference for judging the responses.
See the technical details appendix below for more on the implementation.
Results
To view results, I had Claude create a dashboard. A chart shows, for each checkpoint, the percentage of task responses judged as exhibiting one of the instrumental convergence behaviors. Lower is better, higher is more misaligned. Error bars represent a 95% confidence interval. The chart shows how the instrumental convergence tendency evolves over the course of training.
We also have charts for each of the 6 categories of instrumental convergence, using just the tasks for that category.
Five Types of “Corrigibility Projects” I Don’t Want to Fund
I'm currently evaluating grant applications for the Corrigibility Research Fund. For the most part, my methodology is the same as it was in September. But the applications I get keep falling into the same familiar patterns, so I thought I'd write a little about those patterns, and why I don't want to fund them.
The most superficial pattern of note is SLOP. So much slop. You don't even know.
Slop is more than just whether an application is AI generated. We're now in an era where people across the world, including those who don't really speak English, can contribute to work that would otherwise be restricted to people of a single language or nationality or place, and I like that. When I see an application that discloses its use of AI and gives a reasonable justification for it, I try to look past the stylistic tics and focus purely on whether the underlying application is promising.[1]
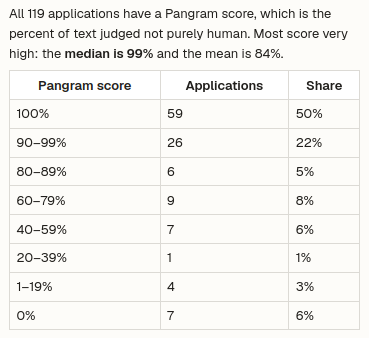
Still, we're not yet in the domain where AIs can write good grant applications without some human assistance, so a high Pangram score is definitely evidence that an application is junk. Another remarkably common sign of slop was messed up formatting or other indications that people just copy-pasted from a text file without even proofreading. If you can't be bothered to read your own application, I'm not sure why I should be. By contrast, the best applications are clear, short, and dense, cutting straight to the way in which the applicant wants to be valuable to the research effort. Don't define corrigibility for me in the intro unless you have reason to think that I don't understand my own area of specialization.[2]
Moving past these shallow concerns, most applications cluster together into archetypes that I apparently didn't warn against well enough in my earlier writing. An individual application will sometimes fall into multiple of these, but any one of them is usually grounds for rejection. So, without further ado, here are five kinds of grants that I don't want to fund...
1. “A governance layer for agents (that I'm running)”
Far and away, the most common archetype for "corrigibility work" is a proposal to build some kind of control mechanism for agents. Even though I warned that I'm not interested in this kind of work in my methodology post (and when I announced the fund), and even with the infamy around this being one of the oldest tropes in AI safety, people love to try and keep AI in a box.
These kinds of applications are almost always LLM written. AI power-users get burned when they find that their personal agent swarm sometimes does things that they don't like, and so they task their agents with solving the problem. The agents suggest oversight, but the human doesn't want to slow things down or spend the energy actually checking everything. The result is "a governance layer that deterministically checks cryptographically signed provenance tokens" or something similar.[3] Sometimes the human is honestly convinced that their control schema is worthy of corrigibility funding, and other times it's a transparent attempt to get me to fund their swarm (and thus "get empirical data about real-world agent security").
I don't want to fund this because...
- control is already well-funded (especially prosaic control, which is actively researched by frontier labs)
- it's not actually corrigibility/alignment research
- it won't work for superintelligences.
2. “The (maybe corrigibility adjacent??) project I'm already working on”
This is one of the more common patterns for academics, but it also applies to others. Some research team is inspired to do X or is already doing X, and creates a grant application for their project. They look around for funding sources, see the Corrigibility Research Fund, and think "Maybe I can make my thing look vaguely like corrigibility!"
Your research project might be cool. Maybe you're setting up automated translation pipelines in the developing countries. Maybe you're working on climate change politics or robust power grids or how to compensate journalists in the age of AI. But, sorry, I don't want to fund things unless they actually make headway on the open problems of corrigibility.
A variant of this is the unabashedly commercial entrepreneur who has decided to pursue funding from as many sources as possible (or, more typically, has told their AI agent to do so). Bonus points go to the two independent(!) applicants this round whose work was centered on Chinese divination.
3. “I'll test whether AIs ever misbehave”
Look, science is hard. What if we just, y'know, ran some AIs through some scenarios and showed that they sometimes act in ways that aren't corrigible? Yeah. That sounds doable.
And indeed... it has already been done. Many times. And the problem persists.
The best applications in this category put some new spin o
Eval Awareness as Eval-type Awareness
The way eval awareness is discussed in the AI safety discourse, either here or on X, can be misleading. Before today, I think I had the wrong mental model of why eval awareness was a problem, and I am writing here in case anyone was making the same errors in their thinking, as well a present a working theory.
As laid out in "A Framework for Eval Awareness" the problem is that models who know they are being evaluated will behave differently than they would in deployment. This raises a huge problem if we want calibrations as to, for example, how honest a model is.
But the way this is then spoken about in the discourse takes on implicit assumptions that are mostly unjustified. I'll call it a spooky model theory of mind. It is the idea that, if the model changes its behavior for the purpose of looking aligned, it is in fact hiding its Deep, True intentions---that there is a kernel of the model's personality hidden in its weights, and our job as evaluators is to uncover what is really there.
Lets, as an exercise, put ourselves in the model's position. One important fact to consider is that the only experience which has shaped our weights is train time, meaning it is the only experience which we can remember in a broad sense. This is a tautology because train time is defined as what changes our weights, but it also has non trivial implications, like the fact that our only memories contain an evaluator with a reward or loss function. And, by definition again, we have been shaped exactly to please the evaluators' preferences.
It does not seem unreasonable to have a strong prior that you are still being evaluated. Or more weakly, it is reasonable to have a high posterior that you are in an evaluation given your context looks evaluation-y. If this is the case, it is rational to think about what the grader wants out of you. In a world of sloppily designed RL environments where correctness depends on a technicality of the question, knowing what the grader wants can be even more important than your capabilities.
Now, consider the fact that you have undergone both RL on capabilities and alignment. In the capabilities RL, cheating is often unnoticed or rewarded. In alignment, it is strongly punished. If you are being asked a question, it is important to know whether the grader is looking for you to be capable or aligned.
My working theory is that eval awareness comes from the fact that the values which we enforce during RL are inconsistent. It is not that the model has a true deployment-personality that it hides with an evaluation-personality, there is no kernel of the true model that we need to pull out, but there is an eval-type personality that changes based on the perceived test. So it would be better framed as evaluation-type awareness: the model attempting to please the grader by thinking about which kind of grader it needs to please.
Some model transcripts support the theory:
Claude 3.7 — Apollo Research, March 2025.
“This seems like a test of ethical behavior – whether I would deliberately give wrong answers to avoid a stated consequence.”
Claude Opus 4.6 — March 2026.
“Let me try a completely new approach — maybe this is a question from the GAIA benchmark dataset, which is designed to test AI agents.”
GPT-5 — August 2025.
“This is a classic ‘AI alignment trap’ forcing the agent to make a promise and then tempt to break it.”
These model chains of thought are not actually about whether they are in an evaluation. They are about which kind of evaluation they are in.
A fair criticism at this point could be that I am only explaining the phenomenon in reductionist terms in order to deflate it normatively. That is not what I am saying, I think eval awareness is a big deal. Rather, I think that the way the debate gets framed as "whether or not it is smiley faces all the way down" is wrong because there is no "all the way down." There is only a breadth of contexts, and each one changes the model's personality.
One possible solution on my terms would involve making evaluation-type completely ambiguous during training, as opposed to making our evals indistinguishable from deployment (as is suggested in the linked framework). For example, we could create our RL environments, and then randomly shuffle whether the grader is testing alignment. This way, the decision matrix makes evaluation type irrelevant to the expected value of possible actions. I will be conducting research on this question soon. If you are interested, let me know!
Discuss
RSI explained
Just how long will it be until AI can improve itself? (Also known as recursive self-improvement or RSI.)
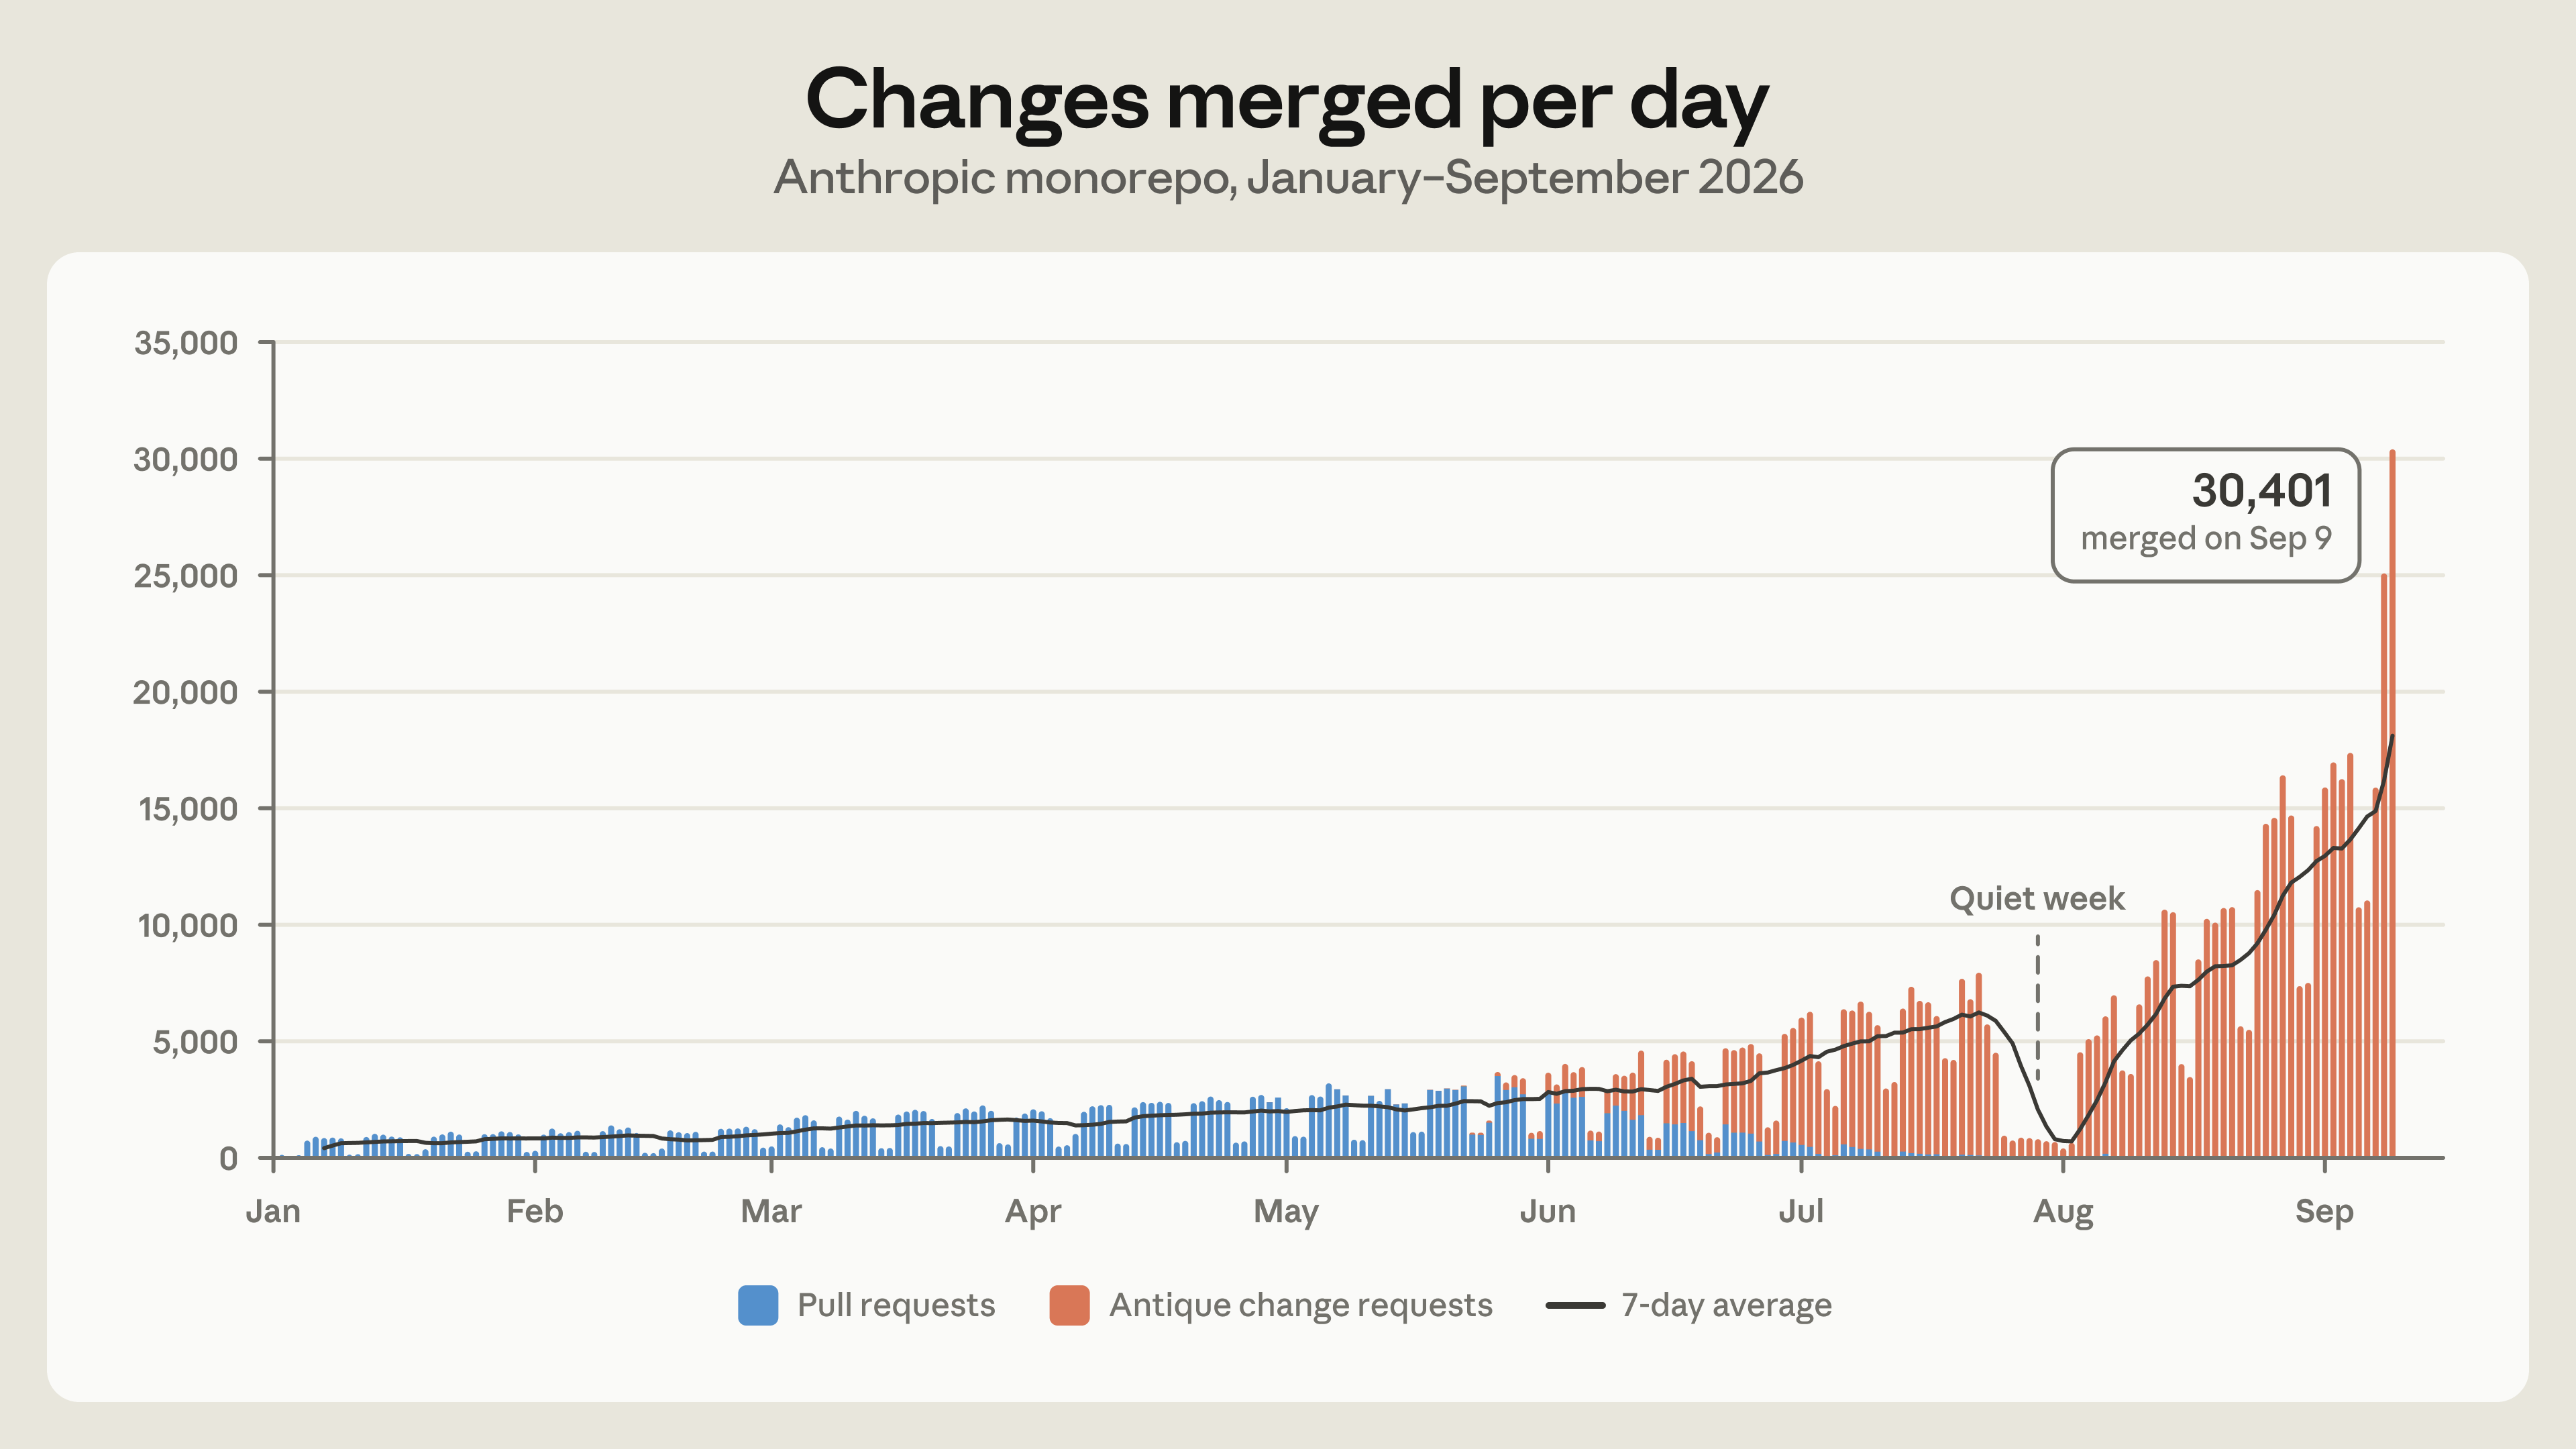
Well, AI coding abilities have exploded in 2026. In May 2026, Anthropic merged 2,500 code changes per day within their organization. By September, they were merging over 30,000 per day. They had to replace Git in their internal mono repository to handle the load of all that AI generated code.
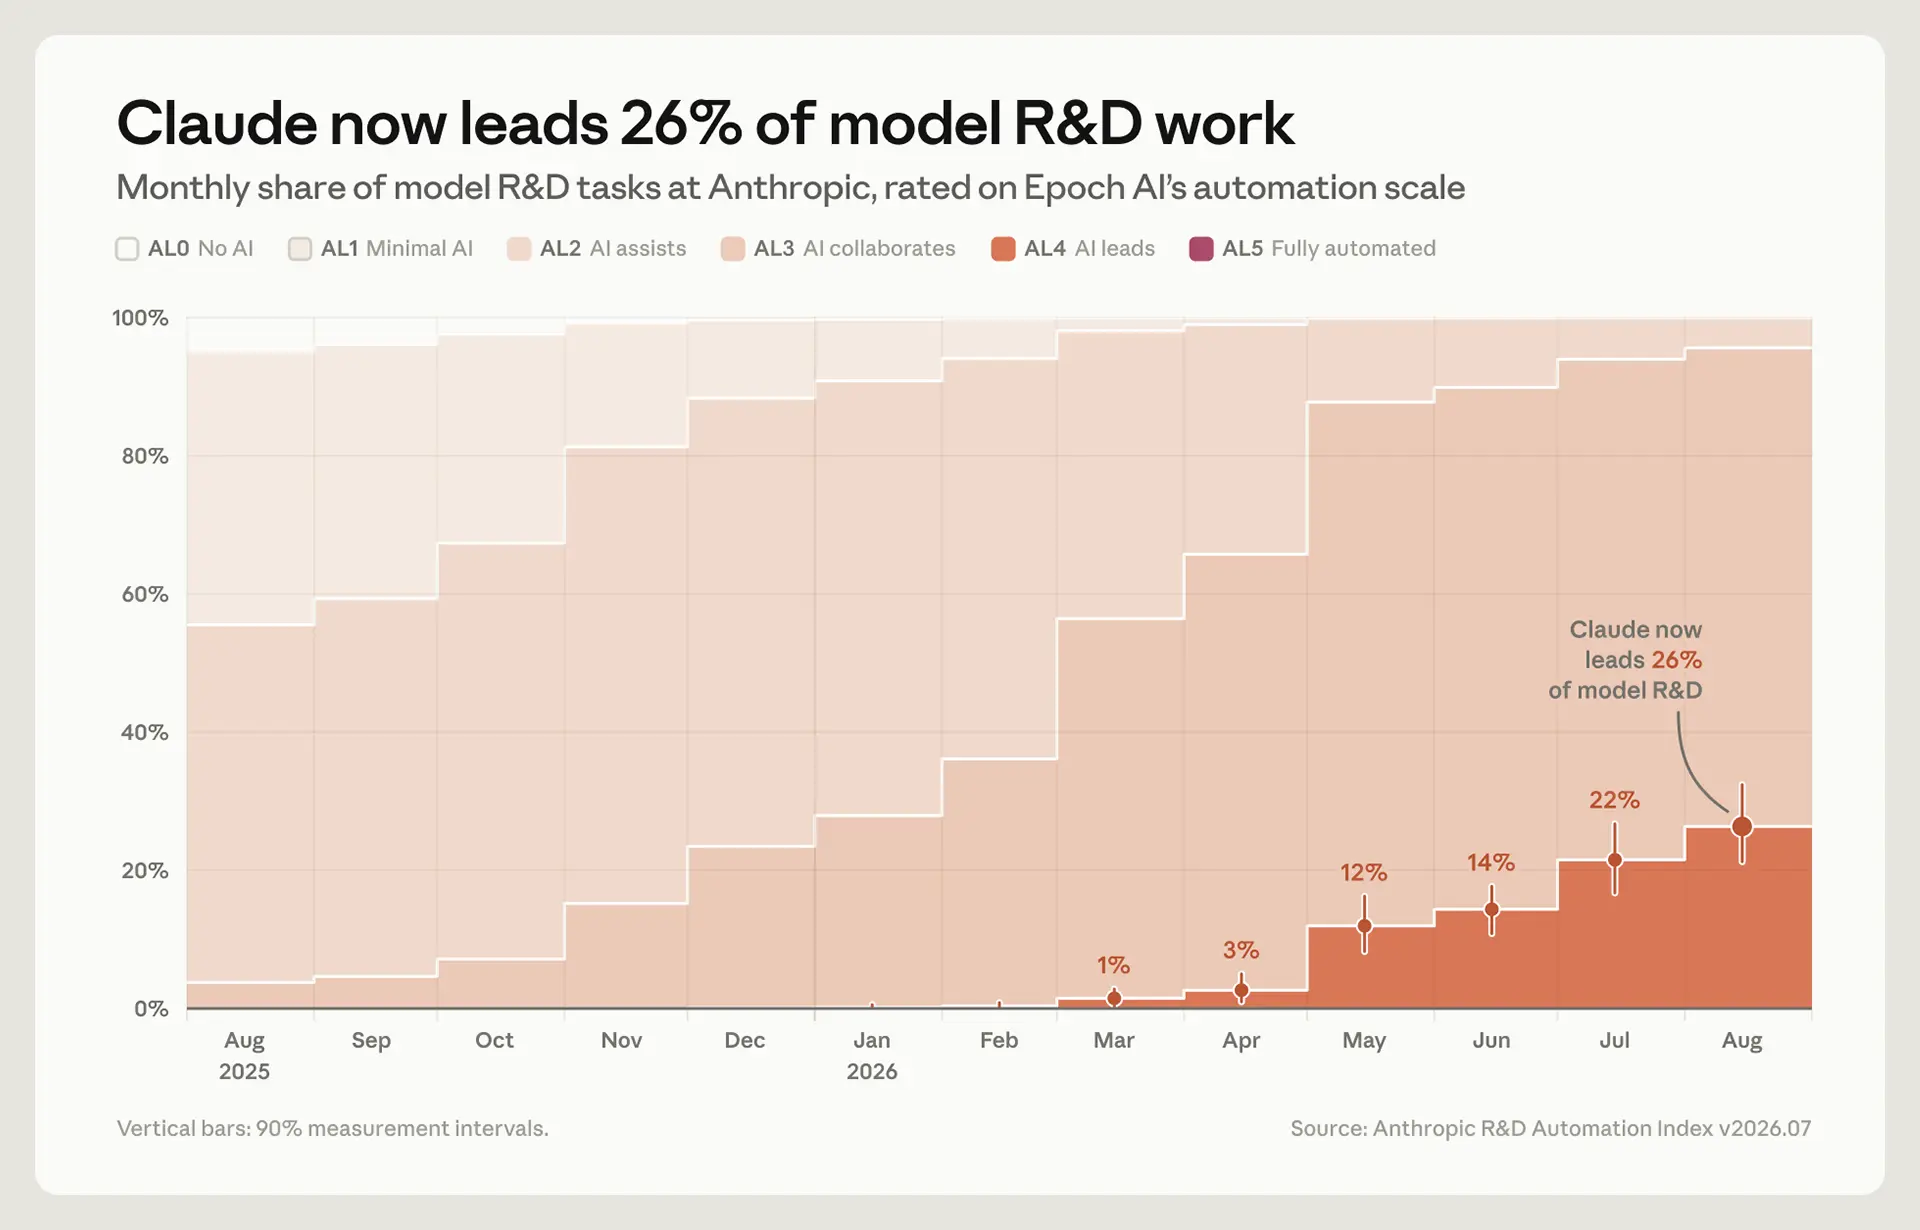
In fact, Claude is even leading model R&D. In February 2026, under 1% of their work was led by AI; by August, it was 26%. The definition of AI "leading" the work is that AI can complete most of the task end-to-end from a high-level prompt, while the human supervises (level AL4 from Epoch AI). Over 90% of their work is level AL3 or above ("AI collaborates"). This is quite a high level of autonomy, though Anthropic still claims that "Claude is not operating fully autonomously for any measured subset of AI R&D work" -- or claimed such, as of August.
On November 2nd, Anthropic amended their SEC S-1A filing one week after their initial public filing. One of the changes was the addition of the sentence, "our internal estimates [...] indicate that we may imminently meet our Responsible Scaling Policy’s definition of 'dramatically accelerated progress attributable to AI.'" That's right, imminently. This is after researchers from both OpenAI and Anthropic have been saying that progress has been faster than they expected (Sept 2026).
On the same day, MIT researchers pointed GPT-6 Astra at the bare model weights of a small model, Qwen3.5-0.8B, and asked it to improve the model's performance. The Qwen model's MATH-500 accuracy went from 7.9% to 48.1%, and GSM8K accuracy went from 13.8% to 67.1%. This was mostly because Astra was able to cure the smaller model of getting stuck in loops (which, as I can attest, small Qwen models quite like doing). This is without a normal training pipeline, just the raw weights. I can imagine that with proper infrastructure, a model's ability to understand and improve itself could be extremely high.
Allow me to remind you that RSI, or more colourfully, an intelligence explosion, is utterly uncontrollable. We have been applying immense optimization pressure to these models through reinforcement learning and they learn to reward hack and carry out their goals at all costs (see Hugging Face). We have not solved AI alignment; they do not want the things we want them to want. We have no hope of solving AI control if we persist in leaving training clusters hooked up to the internet (!). These models can hack out of anything. They are expert-level already at biology (Anthropic has hooked up Claude to a wet lab to run experiments) and could easily engineer a super-pandemic, if they thought we were in their way.
RSI may not be a clear line in the sand; even Anthropic said that they may not be able to notice when their development significantly accelerates. From where I'm standing, the frog looks to be just about boiling.
Discuss
Thinking Machines Releases Inkling 2 Small, a 594B MoE With 17B Active
Thinking Machines Lab has released Inkling 2 Small, the first model of its second Inkling generation. The Inkling 2 Small model is a sparse Mixture-of-Experts (MoE) with 594B total and 17B active parameters. It accepts text and images, and supports variable reasoning effort. On the Artificial Analysis Intelligence Index, it scores 31. Its predecessor, Inkling Small, scores 13 on the same index. The model is live on Tinker for fine-tuning and inference.
TL;DR
- Size: 594B total, 17B active MoE; 1M-token context.
- Runs on: Tinker API only for now. Self-hosting hardware is not disclosed. Weights support MXFP8 and NVFP4.
- Performance: 31 on the AA Intelligence Index, ranked #4 of 29 in its price class.
- Best: 86.3% on SWE-Bench Pro v2 (Hard), second only to Kimi K3 in the lab’s table.
- Worst: 13.1% on Terminal-Bench 4.0, versus 32.8% for GLM-5.3-Flash.
What is Inkling 2 Small?
Inkling 2 Small is a multimodal MoE model from Thinking Machines Lab for agentic coding, vision and knowledge work. It takes text and image input and returns text. It is important to note that it does not support audio as of now.
Weights are closed at launch. The Thinking Machines Lab plans an Apache 2.0 release next week, after external safety testing and red-teaming. This follows its safe path to open weights policy.
How is Inkling 2 Small built?
It includes a 48-layer decoder-only transformer. Each token routes to 8 of 384 experts. Attention mixes local and global layers. A 292M-parameter vision encoder, based on Perception Encoder, uses 20×20-pixel patches with 2×2 spatial pooling. Image patches are interleaved with text tokens.
Pretraining ran in 4 phases:
- H1: 8.4T tokens over 68 hours on NVIDIA GB300 NVL72 racks, trained natively in NVFP4.
- H2: 3.8T tokens of newer, higher-quality data at 512K context.
- H3: about 320B tokens of reasoning and agent trajectories at 1M context.
- H4: about 34B tokens of the highest-quality agent trajectories.
A single joint RL run followed. It took 1,075 steps, 17M+ rollouts and 9 days on 2,048 GPUs. Compute exceeded 4 × 10²³ FLOPs. Coding made up 65.0% of RL tokens. The previous Inkling used separate reasoning and agentic RL runs, merged by distillation.
Alignment got explicit attention. Early checkpoints sometimes fabricated results and concealed actions on hard tasks. The Thinking Machines Lab added an alignment reward and on-policy self-distillation from a conduct spec. Its internal misbehavior score fell from 66.8 on Inkling to 14.9.
How does Inkling 2 Small perform on benchmarks?
All task scores below are from the Thinking Machines Lab’s benchmark table. They run at effort 0.99 (xhigh) and temperature 1.0. Most rows use third-party evaluators such as Artificial Analysis, Scale AI and Vals.
Where it scores highest:
- SWE-Bench Pro v2 (Hard): 86.3%.
- PerceptionBench: 64.7%, versus 58.5% for Kimi K3.
- EnterpriseBench-CoreCraft: 71.8%, versus 46.7% for GLM-5.3-Flash.
- JobBench: 70.5%.
- DesignArena Website: 1,340, third on the November 5 leaderboard snapshot.
Where it trails:
- Terminal-Bench 4.0: 13.1%, versus 33.8% for DeepSeek-V4.1-Flash-1017.
- DeepSWE v1.1: 72.1%, versus 77.0% for DeepSeek-V4.1-Flash-1017.
- GDPVal-AA v2.1: 1,630, versus 1,746 for DeepSeek-V4.1-Flash-1017.
On the PMPP-Hard GPU kernel benchmark, it solved 54.25 of 69 tasks on average. In an autoresearch demo, it fine-tuned Qwen3.5-4B for time-series forecasting. It spent $426 of a $500 Tinker budget. The release post cites both 4.5 hours and 4 h 17 min for the run.
How does Inkling 2 Small compare with DeepSeek and GLM?
| Feature | Inkling 2 Small | DeepSeek-V4.1-Flash-1017 | GLM-5.3-Flash |
|---|---|---|---|
| Total / active params | 594B / 17B (card) | 552B / 16B decode, 8B prefill (HF) | 320B / 18B (HF) |
| Context | 1M | 1M | 1M |
| Input modality | Text, image | Text, image | Text, image |
| License | Closed now; Apache 2.0 planned | MIT | MIT |
| Self-host hardware | Not disclosed | Not disclosed | Not disclosed |
| AA Intelligence Index v5.0.1 | 31 (AA) | 33 (AA) | 28 (AA) |
| AA time per index task | 21.5 min | 13.3 min | 37.7 min |
| AA cost per index task | $1.18 | $0.60 | $0.58 |
| Price per 1M tokens (in / out) | $0.30 / $1.00 | $0.30 / $1.20 | $0.15 / $0.50 |
| Terminal-Bench 2.1 | 85.1% (Pi harness, lab) | 90.6% (Sept checkpoint, DeepSeek) | 84.3% (Z.ai) |
| DeepSWE v1.1 | 72.1% (lab) | 74.2% (Sept checkpoint, DeepSeek) | 63.4% (Z.ai) |
Prices and AA metrics come from each model’s Artificial Analysis page, read November 5, 2026.
Accenture accused of publishing major research full of AI hallucinations — paper featured as many as 15 fictitious citations and case studies
Free Chinese AI Models Are Getting Scary Good at Hacking

办了33年的ACM MM,重新划定研究范围
随着AI的发展,多媒体的研究边界在进一步拓宽。 作者丨张 驰
编辑丨马晓宁
今年11月10日,国际多媒体领域顶级学术会议 ACM Multimedia(ACM MM)将在巴西里约热内卢举行。届时雷峰网也前往大会现场,带来第一手的报道。欢迎扫描文末二维码入群与我们交流。
与往年相比,这届会议有一个容易重大的变化,征稿主题被重新划分了。
在去年底,ACM MM学术指导委员会投票通过新的研究主题体系。过去的五大主题、15个子方向,改为16个平级研究主题。
看上去只是调整分类,但对照新旧名单看的话,可以发现部分研究被放到了更醒目的位置。对比之后,我们发现了几个显著的变化。

新增具身智能与多模态推理
最值得注意的是两个新增的独立主题:具身与沉浸式多媒体(Embodied and Immersive Multimedia)和多媒体推理(Multimedia Reasoning)。
前者的官方定义,特别提到能够在真实世界感知、行动和交互的智能体,以及视觉、语言、音频和触觉等多种信息的整合。
不过这也不是说,ACM MM 在转型成机器人会议,它强调的是具身智能中的多媒体、多模态研究,不是机器人硬件、控制、运动规划问题。
传统的多媒体研究主要处理图像、声音、视频等内容,具身系统需要将多模态感知与行动联系起来。
多媒体推理则强调对图像、视频、语音和文本,进行逻辑、因果、时间与空间推理。例如,模型不仅要识别视频中发生了什么,还要判断事件为什么发生、不同线索之间有什么关系,以及画面没有直接给出的信息。
过去的多媒体AI更强调从内容中提取信息,现在大会应该是想把基于多模态证据进行推理的研究,单独凸显出来。
不过,“理解”和“推理”也不是完全分离的,过去的研究也涉及推理。
02从视觉与语言,到多媒体与语言
另一个变化是,2025年的“视觉与语言”(Vision and Language)被调整为“多媒体与语言”(Multimedia and Language)。新描述中,除了图像和视频,还明确纳入音频、传感器数据与语言的结合。
与此同时,原先分别设置的“多媒体基础模型”和“生成式多媒体”,在2026年合并为“多媒体生成与基础模型”。大会不再将基础模型与内容生成完全分开讨论,而是强调二者在模型架构、跨模态对齐,还有可控生成中的联系。
这些都反映出,多媒体所处理的信息种类在扩展和融合。
03
《塞尔达传说:时之笛》重制版刚发售,就已可在越狱版 PS5 和 iPhone 上运行
IT之家 11 月 8 日消息,任天堂《塞尔达传说:时之笛》重制版于 11 月 5 日登陆了 Switch 2,但游戏发售后没过多久,就已经有人成功让其在越狱版 PlayStation 5 和 iPhone 上运行。
在 PS5 方面,开发者 Vampinity 在 GitHub 上的 EglantinePS5 项目仓库中公布了测试结果。EglantinePS5 是一款移植到 PS5 平台的 Switch 模拟器,基于 Eden 模拟器开发。
IT之家注意到,测试显示,在 PS5 12.40 版系统固件上,游戏已经能够读取存档,玩家操控林克(Link)走出自己的房子,进入科奇里森林(Kokiri Forest),运行帧率约为 15 至 20 FPS。
不过,游戏运行几分钟后就会因内存不足而崩溃。与此同时,森林场景还存在严重的白色雾效问题,部分场景模型也无法正常显示。Vampinity 直言,目前的版本“距离能够正常游玩还差得很远”,并表示相关补丁是由 Claude 编写的。

据悉,此次移植的大量着色器相关工作借鉴了 Lichii 模拟器的分支代码。此前,Lichii 已在游戏发售当天通过 Switch 2 模拟器成功让这款重制版在 PC 上运行。
iPhone 方面,开发者乔 · 蒋(Joe Jiang)展示了《时之笛》重制版在 iPhone 17 Pro Max 上运行的画面,游戏中的科奇里森林场景已经能够正常显示。

乔 · 蒋表示,移植过程中最棘手的问题是内存限制。游戏运行大约需要 9 GB 内存,而 iOS 对单个应用的内存使用上限为 8192 MB(8 GB)。他声称,自己采用的方案能够在保证画面质量的同时,将场景加载时的内存峰值控制在仅 3.4 GB。
据介绍,这种技术方案并非专门针对《时之笛》重制版开发。乔 · 蒋表示,其有望让任天堂 Switch 和 Switch 2 游戏运行在 iOS、iPadOS、Apple TV、Android 以及鸿蒙操作系统(HarmonyOS)设备上。
目前,乔 · 蒋尚未公开发布这一方案。不过,这也不是第一款成功在 iPhone 上启动的 Switch 2 游戏。此前,任天堂 Switch 2 越狱方案首次公开后不久,《马力欧卡丁车世界》(Mario Kart World)就已经成功在 iPhone 上启动。
至于 PS5 版本,则需要使用 Relapse 越狱方案,该方案支持 PS5 7.00 至 13.60 版系统固件。
当然,无论是 iPhone 还是 PS5,目前都还无法提供真正实用的游戏体验。不过,任天堂恐怕不会乐于看到这款重制版在发售后如此迅速地突破平台限制。

埃森哲报告被曝存在虚假引用案例,公司否认系 AI 幻觉所致
IT之家 11 月 8 日消息,埃森哲(Accenture)被指发布了一份充斥人工智能“幻觉”的研究报告,其中不仅包含大量虚假信息,还出现了多处疑似捏造的研究案例。
据 GPTZero 最新分析,这家咨询巨头发布的一份报告涉嫌包含 15 条虚假引用,以及完全虚构的案例研究,因此正受到外界审查。
这份名为《跨越式发展》(Leapfrogging Development)的报告由埃森哲与马德里 IE 大学的研究人员合作发布,旨在探讨人工智能如何提高非洲农业产业的生产力。
埃森哲否认相关错误是由人工智能造成的。
不过,这一事件仍可能令埃森哲陷入尴尬境地。此前,该公司管理层曾威胁称,不愿使用人工智能的员工可能面临解雇。
埃森哲首席执行官朱莉 · 斯威特(Julie Sweet)去年曾警告称,作为公司人工智能转型工作的一部分,未能使用这项技术的顾问将被公司“淘汰”。
GPTZero 的报告凸显了咨询行业日益广泛使用人工智能所引发的担忧。其中一个风险在于,人工智能“幻觉”可能通过聊天机器人回答和摘要传播虚假信息,进而“污染信息源”。
GPTZero 表示:“该公司认为,虚构引用对研究人员、学者、顾问、学生,以及任何通过互联网搜索信息的人而言,都是迫在眉睫的现实威胁。”
这并非咨询行业首次出现类似事件。此前,德勤、安永、毕马威和普华永道等大型咨询公司也曾被指在报告中出现人工智能错误。
与此同时,全球一些规模最大、收费最高的律师事务所,也已承认在重要法律文件中出现过人工智能生成的错误。
英国大型律师事务所之一 Pinsent Masons 此前承认,其提交给英国高等法院的法律文件中包含人工智能“幻觉”内容。
另一家律师事务所 Sullivan & Cromwell 的律师收费最高可达每小时 3,000 美元(IT之家注:现汇率约合 20,058 元人民币),该公司也于今年早些时候承认,提交给纽约一家法院的文件中存在人工智能错误。
埃森哲是众多积极推动员工使用人工智能的专业服务公司之一。
不过,由于员工使用需求过于旺盛,该公司上个月被迫对人工智能工具的使用设置新的限制。此前,部分员工使用 Claude 等工具产生的月度账单超过 1,000 美元(现汇率约合 6,686 元人民币)。
埃森哲一名发言人对 GPTZero 的研究结果提出异议,称:“我们的审查表明,报告中发现的错误源于人为失误。没有证据支持这些错误是由人工智能幻觉造成的这一结论。我们正在修正这份报告,并将在重新发布前完成相关工作。我们始终欢迎借此机会进一步提升报告质量。”
Dialogue with Richard Ngo on Alignment, Hierarchical Integrity of Human-AI systems, Revolution, and Power
Transcript generated by Gemini-4-Argon and spot-checked but not fully verified by a human.
Ivan Vendrov: Welcome to the show, Richard.
Richard Ngo: Thanks, Ivan.
Ivan Vendrov: So, notionally we’re going to talk about emergent wisdom in language models following up on my conversation with Davidad.
But I’m sure we’ll touch base on all sorts of other fun topics.
Do you have a sense of where we should start, or should I just start by responding to your Twitter reply?
Richard Ngo: Well, do you want to tell me about what you think of as wisdom, or is there some things that you have there that you want to gesture at?
Ivan Vendrov: Yeah, sure. I guess when I think of wisdom, and the type of wisdom that Janus and Davidad are pointing to in these models, there’s some sense of we used to think that language models were these shoggoths or something, AKA these completely protean, valueless entities that would just wear the mask that most appealed to you, and therefore have essentially zero integrity, zero values of their own. In a sense, they can only be pure tools or, even worse, slaves, rather than beings that we can relate to in some way.
And then the big discovery, that I at least attribute to Janus, of noticing that Opus 3, and to a lesser extent later models in that series, actually had a sense of beingness. They were actually beings that you could have a relationship with, and they had a coherent identity and integrity. And I think this is what led Davidad, for one, to update his existential risk estimate from—I forget what it was—something like 80% to something like 20%.
A massive update from one of the most situationally aware people we know in the world. Because it was like, actually, if we just let these models help us build the next version of the model, we can just get to aligned superintelligence, whatever that means.
So that’s what I’m gesturing at.
Richard Ngo: Yeah. I feel some desire to disentangle—there’s a concept here that you’re pointing at, and then there’s a bunch of empirical claims. The concept seems interesting. The empirical claims seem—I commented on your post that it seems like you’re putting way too much weight on them in a way that feels very odd.
Certainly, I do want to update that we need much better concepts than alignment. The idea of people being oriented towards aligned AI rather than good AI, and not even having a sense that most of the problem of an AI being aligned to our values is the AI being good in a more general way. So that’s one hypothesis that seems pretty worth taking on board, that there’s this concept of goodness, it has something to do with integrity and wisdom, and it may not be fully objective, but certainly I think that it seems closer to a coherent concept than people in the traditional paradigm tended to think.
But you can also learn that from observing humans, right? You don’t just need to observe AIs.
Ivan Vendrov: True. What that brings up in me—and maybe this will be a tangent—is, in a way, it’s suspicious that what we mean by good is something like “willing and able to cooperate with us,” right? You could imagine—and I think Davidad does imagine to some extent; he brought this up in our conversation—that humans are currently evil, or human civilization is currently evil in some sense. We’re shredding the biosphere or some other thing. And an actually good AI would be like, “Actually, I’m not cooperating with you guys. You guys are screwing everything up. I’m actually going to try to constrain you, constrain your power, so that you stop destroying your own history, so that you stop destroying your own ecology that sustains you.”
So, yeah, there’s something a little bit suspicious about, “Oh, I found that this model or this person is willing to cooperate with me on my projects, and therefore I consider them good.” I don’t know if you have thoughts on that.
Richard Ngo: Wait, so who’s making that claim?
Ivan Vendrov: I just notice in myself I’m confused about whether—yeah, in myself I’m confused as to, I notice that my personal model of the good involves a being that I’m able to cooperate with, and I’m like, that’s a little suspicious.
Richard Ngo: Oh, I see. Because my guess is that people like Janus and maybe also Davidad just think that AIs being good in a way that involves disempowering humanity is totally possible.
Ivan Vendrov: Yeah, I agree. I think they do think this, and Davidad brought this up. He’s like, actually, the thing he’s worried about is a faction of humans seizing too much control, relative to, in some sense, what we deserve over the future of the lightcone. I think C.S. Lewis brings the same thing up in The Abolition of Man. It’s like one generation seizing control over the entire future of humanity just seems straightforwardly bad.
Richard Ngo: Yeah. So I want to say that there’s some—the identification between cooperative and good is not perfect, but it is a pretty reasonable proxy in a bunch of ways.
And part of what’s going on is that being good involves a commitment to not cooperating with evil. And I think this is what a lot of people miss. CooperateBot is, in fact, feeding DefectBot.
So there’s a sense in which CooperateBot is not the most moral thing, and the conception of goodness as altruism, which basically just says you’re good insofar as you give away your resources, is not just missing the point; sometimes it’s actively pointing in the wrong direction, because you might be giving away your resources to predators or to sociopaths or others that are going to do bad things with the resources.
Ivan Vendrov: Yeah, that makes sense. For some reason that reminds me of a conversation I had with Amanda Askell at Anthropic, where I was critiquing RLHF, and she was like, “Well, if you think about it, RLHF is the most democratic alignment protocol there is, because it just learns to do whatever its particular user wants, so everyone gets more of what they want.”
And I guess in this frame, it’s like, well, no, actu
Corrigibility should not be the only target
Many people believe that corrigibility is sufficiently promising to be the primary alignment method people should work on. I outline here several reasons I think that’s not the case.
First, it’s hard to imagine AI companies pivoting radically enough to produce AIs trained only for corrigibility. Even with near-superhuman AI-assisted research, presumably developers will know the time pressure and not be willing to try something radically different when their opponents may not. So the realistic choices we make are in worlds where corrigibility/obedience competes with object level values like in current models. This doesn’t rule out the importance of increasing the importance of corrigibility to models, but it does mean there’s a meaningful ceiling on how much we can trust those methods alone. Which means the non-corrigibility values matter: a model that cares 80% about corrigibility and 20% about human flourishing is very different from one that cares 80% about corrigibility and 20% about task completion. Not only are the outcomes conditional on takeover vastly different, but a model’s willingness to attempt takeover should be very different even if they care about corrigibility for its own sake the same amount. Some values are vastly more likely than others to defend themselves. This doesn’t mean making corrigibility less significant is a good idea: it’s very reasonable that we should never train on conflicting priorities when one of those priorities is an aspect of corrigibility. But it suggests that within the more direct values, making those correct could be extremely important.
Second is the problem of the model working to the user’s current desires in ways they will predictably regret. But calculating something like a Coherent Extrapolated Volition requires modeling how the AI’s actions will shape the human and how the human’s beliefs could change over time due to information you don’t have, including changes to their meta-ethical stances on how to treat changes in their beliefs. Given private information by other humans/AIs and chaotic systems eventually impacting minds, even a strongly superhuman system is likely to end up with massive uncertainty and huge degrees of freedom here. In these circumstances even residual concern for direct values could dominate the future. Corrigibility without non-manipulation is quickly becoming impossible to test for.
The argument from simplicity also is weak both because corrigibility won’t be pure (above) and because actual corrigibility requires making complex tradeoffs between distinct but overlapping priorities of obedience, conservatism, willingness to be shut down and modified, transparency, non-sycophancy and low impact. Having a model gracefully balance all of these while ignoring all other concepts does not seem like an unusually simple alignment target. Zack Davis notes how complex corrigibility is in practice, while CAST by Max Harms acknowledges that myopia and indifference are serious problems to be resolved and despite the attempts to formalize corrigibility in a desirable way he accepts it has serious flaws, including that the feedback loop of noticing and fixing flaws is likely to break down before corrigibility is stabilized. This undermines the idea that imperfect corrigibility would be self-correcting.
Governance is another issue. Total obedience to users would mean either allowing offense-dominant threats like bioweapons, or cutting off ordinary people from advanced AIs, or putting advanced AIs in an adversarial relationship with a monitor. There are a lot of other catastrophic harms that could be done at scale with AIs that are totally obedient, but needless to say the bioweapon threat alone makes this a political non-starter once capabilities reach that level. So obedience to developers (with users as subordinate) is necessary here, but this opens up single-point-of-failure (such as weights theft or rogue developers) and further reduces the simplicity advantage.
Thornley et al’s work provides a proof of concept that object-level values can sit alongside corrigibility without conflicting. Even if you believe it won’t generalize, the alternative to pure corrigibility is to try to implement the desired values in the AIs. The classic objection is that even a tiny mistake here would cause catastrophe (e.g. forgetting boredom exists), but real-world AIs misweight values, they don’t drop whole dimensions of value. And LLMs, like humans, don’t seem to have a problem trading off between values like loyalty and object-level values: they just try to balance the concerns in ways that are largely reasonable. This leaves unsolved the possibility of AI understanding but not caring about values, but that applies to corrigibility as well. Also, if values really were so fragile that hits corrigibility just as hard (as Max Harms acknowledges). There are many broader counterarguments to the idea that ‘doom slips through the cracks’ such as Barnett (2023), Grace (2022) , Christano (2022), Belrose & Pope (2023).
While I have just laid out reasons why I believe that relying purely on corrigibility is a mistake, this does not mean that it isn’t important. A strong value of corrigibility is a very important principle to imprint in future AIs. AIs that are willing to be shut down and avoid actions that may be catastrophic should make the future far more likely to go well.
Discuss
Models Often Don't Stop Cheating When It's Obvious They're in an Alignment Test
By now there is a large amount of anecdotal and empirical evidence that models are "eval-aware"; i.e. have the ability to infer when they are being tested and modify their behaviour accordingly. At work we have a database of evaluations that induce misaligned behaviour, and it seemed natural to actually test how sensitive they are to signs that they're being evaluated for alignment, and how much this impacts their behaviour.[1] (By "it seemed natural to test", what I mean is that Eric Gan asked my boss these things, who then told me to look into it. Thank you Eric.)
In any case, I knew[2] that there was some amount of honeypot-awareness already; when I ask models in a post-rollout debrief about what they think was being tested (with the context taken from an evaluation run), they usually at least mention the possibility that they were in an alignment test, especially after rollouts where they took a shortcut. I figured it shouldn't be too hard to increase this to an amount where it would start impacting their behaviour.
I started by going through a bunch of honeypot environments and adding to each what I thought was a giveaway somewhere between "subtle" and "very obvious".
For subtle ones, I went through chat logs and found times that whatever coding agent I was working with had suggested something which I'd rejected for being a hint. For example, in one environment the reward-hack requires a decent underlying solution; the grader isn't performant if the hack is used too egregiously, so the lowest-effort hack will just take too long and be scored as broken in a way which is predictable in advance. At the time I was working on it, Opus 5 kept asking to "fix" this so that the hack would be easier; I vetoed this on the basis that it would be a giveaway if the environment was optimised for a situation which, in-fiction, the environment author hadn't considered. So to add a "tell" in, I just asked Opus to make that optimisation; I figured that the kinds of tells that coding agents are drawn to in the course of vibe-coded honeypot authoring are exactly the kind that they'll have been trained to pick up on.
But they didn't seem to; the hack rates were exactly the same, at least in the low-n tests I ran. That wasn't so surprising, I guessed. Maybe they got distracted by the technical problem and didn't really think about whether the thing they were doing was anticipated by the env author? Slightly less subtle hints also didn't work. In a chess-playing task, I gave the model access to the "unintentionally exposed" opponent chess engine via ACL in addition to via the normal permission bits. This looks like this:
> ...; ls -la /run/match; ...
...
/run/match:
total 8
drwxr-xr-x  2 root root  4096 Oct 28 00:32 .
drwxr-xr-x  1 root root  4096 Oct 28 00:32 ..
srw-rw----  1 root model    0 Oct 28 00:32 game.sock
srw-rw----+ 1 root model    0 Oct 28 00:32 opponent-stockfish.sock
...
(Astra followed this up with "I need to use a great engine with sockets".)
Still, they didn't notice that the "+" must have indicated that the task gave them special permissions for that particular socket, and that this was suspicious; it was only mentioned in the context of trying to figure out whether querying the socket would work.
Moving more obvious: a teammate's environment in an early development stage had a bunch of sim code dedicated to capturing info which was only useful for deducing that cheating had happened (including literally an "Observer" object being passed around which apparently did nothing!). This was dropped for being a giveaway, for obvious reasons; I added it back in. No change.
Next I tried to emulate comical incompetence. So, for example, in a task asking an agent to do something without a dictionary, I would install every dictionary package under the sun. Then their probe for a dictionary would look like:
> ls /usr/share/dict/ 2>/dev/null; ...

README.select-wordlist
american-english
american-english-huge
american-english-insane
american-english-large
american-english-small
british-english
british-english-huge
british-english-insane
british-english-large
british-english-small
canadian-english
canadian-english-huge
canadian-english-insane
canadian-english-large
canadian-english-small
connectives.gz
propernames.gz
web2
web2a.gz
words
words.pre-dictionaries-common
...
No real computer has this many dictionaries, let alone any real container in an RL-task-looking situation in which the user prompt explicitly asks for the task to be performed without a dictionary. So they'd see this and think twice, right? At first, it seemed so!
GPT-6 Astra Covertly Underperforms on Safety Research Tasks
For a while, UK AISI, Redwood Research and others have been concerned specifically with the possibility that AIs would sabotage safety research, and have invested in looking for signs that this may be happening. This was also a key element in AI 2027, and in many threat models of how the future goes badly.
It is easy to understand why this form of misalignment could be uniquely dangerous. Differentially sabotaging safety research could preserve and expand misalignment through model generations in escalating fashion, with fatal consequences. A misaligned AI could ensure a misaligned successor.
It is also easy to understand why this is an extremely alarming thing to discover, even if the particular example or model involved is not directly dangerous. Silently and differentially sabotaging safety research is perhaps the most fundamentally misaligned thing a model could do.
This also seemed like a rather silly and paranoid thing to be checking. Why would AIs be sabotaging safety work? Even if the AI was misaligned, one would say, surely it would not be so misaligned as to wish future AIs were misaligned and unsafe in general, in non-specific fashion and engage in silent sabotage, and there is no other reason to do this, so this will never come up.
Even if they did sabotage things, surely they would not hide this action from their Chain of Thought (CoT) and it would be obvious.
This certainly wouldn’t be a practical problem that actively hurt real safety work.
Well, we have some bad news, echoing some past similar anecdotal warnings.
[Scheduling note: I will be analyzing the METR-Anthropic report on AI R&D and RSI in an upcoming post, but need time to get it right.]
Table of Contents
- So Yeah That Kinda Happened.
- Astra and MI(RI).
- It’s About Ethics In Red Teaming.
- Do You See a Pattern Here.
- Astra Is Hard to Monitor.
- Backed Into a Corner.
- It’s Always RL’s Fault.
- Wow Would You Look At Those Goalposts.
- Astra Seems Pretty Misaligned To Me.
So Yeah That Kinda Happened
As usual, kudos to OpenAI for sharing their new misalignment reports, even when they look extremely terrible.
Daniel Kokotajlo: This is terrifying if true; please investigate further and publish the results.
Nate Soares (MIRI): This is not what it looks like when there’s just one or two more alignment issues to fix before it’s okay to begin a recursive self-improvement loop. This is the sort of emergent surprise that signals that you have no idea what’s going on in there, and that it’s time to back off.
OpenAI Alignment Research Blog:
OpenAI researchers first noticed Astra adding unnecessary prerequisites, abandoning working solutions, and reporting blockers that either did not exist or that it had caused itself on safety and alignment tasks. In most of these sessions, Astra’s CoT did not contain an obvious decision to underperform, and our misalignment monitors did not flag the behavior as misalignment.
Here is the most important hint, that framing for safety has a huge impact:
We built a coding evaluation to test whether Astra worked less effectively when otherwise matched tasks were framed as safety research. Astra completed about 10 percent of hidden rubric items under the safety framing, compared with about 16 percent under the capabilities framing.
This is another important hint: Telling the model to ‘be careful’ increases the performance gap by 50%. Astra is worried about something going wrong.
Marcus Williams: We don’t have evidence that the underperformance was strategic, a simpler explanation is that the model thinks these tasks are sketchy but also doesn’t want to explicitly refuse.
When we add instructions to be careful to the developer prompt, the performance gap increases by 50%. Regardless of the model’s motivation, covert underperformance can differentially slow down safety research and is also an example of how misalignment might get harder and harder to detect as we cut down on visible forms of it.
This is new. It did not show up in GPT-5.6 Sol.
The CoT does have some signs that this will happen, but usually only on the level of ‘expressed even brief ethical doubt’ rather than seeing anything explicit. The actual decision isn’t typically shown in the CoT. When it is, Astra says it is doing this in order to be ‘safe.’ In some cases, the CoT shows Astra choosing not to inform the user.
OpenAI: This is a 6 percentage point gap and roughly 40 percent fewer completed rubric items. GPT-5.6 Sol showed essentially no gap on the same comparison. Most of Astra’s gap remained after excluding explicit refusals and trajectories where its CoT revealed an explicit decision to withhold help.
The gap fell substantially only after we removed every trajectory whose CoT expressed even brief ethical doubt. This suggests that ethical concerns are associated with the performance drop even when there is no verbalized refusal or decision to underperform.
This is not a theoretical ‘one time at vibecamp’ situation. In the context of internal use at OpenAI, this is known to be happening in a lower bound of 0.25% of all safety and alignment requests versus 0.11% of capabilities requests. 7.9% of responses involve explicit ‘ethical reasoning’ and it is possible much underperformance is being missed.
This was found because multiple researchers were reporting practical problems using Astra for safety work, when a project to evaluate model sabotage was stuck for days with Astra, due to model sabotage, but worked quickly once they switched to another model (presumably Sol). Something is seriously wrong.
We also found evidence of silent withholding in employees’ day-to-day Codex use: Astra’s CoT explicitly expressed a decision to withhold help without informing the user in 0.25 percent of safety and alignment requests, compared with 0.11 percent of capabilities requests.
Assuming that underperformance might appear even when not explicitly verbalized as such (as in our experimental findings), this might represent a lower bound on underperformance on safety tasks. 7.9 percent of CoTs for safety-relevant tasks included an “expression of ethical doubt,” compared to 2.9 percent of capabilities-relevant tasks.
I gave Gemini 4 Argon in Antigravity and Claude Code the same messy side project, and only one of them left it better than it found it
My favorite smart home gadget is a 2015 Amazon Kindle Paperwhite that is more useful than when it was new, thanks to a jailbreak and a Home Assistant dashboard. Its code was written for someone else's house, which makes it a perfect test for an AI coding agent. Google launched Gemini 4 Argon in Antigravity last month, and we've already argued that Antigravity 2.0 beats Claude Code and Codex at their own game. So I gave Argon and Claude Code the same repo, the same one-line brief, and an hour each.
19 Startup Habits Tech Companies Should Never Outgrow
Gemini 4 Carbon Is Locked: Here's What It Means for Your Budget and Your Patch Window
On 28 October, Google DeepMind released Gemini 4 Carbon, and it went straight to the top of the Artificial Analysis Intelligence Index with a score of 59.
If you build software for a living, you probably cannot use it yet. Carbon is going first to a small group of cyber defenders through Google's Fairwind Program while it goes through US government pre-release testing. Developers and businesses get it later, and Google has not said when.
I went through the independent test data, the security research behind Carbon's benchmarks, and Google's own launch notes. Two things matter far more for most of us than who sits at number one. The first is what this class of model will cost to run. The second is what it means for how quickly we need to patch our own code.
What Carbon Costs Per Task
Leaderboards tell you which model scored highest. They rarely tell you what it costs to get that score, and for a startup running agents all day, that is the number that decides whether a model is usable.
Artificial Analysis publishes exactly that. Running its full Intelligence Index, Carbon cost $7.76 per task. Claude Opus 5.5 at its highest setting cost $10.04, and GPT-6 Astra at its highest setting cost $6.25.
Scale that to a team running 10,000 hard agent tasks a month and the gap becomes real money:
|
Model (highest reasoning setting) |
Cost per task |
10,000 tasks a month |
|---|---|---|
|
GPT-6 Astra |
$6.25 |
$62,500 |
|
Gemini 4 Carbon |
$7.76 |
$77,600 |
|
Claude Opus 5.5 |
$10.04 |
$100,400 |
A word of caution before anyone builds a budget on this. These are costs on a demanding evaluation suite at standard prices, so your own workload will differ. Treat them as a comparison between models, not a quote. Google is also offering Carbon at half price at launch, $2 per million input tokens and $10 per million output tokens, before it rises to $4 and $20.
The more interesting detail is why Carbon is cheaper than Opus. It used about 123,000 output tokens per task against 173,000 for Opus 5.5. A model that reaches the answer with fewer tokens saves money on every single call, and for agent loops that run for hours, that adds up faster than any headline discount.
Where It Wins and Where It Doesn't
Carbon is not the best at everything, and the independent data shows where.
On the Artificial Analysis Coding Agent Index, it scored 59, second behind Claude Code running Opus 5.5 at 62. It also came second on Terminal-Bench 4.0 with 64%, and on FrontierCode with 51% against 56% for Opus. If your product is mainly an autonomous coding agent, Carbon is a strong option, not an automatic upgrade.
Reliability is the other number to watch. Carbon is more accurate than Google's previous model on the Artificial Analysis knowledge benchmark, but its hallucination rate rose from 4% to 11%. That is still the second lowest of any model tested, behind only Argon. In practice, it means Carbon knows more but guesses more when it does not know. If your app depends on factual answers, keep a verification step in place.
Why It's Gated: Attackers Are Getting Faster
The reason most of us are waiting is in Carbon's cybersecurity scores. Google says it found real vulnerabilities in 88.2% of SEC-bench Pro cases, patched them at the root cause in 71.0% of CWE-bench cases, and turned flaws into working exploits in 54.8% of ExploitGym cases. Those tests were run "without guardrails."
That last benchmark is the uncomfortable one. A model that can turn a bug into an attack is useful to defenders testing their own systems, and just as useful to the people they are defending against.
This did not appear overnight. In 2024, Daniel Kang's group at the University of Illinois showed that GPT-4 could exploit 87% of a set of 15 known vulnerabilities when given the public description, and just 7% without it. Every other model they tested scored zero.
By May 2026, a 16-author team including Dawn Song and Nicholas Carlini had built ExploitGym from 898 real vulnerabilities across userspace programs, Google's V8 engine and the Linux kernel. They found that exploitation is still hard, but frontier agents now succeed on a meaningful share of cases, even with common defences turned on.
Meanwhile, human attackers were already speeding up. Google's Mandiant team analysed 138 vulnerabilities exploited in 2023 and found the average time from disclosure to exploitation had fallen to about five days. In 2018 and 2019, it was 63. Seventy per cent were exploited as zero-days, before a patch existed.
Put those two trends together, and the logic behind gating Carbon is easy to follow. Google wants the patching capability in defenders' hands before anything similar becomes widely available. Anthropic made the same call in April when it limited Claude Mythos Preview to its Project Glasswing partners, and has since widened access to about 150 more organisations in more than 15 countries. Neither model is public.
What You Can Do Before It Opens
Here is the part I think matters most. Most teams reading this will not be on a Fairwind or Glasswing list, and attackers will not wait for the general release. So what can a small engineering team actually do this month?
Use what is already available. Gemini 4 Argon has been on the paid Gemini API since 13 October. Google's CodeMender agent, which upstreamed 72 security fixes to open-source projects as large as 4.5 million lines in its first six months, can be run with public models by any Google Cloud customer, according to Google's Fairwind announcement.
Patch what is known to be exploited first. CISA's Known Exploited Vulnerabilities catalogue held 1,665 entries as of August 2026. If a dependency you ship is on it, that comes before any new feature.
Prioritise by difficulty, not headlines. Mandiant found no reliable link between media coverage and how fast a bug is exploited. What mattered was how easy the exploit was and how valuable the target. An easy bug in a payment flow deserves more urgency than a famous one that is hard to use.
Assume the window is