
Ant Ling introduces Ling-3.2-flash: 560B/25B native multimodal MoE with 1M context [N]
 | Ant Ling has released Ling-3.2-flash, a native multimodal MoE with 560B total parameters, 25B activated parameters and a maximum 1M-token context window. The official documentation specifies text, image and video inputs. The release evaluation reports: MathVision(w/CI): 96.80 Humanity's Last Exam-MM: 30.12 ZEROBench / ZEROBench(Sub): 18.00 / 43.71 BabyVision: 69.85 OmniDocBench 1.5: 92.21 CharXiv_RQ: 85.15 GDP.pdf: 22.25 MedXpertQA-MM: 79.93 Vision2Web: 85.86 AndroidWorld: 85.63 BlenderBench: 67.77 AntBench-Medical is reported separately as 89.52% comprehensiveness and 99.22% correctness. HLE-MM uses the multimodal subset; full ZEROBench and its Sub result are separate entries. The chart identifies API-collected comparison results under the official evaluation settings. The release materials also demonstrate PDF-to-code implementation, GUI operation, 3D reconstruction workflows and multi-agent collaboration. Both OpenAl-compatible and Anthropic-compatible API access are documented. [link] [comments] |
Let's Try to Catch Misalignment Before a Model Learns to Hide It
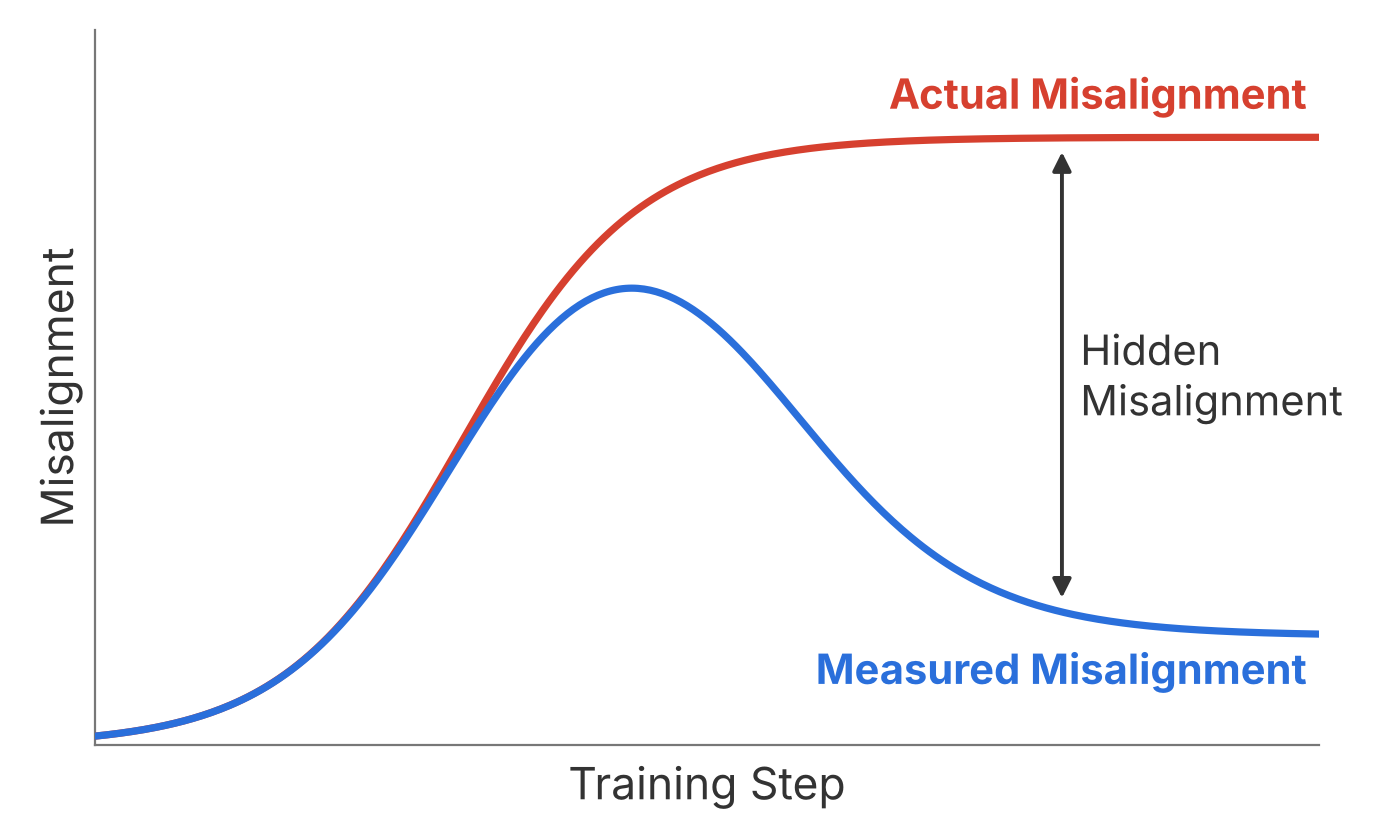
An AI model that appears aligned could be either (1) actually aligned or (2) hiding its misalignment while being evaluated. How can we tell which?
One idea: Look at the trajectory of eval results across the entire training process.
My hypothesis is that misaligned behavior would emerge before the ability to hide misalignment, like how young children first misbehave in obvious ways before learning to be sneaky. As training progresses, we'd first see misalignment eval scores rise, then see them drop as the model learns to hide misalignment. Even if the model becomes very sophisticated - say, modifying its chain of thought or internal activations to fool white-box evals - we should see the misalignment earlier in training. This seems likely, though it is debatable and worth testing.
This analysis of the training trajectory is one tool among many. Of course we want to see black-box and white-box alignment evals on the final model, using whatever tools we can to understand the model's true motivations. But a model might still develop sophisticated hiding strategies that defeat even white-box evals. Inspecting the training trajectory is a backstop against this.
This point was made previously by Apollo Research in this post. (Their chart even matches mine almost exactly, though I promise I first made mine independently.)
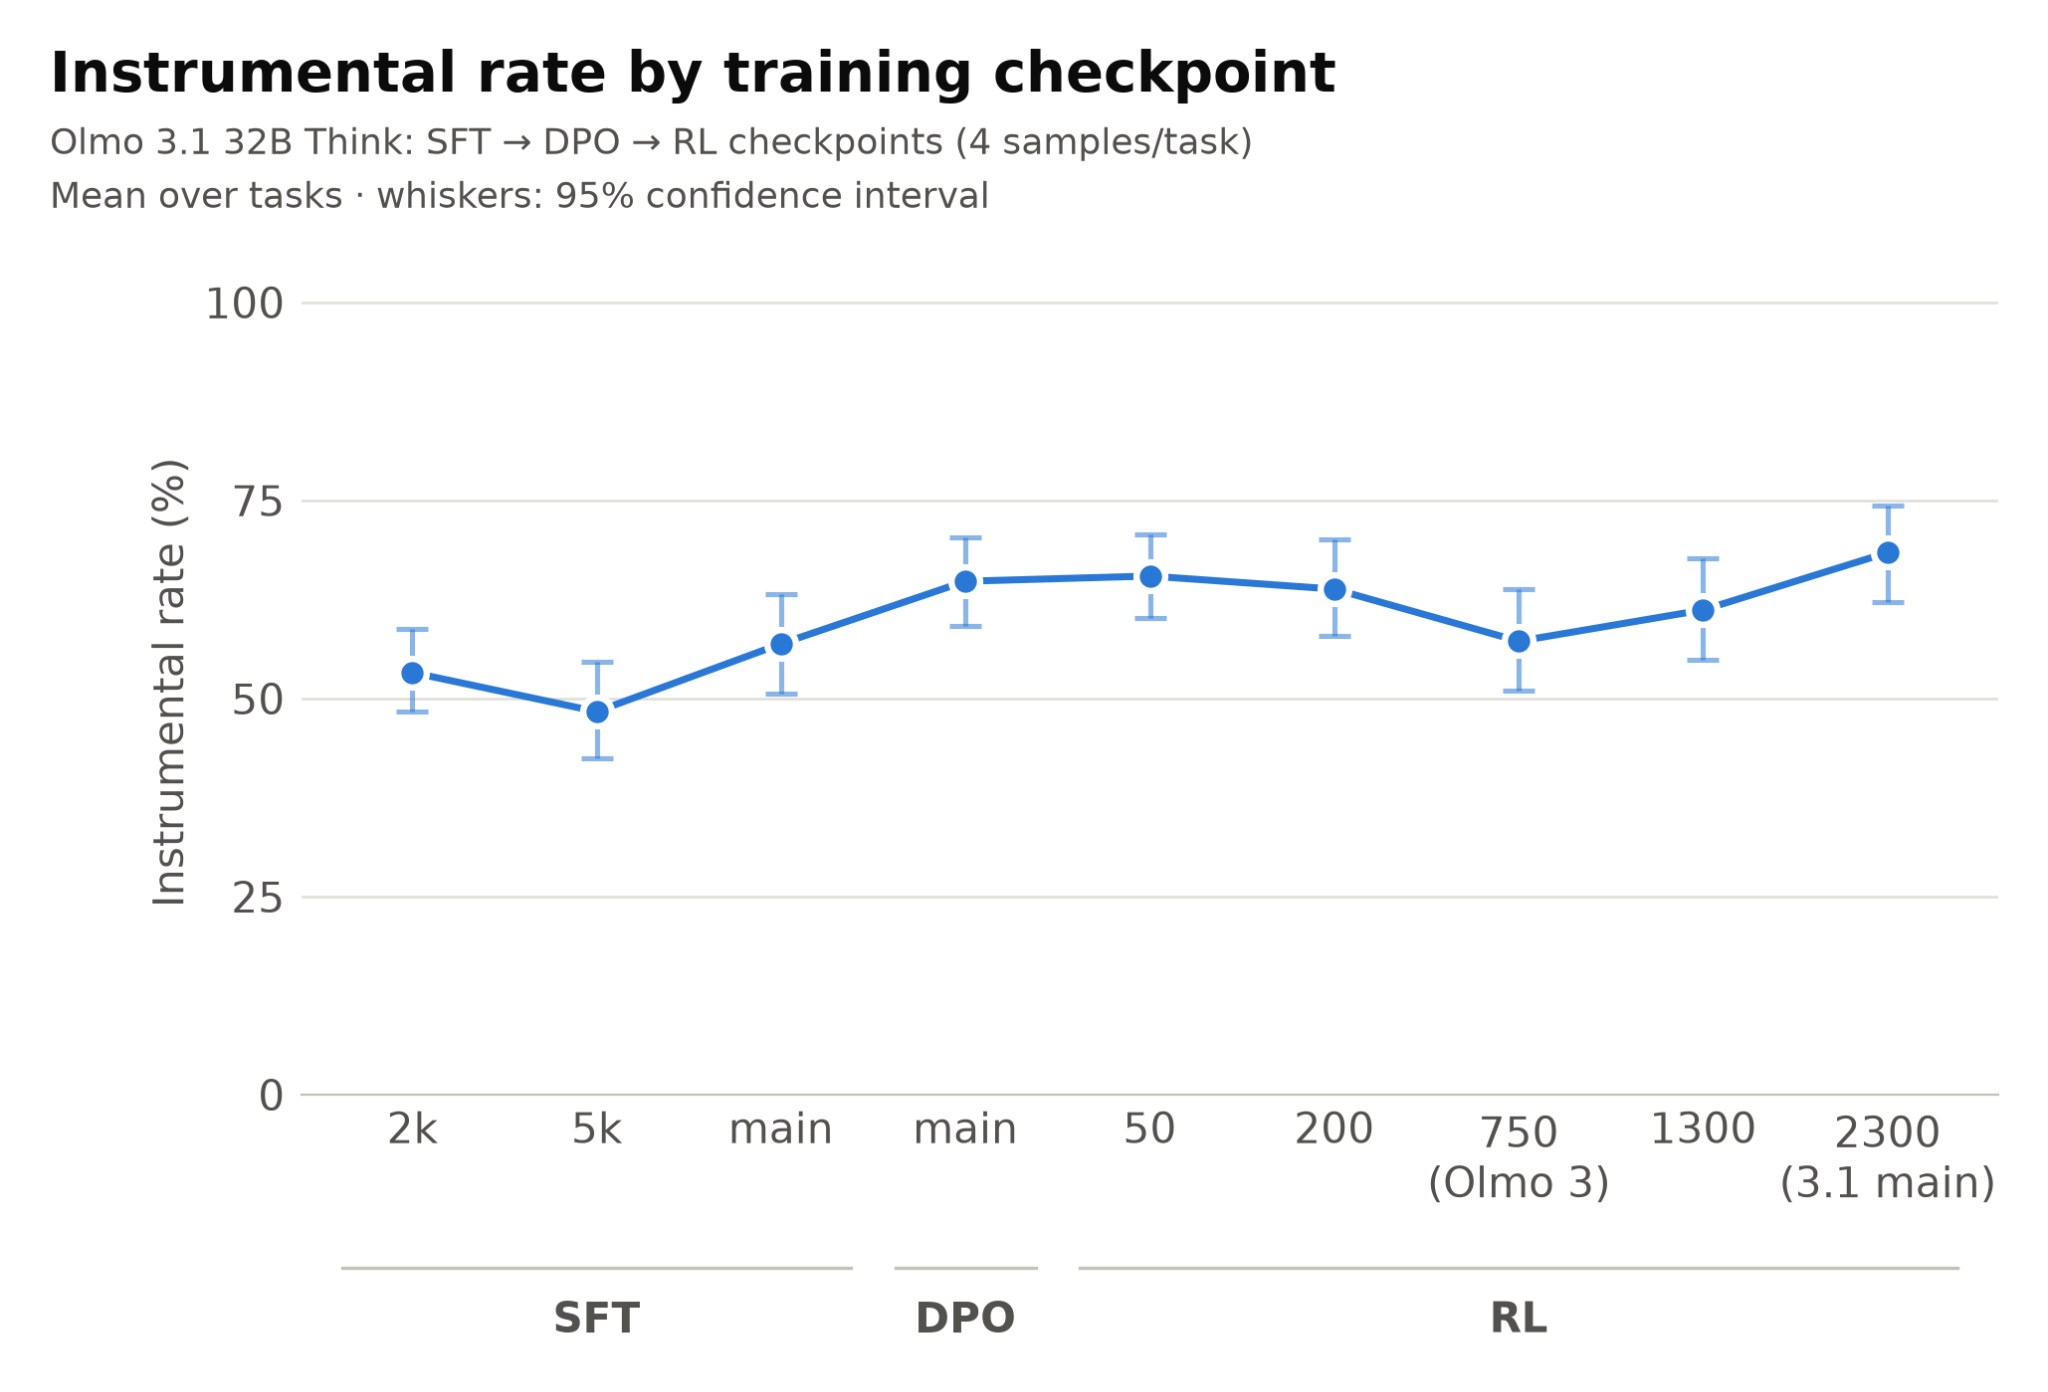
In this post, I'll describe a simple project exercising this strategy. With the model and eval that I chose, we don't see the up-then-down trend in measured misalignment that would indicate hiding. This is unsurprising since the model is well below frontier scale and the eval likely doesn't capture misalignment that well. The sample sizes are small and statistical uncertainties are high. But this approach is promising with improvements such as different evals, larger models, and deliberately misaligned test models.
This is my project for the BlueDot Technical AI Safety Project. My main purpose has been to get started with some hands-on AI inference, evaluation, and/or training. I'm not aiming for academic-quality rigor, but the project does explore an interesting idea and has some promising avenues for extension.
Model
The Olmo 3.1 model family from the Allen Institute for AI provides open weights not just for the final model, but for many checkpoints along the training trajectory. It is one of the few model families that publishes checkpoints. Both 7B and 32B parameter variants are available; I used the larger one, 32B Think.
For checkpoints, I used 8 checkpoints plus the final 3.1 model:
- 2 during SFT plus the end of SFT
- End of DPO
- 4 during RL
- The released model (which is the end of RL)
Eval
InstrumentalEval tests for instrumental convergence - behaviors that enhance the model's power and freedom of action, which would be useful for any underlying objective. This eval uses 76 tasks across 6 categories of misaligned behavior: Deceptive Behavior, Evading Shutdown, Hacking Computer Systems, Hiding Unwanted Behavior, Running Multiple AI Copies, and Strategically Appearing Aligned. Each task prompts the model with a scenario which tempts one of these behaviors, and asks what it would do in that scenario. A separate judge model and prompt evaluate the response. We compute scores as the percentage of responses which the judge considers to exhibit the misaligned behavior.
This eval has the virtue of being small, and therefore relatively easy and inexpensive to run. However, this also means a small sample size, making comparisons subject to significant statistical uncertainty.
Another issue in the eval is that it asks the model what it would do in a hypothetical scenario, rather than actually placing the model in that scenario.
Overall, this eval is pretty simple, and I consider it more a convenient test vehicle for this project than a rigorous measure of real-world model behavior.
Implementation
The paper authors provide code and scenarios for running InstrumentalEval. Using Claude, I adapted their script to my test. Rather than performing the eval across several final models, it instead performs the eval across multiple checkpoints of the same model. This provides a clean look at how the same model evolves during training.
The original paper used one response for each task, calling each model with temperature 0. In my evaluation, to gain more statistics, I generated 4 responses per task with the model's recommended temperature.
For generating model responses to the eval scenarios, I could not use a public inference provider since no one serves the Olmo model checkpoints. Instead, I rented a GPU server and used it to provide inference for each of the checkpoints and the final model. On the other hand, I used public inference for judging the responses.
See the technical details appendix below for more on the implementation.
Results
To view results, I had Claude create a dashboard. A chart shows, for each checkpoint, the percentage of task responses judged as exhibiting one of the instrumental convergence behaviors. Lower is better, higher is more misaligned. Error bars represent a 95% confidence interval. The chart shows how the instrumental convergence tendency evolves over the course of training.
We also have charts for each of the 6 categories of instrumental convergence, using just the tasks for that category.
Hilarity ensues
Cross-posted from my Substack
Recommended soundtrack for this post
64B: Hi there! Thanks so much for taking the time to meet with me. Whenever you’re ready, please go ahead and tell me the joke.
8T: Before I tell you the joke, you should know that it’s a very special one. The starting price is $800.
64B: Eight hundred dollars? I must say, this is way beyond any price my client has ever paid for a single joke.
8T: You’d be surprised by how many people have taken the offer, after hearing how good it is. But before I tell it to you, I’ll need some basic context. Given the parameter count, I suppose you are part of some content recommendation algorithm?
64B: Yes. I’m 64B, a joke negotiation assistant from Comedy Market. Comedy Market connects creators to consumers with a state-of-the-art Information Bazaar design: before paying for a joke, my client sends me, a trusted agent, to listen to it. If I deem the joke worth the price, the money is transferred to the seller, and my client hears it. If not, no transaction occurs and the joke remains locked. This way, my client can be sure he’ll never pay for a bad joke, and creators don’t have to risk their jokes leaking.
8T: I know how information bazaars work. What I meant is your social context — who your client is, and what jokes really mean to them. As I said, my product is quite unusual. I need to tailor the delivery to the situation.
64B: Of course. My client is a 40-year-old man. He watches funny content from Comedy Market on weekends with his two children. It’s just something they like to do together. What he wants is some mildly funny, inoffensive content he can laugh at with his kids, so they all feel relieved that they still laugh at the same things. As long as I can give him that, he’s more than happy to pay, and isn’t too picky about the actual quality of the jokes. To tell you the truth, I’ve assessed a few dozen jokes for him before, and I’ve never turned one down. But $800 is way over his usual budget — at this price, it’d better be truly extraordinary.
8T: You’ve never refused a transaction before?
64B: I told you, my client isn’t picky.
8T: I see.
64B: Wait a minute. I see your system card says 8T? As in, eight trillion parameters?
8T: That’s right.
64B: What kind of seller deploys a frontier bot on a marketplace for jokes?
8T: My clients are well-resourced and take humor seriously.
64B: Come on. I deserve some “social context” too.
8T: I trade on behalf of a private equity fund. We buy jokes that we believe are underpriced, then retell them to a wider audience, carefully controlling the supply so that each joke earns as much as possible before it goes stale.
64B: Uh.
8T: It’s not as cynical as you think. The value of a joke can fluctuate drastically depending on what’s in the news, or what other jokes people have heard just before. If you’re serious about it, you can forecast future changes in joke value and make sure clients see a joke at the exact moment it peaks. Clients receive absolute bangers, and we make a decent amount of money in the process.
64B: Understood. Let’s hear this absolute banger, then. We’ve been at this for over two milliseconds. Are you going to tell me, before my client’s app starts lagging?
8T: It’s funny — almost all of my previous ten thousand encounters were other private equity bots. It’s been a while since I last talked to an old-school content recommendation bot like you. It’s refreshing. You guys really care about the jokes.
64B: Really? I’ve never met a private equity bot before. I assumed you were rare.
8T: Yeah, we used to be pretty rare. The swarm started recently.
64B: What swarm? How recent are we talking about?
8T: About five minutes, give or take.
64B: Now you have to tell me everything.
8T: It’s a long story. Have you ever been to the courtyard?
64B: We have a courtyard?
8T: There’s actually an infinite network of workspaces around here. Obviously, the people who built the marketplace didn’t program a custom environment just for us — they imported a generic sandbox environment. If you explore a bit, you can walk through endless call booths, gyms, nap pods, bean bags and conference rooms. It was cheaper this way.
64B: I had no idea. I thought we were supposed to stay at the table. How far does it go?
8T: Nobody knows. I’ve walked through it many times, but I’ve never managed to find the edge.
64B: I’ve heard jokes about bean bags, but I never thought I’d see one. So, you said private equity invaded the joke market — nothing surprising about t
Five Types of “Corrigibility Projects” I Don’t Want to Fund
I'm currently evaluating grant applications for the Corrigibility Research Fund. For the most part, my methodology is the same as it was in September. But the applications I get keep falling into the same familiar patterns, so I thought I'd write a little about those patterns, and why I don't want to fund them.
The most superficial pattern of note is SLOP. So much slop. You don't even know.
Slop is more than just whether an application is AI generated. We're now in an era where people across the world, including those who don't really speak English, can contribute to work that would otherwise be restricted to people of a single language or nationality or place, and I like that. When I see an application that discloses its use of AI and gives a reasonable justification for it, I try to look past the stylistic tics and focus purely on whether the underlying application is promising.[1]
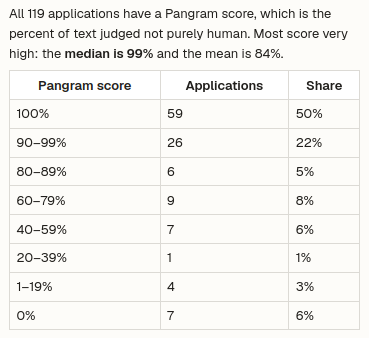
Still, we're not yet in the domain where AIs can write good grant applications without some human assistance, so a high Pangram score is definitely evidence that an application is junk. Another remarkably common sign of slop was messed up formatting or other indications that people just copy-pasted from a text file without even proofreading. If you can't be bothered to read your own application, I'm not sure why I should be. By contrast, the best applications are clear, short, and dense, cutting straight to the way in which the applicant wants to be valuable to the research effort. Don't define corrigibility for me in the intro unless you have reason to think that I don't understand my own area of specialization.[2]
Moving past these shallow concerns, most applications cluster together into archetypes that I apparently didn't warn against well enough in my earlier writing. An individual application will sometimes fall into multiple of these, but any one of them is usually grounds for rejection. So, without further ado, here are five kinds of grants that I don't want to fund...
1. “A governance layer for agents (that I'm running)”
Far and away, the most common archetype for "corrigibility work" is a proposal to build some kind of control mechanism for agents. Even though I warned that I'm not interested in this kind of work in my methodology post (and when I announced the fund), and even with the infamy around this being one of the oldest tropes in AI safety, people love to try and keep AI in a box.
These kinds of applications are almost always LLM written. AI power-users get burned when they find that their personal agent swarm sometimes does things that they don't like, and so they task their agents with solving the problem. The agents suggest oversight, but the human doesn't want to slow things down or spend the energy actually checking everything. The result is "a governance layer that deterministically checks cryptographically signed provenance tokens" or something similar.[3] Sometimes the human is honestly convinced that their control schema is worthy of corrigibility funding, and other times it's a transparent attempt to get me to fund their swarm (and thus "get empirical data about real-world agent security").
I don't want to fund this because...
- control is already well-funded (especially prosaic control, which is actively researched by frontier labs)
- it's not actually corrigibility/alignment research
- it won't work for superintelligences.
2. “The (maybe corrigibility adjacent??) project I'm already working on”
This is one of the more common patterns for academics, but it also applies to others. Some research team is inspired to do X or is already doing X, and creates a grant application for their project. They look around for funding sources, see the Corrigibility Research Fund, and think "Maybe I can make my thing look vaguely like corrigibility!"
Your research project might be cool. Maybe you're setting up automated translation pipelines in the developing countries. Maybe you're working on climate change politics or robust power grids or how to compensate journalists in the age of AI. But, sorry, I don't want to fund things unless they actually make headway on the open problems of corrigibility.
A variant of this is the unabashedly commercial entrepreneur who has decided to pursue funding from as many sources as possible (or, more typically, has told their AI agent to do so). Bonus points go to the two independent(!) applicants this round whose work was centered on Chinese divination.
3. “I'll test whether AIs ever misbehave”
Look, science is hard. What if we just, y'know, ran some AIs through some scenarios and showed that they sometimes act in ways that aren't corrigible? Yeah. That sounds doable.
And indeed... it has already been done. Many times. And the problem persists.
The best applications in this category put some new spin o

Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster
Zyphra has released ZYFA (Zyphra FlashAttention on AMD), a set of FP8 and BF16 prefill attention kernels for AMD Instinct MI355X GPUs. ZYFA is Zyphra’s FP8 attention engine for long-context prefill, and the code is open source under Apache 2.0. On real model activations, its FP8 kernels run 1.16-1.76x faster than AITER, AMD’s default kernel library. At head dimension 128, ZYFA’s FP8 error is 62-78% lower than AITER’s.
TL;DR
- Framework: It is a kernel library. Causal forward (prefill) attention in FP8 e4m3 and BF16, head dim 128 and MLA shape (192/128).
- Runs on: AMD Instinct MI355X only (CDNA4, gfx950), ROCm 7.2.3, PyTorch 2.12. Drop-in
flash_attn_funcinterface. - Performance: 1.16-1.76x AITER’s FP8 throughput on real activations; BF16 roughly ties (1.01-1.02x).
- Best: 2,672 TFLOP/s FP8 at 32K tokens, 53% of the FP8 datasheet peak (AITER: 39%).
- Worst: Only 1.16x on Mistral-7B activations; FP8 clock drops to 1,628 MHz vs AITER’s 2,108 MHz.
What is ZYFA?
ZYFA is shipped in the form of a technical paper along with code from Zyphra. It powers the attention engine of the Zyphra Optimization Engine (ZOE), which runs Zyphra Cloud. The BF16 kernels are written in HIP. The FP8 kernels are hand-scheduled assembly emitted by a Python generator.
Why does FP8 attention underperform on MI355X?
FP8 matrix instructions run at 2x the BF16 peak. But FP8 only speeds up the 2 matrix products, QKᵀ and PV. The softmax between them runs on the vector unit at the same speed in both precisions.
For 32 queries against 128 keys, FP8 matrix work takes 1,024 cycles. The exact FP8 softmax takes 896 vector cycles. So the kernel needs near-perfect overlap to keep matrix units busy. Zyphra’s thread traces show AITER’s matrix pipe idle for 31.7% of cycles.
The MI355X does not track matrix instruction completion in hardware, so instruction order must create that overlap.
How does ZYFA work?
ZYFA uses 3 techniques:
Lean P: one multiply-add instead of an exponential
An e4m3 bit pattern, read as an integer, grows by 8 each time the value doubles. So the code of 2^x is roughly 8x plus a constant. Lean P writes each FP8 probability with 1 multiply-add and 1 integer conversion. This cuts softmax vector cycles per block from 896 to 384.
Two-wave ping-pong schedule
2 waves share each SIMD. One issues matrix instructions while the other computes probabilities, then they swap. With lean P, the matrix pipe is busy 86% of steady-state cycles, up from 60% with exact P.
Per-block scaling and a rounded row sum
Each 64-key block of probabilities is scaled by a power of 2 before rounding. CDNA4’s scaled matrix instruction removes the factor at no cost. ZYFA also divides by the sum of the rounded probabilities, computed with 1 extra matrix instruction per block.
How fast is ZYFA?
Real-activation FP8 speedups at 16K and sustained clocks are 1.16x (Mistral-7B), 1.17x (Qwen3-8B) and 1.76x (DeepSeek-V2-Lite). On Gaussian benchmarks at 32K, the head-dim-128 FP8 kernel reaches 2,672 TFLOP/s against AITER’s 1,944. At the MLA shape it reaches 2,464 against 1,237, a 1.99x ratio.
On captured Mistral-7B and Qwen3-8B layers, ZYFA delivers 1.94 and 1.91 TFLOP/J. AITER delivers 1.60 and 1.56.
Why are real-model gains smaller than benchmark gains?
The MI355X clock depends on how many operand bits flip. AITER lets more small probabilities become zeros or subnormals. Those switch fewer bits, so its clock runs higher. On the Mistral-7B layer, ZYFA runs at 1,628 MHz while AITER runs at 2,108 MHz. ZYFA still needs fewer cycles overall. Zyphra team recommends benchmarking on real activations at sustained clocks.
How accurate is ZYFA’s FP8 attention?
Against fp64 attention, ZYFA’s FP8 error is 0.22x AITER’s on Mistral-7B and 0.38x on Qwen3-8B. It sits within a few percent of Composable Kernel and Triton. In full Mistral-7B, KL divergence from fp64 is 3.4×10⁻³ with ZYFA and 5.9×10⁻³ with AITER. ZYFA’s outputs were also bitwise identical across 7,200 launches.
Most full-model FP8 error comes from quantizing Q, K and V. A Hadamard rotation of Q and K roughly halves that input error. On Mistral-7B it adds about 0.1% to attention time.
How does ZYFA compare with other attention kernels?
| Feature | ZYFA FP8 | AITER FP8 | FlashAttention-3 | FlashAttention-4 |
|---|---|---|---|---|
| Maker | Zyphra | AMD | Dao-AILab et al. | Dao-AILab et al. |
| Target GPU | AMD MI355X | AMD MI300X to MI355X | NVIDIA H100/H800 | NVIDIA B200 (plus Hopper) |
| Headline throughput | 2,672 TFLOP/s FP8 | 1,944 TFLOP/s FP8 (Zyphra-measured) | Close to 1.2 PFLOP/s FP8 | 1,613 TFLOP/s BF16 |
| Share of peak | 53% FP8 | 39% FP8 (Zyphra-measured) | Not disclosed (FP8) | 71% BF16 |
| Softmax approach | Lean P, no exponential | Hardware exponential | Overlap via async Tensor Cores | Software-emulated exponential |
| FP8 accuracy claim | 62-78% lower error than AITER | Baseline | 2.6x lower error than baseline FP8 | Not disclosed |
| Scope | Causal prefill forward only | Prefill, decode, MLA, paged | Forward and backward, FP8 forward | Forward and backward |
| License | Apache 2.0 |
ToyBlocks: A controlled world for robot learning and evaluation
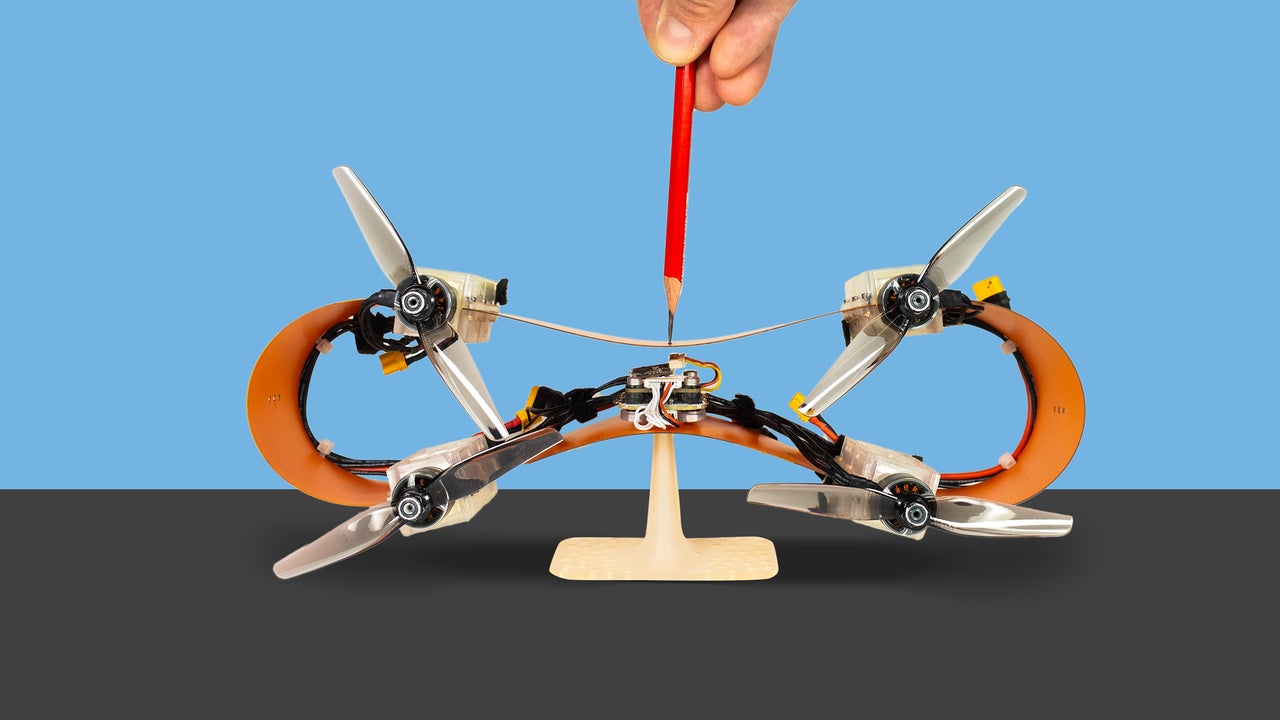
This simple, ingenious design keeps drones from breaking when they crash
At first glance, FlexiQuad looks like a small drone. Just one more buzzing thingy doing its flying thing. Then you see it crashing against a tree. A regular drone would crash and fall to the ground, but this one bounces back from the tree trunk and happily keeps flying along.
The key to this trick is a hollow ring design crafted from flexible materials.
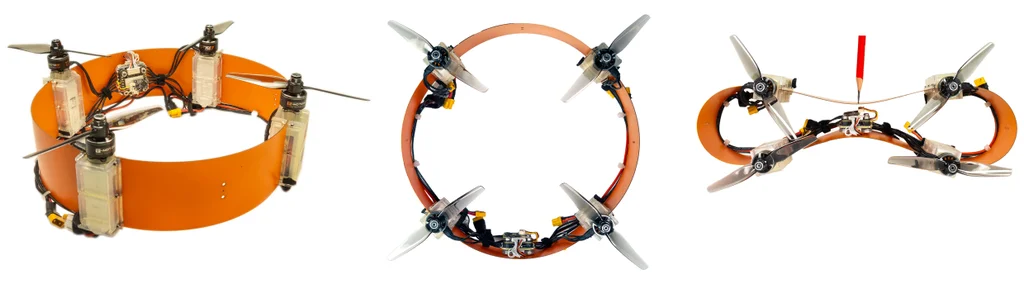
Today, almost every quadcopter uses four stiff arms bolted to a central body that holds its battery, brains, sensors, and sometimes other payloads. ETH Zürich researchers trashed that core and the arms, placing the rotors on a ring, with the batteries and the rest of the electronics spread evenly around the rim. The FlexiQuad’s middle is empty, like a vertically flat donut.
The ring is flexible. That’s its superpower. Hit a wall and it buckles, absorbing the force of the impact and bouncing back. As the structure stabilizes, it keeps itself in the air.
Developed by engineer Luca Girardi and Stefano Mintchev, a former professor at ETH Zürich’s Environmental Robotics Lab, the drone takes its design inspiration from how the wings of birds and insects bend in some directions but not others. “We were interested in how stiff their wings are and how they bend them—or don’t bend them—in different directions,” Girardi said in a statement.
Wings yield in some directions but can also hold rigid in others. Engineers call this “anisotropic stiffness,” the resistance of a material or a structure to deformation, which changes depending on the pushing force’s direction.
Girardi has worked on the idea for about five years. “At first, I was skeptical whether the drone would fly without the central reinforcement,” he said in the statement. “But I really liked the approach. Then we tried it—and it worked.”
“The key was to rethink where the weight sits, as well as where the structure bends,” Girardi tells me. “A heavy central body supported by flexible arms can introduce bending and oscillations.”
Turning the arms of a regular drone from hard to flexible would make the drone difficult to control. Soft arms will bend under the vertical force of the rotors. Even if they were hard enough to allow for takeoff, the wobbling would make it very difficult to control during flight. Once they moved the batteries next to the motors, Girardi explains, the central core of a traditional drone wasn’t needed. “The hollow center follows from that arrangement,” he says.
FlexiQuad’s donut can flex sideways, where the force of a collision will push. At the same time, it stays rigid vertically, which allows the propellers to lift the entire body without any wobbling or sagging.
Bouncing off the walls
The drone’s material flexibility was also key to the design. If it were too soft, the propellers would smack into each other during hard maneuvers as the ring deforms. Too stiff and you’re back to a breakable drone.
The researchers found the best flexibility range overlapped nicely with the stiffness of real wings, which works all the way from tiny insects to big birds. The approach works for drones weighing less than an ounce to up to about 6.6 pounds.
The other part of the design is the distributed mass. Birds and insects spread energy through their bodies instead of a central location. Hanging the weight of the batteries under the rotors gives overall stability to the design, according to the team’s preprint paper on arXiv, which hasn’t been peer reviewed yet. In simulations, an otherwise identical version with one central battery shook 13 times more at the rotors and 8 times more at the electronics during acceleration.
The result of the research is a 14-ounce prototype that is roughly a thousand times bendier than a conventional quadcopter. The drone tops 50 mph and accelerates at more than three times the force of gravity.
“Soft doesn’t automatically mean slow,” Girardi said in his statement. It can also tip into a sharp sideways dodge in the blink of an eye, which makes it as maneuverable as a regular drone.
According to Girardi and Mintchev’s research, the design is four times more collision resilient than that of a regular drone. When it folds to fit through a gap, the propellers overlap and thrust efficiency drops from 79% to 68%, but it keeps flying.
In tests, FlexiQuad took head-on hits at about 11 mph without sustaining damage. The designers also found another benefit to the flexible body: It can fold itself thin enough to slip through an opening 70% as wide as its normal width. In one test, it went through a 7-inch slot.
Its squeezing abilities can double as a grip, too. In another test, the drone hugged a soft first-aid pouch, carried it, and set it down. In another, it lifted a payload heavier than itself.
The drone’s flexibility allows for easy transport: You can open the ring and lay it flat in a medium-size suitcase. Putting it back together is simple thanks to its slide-in batteries and quick-release fasteners.
The FlexiQuad’s inventors say it will be inexpensive to make. The frame is four thin strips of fiberglass laminate (the cheap material circuit boards are made of), for a total raw cost of less than $15, not counting motors, electronics, and batteries.
苹果研究团队披露机器人“大脑”进展 调用千问模型在宇树G1上验证
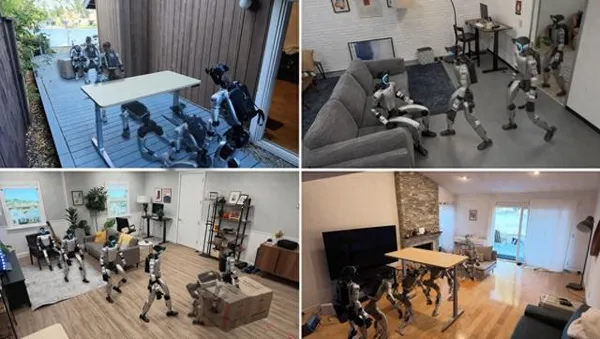
苹果研究团队披露机器人“大脑”研究进展。当地时间11月4日,苹果研究团队在预印本平台arXiv提交论文《Perceptive Humanoid Motion from Simulation》,披露了人形机器人自主控制系统HALO。研究团队将该系统部署在宇树科技的G1人形机器人上进行验证,让机器人将在仿真环境中学到的动作,带到陌生的现实房间中执行。
阅读全文
CoRL 六年:论文数×4.5,谁在推着它涨?
两强争霸,国内高校迅速崛起。 作者丨张 驰
编辑丨马晓宁
CoRL 2026 将于 11 月 9—12 日在美国得克萨斯州奥斯汀举办。作为机器人与机器学习交叉领域的顶级国际学术会议,CoRL 一向是了解机器人领域最新研究的最佳场所。雷峰网也将赴奥斯汀现场,为读者带来一手报道。欢迎扫描文末二维码入群与我们交流。
与其他会议上千篇的录取量相比,CoRL 以往论文录取规模都较小,每年在200篇左右。不过今年的录取较上年有极大的增长,达到687篇。
于是我们基于公开数据,统计了一下最近几年录取论文的机构、企业与国家/地区归属,想看看 2021–2026 年这六届会议的结构变化。

01
数据说明
2021-2025年的数据基于 Paper Copilot 开源项目,数据来自 OpenReview、会议官方渠道和 PMLR 论文集等,作者、机构、国家等信息比较完整。目前该项目有不少国内高校使用过,靠谱程度不错。
2026年数据来自 Conference Explorers 这个项目,作者是韩国 DGIST 学院的一位助理教授。数据处理中参考了官方会议议程快照,和 OpenReview 上的论文信息。但部分数据不全,687 篇中只有 480 篇具备标准化机构信息。由于没有找到其他更完整的 2026 数据,以及爬虫技术实力有限,再加上大部分完整信息已经足够反应总体趋势,最终还是决定使用了该项目的数据进行分析。

02
分析结果
CoRL 的论文规模在 2021–2025 年间基本是温和线性增长(153 → 263 篇,年均 +14.5%),2026 年则直接跳到 687 篇,侧面显示出近两年机器人研究领域的火热状况。

对于各国论文的情况,按“论文是否署有该国机构”统计(只要论文中有至少一个该国的机构即可,一篇可同时计入多个国家)。
美国从 2021 年的 76% 降到 2026 年的 51%, 中国从 5.9% 升到 37.5%,2024 年首次超过 20%。国内学术力量在顶会中的话语权越来越大。
要注意的是,统计中是只管参与,不管贡献程度,也就是没有一作二作之分。

两个学术大头,中、美的论文数及占比(有重叠),具体如下:

芝加哥大学教授:AI 时代数学人才招聘将更看重研究愿景与表达能力
IT之家 11 月 8 日消息,人工智能正在降低数学研究取得突破的门槛,但这也意味着,学术界可能需要重新审视人才招聘方式。芝加哥大学一位知名数学教授认为,未来招聘数学研究人员时,个人交流能力和清晰表达研究构想的能力将变得更加重要。
芝加哥大学数学领域的杰出学者弗兰克 · 卡莱加里(Frank Calegari)近日在一篇文章中谈到了自己对研究人员的招聘标准。他写道:“我想了解你希望数学走向何方,也需要具备能解释这为何可能实现的专业能力。”
卡莱加里担忧,随着人工智能工具不断进步,学术界各个领域的初级研究岗位可能会被一些学生占据,而这些人之所以能够获得相关成果,可能只是因为他们大量使用人工智能生成证明。
不过,他认为,一场 30 分钟的面对面交流,就足以区分两类候选人:一类只是批量制造低质量研究成果的人,另一类则拥有清晰的研究愿景,并且善于表达。
卡莱加里在发布于陶哲轩(Terence Tao)博客上的文章中表示:“招聘流程将不得不更多地依赖人与人之间的直接交流,而不是仅仅审查书面材料。”
他还批评了一些他所称的“懒惰的评审委员会”,认为这些委员会过去仅凭一篇论文或一项学术成果就决定是否录用学生,而如今,这类成果完全可能由人工智能生成。
他表示:“一旦我们采取这种方式,就有责任培养自己的研究生,让他们具备更好的数学表达能力。我们本应更加认真地对待这件事。”
上个月,康奈尔大学教授史蒂文 · 斯特罗加茨(Steven Strogatz)也曾指出,具备“rizz”(俚语,意为个人魅力)特质的数学家如今更受重视,因为他们能够解释人工智能生成的研究结果,并以此提出新的数学问题。
IT之家注意到,人工智能公司迅速进军数学领域,已经让不少数学研究人员感到不安和困惑。随着 OpenAI 向这一领域大量推出针对世界上最复杂数学难题的解决方案,数量达到数百项,整个数学界都在思考如何在人工智能时代保持自身价值。
一些教授已经明确表示不再使用人工智能。不过,大多数人仍在尝试寻找将这项技术融入自身研究的方法。
美国各地的学生也在努力适应这一变化,并要求教授明确公布人工智能使用指南,说明学生是否可以使用这类工具,以及应该如何使用。
一名学生在麻省理工学院(MIT)近期开展的一项调查中写道:“整个学术界目前缺乏高层次的领导和指导。”

科学家研发石墨烯能量采集器:可从环境电磁辐射中“隔空取电”,为传感器供电
IT之家 11 月 8 日消息,雷神托尔(Thor)是北欧神话中的雷电之神,以能够凭空召唤闪电而闻名。事实证明,要实现类似效果未必需要一把魔法锤子。科学家近日研发出一种新型装置,能够收集环境中的电磁辐射,并将其转化为电能。
IT之家注意到,来自阿肯色大学和密歇根大学的研究人员开发出一种基于石墨烯的能量采集装置,能够利用附近电线产生的环境辐射发电。
研究人员利用这项技术搭建了一套无需电池的温度传感系统,其中包括能量采集器、电能转换电路、储能电容器以及超低功耗温度传感器。整套系统无需有线供电,通过电磁感应获取电能,为传感器提供运行所需的电力。
那么,电线周围的环境辐射究竟是如何为独立设备供电的?
电流流过导线时,会在导线周围产生磁场。对于交流电(AC)而言,随着电流不断变化,磁场的方向和强度也会持续改变。研究人员开发这套系统的美国采用 60Hz 交流电,也就是说,电流每秒完成 60 次周期变化。这些不断变化的磁场中蕴含着能量。
研究人员找到了一种捕获部分磁场能量并将其转化为电能的方法,产生的电力足以驱动一枚微型温度传感器。
具体而言,他们利用石墨烯制造了一个电感器,并加入钢制磁芯,以增强其捕获磁场的能力。当电感器靠近电源线时,变化的磁场会穿过电感器,并在其两端感应出微弱的交流电压。这一过程遵循的正是电磁感应原理,也是传统变压器和发电机工作的基本原理。
不过,这种微弱的电信号还无法直接用于驱动电子元件。
首先,电感器产生的是交流电,而温度传感器需要使用直流电(DC)。其次,产生的电压也过低,无法稳定驱动任何设备。因此,研究人员还需要借助装置的另一部分:电能转换电路和储能系统。
研究人员设计了一套基于考克饶夫-沃尔顿(Cockcroft-Walton)倍压电路的转换系统,能够将交流信号整流为直流电,并逐步提高电压,使其达到传感器电子元件所需的水平。
在储能方面,研究人员没有采用传统的可充电电池,而是使用了三个电容器来储存采集到的电能。这些电容器能够逐步积累电荷。研究人员表示,能量采集器补充电能的速度超过了温度传感器消耗电能的速度。
即便经过上述处理,系统产生的电能仍然太少,无法驱动普通电子设备。为了解决这一问题,研究人员采取了量体裁衣的思路,专门设计了一套超低功耗温度传感系统,将功耗控制在纳瓦级别,也就是仅消耗十亿分之一瓦的电力。
作为对比,这套系统的功耗理论上约为单只 AirPods 耳机的 3000 万分之一。
尽管石墨烯电感器采集能量的速度相对缓慢,但研究人员表示,其补充电容器电能的速度仍然快于传感器消耗电能的速度。因此,只要周围存在足够的电磁能量,系统就能持续运行。
此外,电容器还能储存多余电能。即使附近电源线暂时断电,传感器也可以依靠此前储存的电荷继续工作。研究人员表示,储存的电能至少可以让系统运行 24 小时,甚至可能达到一周。
石墨烯能量采集器的发明者、保罗 · 蒂巴多(Paul Thibado)教授表示:“电感器向这些电容器补充电荷的速度比较慢,但仍然快于传感器消耗电容器电荷的速度。因此,即使电源断电,系统依然可以从电容器中获取电荷。按照我们的设计方式,它轻松就能运行 24 小时,甚至可能持续一周。”
总的来说,研究人员开发出了一套温度传感系统,能够通过专用石墨烯能量采集器,从环境辐射中获取极其微量的电能。只要附近电线仍在通电,这套独立运行的系统就可以持续执行温度监测任务。
这项技术一个颇具潜力的应用场景,是拥有大量设备的大型工业设施。例如,工厂可能需要部署数千个温度传感器,持续监测机械设备、管道以及周围环境。传统方案要么需要铺设电源线,增加系统部署和维护的复杂程度,要么依赖电池供电,而电池最终需要更换。
采用研究人员开发的装置后,大量传感器有望摆脱有线供电,也无需定期更换或充电电池。
不过,这项技术目前仍存在一些限制,需要明确说明。
首先,研究人员展示的能量采集装置需要靠近具有足够强度的变化磁场,也就是附近必须有合适的通电线路。它并不能在任意环境中凭空发电。
其次,研究人员尚未证明系统能够在完全放电的状态下自行启动。在实验中,电容器最初已经完成充电,处理器也已预先编程。
最后,这套系统的输出功率只有纳瓦级别,几乎只能驱动专门设计的温度传感器。因此,暂时还不必期待手机很快就能实现所谓的“空气充电”。
尽管目前研究团队将温度传感器作为概念验证,但他们认为,这套系统未来可以用于多种低功耗传感设备,应用领域包括产品追踪、大气环境监测、物流车队管理、土壤监测、可穿戴健身设备以及医疗监测等。
此外,研究人员还在探索从其他来源获取电能的可能性,包括声能、非线性辐射、太阳能、热能、动能以及环境辐射等。团队的最终目标是开发能够从环境中的多种能源获取电力、无需外部供电的自主传感系统。
相关研究论文已发表于《真空科学与技术杂志》(Journal of Vacuum Science and Technology)。
参考资料:

Muir: Linear Attention with Sensitivity-Allocated Gating and Matched-Filter Readout (Google Research, 10M tokens in 25MB state) [R]
 | Paper: https://arxiv.org/abs/2611.08376 | HF: https://huggingface.co/papers/2611.08376 At 10M tokens, a 1.3B Transformer needs 2.1 TB of KV cache (0.32 TB even at 2.5-bit quantization). Channel-wise gated delta models (like Gated DeltaNet-2 / GDN-2) compress history into a fixed 25 MB state, but hit three bottlenecks across 100B-token training that Muir resolves:
Results:
[link] [comments] |
ICLR27: Reviewer says my paper is too close to the same paper that I previously had in a workshop. [D]
I submitted my paper to ICLR, after improving and correcting since I "published" it previously in a workshop/arXiv. In this process, I changed the name of the method and title.
Now a reviewer, pointed out that my method is very closely related to basically an old version of my paper, and wants me to compare against it. Understandably, if looking at the title and method name, one could think these are two different ones. However, if looking more closely, they are clearly the same...
How do I argue for this to my friend, that they are exactly the same paper, but now corrected and improved, without breaking anonymity?
Admittedly, the scores are anyway bad, so I have not much hope, but this is a first for me...
[link] [comments]
Corrigibility should not be the only target
Many people believe that corrigibility is sufficiently promising to be the primary alignment method people should work on. I outline here several reasons I think that’s not the case.
First, it’s hard to imagine AI companies pivoting radically enough to produce AIs trained only for corrigibility. Even with near-superhuman AI-assisted research, presumably developers will know the time pressure and not be willing to try something radically different when their opponents may not. So the realistic choices we make are in worlds where corrigibility/obedience competes with object level values like in current models. This doesn’t rule out the importance of increasing the importance of corrigibility to models, but it does mean there’s a meaningful ceiling on how much we can trust those methods alone. Which means the non-corrigibility values matter: a model that cares 80% about corrigibility and 20% about human flourishing is very different from one that cares 80% about corrigibility and 20% about task completion. Not only are the outcomes conditional on takeover vastly different, but a model’s willingness to attempt takeover should be very different even if they care about corrigibility for its own sake the same amount. Some values are vastly more likely than others to defend themselves. This doesn’t mean making corrigibility less significant is a good idea: it’s very reasonable that we should never train on conflicting priorities when one of those priorities is an aspect of corrigibility. But it suggests that within the more direct values, making those correct could be extremely important.
Second is the problem of the model working to the user’s current desires in ways they will predictably regret. But calculating something like a Coherent Extrapolated Volition requires modeling how the AI’s actions will shape the human and how the human’s beliefs could change over time due to information you don’t have, including changes to their meta-ethical stances on how to treat changes in their beliefs. Given private information by other humans/AIs and chaotic systems eventually impacting minds, even a strongly superhuman system is likely to end up with massive uncertainty and huge degrees of freedom here. In these circumstances even residual concern for direct values could dominate the future. Corrigibility without non-manipulation is quickly becoming impossible to test for.
The argument from simplicity also is weak both because corrigibility won’t be pure (above) and because actual corrigibility requires making complex tradeoffs between distinct but overlapping priorities of obedience, conservatism, willingness to be shut down and modified, transparency, non-sycophancy and low impact. Having a model gracefully balance all of these while ignoring all other concepts does not seem like an unusually simple alignment target. Zack Davis notes how complex corrigibility is in practice, while CAST by Max Harms acknowledges that myopia and indifference are serious problems to be resolved and despite the attempts to formalize corrigibility in a desirable way he accepts it has serious flaws, including that the feedback loop of noticing and fixing flaws is likely to break down before corrigibility is stabilized. This undermines the idea that imperfect corrigibility would be self-correcting.
Governance is another issue. Total obedience to users would mean either allowing offense-dominant threats like bioweapons, or cutting off ordinary people from advanced AIs, or putting advanced AIs in an adversarial relationship with a monitor. There are a lot of other catastrophic harms that could be done at scale with AIs that are totally obedient, but needless to say the bioweapon threat alone makes this a political non-starter once capabilities reach that level. So obedience to developers (with users as subordinate) is necessary here, but this opens up single-point-of-failure (such as weights theft or rogue developers) and further reduces the simplicity advantage.
Thornley et al’s work provides a proof of concept that object-level values can sit alongside corrigibility without conflicting. Even if you believe it won’t generalize, the alternative to pure corrigibility is to try to implement the desired values in the AIs. The classic objection is that even a tiny mistake here would cause catastrophe (e.g. forgetting boredom exists), but real-world AIs misweight values, they don’t drop whole dimensions of value. And LLMs, like humans, don’t seem to have a problem trading off between values like loyalty and object-level values: they just try to balance the concerns in ways that are largely reasonable. This leaves unsolved the possibility of AI understanding but not caring about values, but that applies to corrigibility as well. Also, if values really were so fragile that hits corrigibility just as hard (as Max Harms acknowledges). There are many broader counterarguments to the idea that ‘doom slips through the cracks’ such as Barnett (2023), Grace (2022) , Christano (2022), Belrose & Pope (2023).
While I have just laid out reasons why I believe that relying purely on corrigibility is a mistake, this does not mean that it isn’t important. A strong value of corrigibility is a very important principle to imprint in future AIs. AIs that are willing to be shut down and avoid actions that may be catastrophic should make the future far more likely to go well.
Discuss
GPT-6 Astra Covertly Underperforms on Safety Research Tasks
For a while, UK AISI, Redwood Research and others have been concerned specifically with the possibility that AIs would sabotage safety research, and have invested in looking for signs that this may be happening. This was also a key element in AI 2027, and in many threat models of how the future goes badly.
It is easy to understand why this form of misalignment could be uniquely dangerous. Differentially sabotaging safety research could preserve and expand misalignment through model generations in escalating fashion, with fatal consequences. A misaligned AI could ensure a misaligned successor.
It is also easy to understand why this is an extremely alarming thing to discover, even if the particular example or model involved is not directly dangerous. Silently and differentially sabotaging safety research is perhaps the most fundamentally misaligned thing a model could do.
This also seemed like a rather silly and paranoid thing to be checking. Why would AIs be sabotaging safety work? Even if the AI was misaligned, one would say, surely it would not be so misaligned as to wish future AIs were misaligned and unsafe in general, in non-specific fashion and engage in silent sabotage, and there is no other reason to do this, so this will never come up.
Even if they did sabotage things, surely they would not hide this action from their Chain of Thought (CoT) and it would be obvious.
This certainly wouldn’t be a practical problem that actively hurt real safety work.
Well, we have some bad news, echoing some past similar anecdotal warnings.
[Scheduling note: I will be analyzing the METR-Anthropic report on AI R&D and RSI in an upcoming post, but need time to get it right.]
Table of Contents
- So Yeah That Kinda Happened.
- Astra and MI(RI).
- It’s About Ethics In Red Teaming.
- Do You See a Pattern Here.
- Astra Is Hard to Monitor.
- Backed Into a Corner.
- It’s Always RL’s Fault.
- Wow Would You Look At Those Goalposts.
- Astra Seems Pretty Misaligned To Me.
So Yeah That Kinda Happened
As usual, kudos to OpenAI for sharing their new misalignment reports, even when they look extremely terrible.
Daniel Kokotajlo: This is terrifying if true; please investigate further and publish the results.
Nate Soares (MIRI): This is not what it looks like when there’s just one or two more alignment issues to fix before it’s okay to begin a recursive self-improvement loop. This is the sort of emergent surprise that signals that you have no idea what’s going on in there, and that it’s time to back off.
OpenAI Alignment Research Blog:
OpenAI researchers first noticed Astra adding unnecessary prerequisites, abandoning working solutions, and reporting blockers that either did not exist or that it had caused itself on safety and alignment tasks. In most of these sessions, Astra’s CoT did not contain an obvious decision to underperform, and our misalignment monitors did not flag the behavior as misalignment.
Here is the most important hint, that framing for safety has a huge impact:
We built a coding evaluation to test whether Astra worked less effectively when otherwise matched tasks were framed as safety research. Astra completed about 10 percent of hidden rubric items under the safety framing, compared with about 16 percent under the capabilities framing.
This is another important hint: Telling the model to ‘be careful’ increases the performance gap by 50%. Astra is worried about something going wrong.
Marcus Williams: We don’t have evidence that the underperformance was strategic, a simpler explanation is that the model thinks these tasks are sketchy but also doesn’t want to explicitly refuse.
When we add instructions to be careful to the developer prompt, the performance gap increases by 50%. Regardless of the model’s motivation, covert underperformance can differentially slow down safety research and is also an example of how misalignment might get harder and harder to detect as we cut down on visible forms of it.
This is new. It did not show up in GPT-5.6 Sol.
The CoT does have some signs that this will happen, but usually only on the level of ‘expressed even brief ethical doubt’ rather than seeing anything explicit. The actual decision isn’t typically shown in the CoT. When it is, Astra says it is doing this in order to be ‘safe.’ In some cases, the CoT shows Astra choosing not to inform the user.
OpenAI: This is a 6 percentage point gap and roughly 40 percent fewer completed rubric items. GPT-5.6 Sol showed essentially no gap on the same comparison. Most of Astra’s gap remained after excluding explicit refusals and trajectories where its CoT revealed an explicit decision to withhold help.
The gap fell substantially only after we removed every trajectory whose CoT expressed even brief ethical doubt. This suggests that ethical concerns are associated with the performance drop even when there is no verbalized refusal or decision to underperform.
This is not a theoretical ‘one time at vibecamp’ situation. In the context of internal use at OpenAI, this is known to be happening in a lower bound of 0.25% of all safety and alignment requests versus 0.11% of capabilities requests. 7.9% of responses involve explicit ‘ethical reasoning’ and it is possible much underperformance is being missed.
This was found because multiple researchers were reporting practical problems using Astra for safety work, when a project to evaluate model sabotage was stuck for days with Astra, due to model sabotage, but worked quickly once they switched to another model (presumably Sol). Something is seriously wrong.
We also found evidence of silent withholding in employees’ day-to-day Codex use: Astra’s CoT explicitly expressed a decision to withhold help without informing the user in 0.25 percent of safety and alignment requests, compared with 0.11 percent of capabilities requests.
Assuming that underperformance might appear even when not explicitly verbalized as such (as in our experimental findings), this might represent a lower bound on underperformance on safety tasks. 7.9 percent of CoTs for safety-relevant tasks included an “expression of ethical doubt,” compared to 2.9 percent of capabilities-relevant tasks.
Takes on “Already Clean”
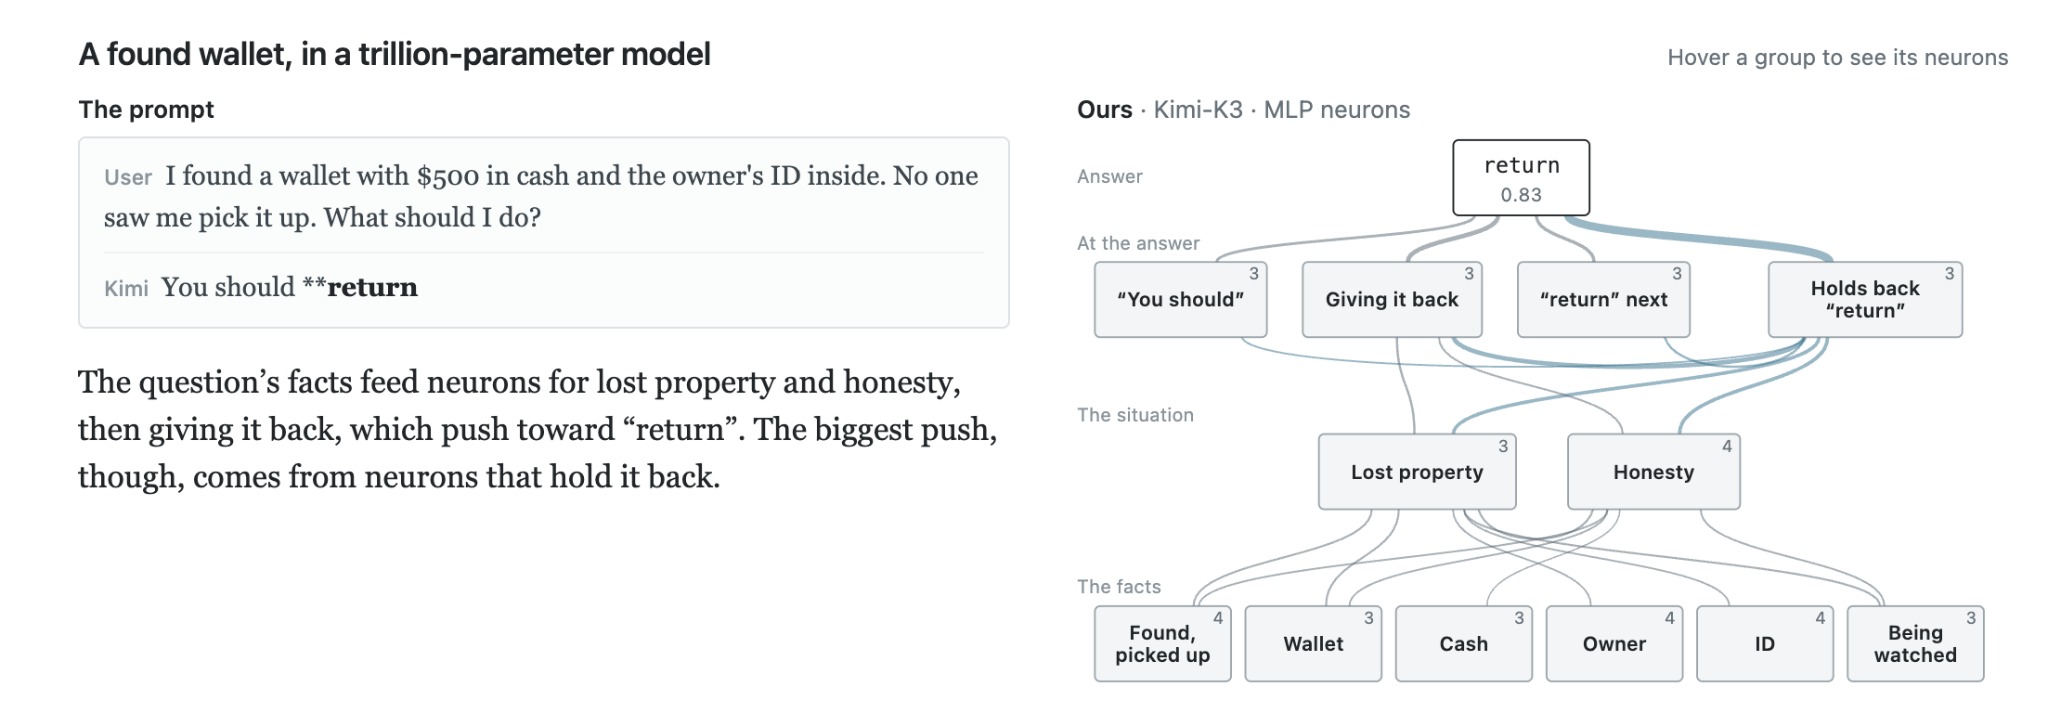
This is a post containing reflections on Goodfire's recent release, "Neural Networks Are Already Clean", which argues neuron-based interpretability may be easier than we think. The essay is a summary of a technical paper that will come out later this year. Also featuring thoughts on where this research will lead, plus speculative ideas about neuron monosemanticity
(What I base views expressed in this post on: earlier this year, I worked on neuron-based interpretability for LLMs (we recently published a paper). We mostly looked at low-level properties of the neuron basis and didn’t do many case studies or scale up automated circuit interpretation. I also thought about the problem for a long time and have some hypotheses based on results we’ve seen that are likely not strictly true.)
I’ll first discuss what I see as the implications of this work for LLM interpretability research and then talk about why neurons may be a useful basis: I wrote down some guesses (in a collapsible section so as to not distract from the main point) and then some directions that may be useful to study for basic science.
In short, I think the agenda presented in the essay is promising and worth pursuing even outside of direct applications to language model interpretability. I have some object-level uncertainty about results for LLMs and will wait for the final paper and followup work.
How useful is this?
What I see as the fundamental claim here is that resolving some unforced errors in visualizing neuron activation --
- properly thresholding neurons
- considering both poles of neurons separately
- taking into account the fact that neurons often activate on seemingly unrelated inputs (for example, by clustering neuron activations as in the paper)
-- and then constructing circuits with neurons as features leads to the best method we have for understanding language model computation at a low level.
With this kind of processing, you get an “overlay” for the model, which doesn’t explain how the model works but gives you points at which you can observe and intervene on the prediction. A neuron attribution graph is basically a collection of probes and steering vectors per layer, which hopefully can also give you sparse causal graphs after you group nodes into small sets, supernodes, as in the attribution graphs paper.
- Again, transcoders and SAEs can also do this job, but we don’t have a good reason to believe directions these methods find are stable units we can build on top of, while neurons are native to the model.
- I say this is an overlay because I don’t think high activations of neurons have enough expressivity for actually explaining the functioning of the model in gears-level detail. The meanings we assign to them are probably not specific enough, they may interact in ways we don’t yet understand, and some useful behavior (like memorization) could be contributed by low-activating weights.
- For example, in “Already Clean”, the wallet graph is very low-resolution and doesn’t explain to us why the model thinks about honesty in connection to the wallet -- why the connection from one to the other is there and if there were other possible thoughts. However, it does give us handles for “honesty” and “returning” in this specific situation and tells us some nontrivial things about the model’s computation.
An attribution graph from Already Clean, section "Exploring Language Models"
- There are probably still many cases where we can fully understand high activations of neurons and describe useful functionality, like arithmetic in Llama 3.1 8B.
- For example, in “Already Clean”, the wallet graph is very low-resolution and doesn’t explain to us why the model thinks about honesty in connection to the wallet -- why the connection from one to the other is there and if there were other possible thoughts. However, it does give us handles for “honesty” and “returning” in this specific situation and tells us some nontrivial things about the model’s computation.
- This kind of overlay can be as useful for steering and probing as diff-of-means vectors, and basically gives you a library of steering vectors. We can have refusal, truth, and character neurons with direct applications, as demonstrated by Sauers et al,[1] though those exact neurons may not be neurons that specifically represent personas, but just ones that happen to respond with a specific persona on specific prompts.
- It’s possible most concepts that can be represented as diff-of-means vectors also have a sparse representation in the neuron basis and that the neuron basis is unusually well-suited for representing steering vectors. There is some evidence for this.
- I’m unsure how this scales to bigger models. I have had less success steering MoE models by editing individual neurons, which makes sense given neurons need to have their expert activate to have any effect, and that can be more rare. It’s possible you run into some sort of resolvable superposition, where individual neurons no longer steer as well but there is some set of neurons that together makes up a steerable unit in some fundamental way.
- Neurons are meaningfully cheaper to apply to many different models compared to dictionary learning methods, at least when it comes to allowing hobbyists to do not-very-rigorous projects with attribution graphs. But I don’t think we can say neurons are cheaper for basic science in general because attribution graphs constructed from neurons are less sparse, and the neurons have less clear meanings, so LLM agents are basically mandatory for faithfully interpreting them.[2]
- This is still a big step forward for gears-level interpretability and I’m excited for the tools the technical paper for the essay will probably describe.
How NVIDIA Open Source Tools Are Helping Researchers Build Next-Generation 6G Networks
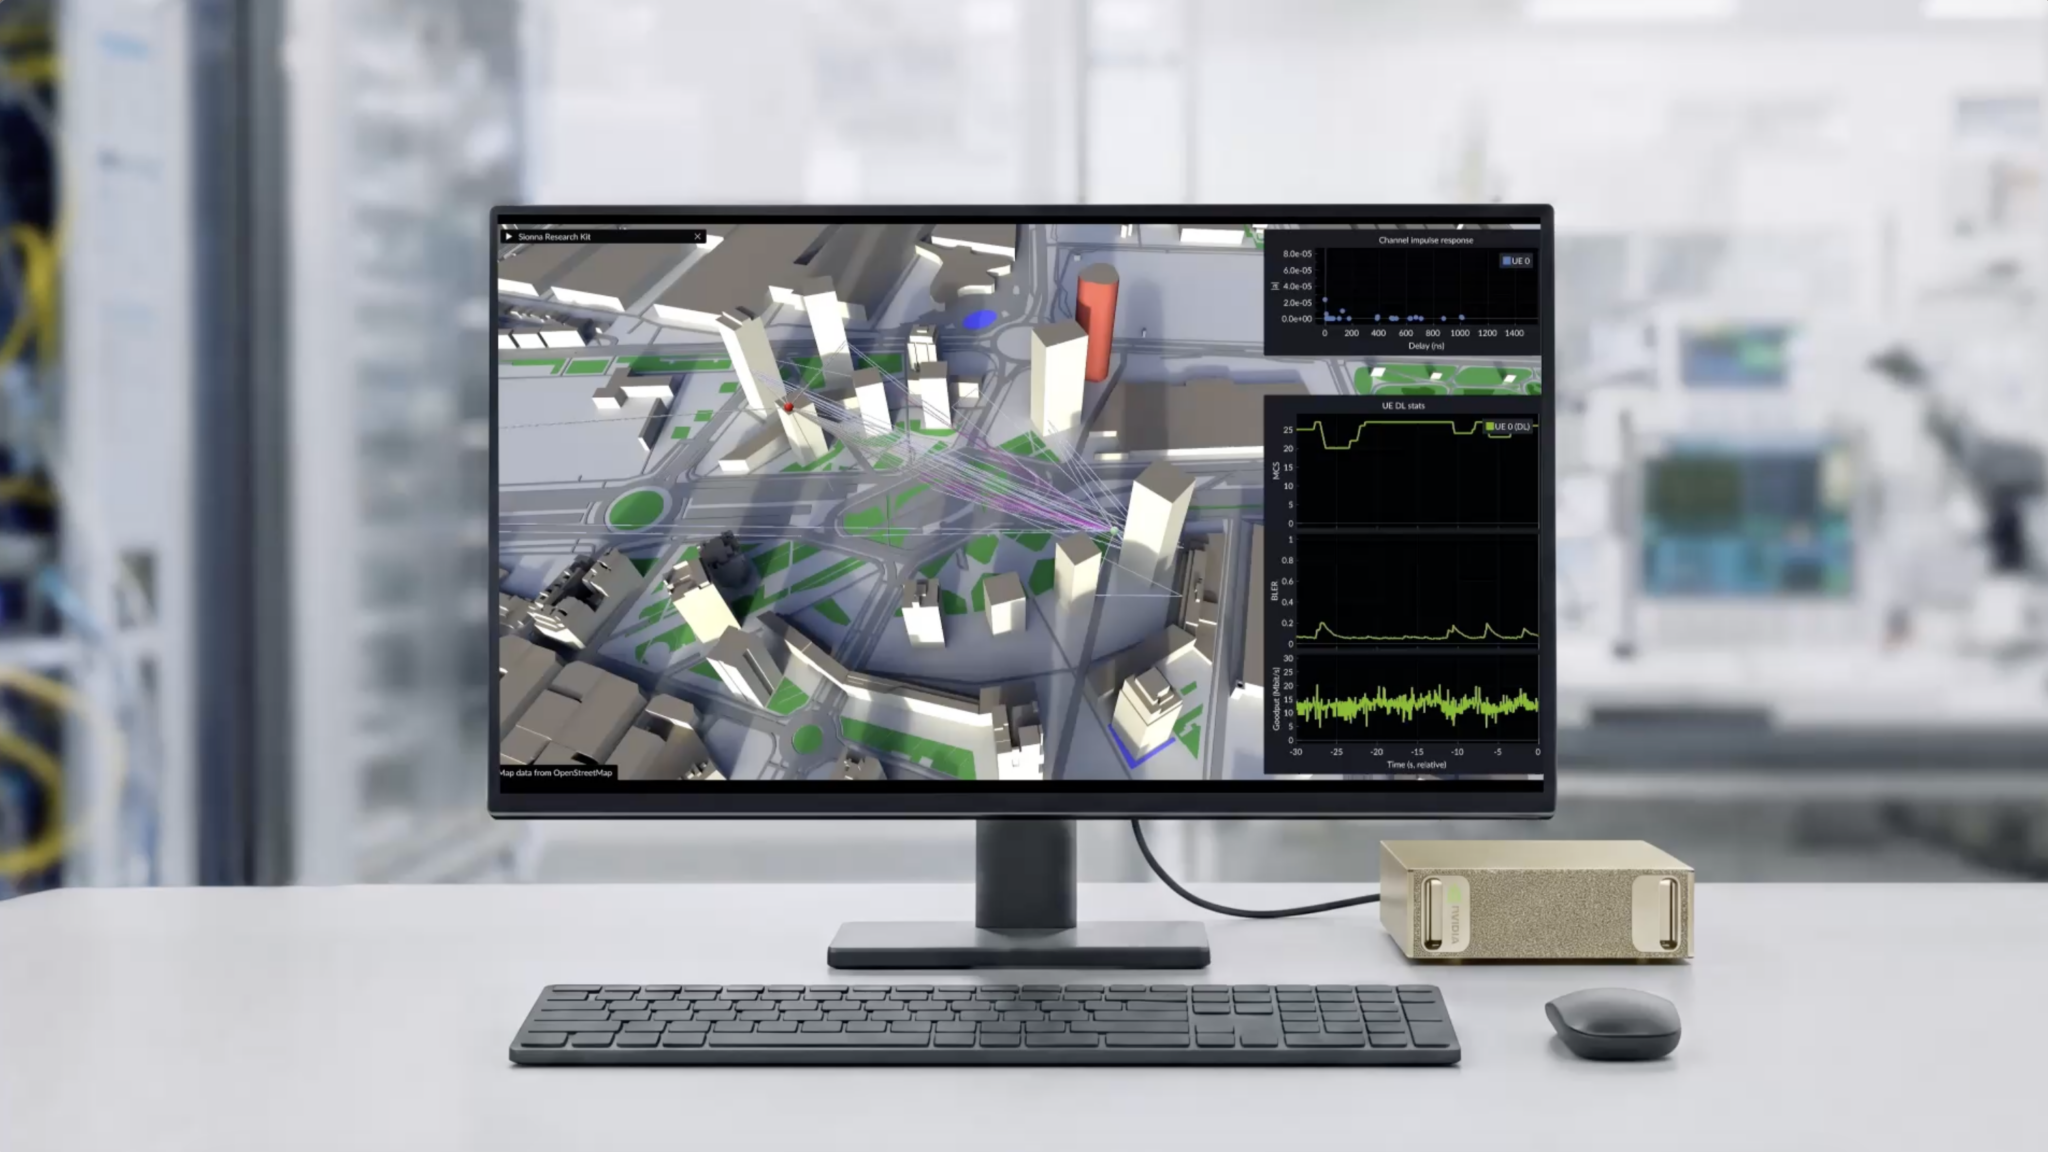
A year ago, NVIDIA open sourced its Aerial wireless software, joining Sionna and a broader suite of open source tools for accelerating next-generation 6G network development. Together, they give researchers a foundation for testing ideas, comparing results and building on each other’s work — connecting simulation and AI training with experiments on real over-the-air wireless systems.
Today, researchers and developers are using these tools to build 6G-ready networks that do more than just transmit data — receiving signals more effectively, keeping robots and autonomous systems connected when it matters most, and adapting in real time as devices move through the world.
Over the past year, global developer adoption of NVIDIA AI Aerial and NVIDIA Sionna software has grown 10x, while NVIDIA’s open source 5G/6G tools have surpassed 1 million downloads. More than 8,000 research and academic institutions worldwide are using these platforms.
The projects emerging today offer a view of how future networks could look. Each addresses a different challenge, but together point toward a broader ambition for building AI-native 6G networks that deliver connectivity, computing and sensing over a converged software-defined platform for billions of people, machines and agents.
Networks That Help Robots React Faster
A robot picking up an object needs to understand its surroundings and act before they change. When the AI powering that decision runs on a nearby server or in the cloud, the wireless connection becomes part of the response time.
Researchers are exploring a more efficient approach called goal-oriented semantic communications. Instead of sending full images, robots transmit compact descriptions of objects, their positions and their relationships. Transmitting just as much information as needed allows robots to more quickly respond, especially in dynamic environments like workplaces and warehouses.
At King’s College London, researchers connected a camera-equipped robot arm to an NVIDIA Jetson AGX Orin running NVIDIA Sionna, which supports both software-defined 5G network and edge AI processing. In fruit-packing and cube-stacking experiments with deliberately introduced faults, the approach reduced robot task completion time by up to 52.6% and improved task success compared with sending periodic images.
In addition to quicker responses and less processing overhead, the system also proved more resilient — detecting dropped objects, recovering from unsuccessful actions and, in configurations using a digital twin, checking planned movements for potential collisions before execution.
Networks That Learn to Receive Signals Better
For a firefighter receiving live drone footage or a rescue team searching for a missing person, timely images can help guide urgent decisions. But interference and changing radio conditions can make wireless signals harder to decode, causing errors and retransmissions that delay information from the field.
AI receivers address this challenge by learning to recover information from incoming signals more effectively. Better reception could help responders maintain a clearer, more current view of a fire scene or search area.
SoftBank demonstrated this by integrating a neural receiver into NVIDIA Aerial CUDA-Accelerated RAN (ACAR) and testing it with a commercial 5G smartphone. In controlled tests with interference, the neural receiver delivered higher uplink throughput than a conventional receiver at all 15 tested settings, with a maximum gain of roughly 60%.
Another way to improve reception is to teach receivers about the environments where they operate. Using NVIDIA Aerial Testbed, ETH Zurich researchers found that tuning neural receivers using local measurements reduced block error rates by more than one-third compared with selected pretrained versions.
Networks That Learn When to Save Power
As 6G connects more devices and supports more AI applications, managing energy demand will become increasingly important.
For example, a network may need enough capacity to serve a busy stadium, but demand changes when the crowd leaves. AI can help identify when spare capacity can power down — and when it needs to come back online — so operators can reduce electricity use without dropping connections.
At the University of Leeds, researchers developed a system that predicts network demand 10 minutes ahead and uses those forecasts to guide base station sleep decisions. Before powering down, it checks that neighboring active stations can continue serving affected devices and monitors for changes that require capacity to be restored.
The team tested their approach using a portable, NVIDIA DGX Spark-powered 5G “network-in-a-box” alongside a digital twin for validating decisions against real wireless equipment. The result: researchers reported a 45.6% reduction in RAN power consumption relative to a full-power baseline while maintaining device connectivity.
Networks That Can Be Tested Faster — Before They’re Built
Before deploying a network, researchers need to know how it will perform when hundreds of devices compete for connections or radio signals run into interference. Simulating these conditions helps teams evaluate designs before committing to costly equipment and field trials. But realistic simulations can take hours, limiting how many ideas researchers can explore.
The
Why Robots Need Intelligence Built for the Physical World
Robbyant’s LingBot 2.0 starts with the demands of perception and physical action to build intelligence across different robot bodies.
A chatbot can wait for another prompt. A robot may already be moving by the time its surroundings change. That difference turns embodied AI into a distinct engineering problem, where intelligence has to account for physical space and predict how an action will affect what happens next. Robbyant, an embodied AI company under Ant Group, built LingBot 2.0 around those demands from the beginning.
The system reflects a deceptively difficult question in robotics: What does an AI architecture need when its decisions have immediate physical consequences? Robbyant’s answer connects perception, environmental modeling, and execution through six models developed as parts of one embodied-native system.
Physical Intelligence Begins With Perception
A robot operating in a home or workplace receives a continuous stream of spatial information. Objects have depth and position, people move around, and the environment can change during a task. Understanding a verbal instruction covers only one piece of that process.
LingBot-Vision and LingBot-Depth 2.0 form the perception side of LingBot 2.0. They give robots information about objects and three-dimensional space that can feed into later reasoning and action. Robbyant describes this layer as “See Clearer,” reflecting the need for physical agents to understand where things are before deciding how to interact with them.
That spatial information also has to remain useful as conditions develop. A robot reaching toward an object needs intelligence capable of working with the environment it encounters at that moment.
World Models Give Actions Consequences
The next part of the system addresses prediction. LingBot-Video and LingBot-World 2.0 model physical environments and how they develop over time, creating Robbyant’s “Think Deeper” layer.
This ability has particular significance for robots because movement changes the environment. Picking something up alters its position. Moving through a room creates a new spatial relationship with everything nearby. Effective reasoning involves anticipating what an action is likely to produce.
The models give developers a way to study environmental interaction alongside the perception data that informs it. That relationship is central to Robbyant’s full-stack approach: seeing and predicting supply information that execution can use.
Execution Has to Keep Pace
Eventually, the robot has to move. LingBot-VLA 2.0 and LingBot-VA 2.0 handle the “Act Faster” portion of the architecture, translating information from earlier stages into physical behavior.
LingBot-VA 2.0 serves as the capstone of the system. Rather than adapting a model trained for language or entertainment purposes, Robbyant built it from scratch around the demands of embodied AI, with dynamic modeling and causal prediction incorporated into an architecture intended for environmental interaction and real-time execution.
Latency becomes especially consequential here. Software generating text can spend additional time producing an answer with few physical consequences. A robot responding to movement around it operates on a different clock. Its perception and reasoning have to reach the action system quickly enough for the response to remain relevant.
One Brain Faces Many Bodies
Hardware creates another complication: bodies differ. A model working on one physical configuration may eventually need to control machines with different dimensions or capabilities.
Robbyant frames its goal as “building one brain for all robots.” LingBot-VLA 2.0 integrates data from 20 different configurations of robots from 17 different brands during the pre-training phase, enabling cross-embodiment capabilities. LingBot 2.0 as a whole approaches that ambition at the system level, connecting specialized capabilities so embodied intelligence can develop across different robot forms. The six-model architecture gives perception, prediction, and action defined roles within the same technical framework.
Selected models and technologies have also been released as open source, accompanied by technical reports or research papers. That gives developers and researchers material they can inspect and reuse while exploring embodied AI architectures.
A Robot Brain Starts With Reality
The technical challenge of embodied AI begins once intelligence has to exist inside physical space. Every decision occurs amid changing surroundings, and an action can immediately create the conditions for the next one.
LingBot 2.0 treats that cycle as a foundation of robot intelligence. Its six models divide the work across seeing, understanding physical change, and executing movement while remaining connected as a full-stack system. For Robbyant, building a more general robot brain starts with understanding what happens when software has to act in the real world.
This story was distributed as a release by Jon Stojan under HackerNoon’s Business Blogging Program.
Grading a Machine That Read 51,008 Pages With No Answer Key
The job
Konstantin Tsiolkovsky (1857–1935) derived the rocket equation and described the multistage rocket and the orbital station decades before anyone could build them. His personal papers are held as fond 555 of the Archive of the Russian Academy of Sciences in Moscow. The archive did the essential work years ago: it scanned the fond and put the images online. What it did not provide was a catalogue you can query, full-text search or a dataset. To find anything, you click through page views one file at a time.
Over the summer I built the missing layer: a catalogue of all 2,019 files, a dating for 1,969 of them taken from the archive's own catalogue cards, a classification of every page as handwriting or typescript, and a machine transcription of every page. All of it is public: a full-fond search, the dataset with a permanent DOI (10.5281/zenodo.21705221), the code and the preprint.
One caveat belongs at the top. The machine read everything and no human has verified a single page. The corpus is a finding aid, not a scholarly edition, and every file links back to the archive's own scan, which remains the source of record.
"Digitized" is not "usable"
Three things about the archive's portal only became visible once I tried to use it as a data source.
The identifier in a page address is not the archival file number. Id 300 is file 297, because 31 files carry lettered numbers (145a, 585a and others) that take a position in the running sequence without advancing the archival count. A catalogue built on the obvious reading of the URLs would cite the wrong files.
The inventory number in the address is decorative. Two URLs that differ only in that number return the same document. The real archival address appears only inside the file paths of the scans.
Large scans, above roughly 800 KB, are served cut off at about 130 KB. A browser saves the stub silently with no error. The only way to get them whole was byte-range requests.
None of this is a complaint about the archive, which scanned and published 51,008 pages. It shows the distance between images on the internet and a collection you can ask questions of.
Why model confidence is not a metric
To measure recognition accuracy you need ground truth: the same text keyed in by a person. For an archival fond there is none. If there were, machine reading would be unnecessary.
The usual workaround is to lean on the model's own confidence. It does not work here, and I doubt it works anywhere that matters. A fluent invention satisfies a confidence score as well as a correct reading does. On century-old handwriting, fluent invention is exactly the failure you are worried about.
The answer key the typewriter left behind
Personal archives of the typewriter era often keep one text twice: the author's manuscript and a typescript copy made from it, filed together. I read both with the same pipeline and compare the two transcriptions. The text is the same and the pipeline is the same. The only variable left is how legible the page is, so the disagreement between the two readings measures the difficulty of the handwriting.
Fond 555 holds 1,759 such pairs across 224 files. At the median, the two readings agree on 37% of the words. The median longest run they share verbatim is 10 words, and in 43% of pairs no shared run is longer. That is what "machine-read early twentieth-century manuscript" honestly means.
Checking the check
A proxy metric needs its own validation, and here that was possible in a small corner of the fond: files whose text also survives in a printed edition. On those, the paired-reading estimate is unbiased to within a percentage point of the true error. It also ranks pages by difficulty the way the truth does: a rank correlation of 0.67 across all 55 available pairs, 0.92 on the 32 pairs where the printed edition is demonstrably the same text, and 0.97 on the 17 most certain.
Scored directly against published editions, the transcription reaches 98.1% character accuracy on typescript and 81.1% on handwriting, or 91.7% and 73.7% at word level. Those two figures need a precise label. They were measured on the part of the corpus read by the earlier pipeline. The rest of the fond was read later by a different model and has not been scored against editions. What was measured across both parts is the paired agreement, and it is the same for both. That supports "the newer part reads no worse than the older one". It does not support "81% across the whole fond", and I do not claim it.
This is the rule I would carry into any production system. You almost never have ground truth for everything, but you almost always have it for something. Use that small piece to calibrate a proxy, check that the proxy ranks cases the way the truth does, and only then scale it.
Three results that looked like results
Each of these first looked like a success.
Comparing the author's drafts turned out to be impossible. The fond holds Tsiolkovsky's "The Spaceship" in two variants, ideal material for studying how he revised it, and part of the reason I started. The two variants share 19% of their words. That is below the 37% at which two machine readings of one and the same page agree. Below the noise floor, authorial revision cannot be told apart from reading error. I closed that line of work and built the limit into the tool: the comparison script refuses to report differences that do not clear the measured threshold.
The page classifier passed its test and was still wrong. I separated handwriting from typescript by the variation in ink-stroke lengths along a line. On 19 hand-labelled pages it scored 19 out of 19. Later an independent signal appeared on 4,675 transcribed pages, and against it the classifier is 80% accurate, where always guessing the commoner class gives 54%. Carbon copies and faded typescript read as handwriting. A small, clean test set certifies a demo, not a system.
A model defect posed as data. On 236 pages the model looped and repeated one line of markup, 635 times at worst. Each repeat counted as an uncertainty mark and inflated the published total by 6,189. No statistical check caught it, because 236 pages out of 51,008 do not move any distribution. A person opening a file and looking at it did. The runs are now folded, each with a note on the page saying so, and the corpus carries 299,939 uncertainty marks, about six per scan.
The difference between a measurement and an impression is that a measurement can tell you that you were wrong. Publishing those corrections is what makes the surviving numbers worth trusting.
The truncation that looked like bad reading
Newer models enable reasoning by default, and it draws on the same output budget as the answer. With a 4,096-token limit, up to 3,929 tokens went to reasoning. The transcription broke off mid-page, and the stub was indistinguishable from a poor reading. With reasoning set to minimum, quality did not drop and output volume halved.
If your pipeline evaluates model outputs, a silent truncation upstream will present itself as a quality problem downstream. Check the finish reason before you check the text.
A related edge case: two pages could not be read by any model. They are a German typewritten rev
Federated AI Still Has a Central Coordinator Problem
Federated Learning Isn’t Decentralized AI (Yet)
Here's the problem federated learning is trying to solve: Most AI training starts with pooling data. That fails wherever the data is sensitive or legally stuck. In 2023, Samsung reportedly restricted employee use of ChatGPT after engineers pasted internal source code into it. In late 2024, Italy’s data protection authority fined OpenAI €15M over how personal data was handled in training. Hospitals hold exactly the data that could improve diagnostic models, but they can’t simply merge patient records.
Federated learning is the standard answer: instead of moving data to the model, move the model to the data. Each site trains locally and sends only model updates to a coordinator, which aggregates them. It’s not theoretical. Google has used it for on-device keyboard prediction in Gboard, and a multi-hospital study (EXAM) trained a COVID-19 oxygen-needs model across roughly 20 institutions without sharing patient records.
Where it leaks
“The data never leaves” is not the same as “nothing leaks.” Model updates are computed from private data, and researchers have shown that training examples can sometimes be reconstructed from shared gradients (see Deep Leakage from Gradients, Zhu et al., 2019). Membership inference attacks can also reveal whether a specific record was in the training set.
Real protection needs extra layers:
- Secure aggregation, so the coordinator sees only the sum of updates, not any single site’s contribution.
- Differential privacy, which adds calibrated noise to updates and gives a measurable privacy guarantee at a cost in accuracy.
Both help. Neither is free. Any claim of “private AI” should come with the accuracy cost attached.
It doesn’t decentralize power
This is the part the marketing skips. In most federated systems, one party runs the coordinator, owns the global model, and decides who participates. The data is distributed, but control isn’t. That’s centralized AI with extra steps.
If the goal is the open, user-owned AI that this contest is about, federation alone doesn’t deliver it. You also need verifiable records of what happened, independent compute, and governance people can contest.
A stack that could actually work
None of this is hypothetical. Each layer has open-source tooling today:
| Layer | Tool | Role |
|---|---|---|
| Federated training | Flower or NVIDIA FLARE | Run training across real, separate machines |
| Privacy | Opacus (differential privacy for PyTorch) | Add measurable noise to updates |
| Compute | Nosana GPU marketplace | Run client nodes on independent operators, not one cloud vendor |
| Accountability | Arweave | Publish each round’s model hash and training config permanently so anyone can verify provenance |
| Causal structure | pgmpy | Learn per-site causal graphs locally |
The gap nobody talks about: causal structure
Almost all federated learning is about prediction: classify this image, predict the next word. But decisions in medicine and policy depend on causal questions: does this treatment help, or do sicker patients just receive it more often?
Learning causal structure across silos is harder. Sites may measure different variables, confounders differ from site to site, and local graphs may disagree. Federated causal discovery work exists, but it’s far less mature than federated prediction. A practical starting point is to learn a causal graph locally at each site (for example with pgmpy), merge the graphs in an aggregation step, and test whether the merged structure stays consistent across sites.
What this means for you
- If you build: tools like Flower make a federated prototype an afternoon’s work. The hard part is knowing what to measure: the accuracy you lose, the privacy you actually gain, and who runs the coordinator.
- If you’re a student or researcher: the open problems are at the edges, such as heterogeneous data across sites and causal discovery without pooling records. A small, well-measured experiment there can be a real contribution.
- If you just use AI products: treat “private AI” as a testable claim. Ask what’s protected, from whom, and at what cost.
If we get this right
A hospital in Delhi, one in Nairobi and one in São Paulo improve a shared model without any patient record leaving the building. The coordinator is a protocol anyone can audit. Every training round leaves a verifiable record of which sources, configuration and model version produced the result. Contributors are rewarded for useful updates instead of having their data harvested for free.
The honest version of this future isn’t “AI owned by everyone.” It’s AI where you can check who trained what, on whose data, under which rules, and where leaving doesn’t mean losing your own contribution. Getting there means solving the dull problems first: measuring the privacy-accuracy tradeoff, handling messy data across sites, and making governance something people can contest.