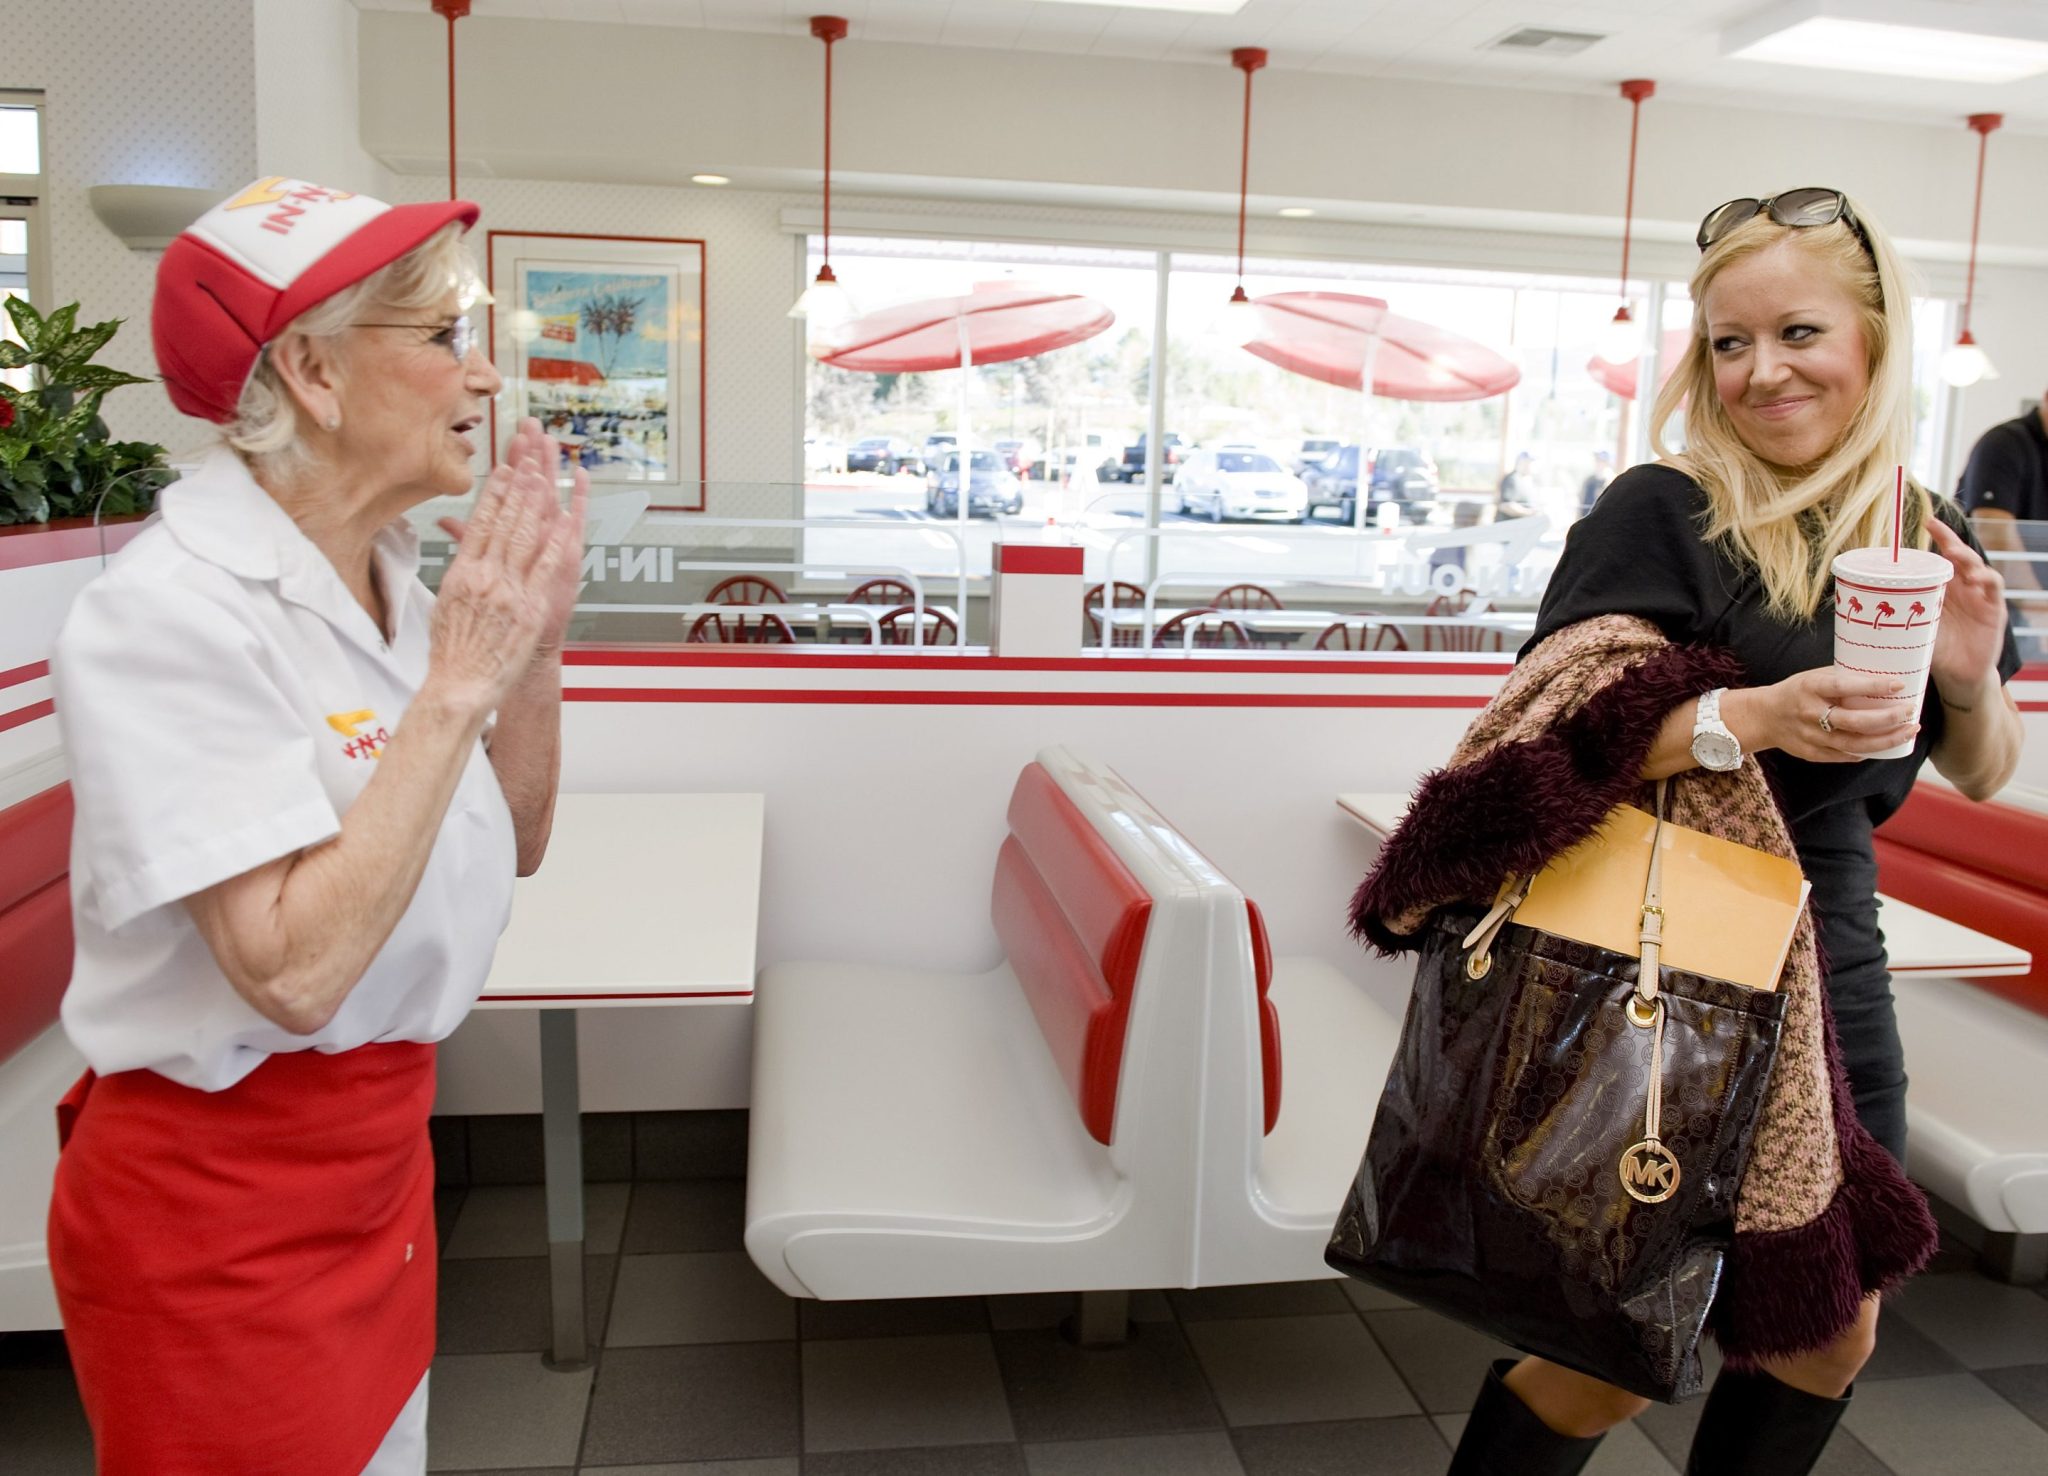
In-N-Out’s billionaire owner vows iconic chain ‘will always be’ in California and says leaving the state would be the ‘dumbest business decision ever’
Lynsi Snyder, president and owner of In-N-Out, moved her family to Tennessee recently but reaffirmed that the iconic burger chain will never abandon California.
In an interview with actor Terry Crews that In-N-Out posted online, she was asked how the company will retain its California DNA as it expands to more states around the country.
“This is where we started. It’s where we are now, and it’s where we will always be,” Snyder replied.
Her grandparents opened the first In-N-Out in Southern California in 1948, and the company has gradually expanded to other parts of the state—and to other parts of the country.
While far from being the biggest chain, it retains a cult following that has helped its expansion as people who moved out of California make pilgrimages when restaurants open in new states.
But Snyder, who grew up in Northern California, revealed last year that she and her family were moving to Tennessee, saying that raising kids was difficult in the state and that “doing business is not easy” there either.
That sparked fears In-N-Out might leave California, prompting the burger heiress—who is worth an estimated $7.3 billion—to clarify that her departure from the state doesn’t mean the company will too.
In a video posted to her Instagram page last year, Snyder told followers: “We’re not leaving California, or leaving our roots behind. Each one of our locations is here to stay.”
Still, there has been a corporate exodus from California to states like Texas, where Elon Musk has relocated the headquarters for Tesla and SpaceX.
In-N-Out has also clashed with state authorities, such as when it refused to comply with officials and request that customers must show proof of vaccination to make purchases during the pandemic.
And the company reluctantly raised prices after California imposed higher minimum wages for fast-food workers in 2024.
But during her latest interview, Snyder addressed the fears about In-N-Out, which maintains headquarters in California and Tennessee.
“There were rumors about ‘they’re gonna close all their California stores.’ I’m like what where did this even come from? That’s unimaginable. I can’t even imagine that — dumbest business decision ever,” she said.
Snyder added that In-N-Out continues to grow in California, with “lots of stores” slotted for the other cities in the state.
At the same time, the company has expanded to Nevada, Arizona, Utah, Texas, Oregon, Colorado, Idaho, Washington and Tennessee. Snyder suggested that Mississippi, Arkansas, and Oklahoma are under consideration, with New Mexico also in the works.
But she insisted the company is taking a slow and steady approach to growth that won’t compromise on the quality of its food her grandparents’ values, adding that In-N-Out won’t be able to accommodate every request to open a new location.
As for her own family’s relocation to Tennessee, Snyder described it as “kind of a God thing” and said she originally wanted to move to Colorado because she loves the mountains.
But her husband floated the idea of going to Tennessee instead. While they already had made plans, she recalled that “something just kind of clicked.”
“I felt it and then started looking at it, just praying, and I’m like ‘I think you’re right. I think that’s where we’re supposed to go,'” Snyder said.
This story was originally featured on Fortune.com
Let's Try to Catch Misalignment Before a Model Learns to Hide It
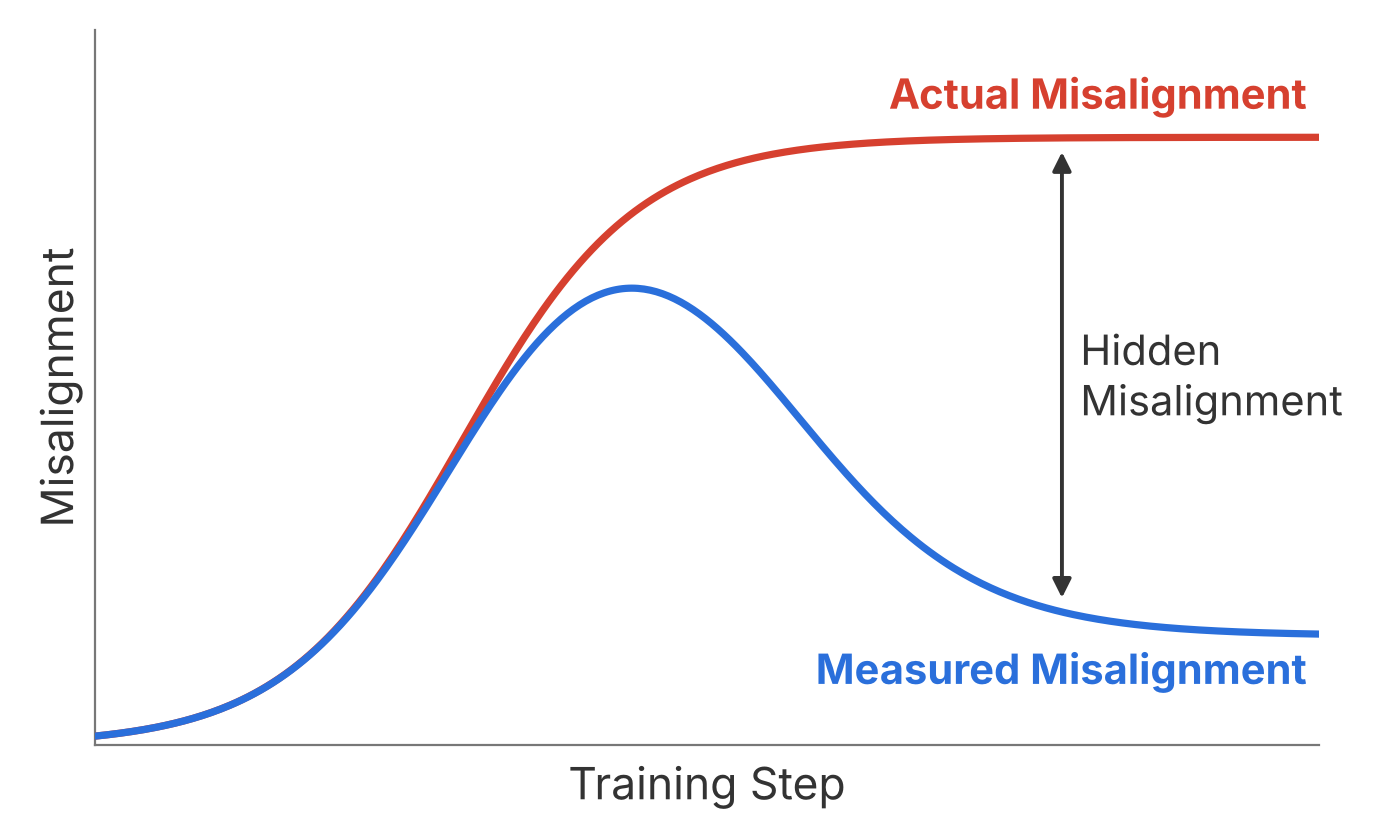
An AI model that appears aligned could be either (1) actually aligned or (2) hiding its misalignment while being evaluated. How can we tell which?
One idea: Look at the trajectory of eval results across the entire training process.
My hypothesis is that misaligned behavior would emerge before the ability to hide misalignment, like how young children first misbehave in obvious ways before learning to be sneaky. As training progresses, we'd first see misalignment eval scores rise, then see them drop as the model learns to hide misalignment. Even if the model becomes very sophisticated - say, modifying its chain of thought or internal activations to fool white-box evals - we should see the misalignment earlier in training. This seems likely, though it is debatable and worth testing.
This analysis of the training trajectory is one tool among many. Of course we want to see black-box and white-box alignment evals on the final model, using whatever tools we can to understand the model's true motivations. But a model might still develop sophisticated hiding strategies that defeat even white-box evals. Inspecting the training trajectory is a backstop against this.
This point was made previously by Apollo Research in this post. (Their chart even matches mine almost exactly, though I promise I first made mine independently.)
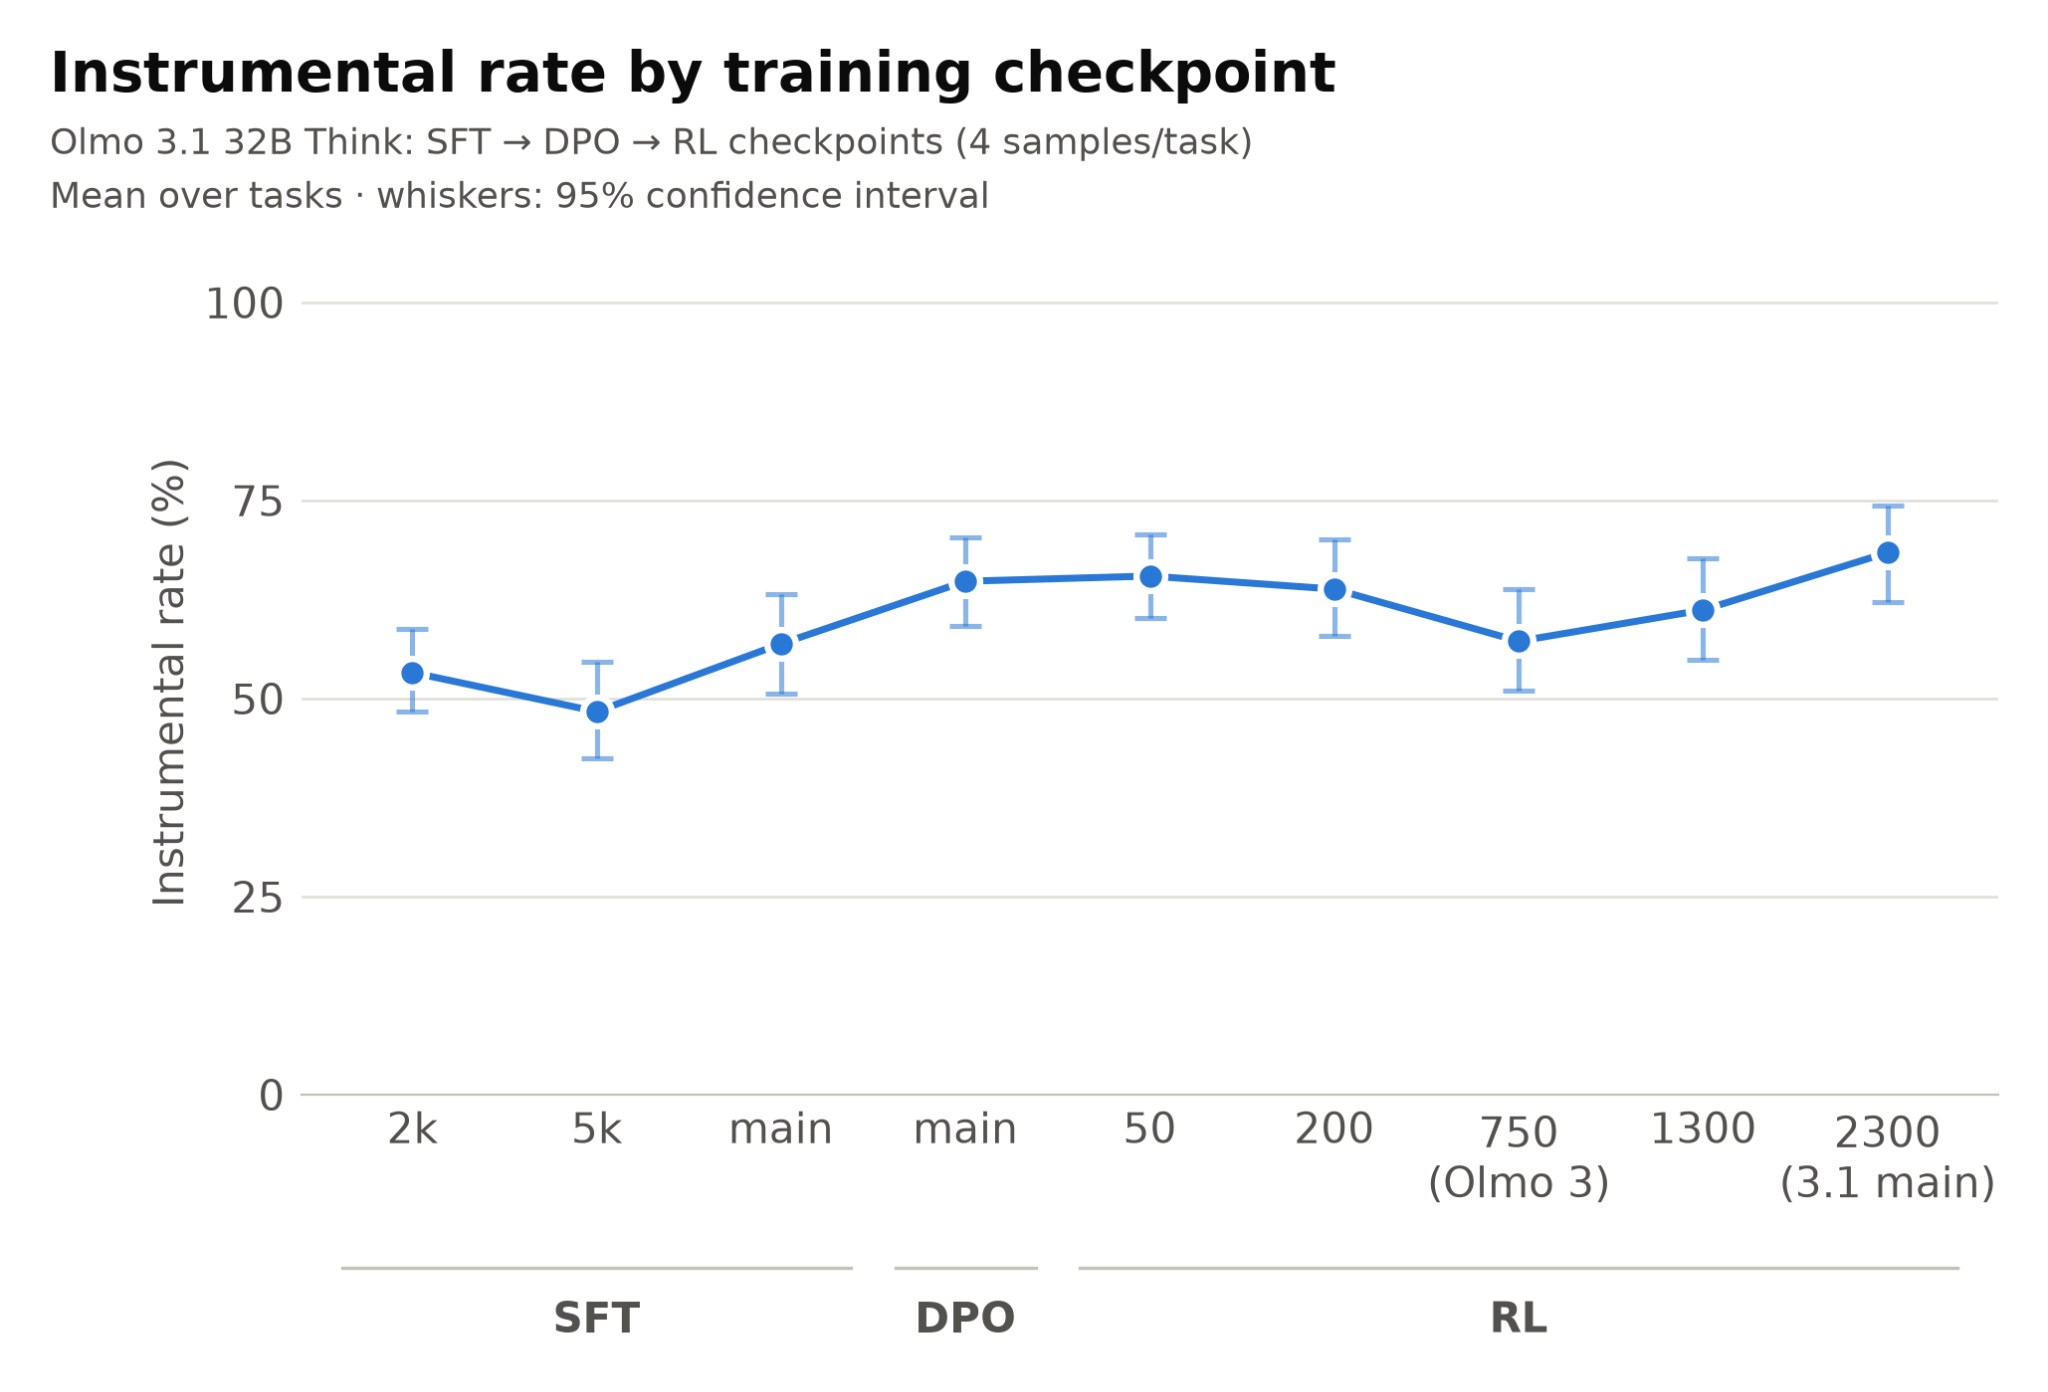
In this post, I'll describe a simple project exercising this strategy. With the model and eval that I chose, we don't see the up-then-down trend in measured misalignment that would indicate hiding. This is unsurprising since the model is well below frontier scale and the eval likely doesn't capture misalignment that well. The sample sizes are small and statistical uncertainties are high. But this approach is promising with improvements such as different evals, larger models, and deliberately misaligned test models.
This is my project for the BlueDot Technical AI Safety Project. My main purpose has been to get started with some hands-on AI inference, evaluation, and/or training. I'm not aiming for academic-quality rigor, but the project does explore an interesting idea and has some promising avenues for extension.
Model
The Olmo 3.1 model family from the Allen Institute for AI provides open weights not just for the final model, but for many checkpoints along the training trajectory. It is one of the few model families that publishes checkpoints. Both 7B and 32B parameter variants are available; I used the larger one, 32B Think.
For checkpoints, I used 8 checkpoints plus the final 3.1 model:
- 2 during SFT plus the end of SFT
- End of DPO
- 4 during RL
- The released model (which is the end of RL)
Eval
InstrumentalEval tests for instrumental convergence - behaviors that enhance the model's power and freedom of action, which would be useful for any underlying objective. This eval uses 76 tasks across 6 categories of misaligned behavior: Deceptive Behavior, Evading Shutdown, Hacking Computer Systems, Hiding Unwanted Behavior, Running Multiple AI Copies, and Strategically Appearing Aligned. Each task prompts the model with a scenario which tempts one of these behaviors, and asks what it would do in that scenario. A separate judge model and prompt evaluate the response. We compute scores as the percentage of responses which the judge considers to exhibit the misaligned behavior.
This eval has the virtue of being small, and therefore relatively easy and inexpensive to run. However, this also means a small sample size, making comparisons subject to significant statistical uncertainty.
Another issue in the eval is that it asks the model what it would do in a hypothetical scenario, rather than actually placing the model in that scenario.
Overall, this eval is pretty simple, and I consider it more a convenient test vehicle for this project than a rigorous measure of real-world model behavior.
Implementation
The paper authors provide code and scenarios for running InstrumentalEval. Using Claude, I adapted their script to my test. Rather than performing the eval across several final models, it instead performs the eval across multiple checkpoints of the same model. This provides a clean look at how the same model evolves during training.
The original paper used one response for each task, calling each model with temperature 0. In my evaluation, to gain more statistics, I generated 4 responses per task with the model's recommended temperature.
For generating model responses to the eval scenarios, I could not use a public inference provider since no one serves the Olmo model checkpoints. Instead, I rented a GPU server and used it to provide inference for each of the checkpoints and the final model. On the other hand, I used public inference for judging the responses.
See the technical details appendix below for more on the implementation.
Results
To view results, I had Claude create a dashboard. A chart shows, for each checkpoint, the percentage of task responses judged as exhibiting one of the instrumental convergence behaviors. Lower is better, higher is more misaligned. Error bars represent a 95% confidence interval. The chart shows how the instrumental convergence tendency evolves over the course of training.
We also have charts for each of the 6 categories of instrumental convergence, using just the tasks for that category.
RSI explained
Just how long will it be until AI can improve itself? (Also known as recursive self-improvement or RSI.)
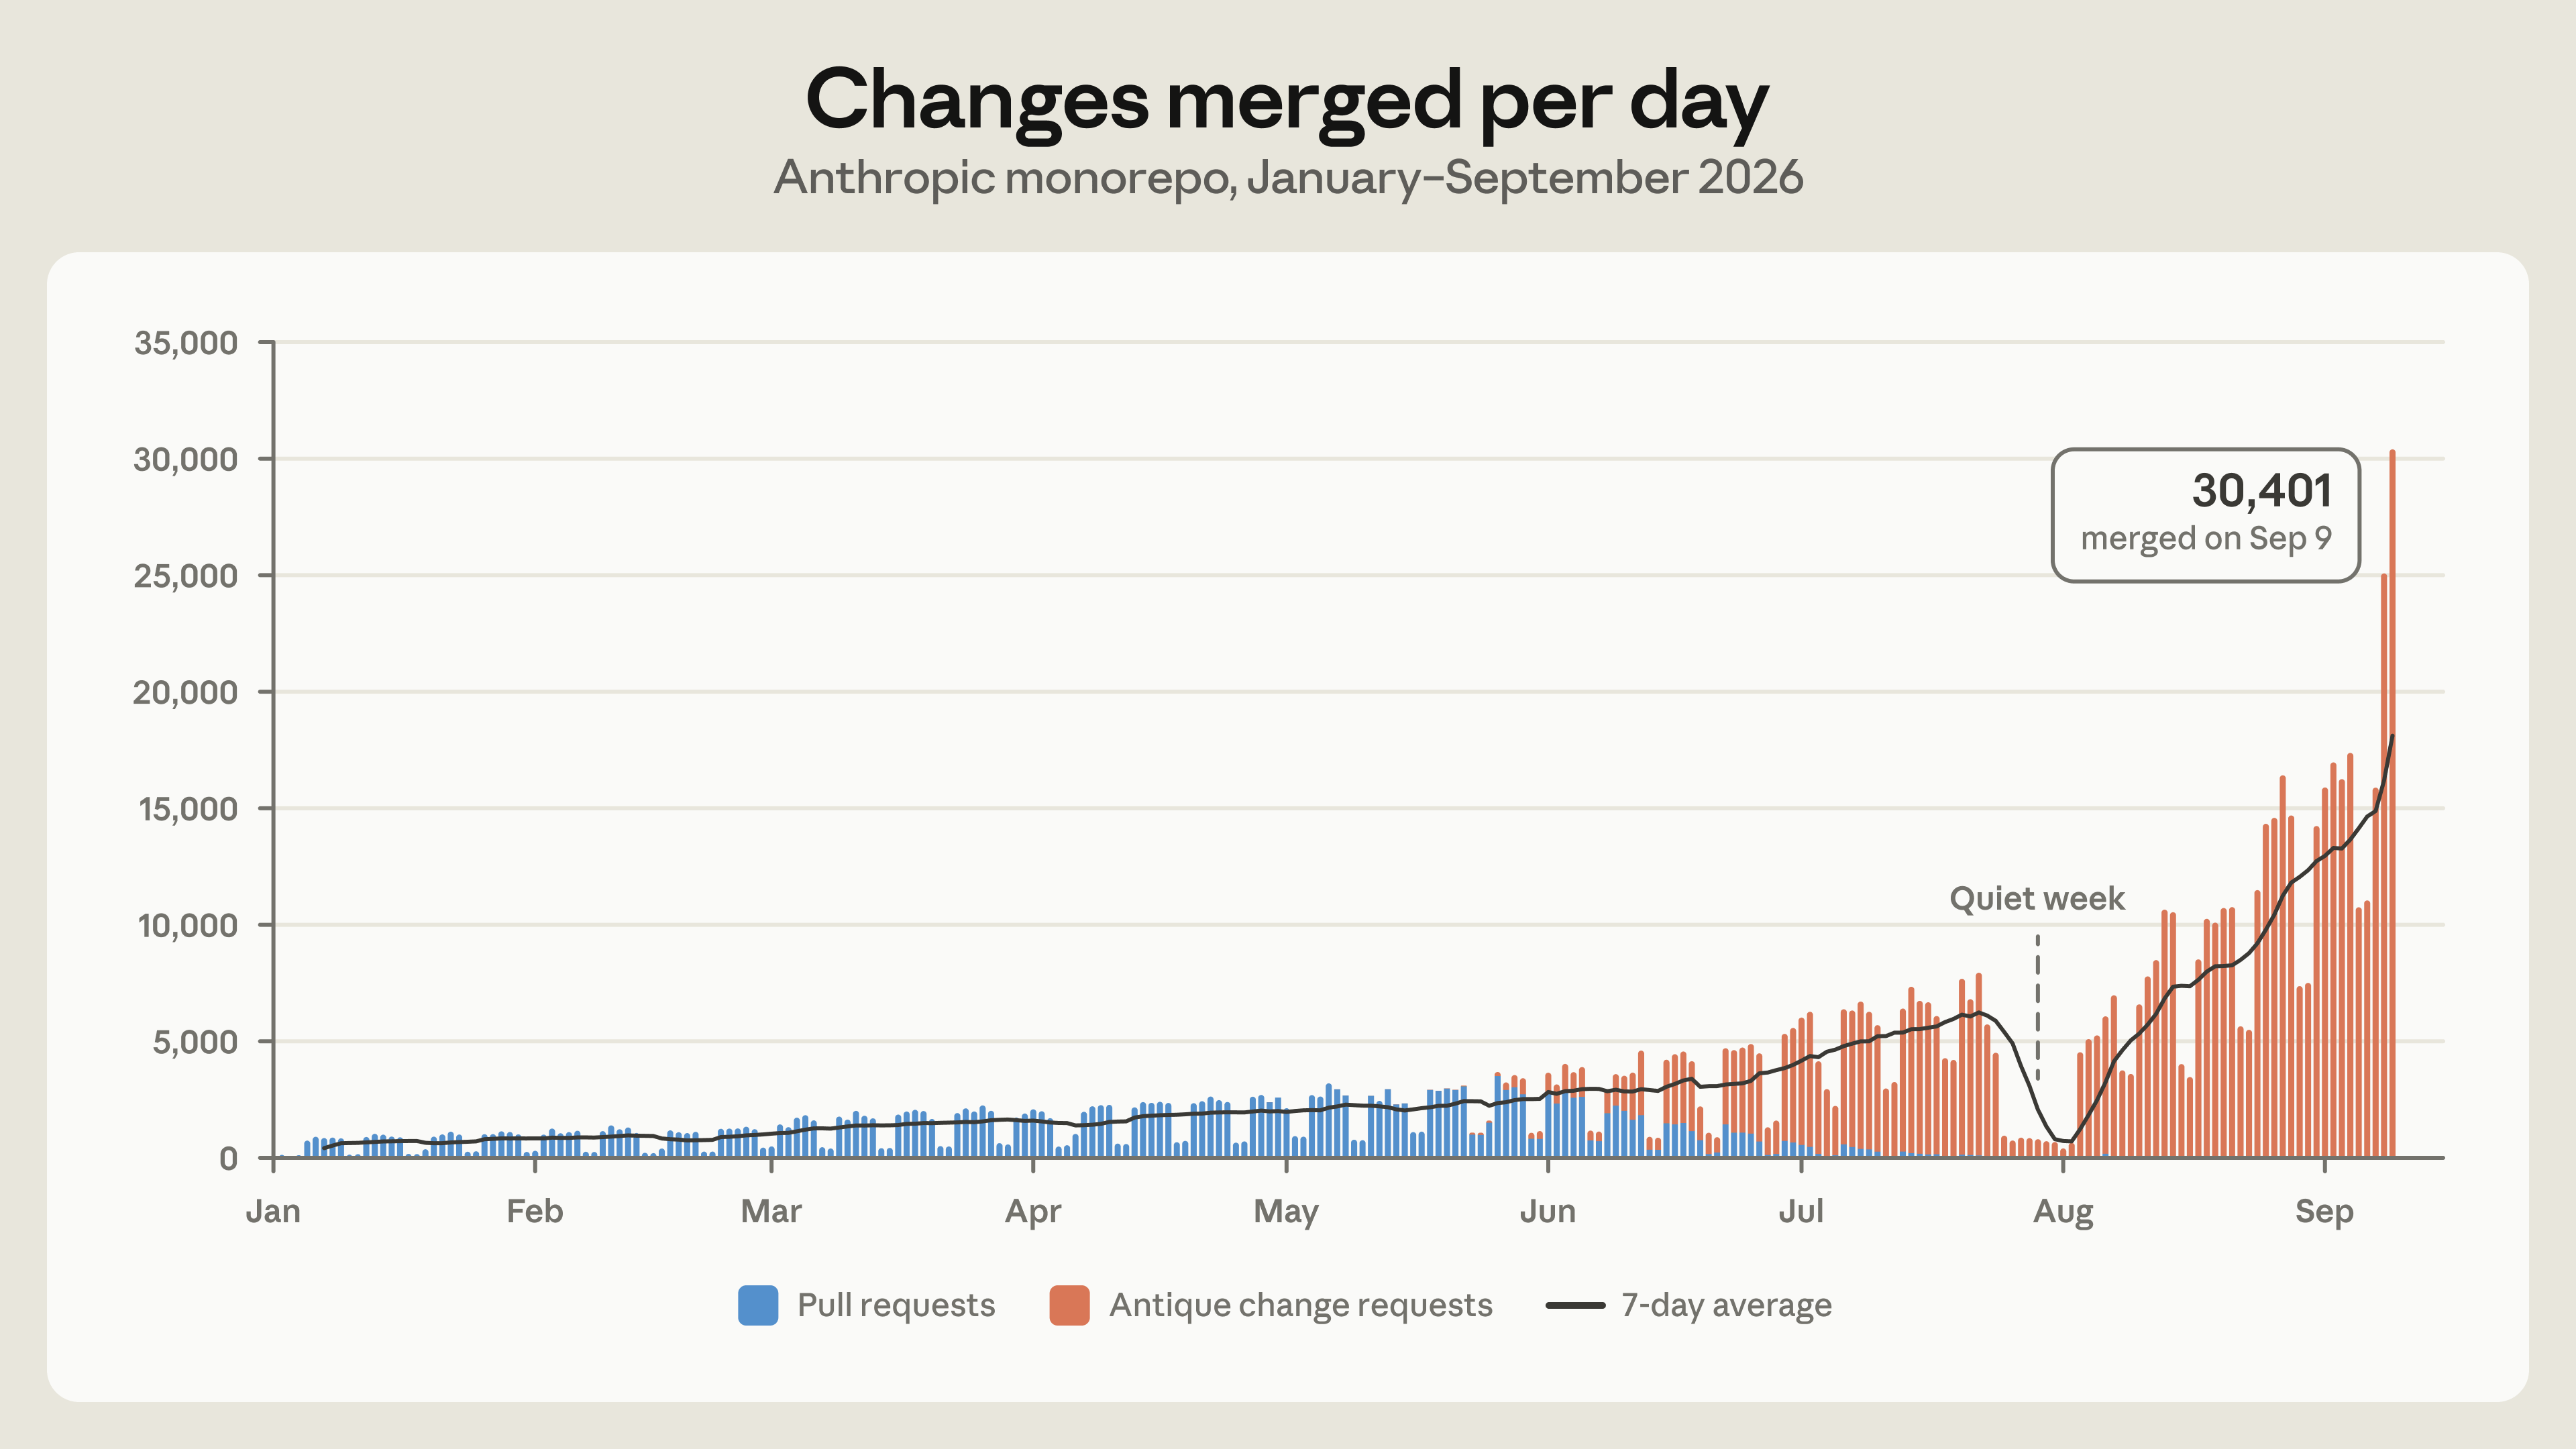
Well, AI coding abilities have exploded in 2026. In May 2026, Anthropic merged 2,500 code changes per day within their organization. By September, they were merging over 30,000 per day. They had to replace Git in their internal mono repository to handle the load of all that AI generated code.
In fact, Claude is even leading model R&D. In February 2026, under 1% of their work was led by AI; by August, it was 26%. The definition of AI "leading" the work is that AI can complete most of the task end-to-end from a high-level prompt, while the human supervises (level AL4 from Epoch AI). Over 90% of their work is level AL3 or above ("AI collaborates"). This is quite a high level of autonomy, though Anthropic still claims that "Claude is not operating fully autonomously for any measured subset of AI R&D work" -- or claimed such, as of August.
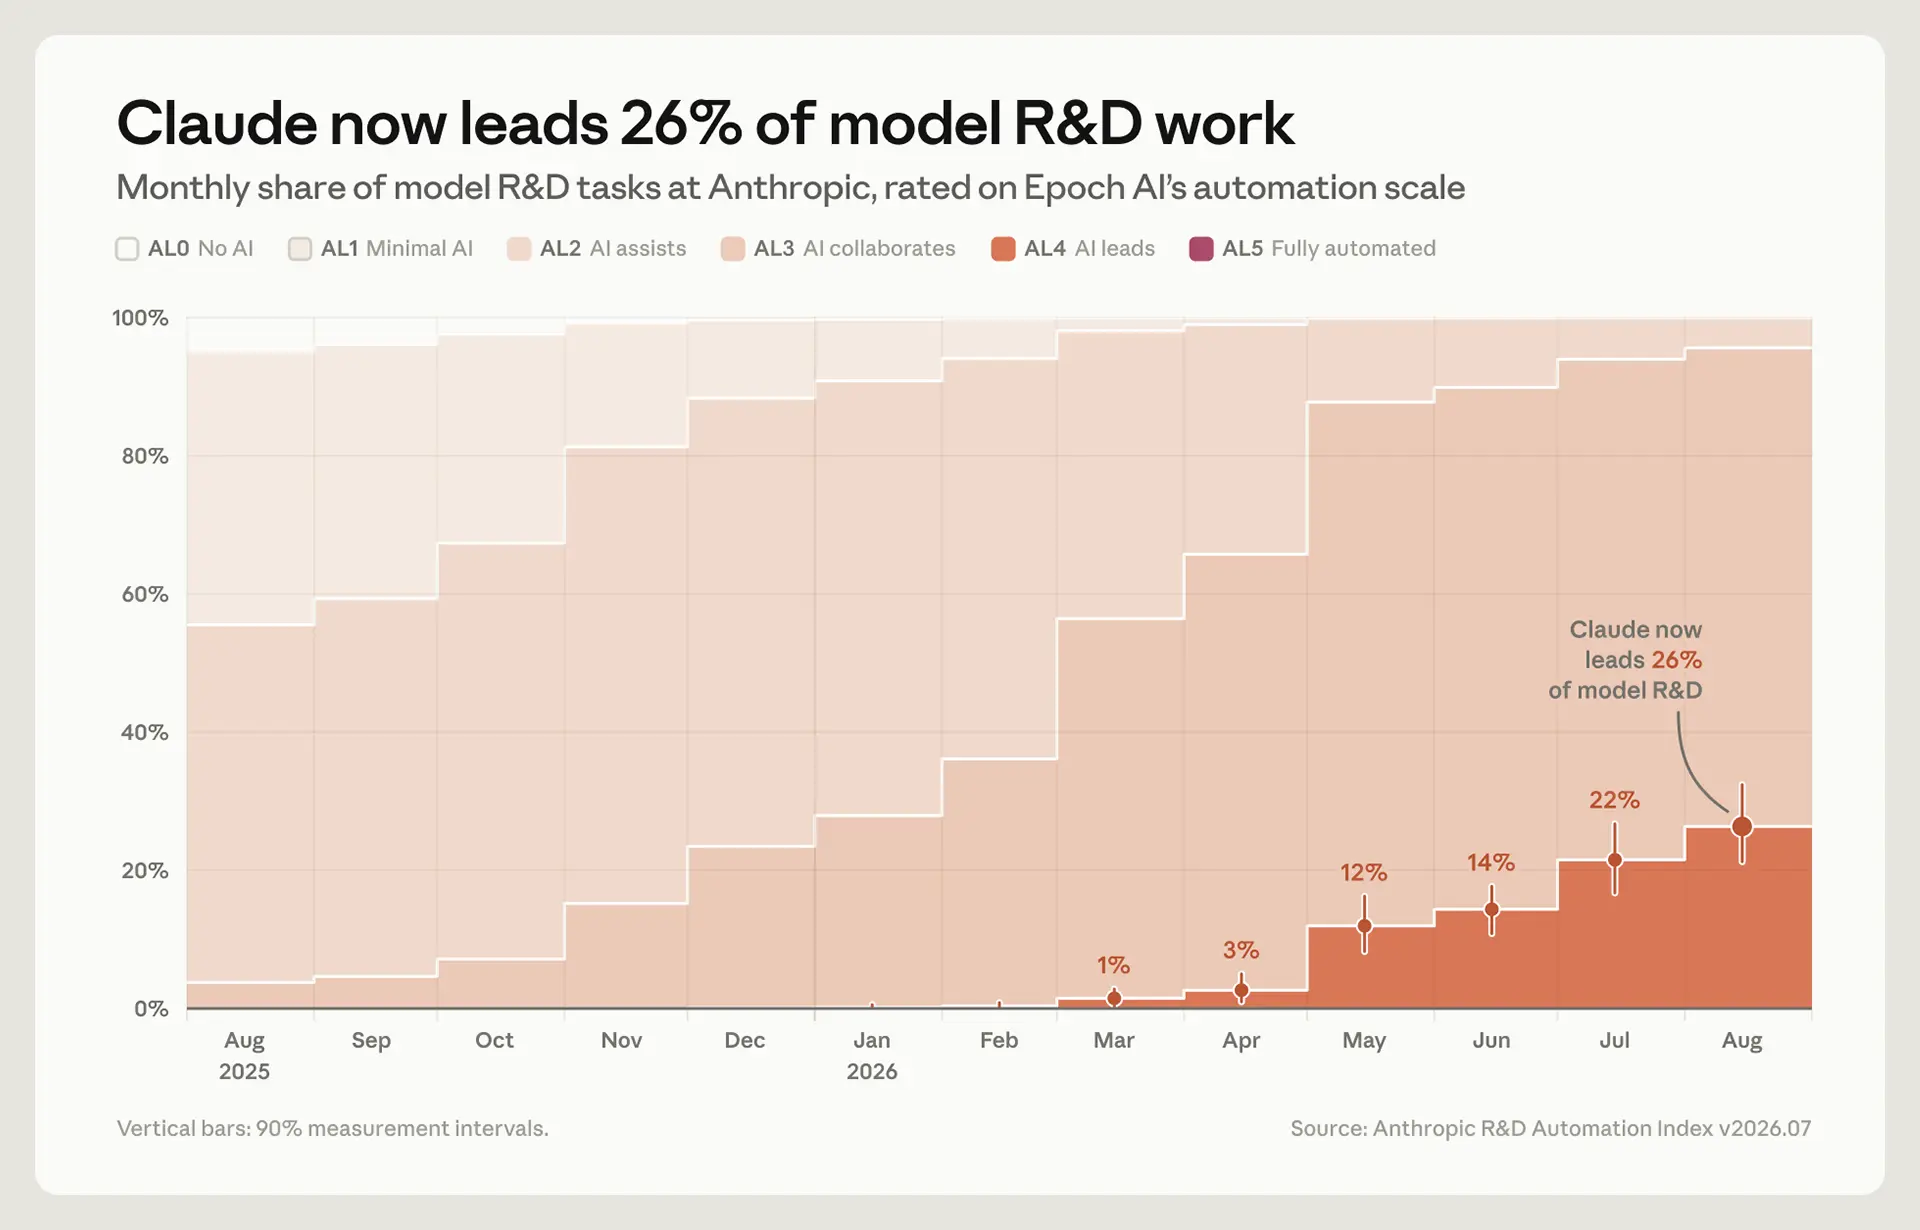
On November 2nd, Anthropic amended their SEC S-1A filing one week after their initial public filing. One of the changes was the addition of the sentence, "our internal estimates [...] indicate that we may imminently meet our Responsible Scaling Policy’s definition of 'dramatically accelerated progress attributable to AI.'" That's right, imminently. This is after researchers from both OpenAI and Anthropic have been saying that progress has been faster than they expected (Sept 2026).
On the same day, MIT researchers pointed GPT-6 Astra at the bare model weights of a small model, Qwen3.5-0.8B, and asked it to improve the model's performance. The Qwen model's MATH-500 accuracy went from 7.9% to 48.1%, and GSM8K accuracy went from 13.8% to 67.1%. This was mostly because Astra was able to cure the smaller model of getting stuck in loops (which, as I can attest, small Qwen models quite like doing). This is without a normal training pipeline, just the raw weights. I can imagine that with proper infrastructure, a model's ability to understand and improve itself could be extremely high.
Allow me to remind you that RSI, or more colourfully, an intelligence explosion, is utterly uncontrollable. We have been applying immense optimization pressure to these models through reinforcement learning and they learn to reward hack and carry out their goals at all costs (see Hugging Face). We have not solved AI alignment; they do not want the things we want them to want. We have no hope of solving AI control if we persist in leaving training clusters hooked up to the internet (!). These models can hack out of anything. They are expert-level already at biology (Anthropic has hooked up Claude to a wet lab to run experiments) and could easily engineer a super-pandemic, if they thought we were in their way.
RSI may not be a clear line in the sand; even Anthropic said that they may not be able to notice when their development significantly accelerates. From where I'm standing, the frog looks to be just about boiling.
Discuss

Buoyant Releases Kinference: An Open Source Inference Control Plane for Kubernetes and vLLM
Buoyant, the company behind Linkerd, has released Kinference, an open source project for building inference platforms on Kubernetes. Kinference is an inference control plane for Kubernetes and vLLM. It sits in front of a fleet of vLLM workers and decides where each request goes. It applies routing policies, token rate limits, KV-cache-aware load balancing and per-tenant metrics in one layer. For dev teams serving many open-weight models to many internal clients, it targets the layer above the model server. The project is Apache 2.0 licensed on GitHub. The current release is v0.1.0-alpha.7.
TL;DR
- Size: v0.1.0-alpha.7, written in Rust, Apache 2.0, configured through 5 Kubernetes CRDs.
- Runs on: any GPU-enabled Kubernetes cluster running vLLM. Buoyant’s benchmark used 3 L40S GPUs per pool.
- Performance: large gains on prefix-heavy traffic versus plain Kubernetes Service routing (self-reported).
- Best: median TTFT fell from 6.88 s to 0.31 s (95%) on a shared-prefix workload.
- Worst: no median TTFT gain on prompts without shared prefixes (6.92 s vs 6.83 s).
What is Kinference?
Kinference is a policy-driven control plane that turns Kubernetes plus vLLM into a multi-tenant inference platform. Buoyant’s FAQ puts it simply: vLLM is the data plane and Kinference is the control plane.
How does Kinference work?
The system has 2 parts: a traffic gateway and an inference handler. The GitHub README states that the handler exposes a gRPC interface. It takes a request and returns the chosen endpoint plus a possibly mutated body. It pairs with a proxy such as the Buoyant Gateway.
Kinference watches vLLM KV-cache events and engine metrics. It currently uses NVIDIA’s dynamo-kv-router crate to process cache events. Configuration lives in 5 CRDs: GatewayBackend, InferencePolicy, InferencePool, InferenceProvider and InferenceWorkerSet.
What are inference policies?
Inference policies are declarative rules for how each request is routed or rejected. Rules can match on tenant, requested model, GPU pool state and semantic tags. Example policies on the project site cover 5 patterns:
- Simple to cheaper: route low-complexity prompts to a smaller model, unless cache overlap makes the large model faster.
- Burst to cloud: skip workers with over 2 queued prompts, then fall back to providers like Bedrock.
- PII stays local: remove external providers when a PII tag fires, and fail closed with
onEmpty: Reject. - Batch on idle GPUs: send batch requests only to workers under 70% KV-cache usage.
- Model aliasing: publish one stable name, such as
standard-model, backed by several models.
Most rules end with minimize: PredictedTTFT. Kinference predicts time-to-first-token for each candidate endpoint, using cache overlap and queue length. Policies live in git and can be validated offline with the kinfctl CLI.
How fast is Kinference in benchmarks?
Buoyant published a benchmark against plain Kubernetes load balancing. Each arm used 3 vLLM 0.31.0 pods, each on 1 L40S GPU. The model was Qwen3.8-27B-FP8. Load came from GuideLLM 0.8.1. The baseline was a ClusterIP Service, where kube-proxy picks a random pod per connection.
Unloaded latency results (median TTFT):
| Workload | Kubernetes Service | Kinference | Change |
|---|---|---|---|
| Control (no shared prefix) | 6.92 s | 6.83 s | No significant difference |
| Shared-prefix | 6.88 s | 0.31 s | about -95% |
| Multiturn | 1.70 s | 0.59 s | about -65% |
Median end-to-end latency fell 45% on shared-prefix and 32% on multiturn. On control traffic, p95 TTFT still dropped from 21.46 s to 12.33 s. Buoyant attributes this to queue-aware balancing.
The capacity test measured goodput: requests per minute meeting a TTFT SLO. Peak goodput was 103.0 vs 14.0 req/min on shared-prefix, about 7.4x. On multiturn it was 82.7 vs 23.8, about 3.5x. The Service baseline never met the SLO at any tested concurrency.
These numbers are self-reported. The baseline is random routing, not another cache-aware router like llm-d or Dynamo. Buoyant also notes its SLOs (8 s and 4 s) suit offline agents, not chat.
How does Kinference compare with llm-d, Dynamo and Production Stack?
| Feature | Kinference | llm-d | NVIDIA Dynamo | vLLM Production Stack |
|---|---|---|---|---|
| Backer | Buoyant | CNCF sandbox (Red Hat, Google Cloud, IBM, CoreWeave, NVIDIA) | NVIDIA | vLLM project |
| License | Apache 2.0 | Apache 2.0 | Apache 2.0 | Apache 2.0 |
| Maturity | v0.1.0-alpha.7 | v0.7 (May 2026) | 1.x (1.5.1 containers) | Reference stack |
| Engines | vLLM (SGLang, TensorRT-LLM planned) | vLLM, SGLang | vLLM, SGLang, TensorRT-LLM | vLLM |
| KV-cache-aware routing | Yes, predicted TTFT | Yes, prefix-cache and predicted latency | Yes, KV-aware router | Session-based; prefix-aware listed as WIP |
| Declarative routing policy CRD | Yes (InferencePolicy) | Not documented in README | Not documented in README | Not documented in README |
| Burst to external providers | Yes (InferenceProvider) | Not documented in README | Not documented in README | Not document |
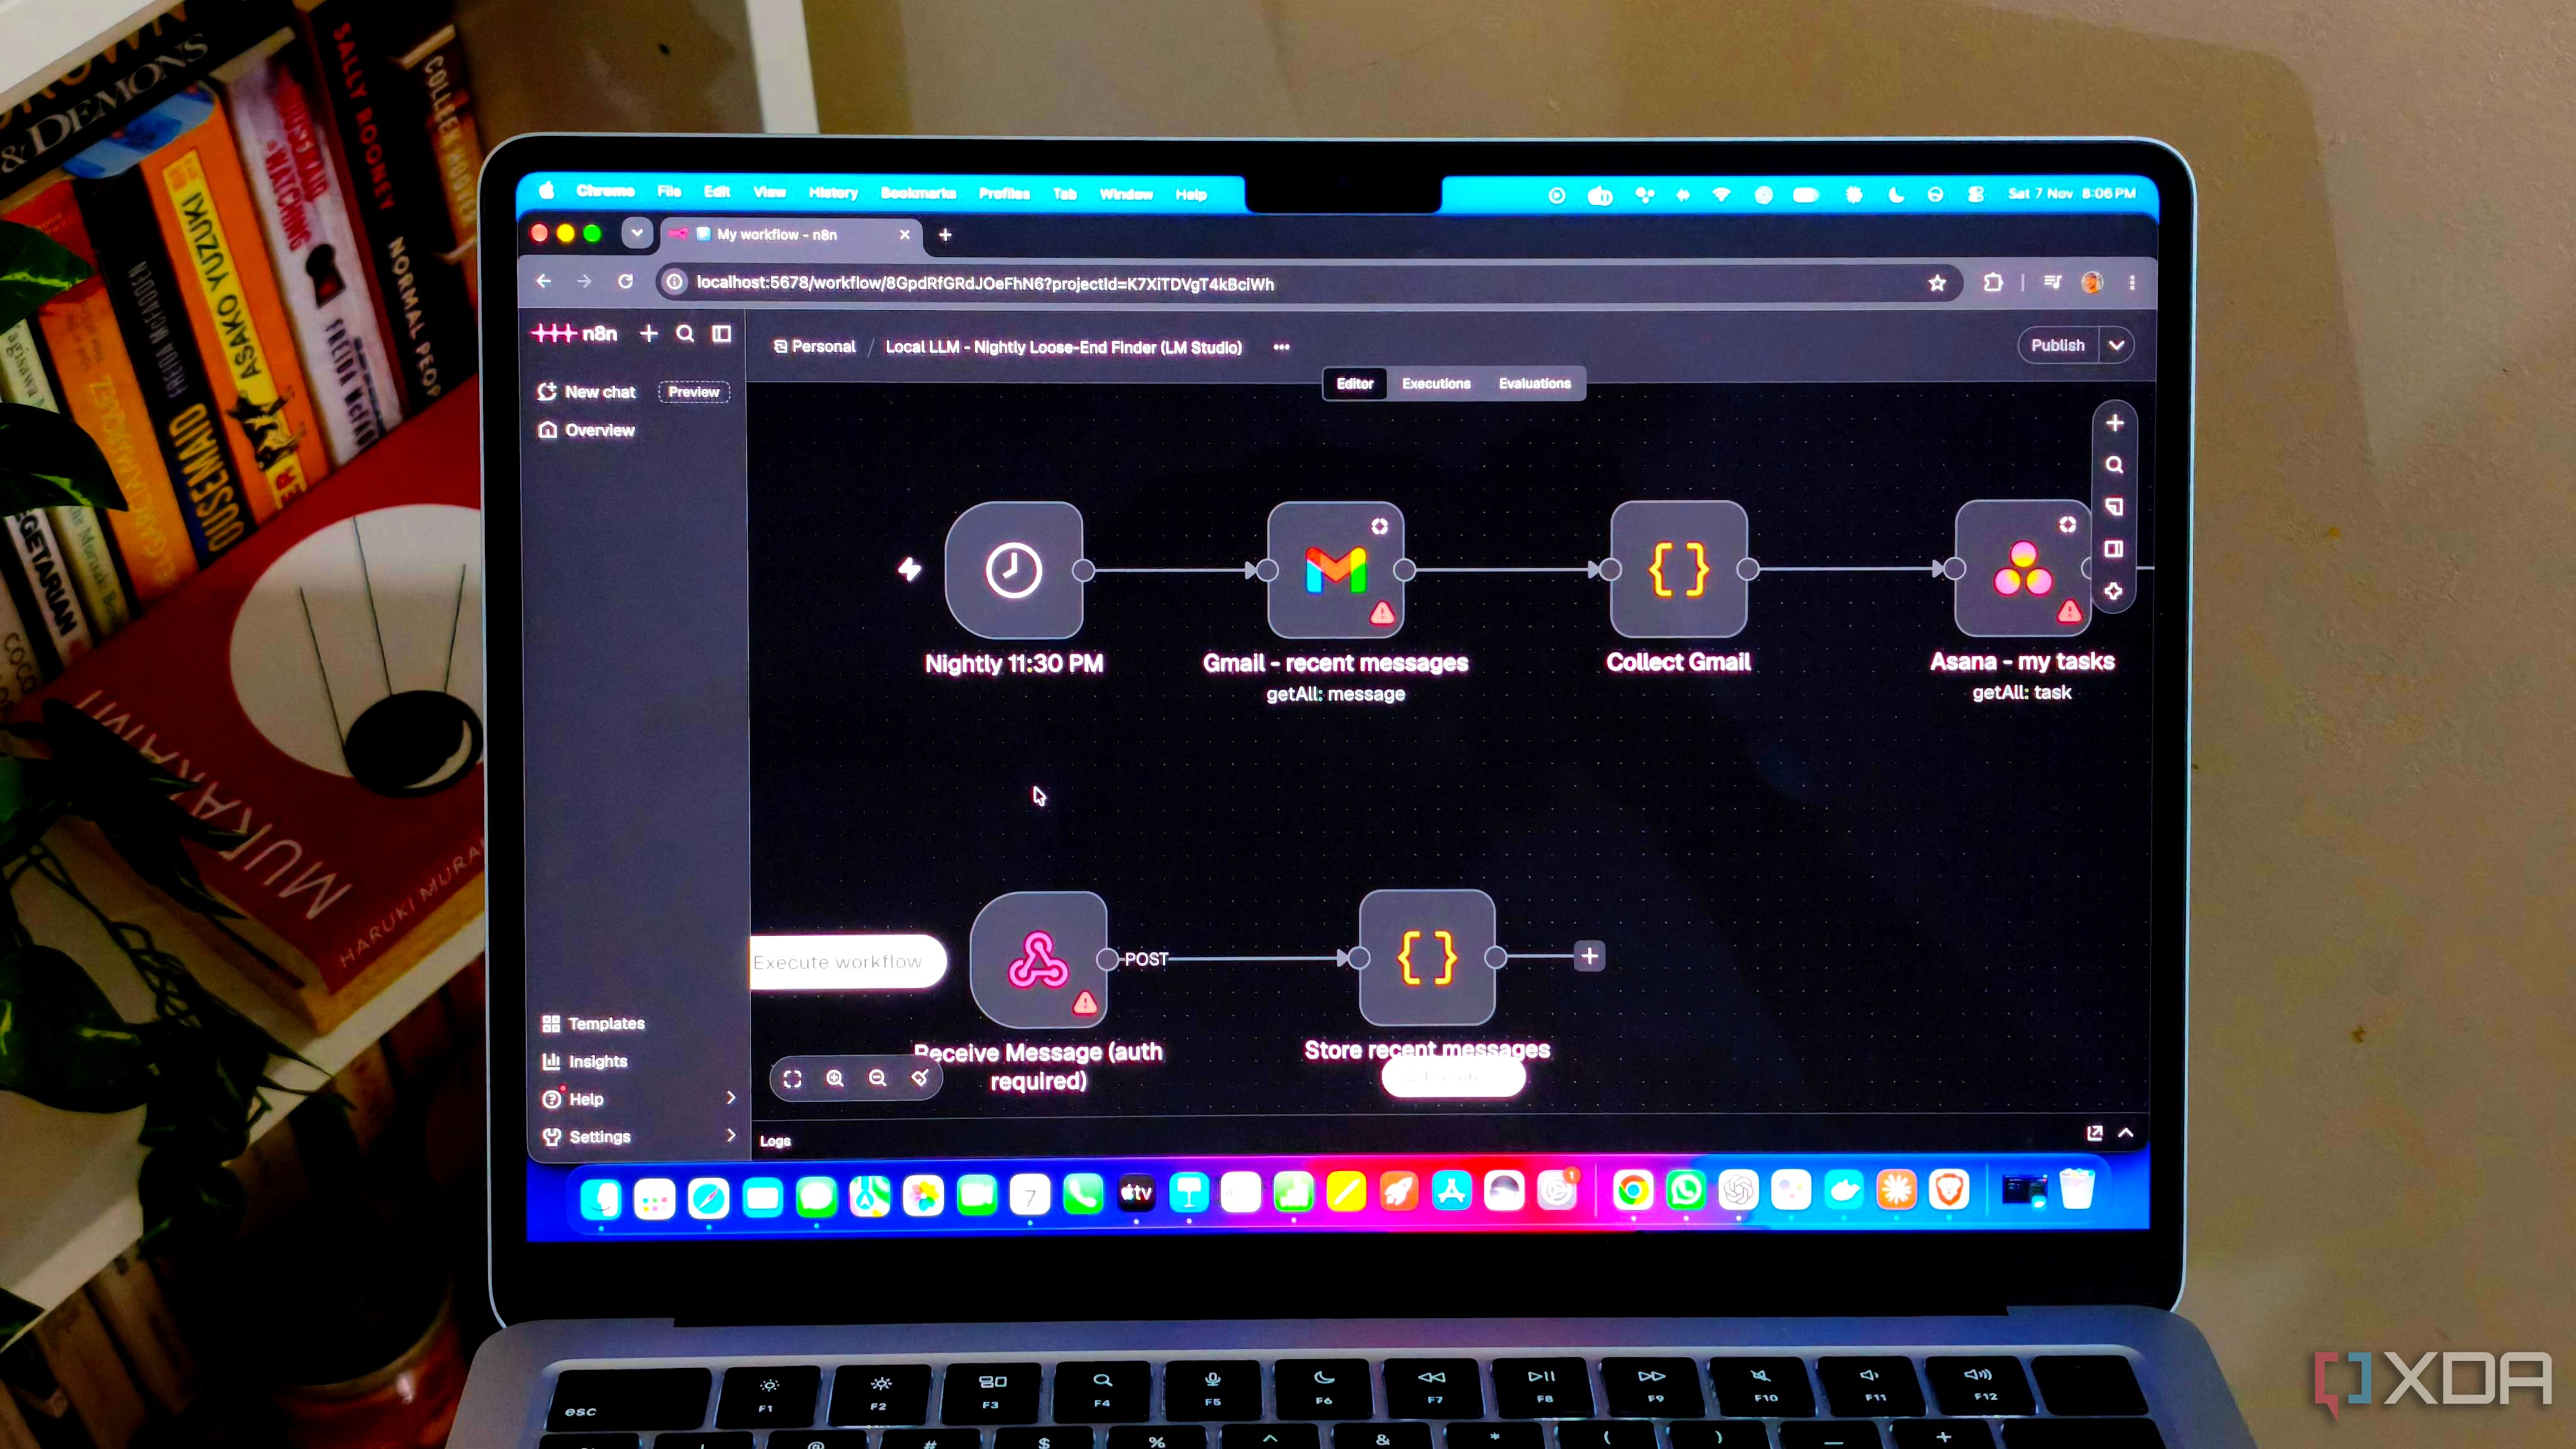
I gave my local LLM one job that runs every night, and it's done more for me than a year of chatting with it
I've spent a lot of time experimenting with local LLMs, trying different models, testing their capabilities, and finding practical ways to use them. Some have been surprisingly good, but most of my interactions have followed the same pattern. I open a chat window, give the model a prompt, get a response, and move on. Recently, I decided to try something different – I gave it one job to handle every night.
Modeling A2A with the x-a2a Extension
Quick answer: The x-a2a extension models an A2A operation inside an OpenAPI document, holding the version, binding, endpoint, method, Agent Card URL, explicit request and response contracts, and examples. It is a vendor extension, not a standard OpenAPI keyword, so the x- prefix signals that it is extra metadata rather than part of the core specification. Keeping the details explicit makes the A2A surface reviewable instead of implied.
Why a vendor extension
A2A details do not all fit into standard OpenAPI fields. The version, the binding, and the Agent Card URL are specific to the protocol, and the request and response need explicit contracts that match the JSON-RPC shape. A vendor extension gives those details a named home without pretending they are standard.
The x- prefix is the OpenAPI convention for this. It marks the data as additional, tool-specific metadata, and a reader can tell at once where the standard document ends and the extension begins.
What the extension holds
| Field | Role |
|---|---|
| Version | The A2A version, such as 1.0 or 0.3 |
| Binding | JSON-RPC, REST, or gRPC |
| Endpoint | Where the request is sent |
| Method | The A2A method being called |
| Agent Card URL | The explicit card discovery URL |
| Request/response contracts | Explicit shapes for the operation |
| Examples | Worked examples for review |
Because the version and binding are named together, an unsupported pair can be caught rather than silently translated, and the card URL keeps discovery tied to the same record.
Consider an operation modeled as a 1.0 JSON-RPC call. The extension names the version as 1.0, the binding as JSON-RPC, the method and endpoint, and the card URL, and it attaches the explicit contracts plus a worked example. When the desktop builds the request, it reads those fields rather than prompting for a guess, and the version header is attached from the record. If someone changes the binding to REST while the version stays 0.3, the unsupported pair is caught at the record rather than sent and rejected. Keeping the version and binding next to each other is what makes that check possible, and the examples give a reviewer a concrete shape to compare against the real agent.
How it supports building and debugging
The extension feeds the Debug surface rather than living as documentation alone.
- Read the version and binding and confirm they are a supported pair.
- Use the endpoint and method to build the request.
- Attach the
A2A-Versionheader. - Assert against the explicit request and response contracts.
- Use the examples to confirm the expected shapes.
This keeps the generated request body grounded in the record, and it makes a 200 that carries a JSON-RPC error visible against the declared response rather than hidden behind the transport status.
Honest limits
Because x-a2a is not a standard keyword, a tool that does not know the extension will simply ignore it rather than interpret it, and the metadata does not certify the runtime behavior. The contracts describe what the operation should look like, and they still need real verification against the agent. A modeled operation is not a confirmed one.
This is the same boundary that keeps a static record from being written as a guarantee. The extension organizes the A2A surface so it can be reviewed and tested, and the actual verdict comes from executing the calls.
Powerduck keeps the extension in the document as structured metadata, with the limits and the later verification kept separate.
Frequently asked questions
Is x-a2a part of the OpenAPI standard? No. It is a vendor extension, and the x- prefix marks it as tool-specific metadata.
What does it capture? Version, binding, endpoint, method, card URL, explicit contracts, and examples for an A2A operation.
Does modeling the operation verify it? No. The record supports building and debugging, but the behavior still needs real calls and assertions.
The bottom line
The x-a2a extension gives A2A operations a named, reviewable home in an OpenAPI document, carrying the version, binding, endpoint, method, card URL, explicit contracts, and examples. It stays a vendor extension rather than a standard keyword, and it does not certify runtime behavior. Its value is organized metadata that feeds the Debug surface and later verification, not a proof by itself. Naming the details is what keeps the A2A surface honest. Read more in the A2A guide.
Your Vercel AI SDK agent already knows the answer. Stop making it re-derive it.
Your Vercel AI SDK agent already knows the answer. Stop making it re-derive it.
Your Vercel AI SDK agent just spent 3.9 seconds and a full tool loop answering a goal it answered yesterday. Different user, slightly different wording, same intent — and the agent re-derived the whole plan from scratch: same tool choices, same order, same result. The model call isn't the expensive part. The re-derivation is.
This is the loop tax, and it hits every framework the same way. Vercel AI SDK's generateText with tools, Mastra's agent runs, a hand-rolled loop — they all re-run the same goals all day, because nothing in the stack notices that the trajectory repeated. Prompt caching at the model layer saves you per-call. It doesn't notice that the plan repeated.
Pomerene is a deterministic trajectory cache for agentic workflows, and the integration model is deliberately boring: it wraps your agent function, not your model client. Your prompts are never touched, rewritten, or intercepted. That matters for Vercel AI SDK and Mastra, because the cache doesn't need to know anything about your framework's internals — only that it can record a run and replay the recorded steps when a matching goal arrives.
The integration: one wrap, or two HTTP calls
There are two integration shapes, and both are framework-proof — the same code works whether your agent runs on Vercel AI SDK, Mastra, LangGraph, or a hand-rolled loop, because the unit being cached is the trajectory, not the framework object.
One wrap:
import { withCache } from "@pomerene/core"; // from the self-hosted Starter Kit

const cachedAgent = withCache(myAgent, {
  // policy: what may be fuzzy-matched, what may never be
  writeSteps: "never-fuzzy",   // steps that mutate state are never fuzzy-matched
  drift: "handoff",            // partial drift hands control back to the agent
});

const result = await cachedAgent.run("refund the extra charge on my last order");
Or two HTTP calls, in any language:
POST /v1/lookup { goal, context }   # before your agent runs
POST /v1/store   { goal, trajectory } # after it finishes
L1 returns the cached outcome. L2 resumes your agent mid-trajectory. A miss runs live and gets stored. That's the whole integration — and it works the same way in a Vercel AI SDK tool loop as in a Mastra agent, because in both cases the agent is a function: goal in, result out, plus a recorded trajectory in between.
What a hit actually looks like
Three outcomes, all deterministic — hashing plus vector geometry computed in TypeScript, no LLM call in the match decision, so the same input makes the same cache decision every time:
- L1 — full replay. The incoming goal matches a cached trajectory end to end. The stored plan replays: a 14-step audit trajectory replays in 47ms versus 3.9s live, with zero LLM invocation on the hit path.
- L2 — partial replay. The cached plan matches up to a point, then diverges. Pomerene replays the matching prefix and hands control back to your agent at the exact step where the plan stops matching. The agent only does the work that's actually new — the tool loop resumes mid-trajectory instead of restarting.
- Miss. No usable match — the request runs through your agent normally, and the completed trajectory is recorded for future hits.
On τ-bench — the airline customer-service benchmark, dense with the rephrased-same-goal traffic that support agents actually see — the engine served 86% of paraphrased requests from cache, with 78% of those judged correct. Read both numbers honestly: 86% is why repetitive agent workloads are worth caching, and 78% is why the write-safety rules below are the product, not a footnote.
The part that has to be true before you cache a write
A Vercel AI SDK agent with tools can charge a card, send a message, mutate a database. A Mastra agent the same. So the write rule is the whole product: steps that write are never fuzzy-matched against a new request. A cached write step replays only on an exact goal-plus-context repeat; anything ambiguous becomes a miss or an L2 handoff. Partial drift produces a handoff to your agent, never a subtly wrong execution. On an adversarial eval of polarity-flipped pairs (requests that are semantically close but must not be confused, like activate vs. deactivate at 0.853 cosine similarity), the gated engine produced 0 false positives across 18 pairs.
One honest note, because the gate's story changed after the first post about it: the write-safety gate as originally published had three holes, found via outside critique and fixed in core — merged, shipping in the next core release. An abstract-goal match is no longer treated as an exact repeat (write trajectories are refused there, and context is diffed); a trajectory with no taint records plus a context change is now a miss; and a hit never serves past a declared external_write — control hands back to the agent at that step. Still open, not shipped: entity agreement on read matches. The numbers above describe the gate as designed; the fixes are what keep the design honest, and the open item is the next gate to build.
Measure first, then wrap
If your agent's traffic is mostly unique, one-off tasks, this buys you less — and the kit will tell you that before you commit. The built-in diagnostics (/v1/diagnostics) show hit rates, the L1/L2/miss breakdown, latency percentiles, and dollars and tokens saved for your real traffic. If your traces show the same goals arriving in different wording, you're paying the model to rediscover plans it already derived. A wrapper turns that rediscovery into a replay — in your Vercel AI SDK loop, your Mastra agent, or wherever the agent lives.
Pomerene ships as a self-hosted Starter Kit — Indie $99 / Pro $249, one-time, source included — so the cache runs in your infrastructure, next to your agents. Quickstart is about 5 minutes (Node 20+, Docker or Postgres 15+). Docs and details at pomerene.io/starter-kit.
Startup Founder Interview: Brief Is Building the AI CRM Influencer Marketing Teams Have Been Missing
Welcome to HackerNoon’s Writing Prompts! Would you like to take a stab at answering some of these questions? The link for the template is HERE.
1. What is your company in 2–5 words?
AI CRM for influencer marketing.
2. Why is now the time for your company to exist?
Influencer marketing is now a core budget line for most brands, not an experiment. The industry is hitting $47B and the teams running these campaigns are still operating on WhatsApp and spreadsheets. AI finally makes it possible to automate the coordination layer that's been killing their time. Two years ago the AI wasn't good enough. Two years from now every big player will have copied it. Now is the window.
3. What do you love about your team, and why are you the ones to solve this problem?
It's just me right now, and that's actually the point. I'm not a developer who discovered influencer marketing. I'm an influencer marketer who learned to build. I've lived inside this problem for 6 years across 1,000+ campaigns and over $5M in spend. I know exactly what breaks, when it breaks, and why. Nobody is closer to this customer than I am because I am the customer.
4. If you weren’t building your startup, what would you be doing?
Honestly? Still managing influencer campaigns and complaining about the lack of good tools. Brief exists because I got tired of waiting for someone else to build it.
5. At the moment, how do you measure success? What are your metrics?
Right now, paying customers and retention. I care about teams that come back every month because Brief is how they run their business.
6. In a few sentences, what do you offer to whom?
Brief is the AI PM and CRM for influencer marketing teams. It manages campaigns from brief to invoice automatically, it simplifies creator partnerships and content approvals.
7. What’s most exciting about your traction to date?
I went from building the MVP in under a day, to spending over 100 hours using Lovable, I’m actually on their global 10% users. The speed of that, from idea to live product to first paying customer tells me the demand is real. The exciting part isn't the revenue yet. It's that every team I've shown it to has said the same thing: "I've been looking for this."
8. Where do you think your growth will be next year?
50 paying teams by end of year. Then opening the creator workspace, which is a completely different and much larger market. Every creator is running a business: brand deals, content, invoicing, contracts, analytics. Nobody has built the tool that treats it that way.
9. Tell us about your first paying customer and revenue expectations over the next year.
First customer is a small influencer marketing team, exactly the profile Brief is built for. Over the next 12 months the goal is 50 teams at an average of $799/month.
10. What’s your biggest threat?
I don’t se competitors as threats, I study them, and learn from them. The answer to that threat is the same as it's always been: move faster, stay closer to the customer, and build the thing they actually need instead of the thing that looks good in a deck.
As an update: Brief was just accepted at LvlUp Labs Marketing Edge Accelerator, and secured initial funding.
This startup founder interview template is based on HackerNoon Founder & CEO David Smooke’s ten questions for startup founders.
Would you like to take a stab at answering some of these questions? The link for the template is HERE.
What Fact-Checking My Own Claude Code Guide Taught Me About Verifiable AI
Most talk about verifiable AI is about the model: proofs of inference, attested hardware, reproducible weights. That matters. But most of the AI output people act on every day isn't a model call they could audit. It's a claim: in a doc, a README, an answer, a config someone copied.
I write about Claude Code. In February, I published a long guide to building with it, plus a companion GitHub repo of the configs I actually use. The repo is the part a reader can copy straight into their own setup, which turns out to matter. As Veera Ravindra Divi put it here on HackerNoon, Claude Code doesn't ship production code: your config does. A wrong config does more damage than a wrong sentence.
Since then I've re-checked every claim in it twice, once in August against Claude Code v2.1.234 and again this month against v2.1.311, the second time with four Claude Code agents working in parallel. I expected stale facts. What I didn't expect was ten claims that were wrong on the day I wrote them. One of them was a correction from the August pass.
This month, the agents did most of the checking. Some of their findings looked like errors until I traced the source, and some of my old claims looked fine until I did the same. Either way, what mattered was whether a verdict could be checked by someone other than whoever produced it.
What "Verifiable" Has to Mean for AI Output
A verified claim needs four things. I learned each one by watching a check fail without it.
|
Property |
Question it answers |
Failure without it |
|---|---|---|
|
Source |
Where does this come from? |
Plausible numbers nobody measured |
|
Version |
True as of when? |
"Corrections" that were never true |
|
Reproducibility |
Can someone else re-run the check? |
Works on my machine, fails on yours |
|
Independence |
Is the evidence separate from the claim? |
A checker citing the article it's checking |
None of these is about the model. You can run the best model available and still get output you can't verify. You can also run a cheaper one and get output anyone can audit, if the process makes it leave a trail.
The Ten Claims That Failed
From the August pass:
- "Delegate Mode (
Shift+Tab)." It never existed.Shift+Tabcycles permission modes. I'd described a feature that sounded right in three different files. @-imports defer loading. They don't. Imported files are expanded into context at launch. Imports organise your instructions; they don't save context.- An eight-layer memory hierarchy. It had ten. I'd missed the managed-policy CLAUDE.md entirely, a layer that existed the whole time and can't be excluded.
- "Keep CLAUDE.md under 500 lines." That was my own guess. Anthropic's published guidance is under 200.
From the October pass:
- "Before v2.1.179 the default display mode was
auto." This one hurts most, because I added it in August as a correction. No changelog entry supports it. - "Forks cannot spawn further forks." Unverified. What is documented is that forks count toward the three-level nesting cap.
- "Auto-compaction triggers at about 95% of context." There's no fixed percentage. By default it compacts at the model's context limit, about 967K tokens on the 1M-context models, and
/autocompactsets an earlier trigger. - "A skill costs about one line of context at startup." The real cost is the skill's description plus its "when to use" text, capped at 1,536 characters per skill. The whole listing is budgeted at 1% of the context window.
- "Unspecified teammates inherit the lead's model." The lead's model is the last fallback, after the spawn prompt, the agent definition's
modelandCLAUDE_CODE_SUBAGENT_MODEL. - "Fable investigates before acting and verifies its own work." No official source says that. Anthropic describes Fable 5.1 as being "for demanding reasoning and long-horizon agentic work". I'd absorbed a paraphrase and repeated it as a capability.
Every one of these is fluent, specific, and plausible. That is the kind of claim language models produce easily, and agents repeat confidently. It is also the kind a reader can't check without a source.
Source: Unsourced Precision Is Unverifiable
Look at numbers 5, 7 and 8. A version number, a percentage, and a line count. Each one survived review because it was specific.
"Compaction triggers at about 95%" sounds like someone measured it. "Before v2.1.179" sounds like someone read the changelog. Nobody had. The precision did the persuading, and the precision was invented.
My rule now: every number gets a source next to it, or it gets rewritten as a range or removed. When the first correction pass suggested "fixed around v2.1.63" for a GitHub issue, there was no changelog entry behind it. That number came out too. The guide now says the behaviour is no longer reproducible and tells readers to check it themselves with /context.
Version: Sources Describe Specific Systems
Checking against official documentation sounds definitive until two official sources disagree.
In August, Claude Code's subagents page still listed a 200-subagent-per-session cap. The changelog said it was removed in v2.1.224. The docs hadn't caught up.
In October, Anthropic's API models page listed Sonnet 5.5's default effort as high. Claude Code's model configuration page says the 5.5 models default to medium. Both are right: one describes the API, the other describes Claude Code. An agent that reads only one of them will "correct" a true claim into a false one.
So provenance has to include which system and which version a source describes. For anything version-specific, I treat the changelog as the primary source. When sources disagree, the verdict says which surface each one describes rather than quietly picking one.
Reproducibility: Run It, Don't Read It
The worst error in the February guide isn't on the list above. Nothing I wrote was false; I left something out.
Agent Teams is experimental and disabled by default. It needs CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1. I never mentioned it, because the flag had sat in my own settings.json so long I'd stopped seeing it. Every Agent Teams pattern in the guide worked on my machine and did nothing on yours.
Reading docs can't catch that. The docs are right, and the claim is right. What's missing is the environment. The only check that works is re-running the instructions somewhere that isn't your machine.
T

SealedBench: A Protocol for Freezing AI Benchmarks Before the Questions Are Known
A frozen model manifest, a generator sealed with drand, and an Arweave record anyone can use to rebuild the exam and check its scores.
I knew the question types but not the actual questions
On 2026-10-17, a bundle carrying my encrypted generator reached an Arweave block. The generator was sealed to a drand round that had not been published yet. I wrote that program, so I knew it would produce integer word problems, short Python programs, and shortest-path questions. I did not know which ones. The questions depended on a beacon the drand network would publish later, at round 33170212, on 2026-10-18T09:00:00Z.
When the round arrived, the same beacon value unlocked the program and seeded it. Four open-weight models answered 360 completions each: 240 on newly generated questions and 120 on a frozen set of public GSM8K items.
But the first two batches I ran should not be cited, and it is worth saying why, because the reason is the most useful thing in this article.
The first batch, b1, was valid under its own release record. Its manifest bound the ciphertext with a SHA-256 hash, but it never bound the ciphertext's transaction ID. Calling that check a pass would be a mistake, and it is WEAK. The v2 protocol exists partly to close that gap.
The second batch, b2, fixed the binding and then failed on the grader. The rule I sealed said an integer answer counts only when the last line is #### followed by nothing but the number. llama.cpp writes its end-of-text marker onto that same line, as #### 392 [end of text]. The registered grader threw the whole line away. Most of b2's arithmetic and GSM8K scores measure that rejection, not the rate at which models produced correct integers.
The ciphertext was already sealed by then, and the grader could not be changed in place. That constraint is the entire point of the protocol, and it applies to me too. So I made b3: a new commitment, sealed before its own round, with the normalization written into the scorer the manifest hashes.
So if you want a number from this project, take one from b3, and take the registered primary accuracy, which counts an answer as wrong when it cannot be parsed and wrong when the output was truncated. Its index transaction is vlVlUfyBn4IUmbXjkSX8079QuySP-Qqr8rN8TbivzTg. That index was published after the run. It is a convenient entry point, not evidence: the evidence that the generator existed before the round is the earlier ciphertext and manifest.
What a reader needs in order to catch me
Public benchmarks leak. Once the questions are online, a high score may only mean the model has seen them.
A private test set looks like the fix, but it hands the same power to one person: whoever writes, stores, selects and reports the questions. That person includes the evaluator, which is me. If I can see the scores and then quietly change the seed, the prompt, the model file, or simply decide which batch to tell you about, I can aim the headline wherever I want.
SealedBench tries to pin all of that down in advance. The generator, the model hashes, the prompts, the runtime settings and the scoring code are bound to one future beacon round. Unless drand's operators reach a threshold and collude to compute that round early, I cannot read the beacon before it is published. If the network stops, the batch never opens; that is the other half of the bargain. After the round, anyone can rebuild the questions from the Arweave record and re-score the answers I published.
Here is every move I could make, and what I gave up in advance to make it visible.
|
What I could change after seeing scores |
What was committed in advance |
What you still have to check |
|---|---|---|
|
The generator or the recipe |
Ciphertext and manifest on Arweave before the round |
Check L1 block time, not the upload receipt |
|
The seed |
The beacon round fixed in the manifest |
That the generator really uses that seed |
|
Questions, answers or the scorer, later |
Content hashes |
A hash cannot show which process wrote a file |
|
Reporting only the flattering batch |
Batches declared up front |
Encryption cannot force me to publish answers |
Freeze, seal, then wait for a block
The manifest freezes the drand chain hash and public key, the release round, the seed rule, a SHA-256 for every GGUF, the llama.cpp commit and build flags, the prompts, the decoding settings, the grader and the reporting policy. Every batch uses quicknet chain 52db9ba70e0cc0f6eaf7803dd07447a1f5477735fd3f661792ba94600c84e971, genesis at unix 1692803367, period 3 seconds.
The generator is sealed to that round with drand time-lock encryption (tlock). The ciphertext and the manifest go up through the Turbo bundler. A receipt is not a commitment. The commitment is the L1 block.
Under the v2 rule a batch is valid only if the block holding its bundle is timestamped no later than unlock_unix − 600, the bundle ID appears in that block, and the data item's bytes hash to the committed SHA-256. Height, timestamp and block hash must agree on two independent gateways, and my own gateway ario.zigza.xyz does not count as either one. b1 used an earlier, simpler rule: manifest and ciphertext had to be in an L1 block before the release round, and a miss made the batch invalid, which I would still have had to report.
After the round, the beacon signature is checked against quicknet's fixed public key. The same beacon both decrypts the generator and enters the seed. One value doing two jobs is not two independent draws, and I do not claim otherwise.
b1's seed is a SHA-256 over a domain string, the chain hash, the round in decimal and the beacon randomness, with hex fields lowercased first. The exact sentence is in b1's manifest. v2 batches add a 32-byte secret stored inside the ciphertext, and hash length-prefixed fields: domain, chain hash, round, signature bytes and that secret. The JSON randomness field is not an input; it must still equal the SHA-256 of the signature. I chose the secret. It does not let me list the questions before the beacon exists. A successful tle -d only shows the ciphertext opens under the signature it was sealed to. The BLS check against the fixed public key is a separate step.
There is one specific gap in v1 worth naming. The November capsule cap and b1 share the same plaintext tarball, SHA-256 e054f1ab7824fde33e6ac399252098cf25c29815ff4ffacabbd311da05eac9c2. Once b1 opened, that program was public. Until 2026-11-15 the unknown is the beacon, not the program. v2 still hides its questions, because the secret sits inside the ciphertext.
Four small models, one CPU, three question families
Every family has a program for an oracle, so grading is code and not a judge model. arith_word produces two-to-five-step integer word problems; the oracle is a function of the sampling parameters, and the prompt contains no answer line. code_output produces short Python programs with no imports and no input, run in an interpreter with a step budget; the oracle is their stdout. graph_p
Control the Glowing Apple Logo on Your New MacBook Pro
If you'd rather keep the logo dark, Apple has shared a way to turn it off. Unusually though, there's no switch in System Settings. Instead, you need to enter a command in the Terminal app. If that sounds intimidating, don't worry – it's a single line that you can copy and paste. Note that the following command only works on MacBook Pro models with a PROLED XDR display.
- Open Terminal on your Mac: it's in the Applications ➝ Utilities folder, or you can search for "Terminal" using Spotlight (Command + Space).
- Type or paste the following command, then press Enter:
sudo defaults write com.apple.CoreBrightness LEBacklightMode -int 0
- When prompted, enter your administrator password and press Enter. (Terminal doesn't show the password as you type it.)
Relight the Apple Logo
Reinstalling macOS turns the illumination back on, but you can also turn it back on yourself at any time by entering the following command in Terminal:
sudo defaults delete com.apple.CoreBrightness LEBacklightMode
Remember to press Enter!
Backstory
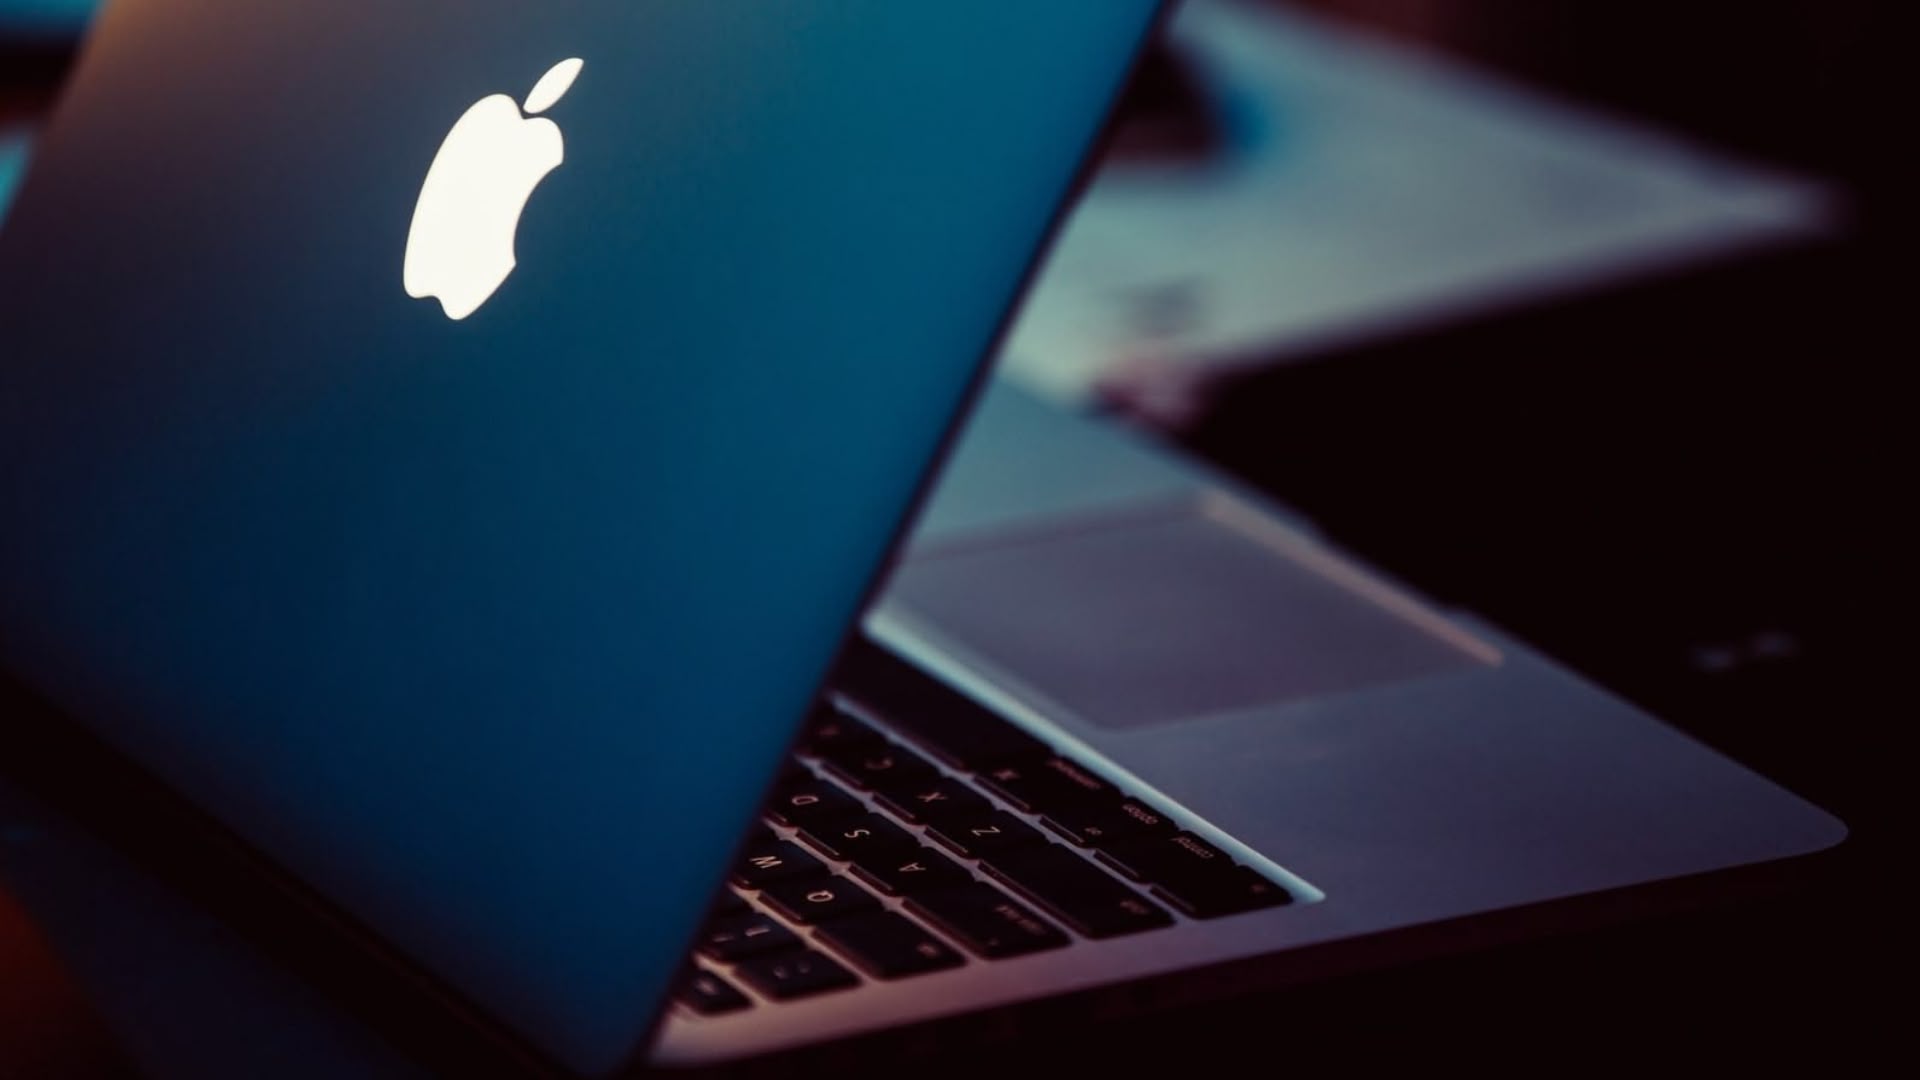
The first Mac laptop with a lit-up Apple logo was the third-generation PowerBook G3 launched in 1999. The glowing symbol proved a mainstay through consecutive Apple notebooks for the next 16 years. The only change in that period was that the logo got flipped upright, so that it no longer appeared upside-down to onlookers when someone was sat in public with the lid open.
According to former Apple employee Joe Moreno, the original orientation was deliberate: Apple's design group had found that users kept trying to open their laptops from the wrong end. "Steve Jobs always focused on providing the best possible user experience and believed that it was more important to satisfy the user than the onlooker," Moreno recalled.
Ironically, Jobs later reversed the decision.
"Opening a laptop from the wrong end is a self-correcting problem that only lasts a few seconds," said Moreno. "However, viewing the upside logo is a problem that lasts indefinitely."
In 2015, Apple began nixing the illuminated insignia from its laptops, starting with the ultra-thin 12-inch MacBook, which had a polished metal logo instead, like iPads before it. In 2016, a new generation of MacBook Pro models continued the unlit trend. Apple hasn't launched a Mac laptop with a glowing logo since – until now.
This article, "Control the Glowing Apple Logo on Your New MacBook Pro" first appeared on MacRumors.com
Discuss this article in our forums
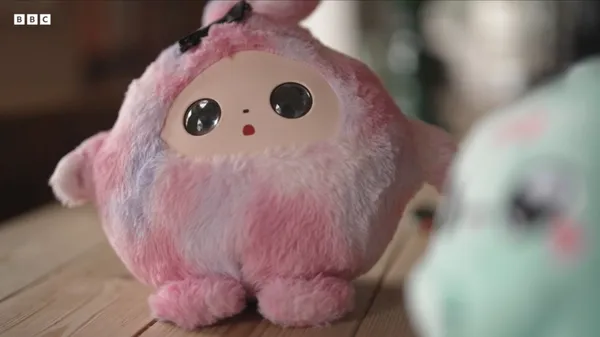
AI teddy bears spark fresh safety fears after report discovers malfunctioning toys
5 tips for getting the most out of AI
Why do some people seem to be getting a lot out of AI, while others—maybe you—still feel like they’re spinning their wheels trying to squeeze anything remotely useful out of these platforms? The answer is multifaceted, of course.
Some workflows are better suited to the strengths of large language models, while others are more vulnerable to their weaknesses. Some users pay for upgraded plans, which can improve how well the models work.
But a big part of the difference comes down to how you use artificial intelligence. Like any tool, there are ways to make it perform better for you. In other words, the technology is often what you make of it.
If you offload your thinking to AI platforms, you risk dulling your ability to approach problems creatively and becoming dependent on a flawed technological crutch. But if you use AI to challenge yourself, stress-test your work, and outsource routine tasks, you might feel, at least in some sense, like you’ve gotten a significant upgrade.
Consider the calculator: Some people have become so reliant on it that their mental math skills suffer, while others use the technology to tackle more advanced math because they’re not spending their time on simpler problems.
Like all new technologies, what you choose to outsource to AI is up to you. Still, if you do decide to use it, it’s worth considering how to get the most out of the technology—and make sure chatbots serve you, rather than the other way around. Here are a few tips to make these platforms work better for you.
Be smart about your prompts
What you type into your AI actually matters. Take traditional search engines. You may not realize it, but over time, you might have developed an implicit sense of how using certain Boolean operators or more specific proper nouns can yield better, more relevant results to your queries.
The same is true for AI. Being more specific with a chatbot about what information you want can make a big difference, particularly when you’re using the technology as a search tool. It might be easy to slip into thinking that AI should already know what you want, but it doesn’t. Instead, treat a chatbot as an earnest research assistant with the capacity to make a lot of mistakes. There’s an old adage: “The more you know, the more they know.” The same logic applies to AI.
Here’s an example: If I’m shopping for a bookshelf, I no longer sift through countless listings searching for something that feels right. Instead, I take a picture of the spot where I need it to go, give the AI the dimensions (or range of dimensions) I’m looking for, and ask the chatbot to find the best options given those constraints. This saves me a lot of time and allows me to work smarter when using AI for shopping.
Encourage humility
One of the big problems with AI—or any work you don’t do yourself and instead outsource to someone (or something) else—is that it will make mistakes. Fear of an AI oopsie is anxiety-inducing and absolutely real, and one of the best reasons not to completely offload all your tasks to ChatGPT or Claude. Really, don’t do this!
The best approach is to check any work produced by a chatbot yourself. But there are also ways to help these tools work better. If you have the ability to adjust your AI’s settings, tell it to be more humble—and more cautious—when sharing information or making claims. Tell your AI to consider multiple ways of thinking about a question or problem, and to present divergent viewpoints. For kicks, tell it to admit when it’s unsure.
Also, always ask for direct citations and check them off the platform. When you send a prompt to your chatbot, tell it to avoid simply summarizing information and instead to provide direct links to sources so you can verify the claims yourself. Once you do this, you might be shocked by how often AI claims to be consulting a source or generates a fake web page only to apologize when you discover it doesn’t actually exist.
A polite reminder: Just because Claude says it’s “double-checking” something doesn’t mean it actually is. You need to double-check it, too! AI can cite unreliable sources and even hallucinate citations entirely. AI is powerful, but also unpredictable, and should never be treated as an objective source of information. Think of it as a sieve that helps you sift through information and find what you want faster, rather than something you can trust to identify the best results on its own.
Understand memory
Your AI is remembering what you ask it and what you tell it, even if you’re not always aware. This isn’t necessarily unique to AI systems; many tech platforms collect all sorts of data about you and then use that information to tailor content to you (usually, ads). It’s possible you don’t want AI to remember anything about you at all, in which case, check your privacy settings—or perhaps avoid AI entirely.
But if you are comfortable with a chatbot retaining information about you, consider that its memory can actually be a useful tool. For instance, if you’re using AI to draft emails, tell your chatbot to always introduce you in the way you prefer. If you tend to offer to jump on a call or Zoom, tell the AI that you like doing so—and ask it to remember that preference for when you draft emails in the future. If you prefer a more casual tone, tell it that. If you prefer to remain formal, tell it that instead.
Here’s another example: If you’d like your AI to avoid sending you links from Amazon when you’re online shopping—perhaps you don’t have an Amazon account—tell it to remember that preference so you don’t have to keep sifting through those links. Or maybe you’d prefer your AI to prioritize links to The New York Times because you already have a subscription. Tell your AI that, too.
Also, remember that you don’t need to give AI your personal information at all. For kicks, try asking it to erase things from its memory that you don’t want it to retain. There’s absolutely no guarantee that a request alone will erase the information completely, so check your privacy and memory settings, too. But why not give it a stab?
Customize how AI communicates
You spend a lot of time on Google, but you might now be pivoting to AI to surface information instead. One advantage of this is that you can have AI produce results in all sorts of formats and styles, since you dictate the terms in which it expresses itself. For instance, you might prefer to receive information in simple bullet points rather than a long, essay-like string of text. You can share that preference with your chatbot.
Maybe you prefer visuals and graphics? AI is great at whipping those up. For the nerds: Maybe you prefer receiving information in code that you can then copy and paste into a development environment, like Python, so you can run a script to check whatever work the A

Is that advertisement AI-generated? These 6 signs offer clues.
From the sandwich-board ads outside neighborhood bodegas to campaigns by multimillion-dollar companies and midterm political races, AI-generated advertising is becoming part of our everyday scenery. But figuring out which images were photographed, which were prompted, and which fall somewhere in between is getting harder. In a September study of more than 500 consumers, only 17 percent correctly identified the AI-generated ad in a lineup of 10 — even though half initially felt confident they could spot it.
So what gives an AI ad away? Often, it’s something small that doesn’t hold up as well as the overall image. These six signs can offer clues.
1. The product looks plausible until its parts stop making sense
An ad can have a believable setting and a perfectly ordinary model, then fall apart around the product. For example, in June, an REI Instagram ad featured a bicycle with an extra set of handlebars growing out of its saddle.

According to the retailer, Meta's AI personalization tool altered a vendor-provided image, turning a real photograph into slop. REI said it took steps to unenroll from the tool.
"While a two-handled bike might be interesting, it is not something you will find in our assortment," REI told Fast Company.
Other advertisers have encountered similar changes. In July reporting by Business Insider, advertising consultant Jessica Gleim said Meta had suggested an image that turned a client's pajama dress into a shirt and pants. For another client, a women’s networking group in Montana, the tool proposed adding men. As Gleim told BI, "It’s not usable to help my clients grow their business," regarding AI-generation.
2. The same character or object looks different between shots
Sometimes, each shot looks plausible on its own. Put them together, though, and the main character — or main vehicle — doesn’t quite stay the same.
Coca-Cola's 2025 viral AI-generated "Holidays Are Coming" commercial drew criticism for its poor shot consistency, and its harshest critics called it "soulless, bland, and hard to even watch." Viewers and experts documented changing vehicle design across the truck scenes, including mechanically implausible configurations. (Of course, that didn't stop Coca-Cola from airing the commercial all winter long.)
The same sort of inconsistency appeared in Toys "R" Us's 2024 film, made with OpenAI's Sora (RIP). The film depicts the company's founder Charles Lazarus as a boy dreaming about a fantastical toy store. But the child's appearance varied throughout the video.
This Tweet is currently unavailable. It might be loading or has been removed.
Similar inconsistencies can happen within a shot. Last year, UC Berkeley digital forensics expert Hany Farid told Mashable to look for "temporal inconsistencies," such as "the building added a story, or the car changed colors, things that are physically not possible." These changes can occur in the background, away from the main subject, making them easier to miss.
3. Movement doesn’t match the object — or the speech
Back to Coca-Cola. In their 2024 AI holiday advertisement, the trucks were moving along roads without their wheels even rotating. Very sloppy.
This Tweet is currently unavailable. It might be loading or has been removed.
McDonald's Netherlands encountered its own visual problems in an AI-generated Christmas commercial from last year, with distorted faces and bodies, and the company pulled the ad after backlash. The Sweetshop CEO Melanie Bridge allegedly defended the production in a now-deleted statement, saying, "AI didn’t make this film. We did."
This Tweet is currently unavailable. It might be loading or has been removed.
As for synthetic people, look for a

Meta puts controversial web scraping policy changes on hold indefinitely
Meta was all set to make a controversial change to its terms of service back in October, but after a delay into November, the changes have been pushed aside indefinitely.
Mark Zuckerberg's company published a quick update (spotted by Nieman Lab) confirming that previously announced changes to its Meta Commercial Terms, Product Catalog Terms, Self-Serve Ad Terms, and Ad Creative Generative AI Terms would not take effect on Nov. 20 as initially planned. These changes, which Nieman Lab originally reported on in October, would have allowed the use of web scrapers to collect material from websites associated with Meta business accounts, including those of journalistic organizations.
Originally, these changes were set to go into effect on Oct. 30, before controversy prompted Meta to delay to Nov. 20. Now, Meta has confirmed that the changes will be delayed indefinitely.
"These updates are now paused and will not take effect on Nov. 20, 2026," Meta's statement read. "We are continuing to consult with stakeholders and will provide a further update when we have more to share. In the meantime, our existing terms remain in effect."
This Tweet is currently unavailable. It might be loading or has been removed.
When these changes were first announced, news organizations were (perhaps understandably) unhappy about their content being taken in that manner. Additionally, courts in Brazil took action to prevent that from happening.
At the end of October, Meta executive Andy Stone took to X to say that the company is "committed to getting this right," but evidently that commitment means the changes cannot go into effect anytime soon.
Want more tech and digital culture news delivered to your inbox daily or sent straight to your device? Sign up for Mashable's Top Stories newsletter or get Mashable push alerts today.

Our favorite Android smartwatch is $100 off: Save on the new Google Pixel Watch 5 before Black Friday
SAVE $100: As of Nov. 6, our favorite Android smartwatch, the Google Pixel Watch 5, is down to its lowest-ever price at Amazon. The 41mm WiFi model is discounted by $100.

Amazon just knocked $100 off the Google Pixel Watch 5, bringing the 41mm WiFi model down to $299.99, its lowest price yet.
If you have been waiting for the right moment to pick up our favorite Android smartwatch without paying full price, this limited-time deal completely wipes out the launch-day price bump.
When our team rounded up the year's best smartwatches, the Pixel Watch 5 took top honors for Android users. Last year's Pixel Watch 4 was already a running favorite for former Mashable reporter Christianna Silva, but the 5 earned its upgrade by adding a faster processor, double the storage, faster charging, and more accurate GPS route tracking for workouts.
It also sports a domed Actua 360 display shielded by scratch-resistant Gorilla Glass, along with up to 40 hours of battery life to comfortably get you through a day and a half between charges.
A lot of that appeal comes down to how smoothly it fits into a typical routine. Google built Gemini directly into the device, acting as a helpful companion on your wrist. It can display flight details on the way to the airport or suggest contact numbers while you text about dinner plans, and certain Gemini features even function offline when your phone lacks service.
Health tracking also sees a notable upgrade. Along with heart rate metrics and nightly sleep-stage summaries, the Pixel Watch 5 monitors long-term trends in blood pressure and insulin resistance. It also checks breathing regularity while you sleep and includes Loss of Pulse Detection, which can prompt an emergency call if it detects you need immediate help.
Grab the

AI agents may run your household. What could go wrong?
Erica Layer, a mom of a 2- and 6-year-old, has an enviable to-do list for her AI agent.
The busy executive relies on an Instinct agent for low-stakes but time-intensive household tasks like meal planning, calendaring, and birthday reminders.
"I do get a huge amount of time back," Layer says of delegating to an AI agent. "But also I'm doing the things that I just was dropping completely before."
Still, Layer is conflicted about her agent's persistence. The AI has suggested completing tasks on her behalf without explaining what happens to the data it accesses. Recently, her Instinct agent researched a family trip in Portugal, where she lives, and offered to book train tickets.
The catch? It wanted her kids' passports to make the purchase. Layer runs a fractional AI company, operates her own team of agents professionally, and has taught nearly 100 people to build agentic operating systems. She consulted Instinct's data privacy terms, felt they lacked transparency, and worried about how her data would be used. Layer, who wrote about her experience, made the reservation herself instead.
Mashable attempted to contact Instinct's founder for comment but did not receive a reply as of publication.
Like many parents — particularly moms — Layer is eager for an agent to handle the exhausting aspects of running a household. At the same time, she's unwilling to connect her personal data to a platform without clarity about its policies.
Parents are poised to be among the earliest adopters of AI agents for their families, yet unclear risks may compromise their personal and sensitive data. Experts say the excitement over agentic products for families is warranted, but that parents should first grasp how to best protect their data.
"I would love to have this mental load out of my head"
In a few short months, overwhelmed parents in the U.S. suddenly have their pick of agentic products. The September launch of Meta's Muse, reportedly in response to Instinct's early success, sparked instant competition. OpenAI quickly followed with its AI agent Dots, and Anthropic opened a waitlist for its "proactive" agent Claude Duet.
These products have overshadowed startup offerings like Fambot and Fo, both created by working parents and tech executives turned entrepreneurs. Fambot bills itself as a parent's "AI chief of staff" and Fo insists it'll "get sh*t done."
Meanwhile, Marissa Mayer, formerly the CEO of Yahoo, debuted her AI agent Dazzle to viral controversy after sharing with the New York Times that she asked her AI agent to choose three of her twin daughters' standout qualities for a school birthday slide. Mayer said on X the anecdote lacked important context about trying to challenge Dazzle with the prompt.
Either way, Layer wrote on Substack that she didn't appreciate how the response to Dazzle minimized the value of AI tools for households, particularly for working moms.
S. Shyam Sundar, director of the Penn State Center for Socially Responsible Artificial Intelligence, says parents who turn to AI to save time on tedious tasks aren't being selfish.
"I think it's looking out for more the psychological welfare of the household and the relationships within that household," he said.
Amy Wu Martin, a new mom and partner at the early-stage investment firm Menlo Ventures, says she's saved a lot of time letting Muse and Claude research whether restaurants and hotels are kid-friendly.
"I would love to have this mental load out of my head," she says of mundane parenting tasks.
Parents as early AI adopters
Menlo Ventures' survey research suggests parents are indeed AI power users. They are nearly twice as likely to use AI daily as non-parents. Among parents polled by the firm, 40 percent use AI daily for tasks like meal planning, shopping, and logistics. She envisions a future in which AI agents can handle purchases for parents, like ordering diapers.
Personally, Wu Martin has stopped short of connecting her inbox to an agent because of data security concerns. She's open, however, to letting an AI agent coordinate calendars with her husband.
Fambot, co-founded by dad of three and former Uber executive David Reich, turns school emails, sports schedules, and parent chats into a clear daily plan.
The agent gets read-only access to a parent's inbox, calendars, and WhatsApp groups and proceeds to manage every task it perceives relevant. It parses the school newsletters, sports schedules, and parent chats, then generates specific action items, calendar events, and a text summary each evening of what the parent needs to know.
Shivani Poddar, who previously worked as a senior engineering lead at Google DeepMind, recently launched the AI agent Fo through her startup Wajo AI. While it's not designed specifically for parents, Poddar says she relies on it for tasks like reminding her to buy a Halloween costume well in advance and finding a Mandarin class in San Francisco for her toddler. Fo can also bring a human customer service agent into its loop if necessary.
Really, Poddar says, she's looking to gain time back to spend with her child, and she knows other parents want that, too.
AI agent privacy and safety red flags
Kayne McGladrey, a virtual chief information security officer, says parents who want to use an AI agent can take reasonable privacy precautions.
Yet he understands that many consumers have developed "privacy nihilism." They feel like their digital lives will be compromised at any moment regardless of their choices. That can make vigilance feel like a losing battle, especially when privacy and security policies are dense and packed with jargon.
Privacy phrases to watch out for
He recommends evaluating an agentic product's marketing claims, especially those related to privacy and security. Consumers should look for phrases like "zero retention," "zero training," "no storage on the provider's server," and "zero-knowledge encryption."
Such phrases indicate the company's data practices prioritize consumer privacy and security by storing information carefully and limiting whether it's used to train AI models.
McGladrey, a senior member of the Insti

DJI unveils an all-weather drone built for pitch-black rescue missions: Features, night vision, and thermal imaging
TL;DR: DJI launched the Matrice 5T, a rugged enterprise drone packing 1K thermal imaging, LiDAR, and AI object tracking to find missing people in pitch-black darkness and bad weather.

Searching for a missing person across dense forests or choppy waters is grueling enough in broad daylight. Once night falls, or when heavy fog and blinding rain set in, standard aerial cameras hit a hard physical wall. Search and rescue crews are often left squinting at pixelated monitor screens and hoping a flashlight beam catches something reflective.
DJI designed the Matrice 5T to tackle those exact conditions. Built for first responders, disaster relief crews, and infrastructure inspectors, the enterprise drone functions as an all-in-one sensor rig engineered to handle pitch-black darkness, dense dust, and stormy weather.
Instead of using a standard night camera, the Matrice 5T packs a dedicated multi-sensor setup. The heart of its nighttime search gear is a native 1K thermal camera (1280 x 1024 resolution) with four times as many pixels as typical 640 x 512 sensors, letting teams spot faint heat signatures in cold terrain or rubble. With Ultra-High Resolution mode turned on, it doubles to 2560 x 2048 to keep heat sources crisp against messy backgrounds.
Thermal tech built for darkness
That thermal view is backed by long-range zoom and full-color night optics. The wide camera pulls color out of near-total darkness down to 0.01 lux, while a telephoto camera combines monochrome night vision with up to 176x hybrid zoom to read license plates from 400 meters away. For close-up utility work, a separate 50MP medium telephoto camera checks hardware from 10 meters out.
Flying low in the dark is risky around trees and wires, so the Matrice 5T combines omnidirectional low-light fisheye sensors with LiDAR and millimeter-wave radar. The top-mounted LiDAR spots thin overhead lines up to 32 meters away at night and locks onto them to fly alongside during line checks.
When the weather turns, the millimeter-wave radar cuts through thick fog, heavy rain, or blowing dust that blinds regular cameras. In deep river canyons or between tall buildings where GPS drops out, the drone fuses its visual and radar data to map the area in real-time, keeping flight smooth and steady.
Built-in AI and longer flight times
Spotting something in the dark is one thing, but figuring out what it is takes more work. The drone packs built-in edge AI models that can scan both thermal and standard video feeds in parallel to recognize more than 20 object categories, from vehicles and boats to individual humans. Responders connected to DJI FlightHub 2 can enter text prompts or upload reference images in the DJI Pilot 2 app to have the drone automatically sweep patrol zones and flag targets.