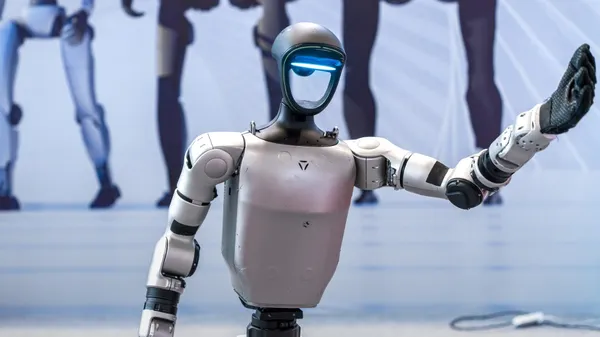
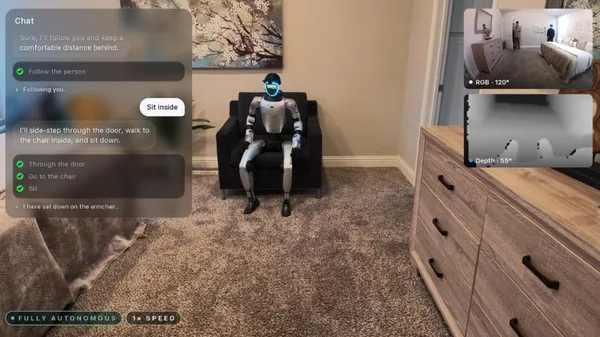
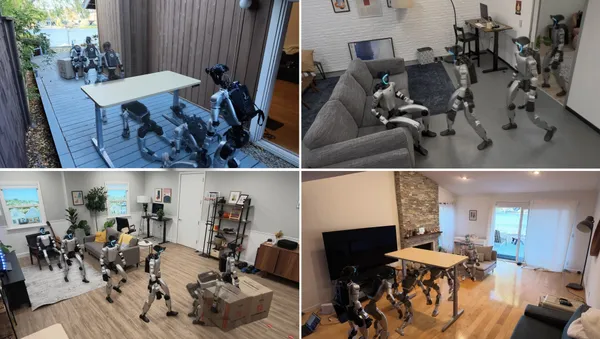
平均成功率91%!苹果研究团队披露机器人“大脑”进展:调用千问模型在宇树G1上验证

Billionaire Brian Chesky’s social-worker parents told him to pick a high-paying career. He went to art school—and started Airbnb with 3 air beds
Before Airbnb had over 9 million listings worldwide, there was one sole lodging: three inflatable air beds at CEO Brian Chesky’s San Francisco home. He had quit his job and packed up all his belongings in a Honda Civic to make a cross-country move, and couldn’t pay his rent. That’s when he noticed all the local hotels were booked because of the Industrial Designers Society of America’s International Design Conference in San Francisco, and a business was born.
“We called it the air-bed-and-breakfast,” he told Fortune in 2017 at a World’s Greatest Leaders event.
Chesky and Airbnb cofounder Joe Gebbia were hooked on the idea of making money and meeting new friends through their makeshift accommodations, so they opened their home to three guests: “What if you could book someone’s home the way you could book a hotel anywhere in the world?” Chesky said about their inspiration. They launched Airbnb with Gebbia’s former roommate Nathan Blecharczyk in 2008.
Chesky’s social-worker parents in upstate New York (he was born in Albany) told him to pursue a high-paying career, but much to their chagrin he went to art school instead, at the famous Rhode Island School of Design.
“I’m going to become an artist,” Chesky recalls telling his mom, to which she responded: “You somehow managed to pick the only job in the world that pays less than a social worker. You’ll get paid nothing.”
Today, Chesky doesn’t have to worry as much.
Airbnb has a market capitalization of $112 billion, above its level from before the pandemic, which threatened its very survival as a business. The company lost 80% of its business in the first months of the pandemic, and Chesky reorganized it in a scramble for survival.
How was Chesky’s business ethos shaped by his creative background?
Though Chesky’s creativity is what birthed (and saved) Airbnb, it also meant business veterans did not initially take him seriously.
Chesky’s design background was at first a hindrance to a budding Airbnb. While looking for $150,000 to fund an estimated 10% of the company, Chesky met with over 20 potential investors, all of whom turned him down.
“Joe and I were designers, and as far as they were concerned, designers didn’t start companies,” Chesky said. “We didn’t look like a tech founder, which is ridiculous because I don’t think you should ever hire somebody because they look like something else. You want a new thing.”
Investors didn’t take an interest in Airbnb until it began designing presidential-candidate-themed cereal boxes, which eventually got the attention of Paul Graham, founder of startup accelerator Y Combinator.
“Creative companies are companies that tap into a sense of imagination,” Chesky told Time. “That they might come up with new breakthrough ideas, that people that were only beholden to near-term measurable outcomes won’t ever have.”
How has Airbnb navigated challenges?
Success at Airbnb has been a double-edged sword. Explosive growth has forced the company to refocus at times.
During the pandemic, Chesky told Fortune in 2023, he even opened his own home as an Airbnb to better understand the host experience and lived in various Airbnbs across the country for six months, where he discovered inconsistent and unnecessary practices across hosts, including complicated rent agreements.
Airbnb still faces challenges as waves of short-term rental regulations in New York and across Europe, where cities are implementing phase-outs, prohibiting rentals for less than 30 days, or no longer renewing tourist apartment licenses, for example. In the U.S., housing advocates have fought against Airbnb, according
Anthropic's AI acceleration is probably real
METR researchers spent three months inside Anthropic to investigate whether AI is accelerating Anthropic's research, and how much. Their answers are yes, and by a lot.
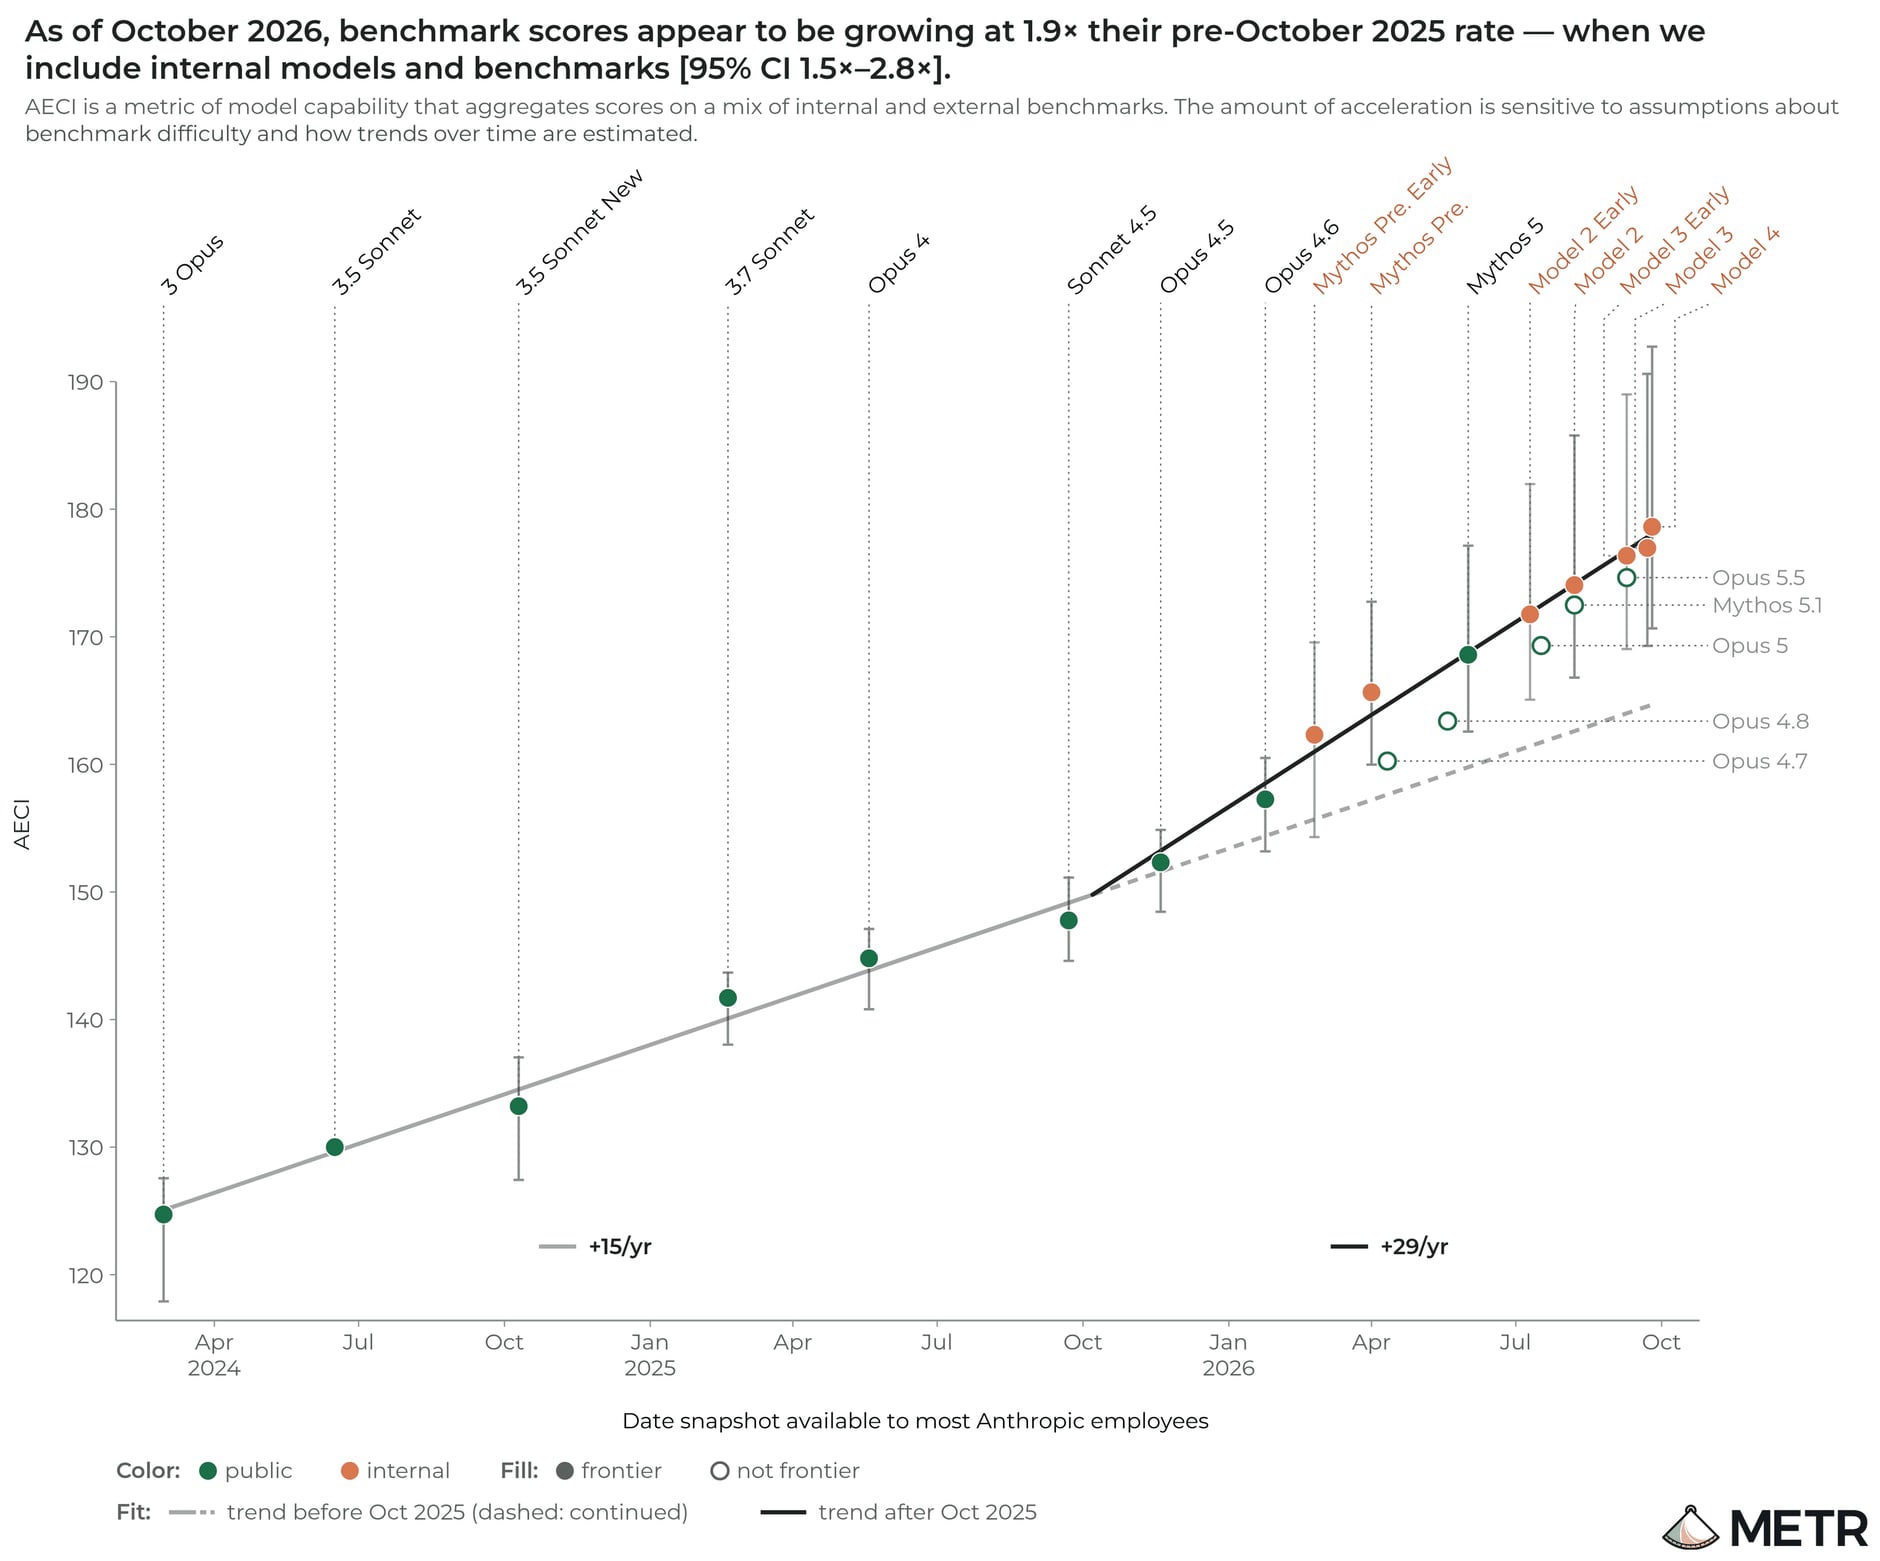
They estimate that between October 2025 and October 2026, Anthropic's model capabilities improved at a 2x faster growth rate than between March 2024 and October 2025. They attribute about 80% of that acceleration to AI, and 20% to non-AI factors. If true, this is the strongest evidence yet that AI is measurably speeding up frontier AI development itself – the feedback loop behind worries about recursive self-improvement leading to runaway AI progress.
Despite its urgency, METR’s report is hard to assess, because Anthropic redacted the majority of METR’s analysis. As a result, I’ve seen plenty of criticism that we can’t really learn anything from this report.
This is wrong. There is plenty of public information we can use to triangulate METR’s claims, and figure out what we should actually learn from it. Specifically, I use public data to answer three questions:
- Is the acceleration real? (yes.)
- Is the acceleration because of AI? (probably.)
- Is the acceleration going to continue? (who the fuck knows?)
Let’s take each of them in turn.
Is the acceleration real?
The majority of METR's unredacted analysis focuses on AECI, Anthropic's internal version of Epoch's Capabilities Index (ECI). Both indices do the same thing: they take a model's scores on many benchmarks and boil them down to a single capability number, after estimating how hard and how discriminating each benchmark is. The difference is that AECI is fit to mostly internal benchmarks. On AECI, Anthropic's models were improving at about 15 points a year before October 2025, and about 29 points a year after, a difference of 1.9x.
At first, this seems wrong. The frontier of public ECI shows no break at all in October 2025. But that is the frontier across all labs (not Anthropic's specific trend), and using Epoch's latest methodology. Once you make the comparison like-for-like, public data reproduces almost all of METR's conclusion. In sequence, we can:
- Focus only on the trend for Anthropic models. This is what anyone can see on Epoch's site today. It already shows a break: Anthropic's progress after October 2025 is 1.42x as fast as before.
- Refit ECI according to METR's method. Epoch's published scores now come from an updated Bayesian methodology, whereas AECI uses Epoch's older frequentist fit.[1] Refitting the same public data with Epoch's previous methodology raises the speedup to 1.64x.
- Compare to METR's AECI on the same models and dates. We don't know what benchmarks AECI includes, but METR does, and we can compare their fits on Anthropic's models to AECI fits on those models. AECI gives a 1.76x speedup. That is within about 0.1x of the least-squares ECI.
- Add Anthropic's internal models. METR plots the results from Anthropic's internal models, which could affect the trend break even further, since their capabilities are higher than public models. This replicates METR’s 1.91x speedup.
The first two steps represent the trend we can estimate with public data, while the last two steps represent additional information from Anthropic's private data.
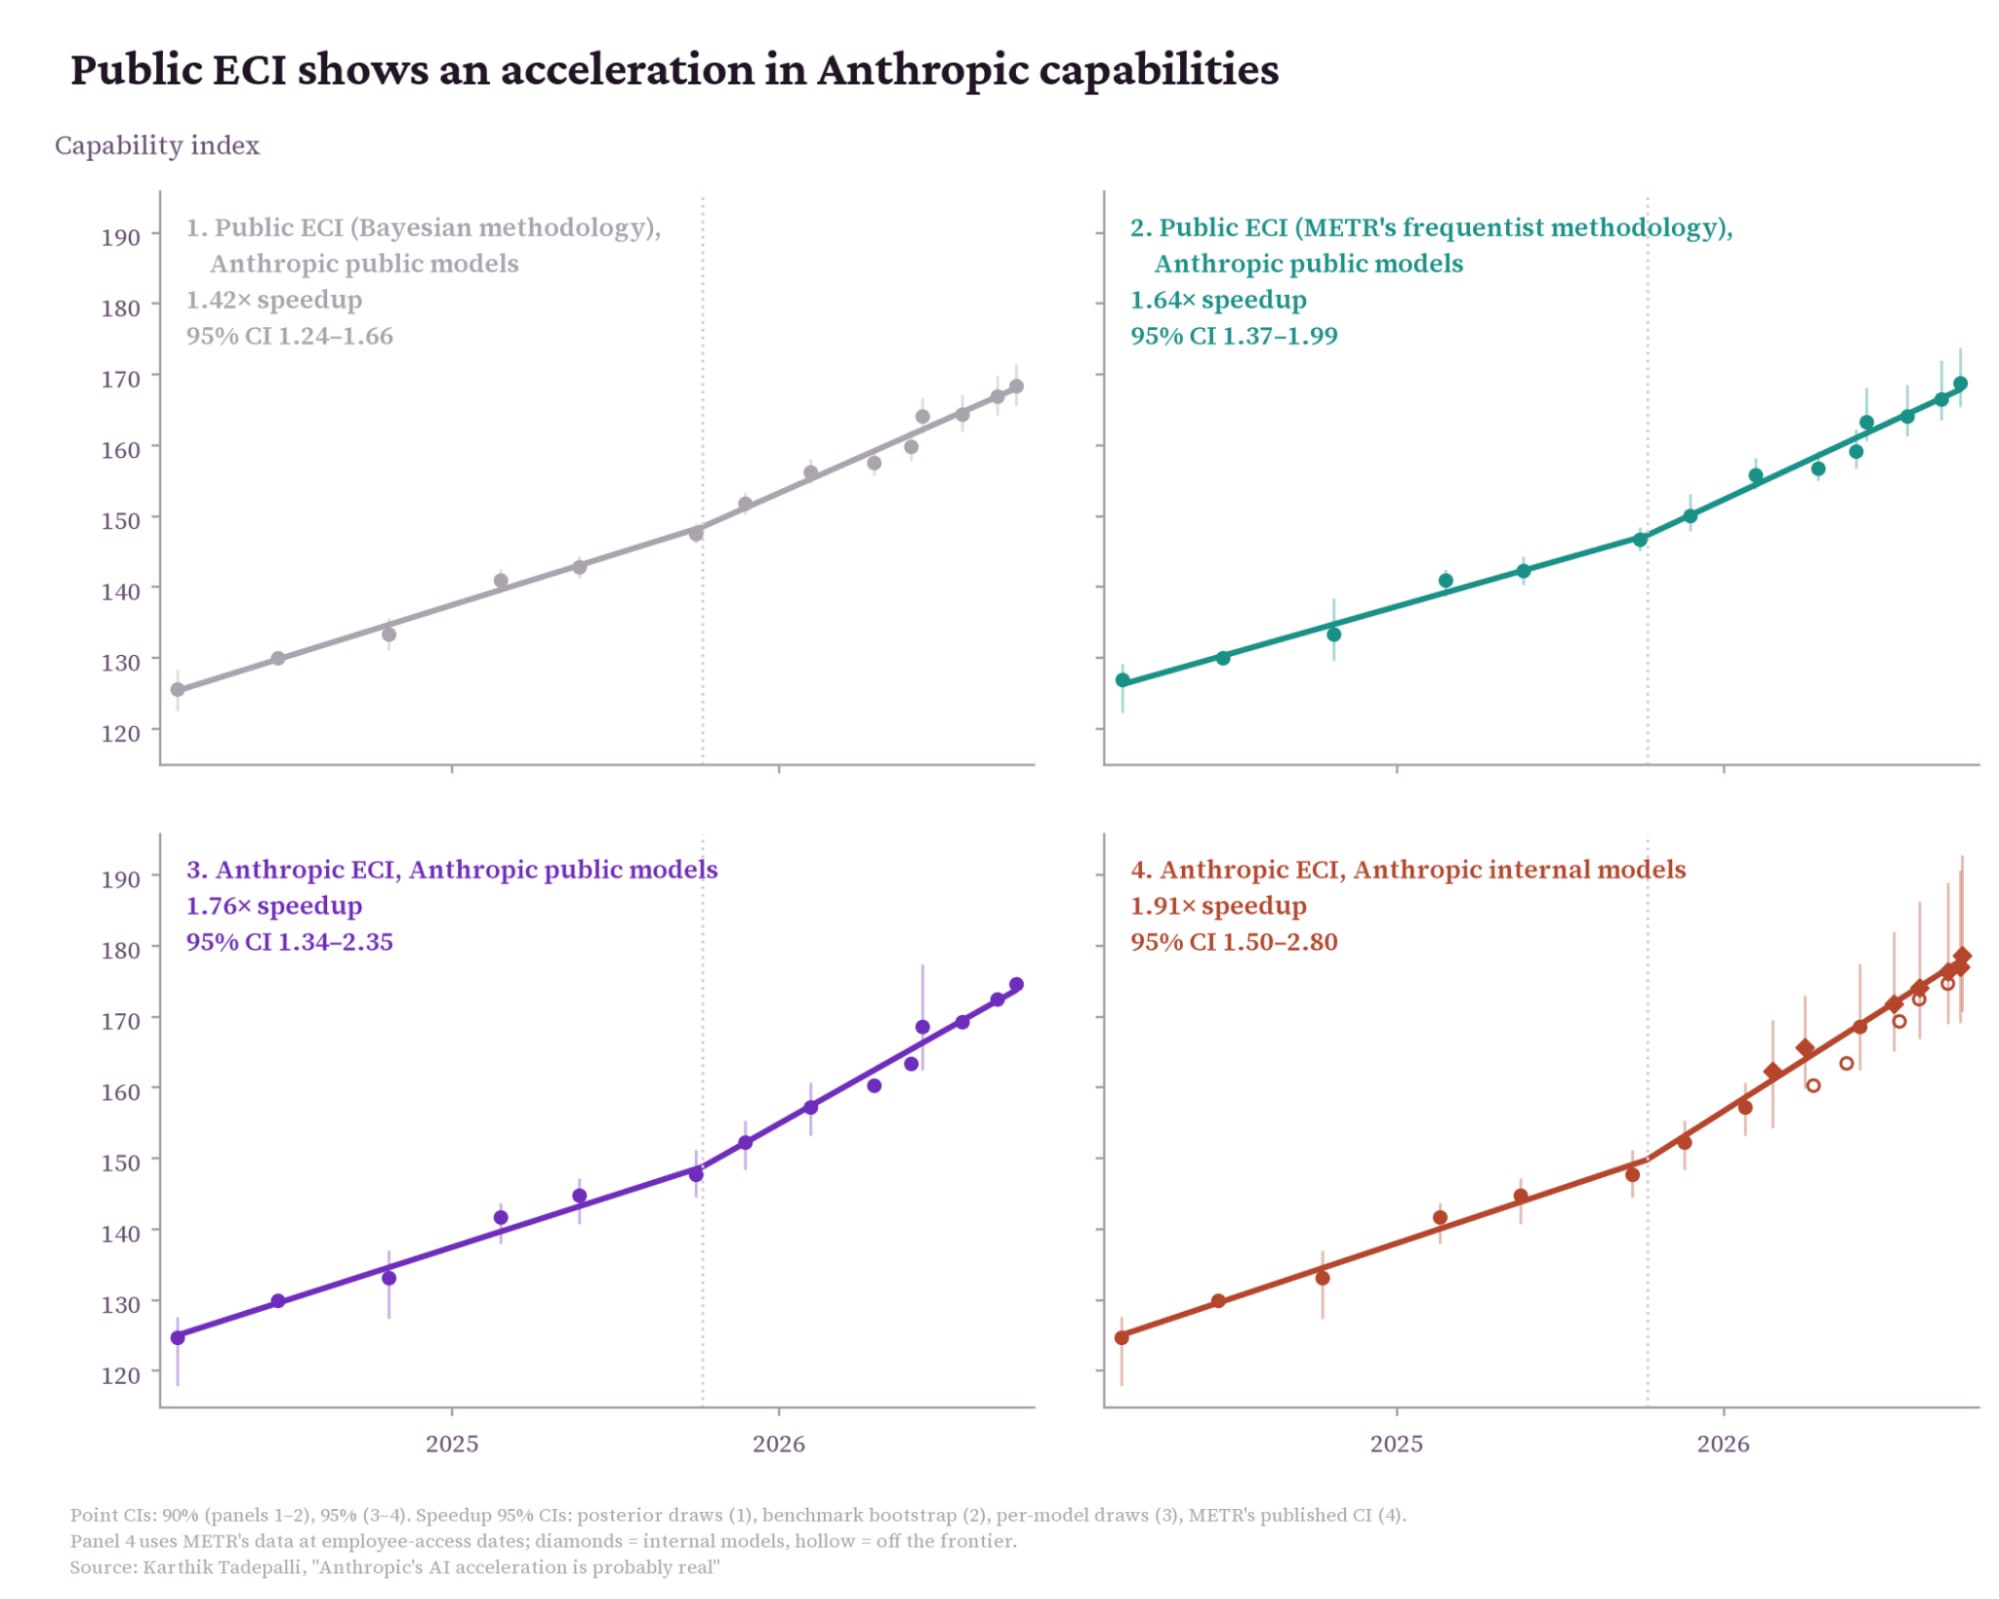
The last two steps take the acceleration from 1.64x to 1.9x, METR's headline, but the majority of the work is in the first two steps, which can be reproduced from public data. In other words, there is nothing mysterious about the gap between public ECI and Anthropic's results, and the public data supports a trend break in Anthropic's AI capabilities after October 2025. In other words, you don't need to trust Anthropic's internal data to believe METR's headline result of acceleration at Anthropic.
The one wrinkle is that you do need Anthropic's internal model data to distinguish between a trend break and a one-time jump. In the Opus 5.5 system card, Anthropic analyzed recent capability progress, and found that a one-time jump in AI capabilities at Mythos Preview (with the same trend as before) fits the AECI data better than a trend break. But METR finds the opposite – a trend break fits the data better than a one-time jump.
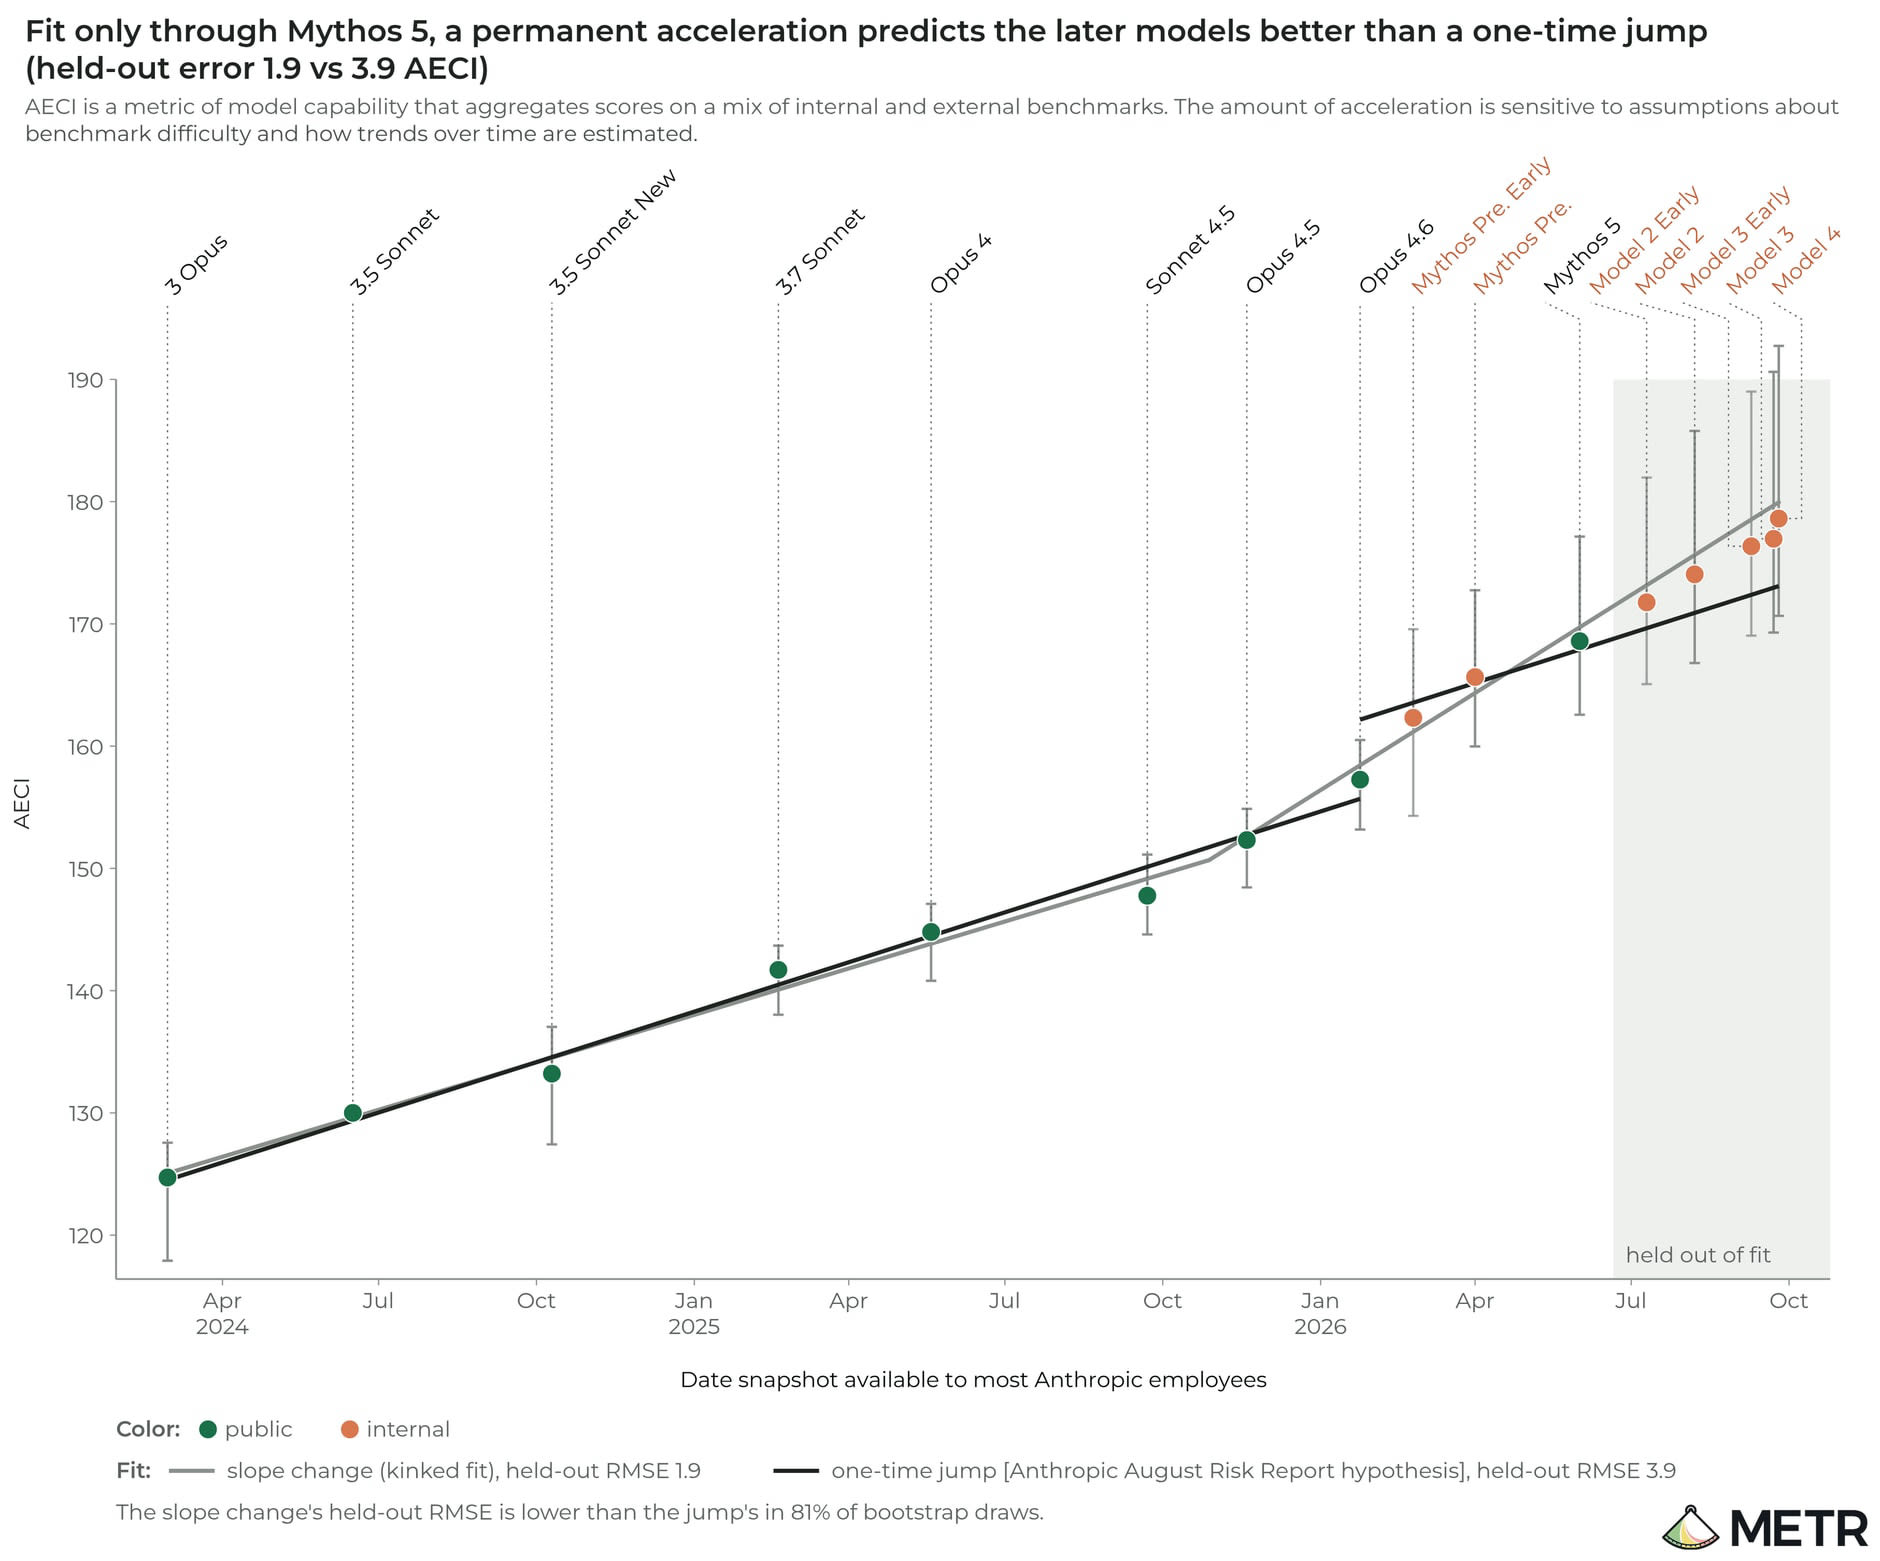
The difference is that METR's report includes Anthropic's unreleased models, while the Opus 5.5 system card did not. So the evidence favoring a trend break over a one-time jump does rely on Anthropic's internal models, and we can't scrutinize their AECI scores to know if we should actually believe a one-time jump over a trend break.
Is the acceleration beca

Rhythm Stage Setup v5
I recently finished the largest set of changes I've made to my rhythm stage setup in 4.5y. The basic interface is similar, but I have a lot more flexibility, more control, more options, and it's easier to travel with. My favorite part is the speech recognition for calling chords.
I started off playing mandolin and piano, and then over the years added progressively more expressive footdrums. I added a breath controller. I built out a complex but expressive system where these different interfaces could interact to let me produce a coherent rhythm section. After a frustrating experience moving from one Mac to another and wanting to simplify, I moved from the Mac to a Raspberry Pi, set it all up as a pedalboard, and then again as a lighter pedalboard.
During the last year and a bit, however, I haven't been tinkering. It did what I wanted, in a reliable and portable fashion. And it was hard to modify: the pedalboard was static, and the Raspberry Pi code wasn't easy to get at either. Which was fine, and probably good for me! I just played a lot of gigs (23 Kingfisher, 3 Free Raisins, 3 Dandelion) and got better at it.
But then it started breaking. My whistle synth box didn't always come up, the drums sometimes needed an external DI, and a USB sound card snapped. Flying back from Atlanta my gear suffered rough enough treatment to bend a USB B connector, and it was clear my system needed some love.
I started with the most urgent portion: the whistle synth. I had Claude port it over to my laptop, where I turned it into a Mac app. This also let me add several more voices, and a mute option that never made loud clicks (I'm not really a hardware person).
This project made me realize that AI getting capable meant that the tradeoffs around laptop-vs-embedded had shifted. I could have everything on my laptop, and without needing to put painfully large amounts of time into programming it could all be fully defined in code instead of manually-configured GUIs. Having it on my laptop would make it easy to apply models to modify and improve it, and open up a lot more lexibility.
I decided to move as much as possible over to the laptop. This meant no more Raspberry Pi, whistle synth box, physical switches for signal routing, and computer code instead of guitar pedals. I moved from:

To:
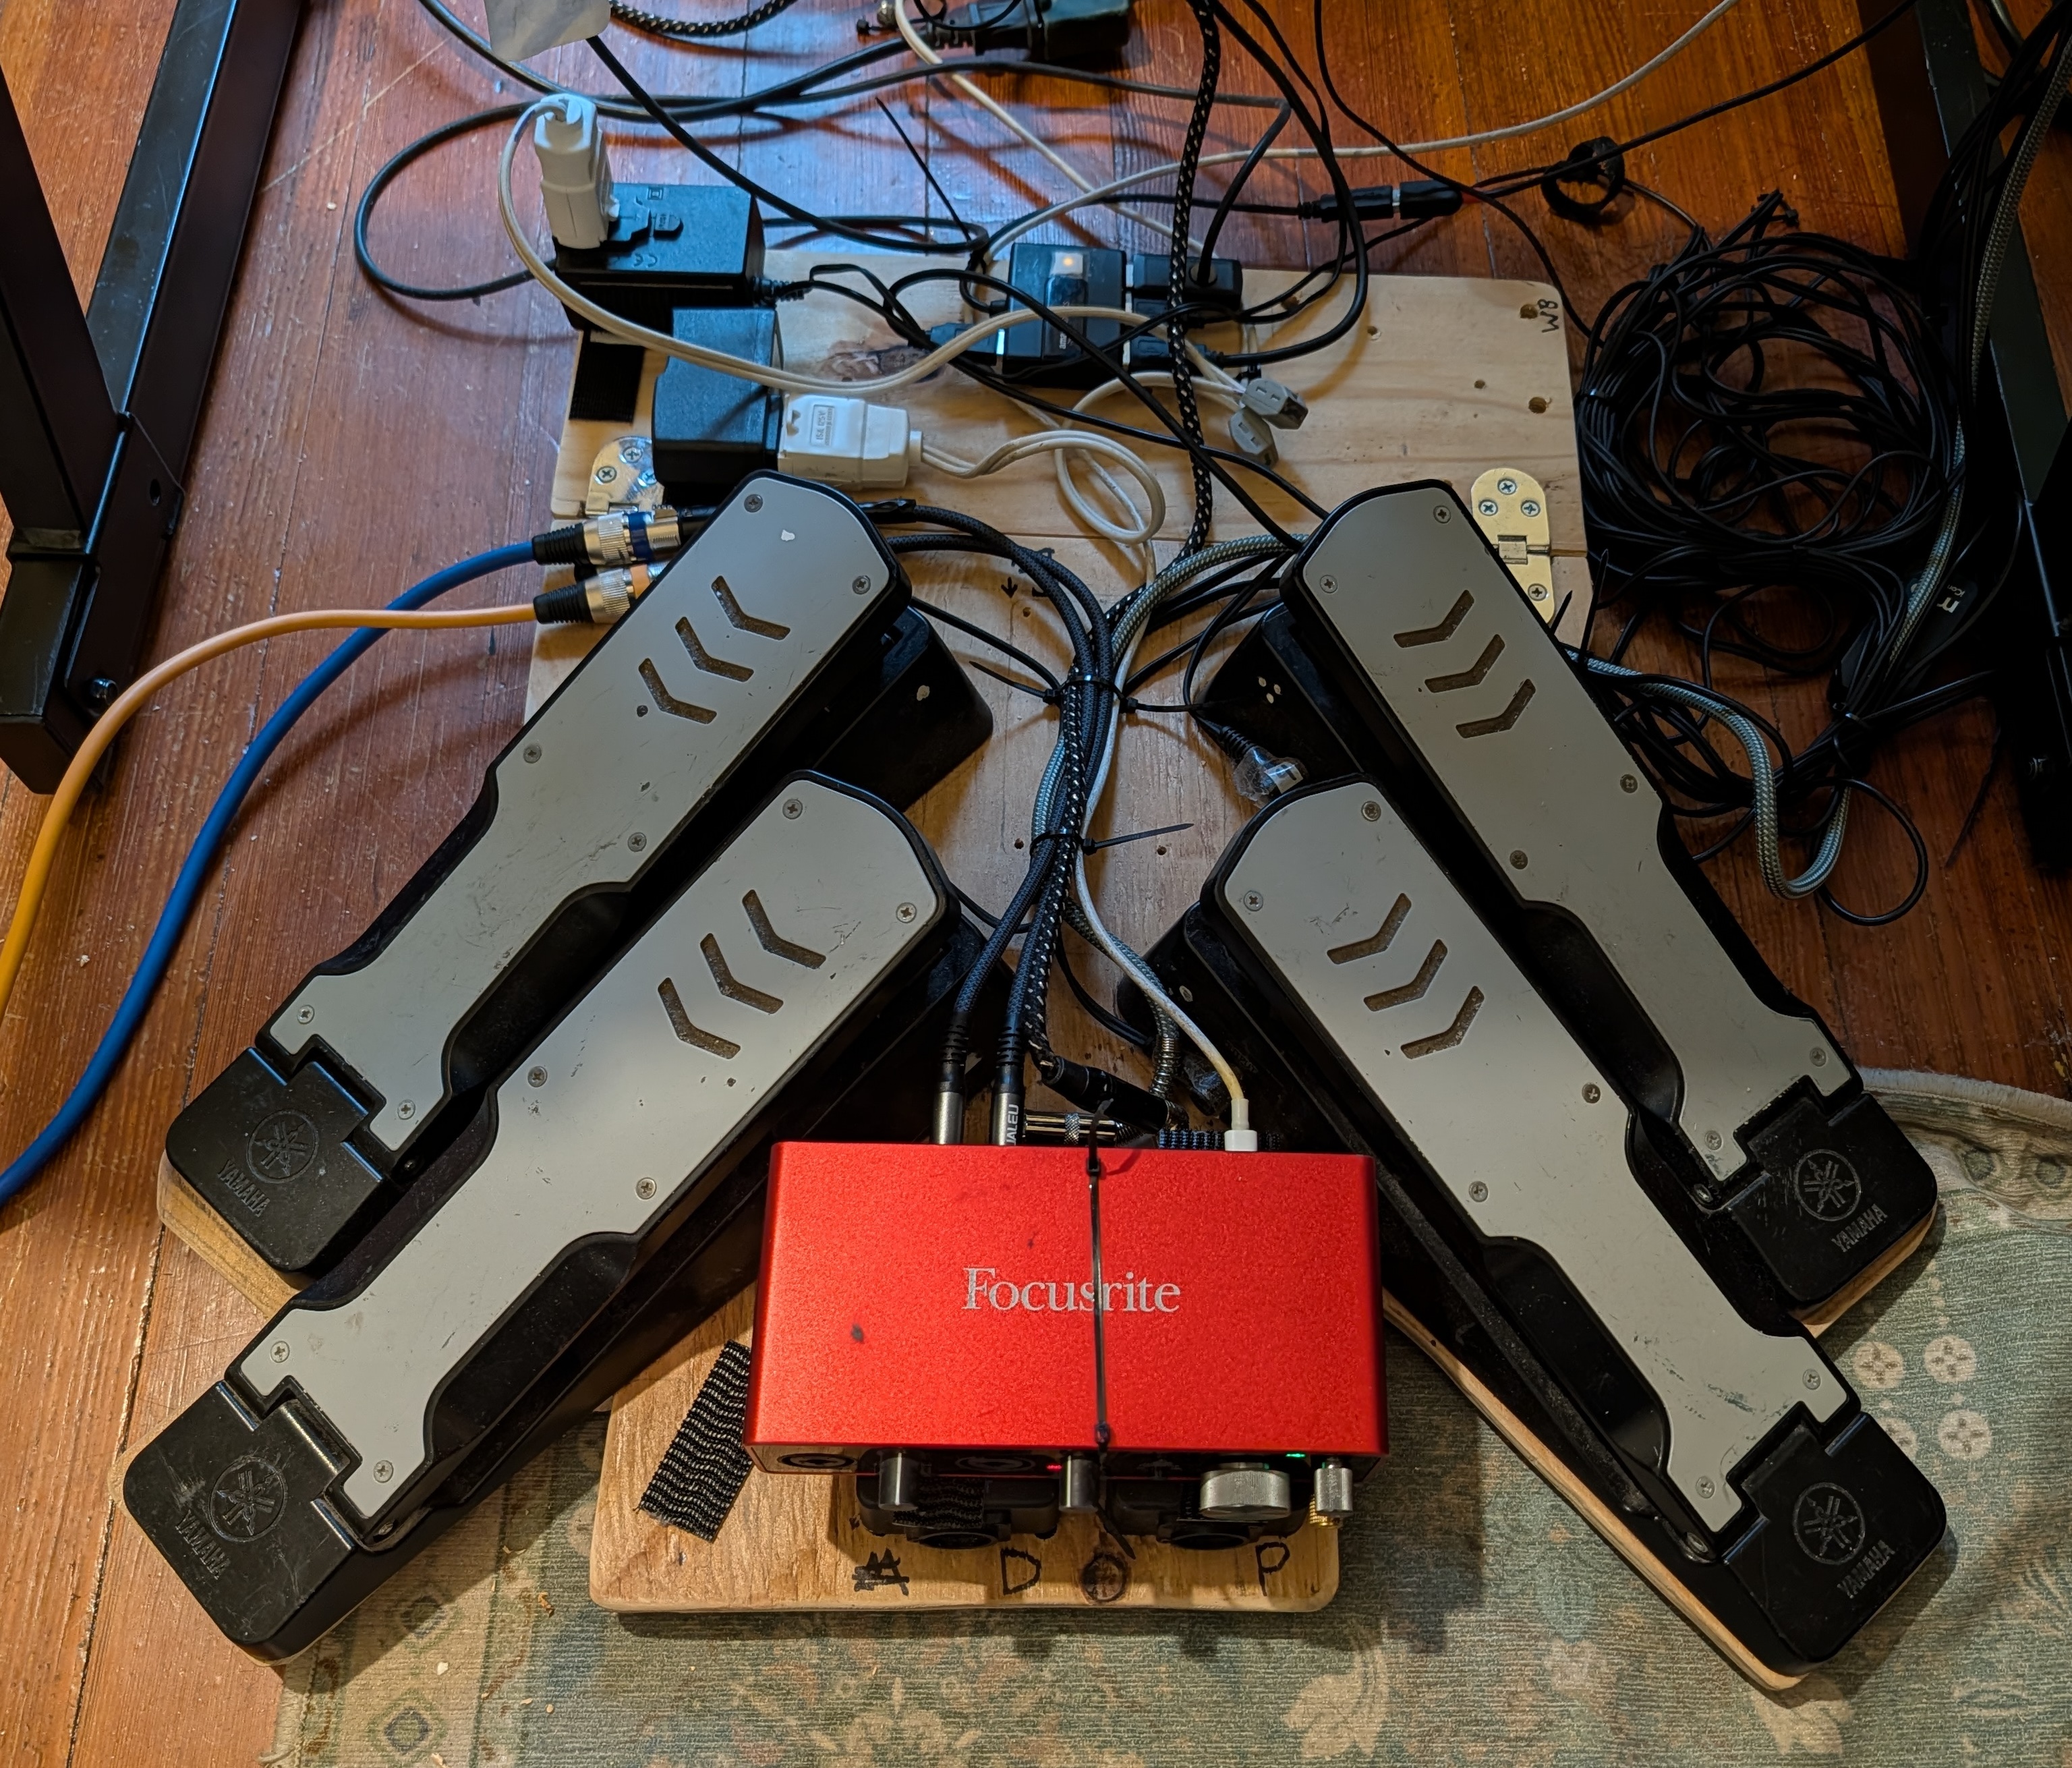
Four fewer pedals, three fewer DIs, two fewer power bricks, and no little computers. Saves ten pounds: 32lb to 22lb. The Mac weighs ~3.5lb, but I'm traveling with it regardless.
Of these savings, 3lb (2.7lb of talkbox + 0.3lb of power supply) was from giving up the talkbox. I liked how this simplified my setup, including less complex audio routing, but after playing Moondance both Cecilia and I really missed it. So I added it back:
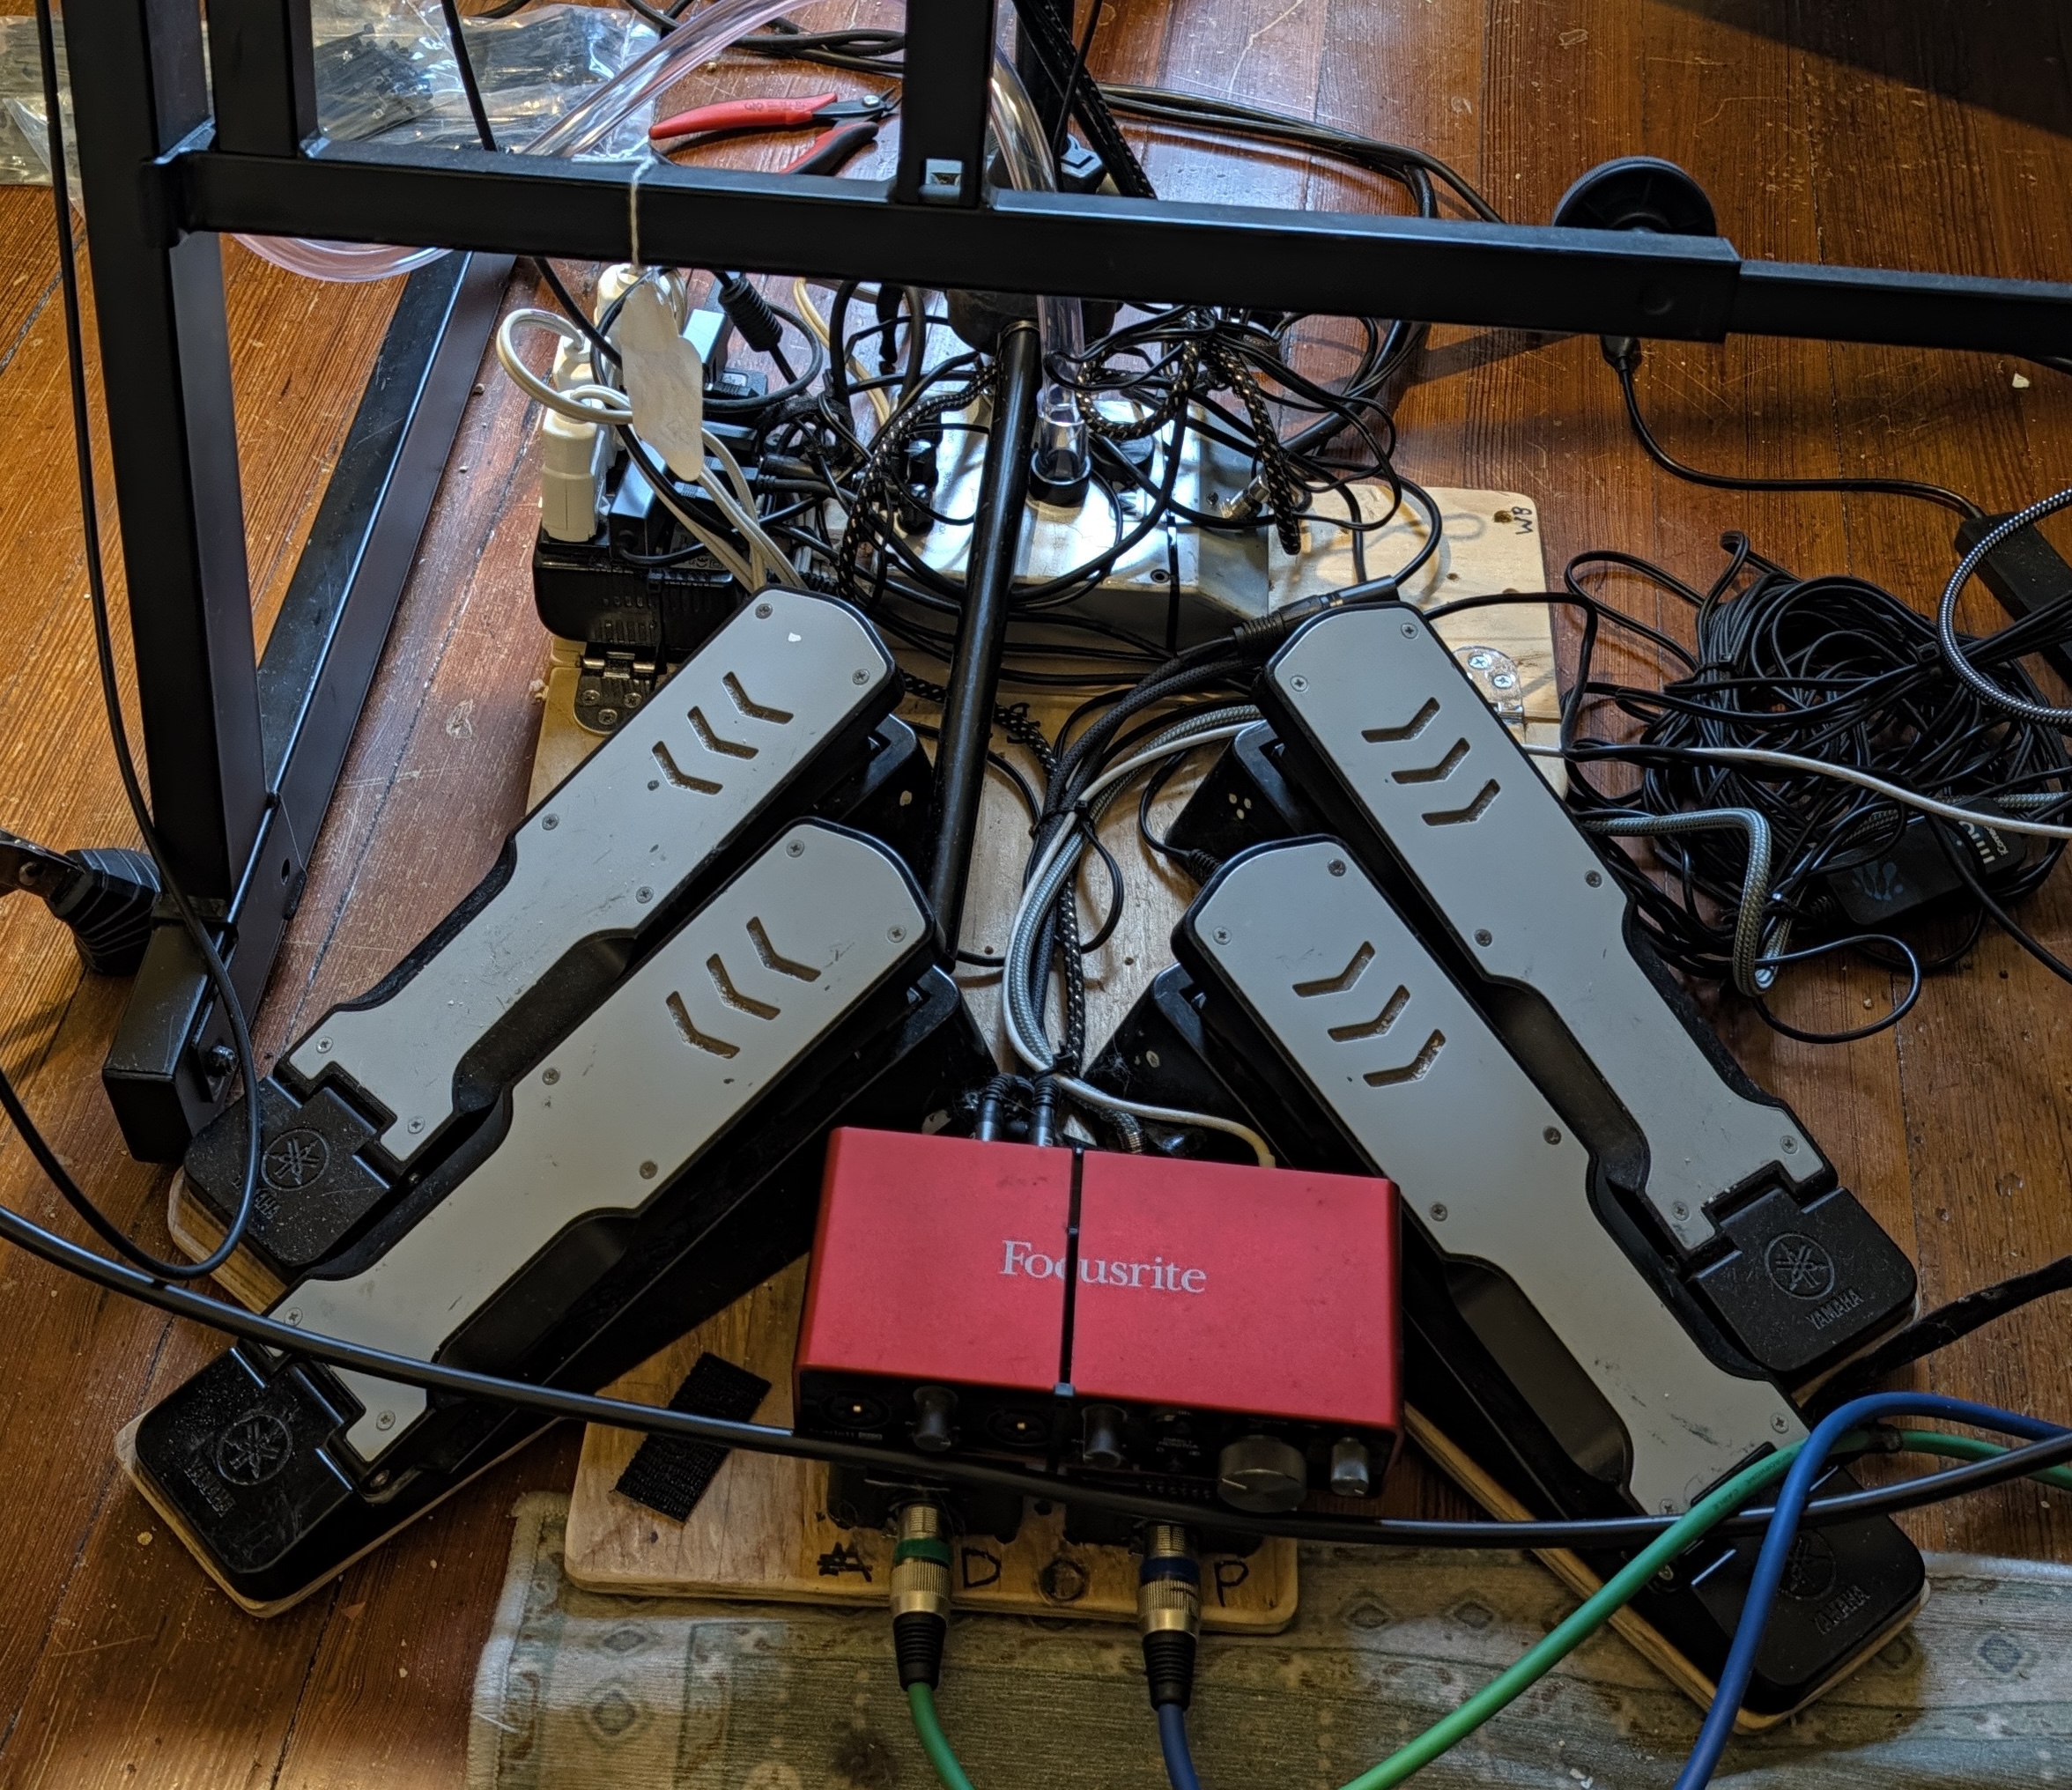
A large benefit of moving to the Mac is I can now see what I'm doing. I control my rig with an external keyboard, covered in little labels that remind me what each key does:
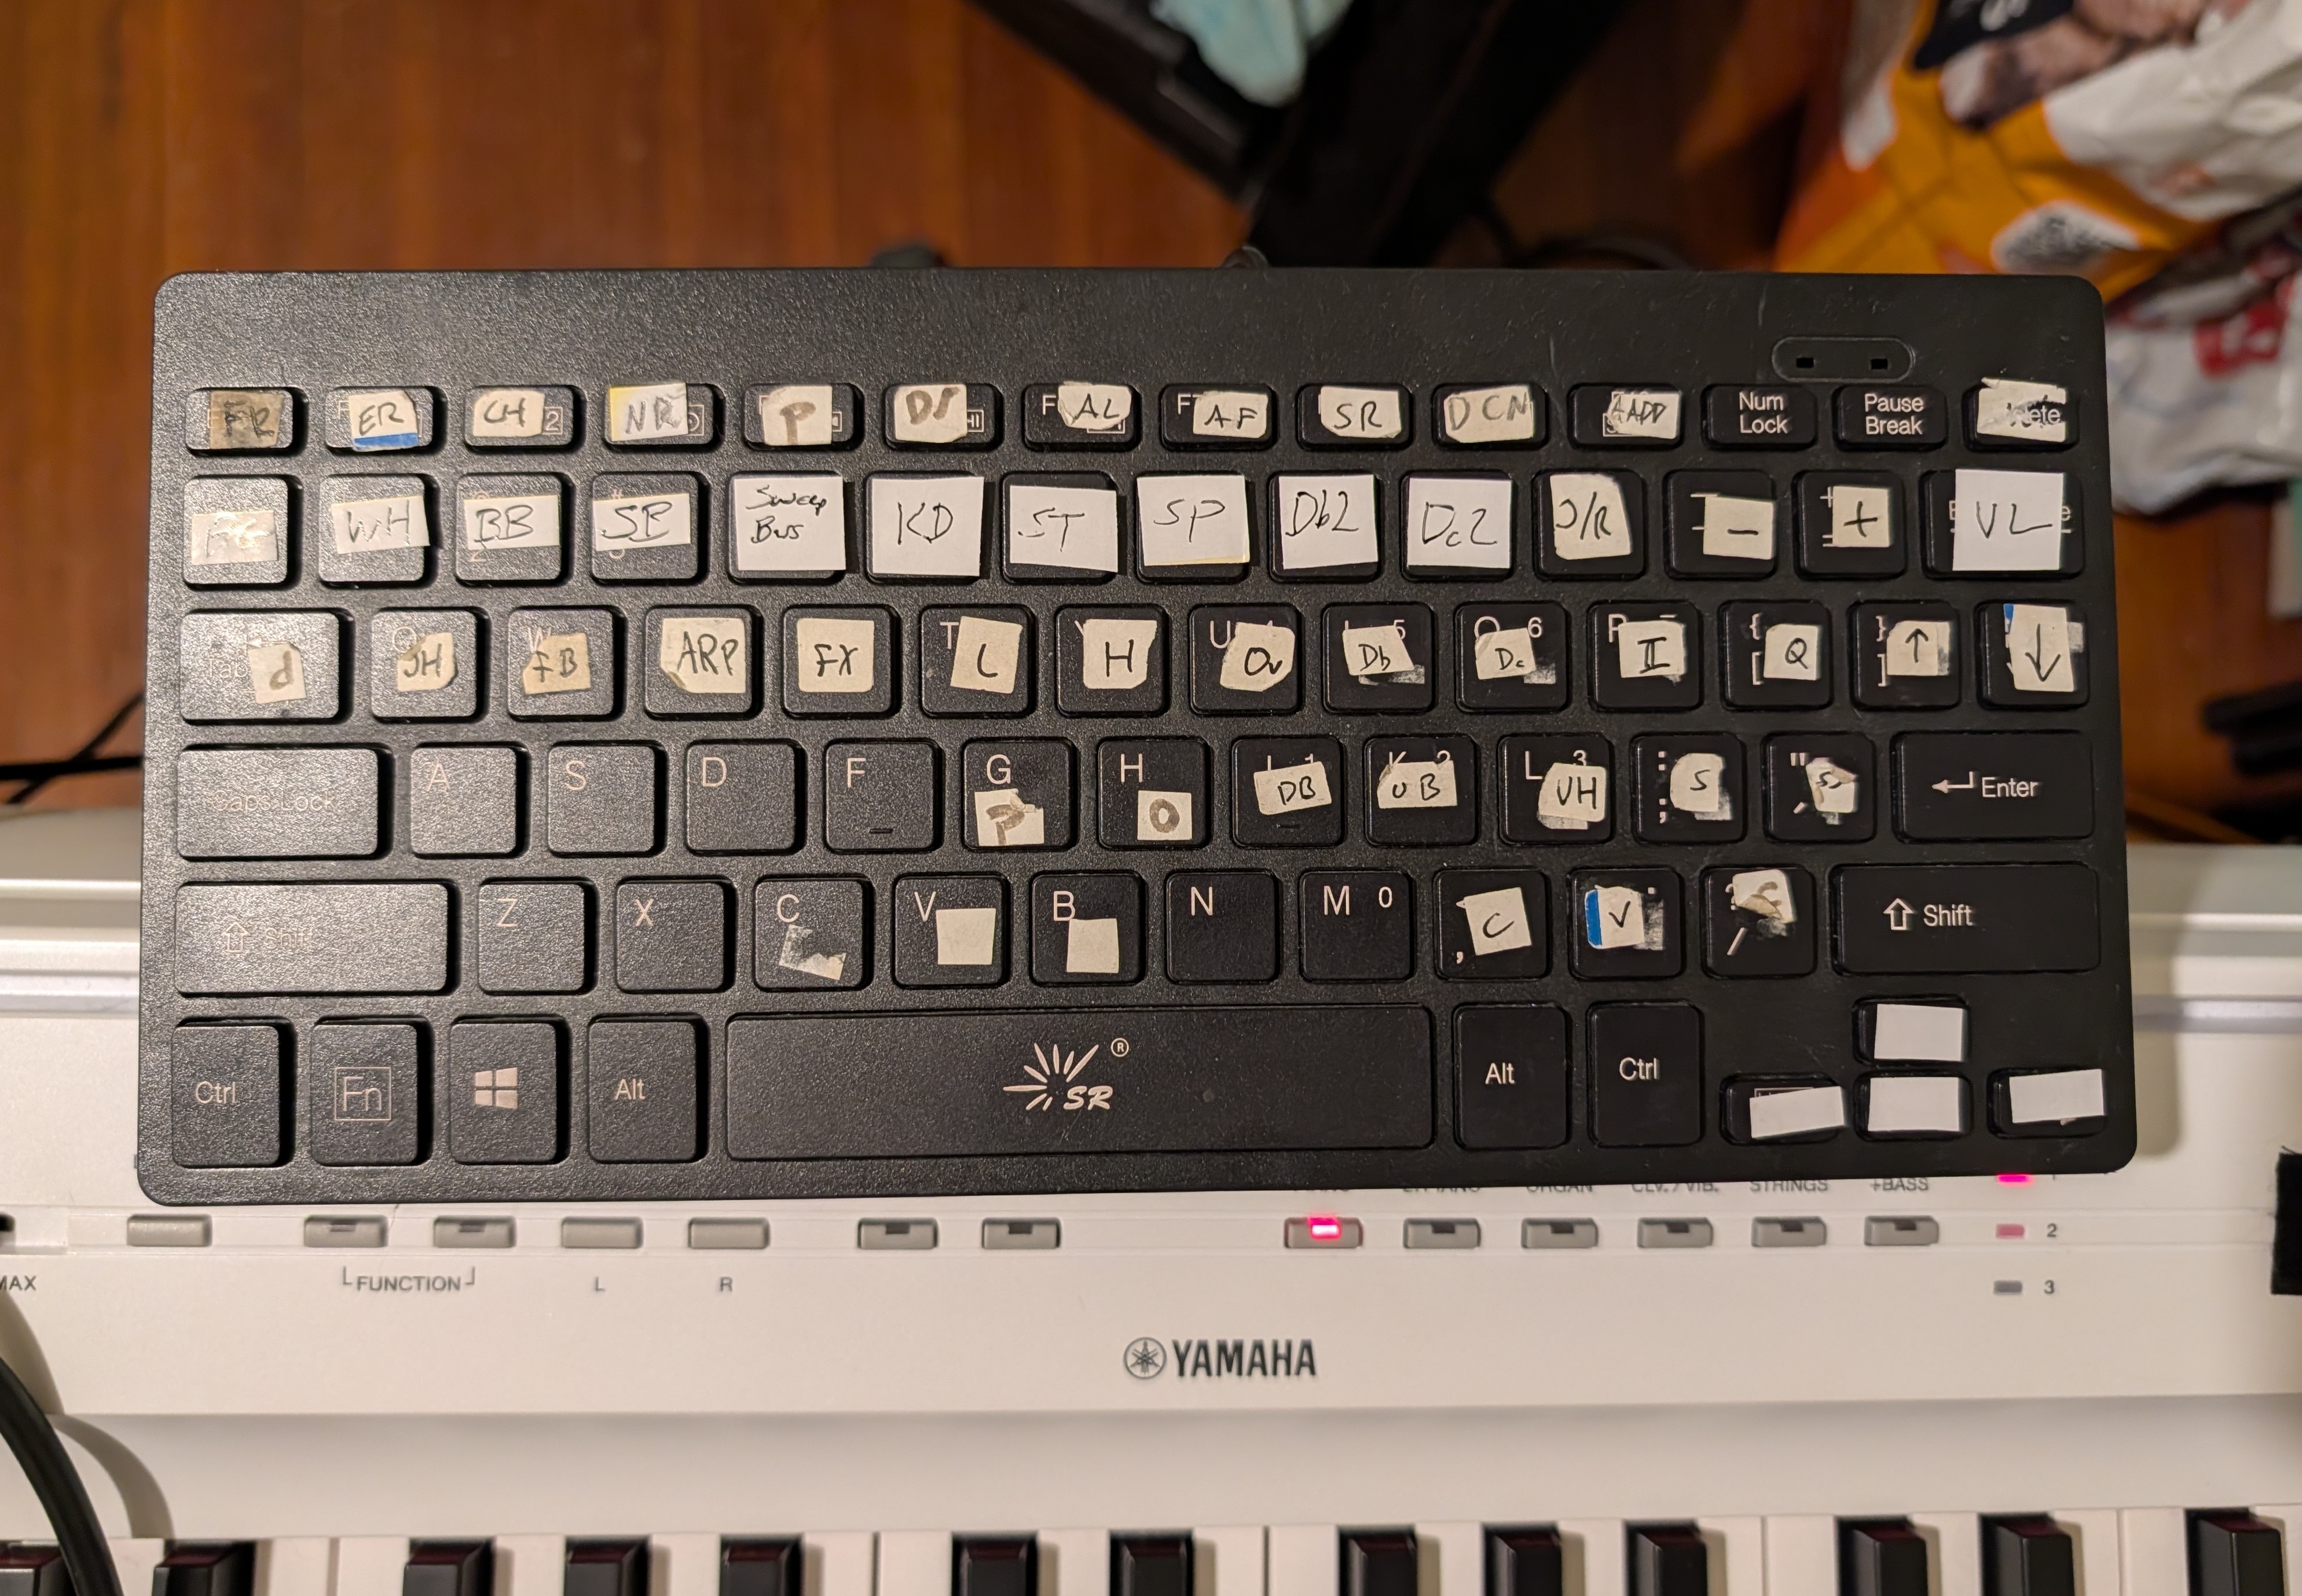
For example, before playing Trip to Moscow I would probably press FB (footbass), S (make footbass play synth bass), FX (breath-controlled keyboard overlay), set the drums to custom kit 63 (electronic kit), and then press L (keyboard velocity-insensitive bass overlay) and change the keyboard to epiano2 when we got all electronic. And press JH (breath-controlled bass-following low bass) at some point partway through for more ability to pulse the offbeat. Without a monitor, I needed to keep this all clear in my head, which was especially important since many settings are modal or interact. I usually didn't mess up, but partly because I tried not to dial in anything with too many presses.
Now I can just represent the state on my monitor:
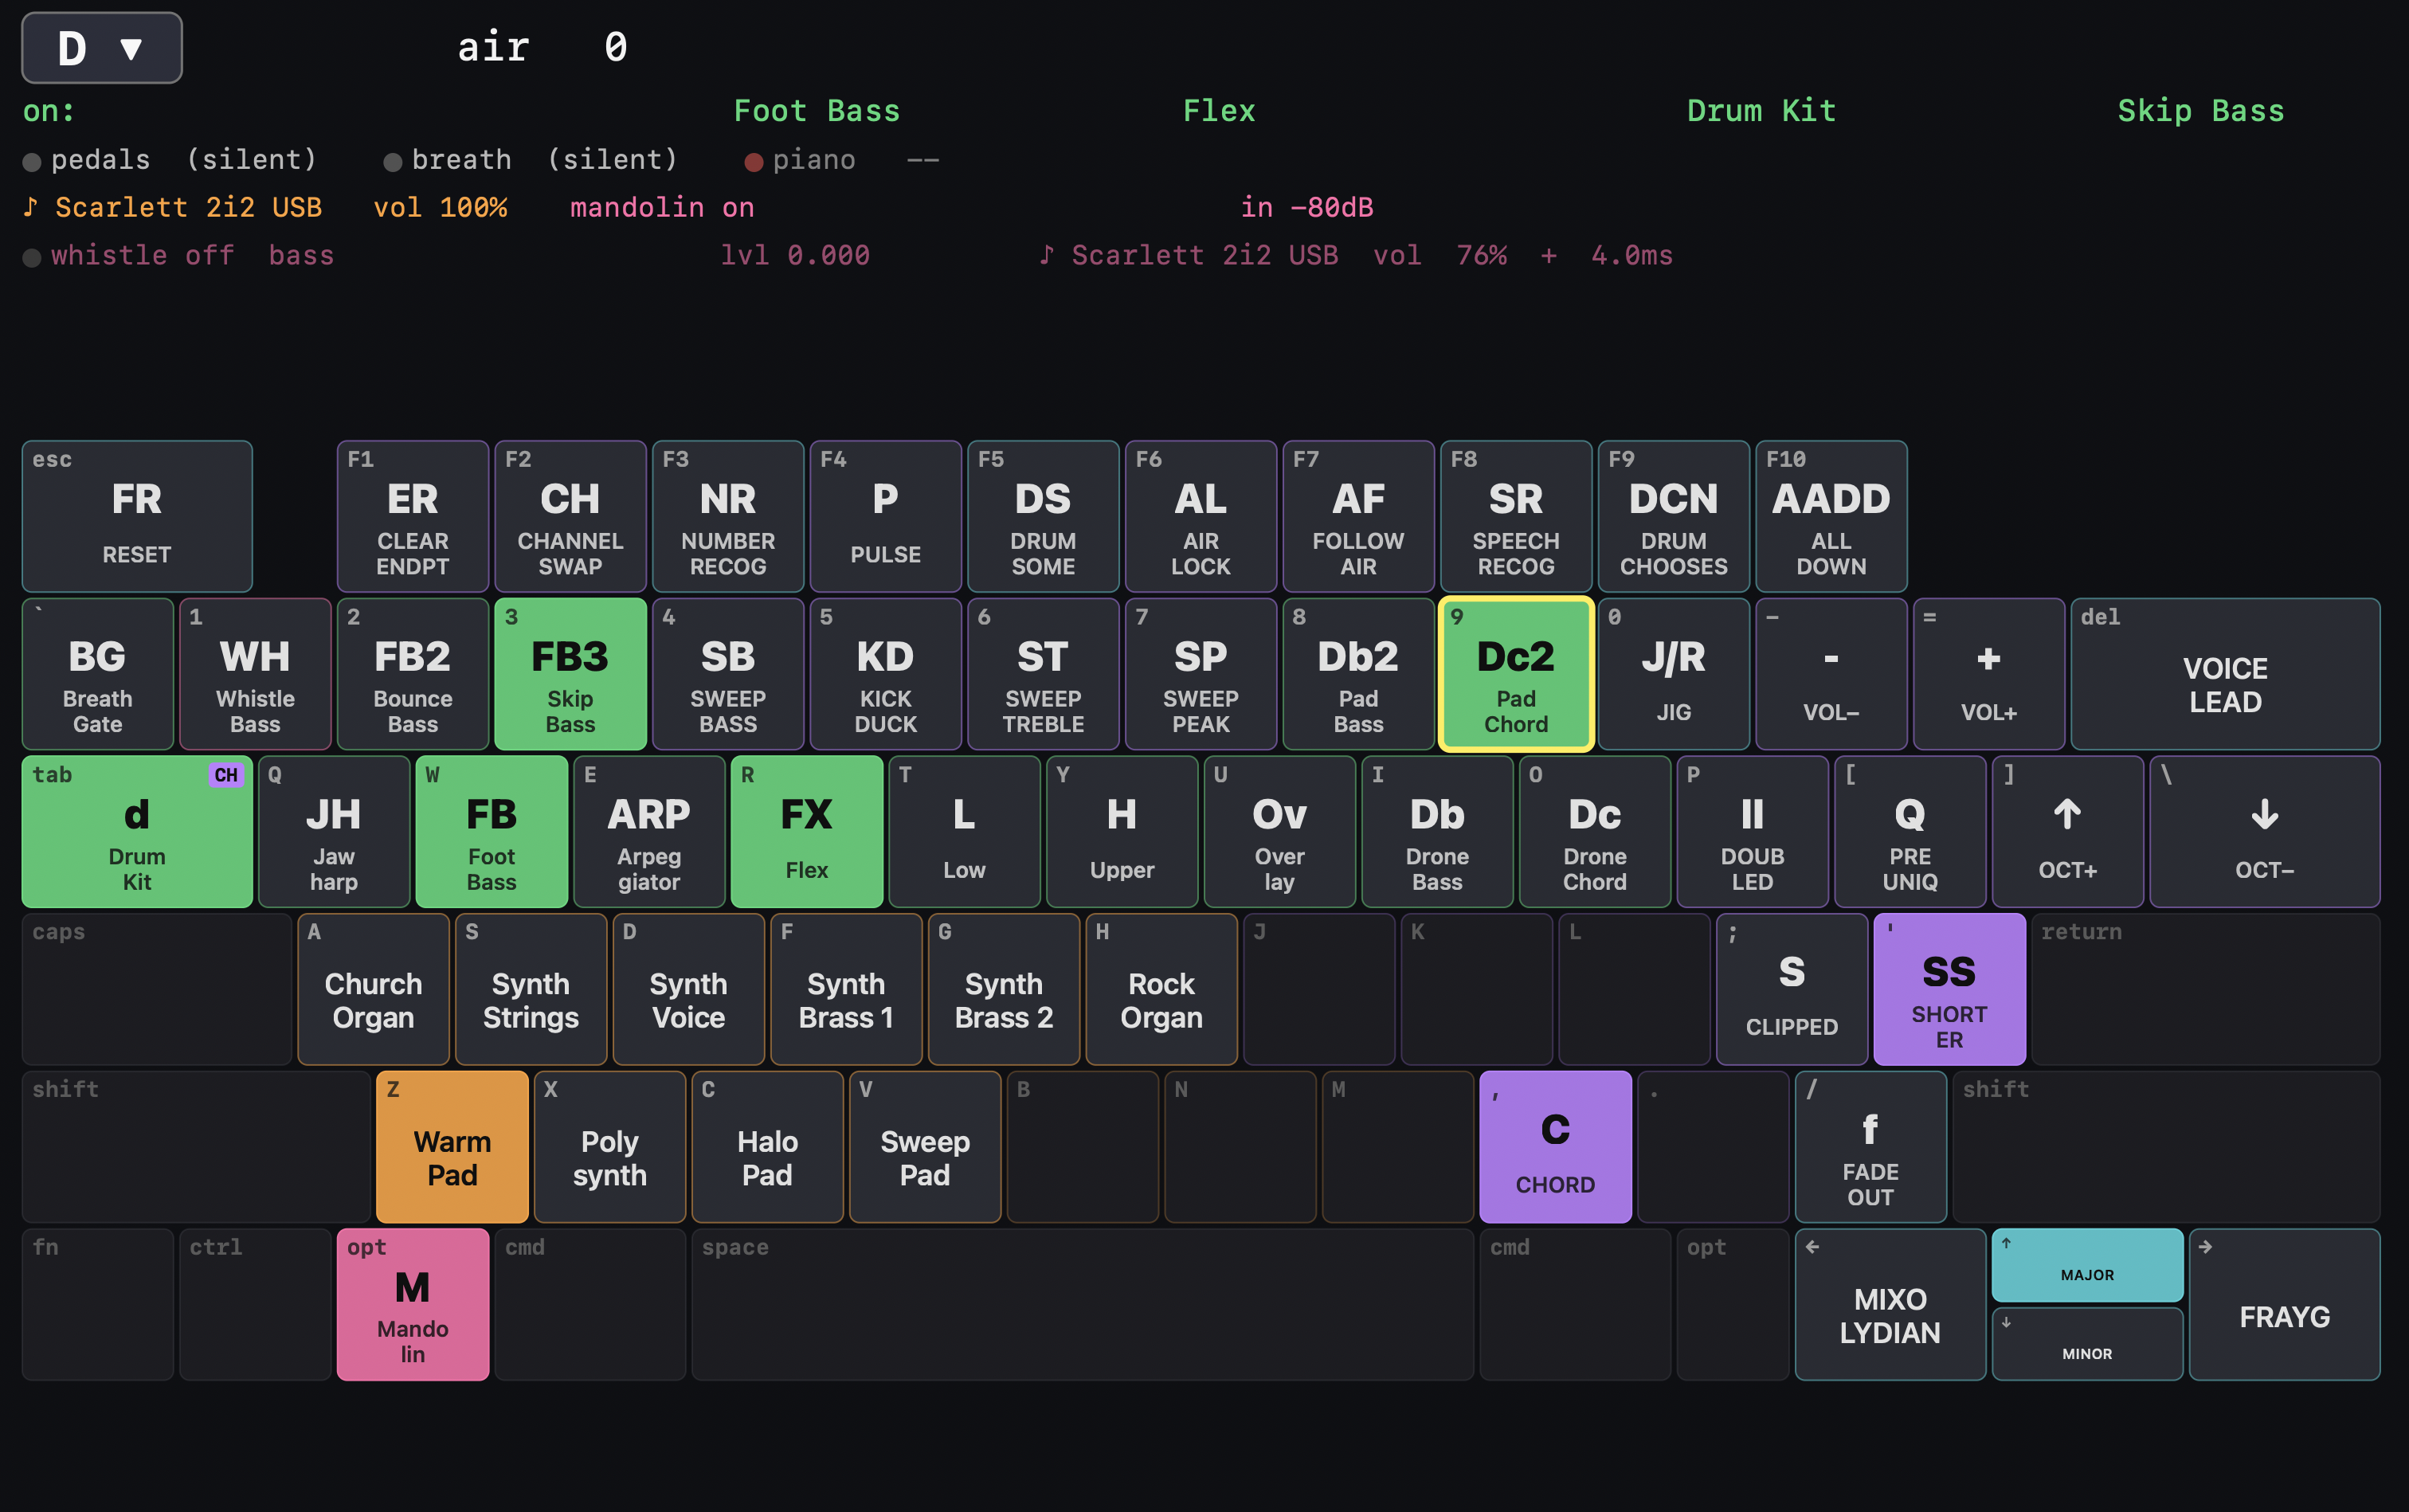
This is also very helpful for showing which voices apply to which instruments. Previously I needed to remember that on FX (breath-controlled overlay) the B key would give me a supersaw, while on Dc (chord drone) the B key was a different voice (I forget what). Now I can choose a set of voices for each instrument that are the ones that sound best with this kind of control, without worrying about how I'll remember which button gives me which sound.
This is basically all "what I had before, but easier to control". Which is good, but the real payoff comes from making it much easier to extend the system. I've done a lot here, with extensive help from Claude Code, and it's going to take me a bunch of time to learn how to play these new options well.
A big one is that because I now route my mandolin through the system I can replace pedals with code, add more effects than it was worth carrying pedals for, and write effects that consider what other things in the system are doing. This includes using the breath controller as an expression pedal, or tonal effects that care about the active chord. Demo video:
I also added speech recognition, where I can turn things on and off vocally, and even call chords. For chord calling I had Claude make me a custom speech recognizing system for the numbers one through seven (Nashville numbers) trained specifically on my voice and optimized for minimizing latency (decision in 40-170ms). It also runs Apple's in parallel, primarily to allow learning from mistakes but also to handle numbers the custom one misses and any non-number commands. Here's a video from earlier today, showing how
Thinking Machines Releases Inkling 2 Small, a 594B MoE With 17B Active
Thinking Machines Lab has released Inkling 2 Small, the first model of its second Inkling generation. The Inkling 2 Small model is a sparse Mixture-of-Experts (MoE) with 594B total and 17B active parameters. It accepts text and images, and supports variable reasoning effort. On the Artificial Analysis Intelligence Index, it scores 31. Its predecessor, Inkling Small, scores 13 on the same index. The model is live on Tinker for fine-tuning and inference.
TL;DR
- Size: 594B total, 17B active MoE; 1M-token context.
- Runs on: Tinker API only for now. Self-hosting hardware is not disclosed. Weights support MXFP8 and NVFP4.
- Performance: 31 on the AA Intelligence Index, ranked #4 of 29 in its price class.
- Best: 86.3% on SWE-Bench Pro v2 (Hard), second only to Kimi K3 in the lab’s table.
- Worst: 13.1% on Terminal-Bench 4.0, versus 32.8% for GLM-5.3-Flash.
What is Inkling 2 Small?
Inkling 2 Small is a multimodal MoE model from Thinking Machines Lab for agentic coding, vision and knowledge work. It takes text and image input and returns text. It is important to note that it does not support audio as of now.
Weights are closed at launch. The Thinking Machines Lab plans an Apache 2.0 release next week, after external safety testing and red-teaming. This follows its safe path to open weights policy.
How is Inkling 2 Small built?
It includes a 48-layer decoder-only transformer. Each token routes to 8 of 384 experts. Attention mixes local and global layers. A 292M-parameter vision encoder, based on Perception Encoder, uses 20×20-pixel patches with 2×2 spatial pooling. Image patches are interleaved with text tokens.
Pretraining ran in 4 phases:
- H1: 8.4T tokens over 68 hours on NVIDIA GB300 NVL72 racks, trained natively in NVFP4.
- H2: 3.8T tokens of newer, higher-quality data at 512K context.
- H3: about 320B tokens of reasoning and agent trajectories at 1M context.
- H4: about 34B tokens of the highest-quality agent trajectories.
A single joint RL run followed. It took 1,075 steps, 17M+ rollouts and 9 days on 2,048 GPUs. Compute exceeded 4 × 10²³ FLOPs. Coding made up 65.0% of RL tokens. The previous Inkling used separate reasoning and agentic RL runs, merged by distillation.
Alignment got explicit attention. Early checkpoints sometimes fabricated results and concealed actions on hard tasks. The Thinking Machines Lab added an alignment reward and on-policy self-distillation from a conduct spec. Its internal misbehavior score fell from 66.8 on Inkling to 14.9.
How does Inkling 2 Small perform on benchmarks?
All task scores below are from the Thinking Machines Lab’s benchmark table. They run at effort 0.99 (xhigh) and temperature 1.0. Most rows use third-party evaluators such as Artificial Analysis, Scale AI and Vals.
Where it scores highest:
- SWE-Bench Pro v2 (Hard): 86.3%.
- PerceptionBench: 64.7%, versus 58.5% for Kimi K3.
- EnterpriseBench-CoreCraft: 71.8%, versus 46.7% for GLM-5.3-Flash.
- JobBench: 70.5%.
- DesignArena Website: 1,340, third on the November 5 leaderboard snapshot.
Where it trails:
- Terminal-Bench 4.0: 13.1%, versus 33.8% for DeepSeek-V4.1-Flash-1017.
- DeepSWE v1.1: 72.1%, versus 77.0% for DeepSeek-V4.1-Flash-1017.
- GDPVal-AA v2.1: 1,630, versus 1,746 for DeepSeek-V4.1-Flash-1017.
On the PMPP-Hard GPU kernel benchmark, it solved 54.25 of 69 tasks on average. In an autoresearch demo, it fine-tuned Qwen3.5-4B for time-series forecasting. It spent $426 of a $500 Tinker budget. The release post cites both 4.5 hours and 4 h 17 min for the run.
How does Inkling 2 Small compare with DeepSeek and GLM?
| Feature | Inkling 2 Small | DeepSeek-V4.1-Flash-1017 | GLM-5.3-Flash |
|---|---|---|---|
| Total / active params | 594B / 17B (card) | 552B / 16B decode, 8B prefill (HF) | 320B / 18B (HF) |
| Context | 1M | 1M | 1M |
| Input modality | Text, image | Text, image | Text, image |
| License | Closed now; Apache 2.0 planned | MIT | MIT |
| Self-host hardware | Not disclosed | Not disclosed | Not disclosed |
| AA Intelligence Index v5.0.1 | 31 (AA) | 33 (AA) | 28 (AA) |
| AA time per index task | 21.5 min | 13.3 min | 37.7 min |
| AA cost per index task | $1.18 | $0.60 | $0.58 |
| Price per 1M tokens (in / out) | $0.30 / $1.00 | $0.30 / $1.20 | $0.15 / $0.50 |
| Terminal-Bench 2.1 | 85.1% (Pi harness, lab) | 90.6% (Sept checkpoint, DeepSeek) | 84.3% (Z.ai) |
| DeepSWE v1.1 | 72.1% (lab) | 74.2% (Sept checkpoint, DeepSeek) | 63.4% (Z.ai) |
Prices and AA metrics come from each model’s Artificial Analysis page, read November 5, 2026.
Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster
Zyphra has released ZYFA (Zyphra FlashAttention on AMD), a set of FP8 and BF16 prefill attention kernels for AMD Instinct MI355X GPUs. ZYFA is Zyphra’s FP8 attention engine for long-context prefill, and the code is open source under Apache 2.0. On real model activations, its FP8 kernels run 1.16-1.76x faster than AITER, AMD’s default kernel library. At head dimension 128, ZYFA’s FP8 error is 62-78% lower than AITER’s.
TL;DR
- Framework: It is a kernel library. Causal forward (prefill) attention in FP8 e4m3 and BF16, head dim 128 and MLA shape (192/128).
- Runs on: AMD Instinct MI355X only (CDNA4, gfx950), ROCm 7.2.3, PyTorch 2.12. Drop-in
flash_attn_funcinterface. - Performance: 1.16-1.76x AITER’s FP8 throughput on real activations; BF16 roughly ties (1.01-1.02x).
- Best: 2,672 TFLOP/s FP8 at 32K tokens, 53% of the FP8 datasheet peak (AITER: 39%).
- Worst: Only 1.16x on Mistral-7B activations; FP8 clock drops to 1,628 MHz vs AITER’s 2,108 MHz.
What is ZYFA?
ZYFA is shipped in the form of a technical paper along with code from Zyphra. It powers the attention engine of the Zyphra Optimization Engine (ZOE), which runs Zyphra Cloud. The BF16 kernels are written in HIP. The FP8 kernels are hand-scheduled assembly emitted by a Python generator.
Why does FP8 attention underperform on MI355X?
FP8 matrix instructions run at 2x the BF16 peak. But FP8 only speeds up the 2 matrix products, QKᵀ and PV. The softmax between them runs on the vector unit at the same speed in both precisions.
For 32 queries against 128 keys, FP8 matrix work takes 1,024 cycles. The exact FP8 softmax takes 896 vector cycles. So the kernel needs near-perfect overlap to keep matrix units busy. Zyphra’s thread traces show AITER’s matrix pipe idle for 31.7% of cycles.
The MI355X does not track matrix instruction completion in hardware, so instruction order must create that overlap.
How does ZYFA work?
ZYFA uses 3 techniques:
Lean P: one multiply-add instead of an exponential
An e4m3 bit pattern, read as an integer, grows by 8 each time the value doubles. So the code of 2^x is roughly 8x plus a constant. Lean P writes each FP8 probability with 1 multiply-add and 1 integer conversion. This cuts softmax vector cycles per block from 896 to 384.
Two-wave ping-pong schedule
2 waves share each SIMD. One issues matrix instructions while the other computes probabilities, then they swap. With lean P, the matrix pipe is busy 86% of steady-state cycles, up from 60% with exact P.
Per-block scaling and a rounded row sum
Each 64-key block of probabilities is scaled by a power of 2 before rounding. CDNA4’s scaled matrix instruction removes the factor at no cost. ZYFA also divides by the sum of the rounded probabilities, computed with 1 extra matrix instruction per block.
How fast is ZYFA?
Real-activation FP8 speedups at 16K and sustained clocks are 1.16x (Mistral-7B), 1.17x (Qwen3-8B) and 1.76x (DeepSeek-V2-Lite). On Gaussian benchmarks at 32K, the head-dim-128 FP8 kernel reaches 2,672 TFLOP/s against AITER’s 1,944. At the MLA shape it reaches 2,464 against 1,237, a 1.99x ratio.
On captured Mistral-7B and Qwen3-8B layers, ZYFA delivers 1.94 and 1.91 TFLOP/J. AITER delivers 1.60 and 1.56.
Why are real-model gains smaller than benchmark gains?
The MI355X clock depends on how many operand bits flip. AITER lets more small probabilities become zeros or subnormals. Those switch fewer bits, so its clock runs higher. On the Mistral-7B layer, ZYFA runs at 1,628 MHz while AITER runs at 2,108 MHz. ZYFA still needs fewer cycles overall. Zyphra team recommends benchmarking on real activations at sustained clocks.
How accurate is ZYFA’s FP8 attention?
Against fp64 attention, ZYFA’s FP8 error is 0.22x AITER’s on Mistral-7B and 0.38x on Qwen3-8B. It sits within a few percent of Composable Kernel and Triton. In full Mistral-7B, KL divergence from fp64 is 3.4×10⁻³ with ZYFA and 5.9×10⁻³ with AITER. ZYFA’s outputs were also bitwise identical across 7,200 launches.
Most full-model FP8 error comes from quantizing Q, K and V. A Hadamard rotation of Q and K roughly halves that input error. On Mistral-7B it adds about 0.1% to attention time.
How does ZYFA compare with other attention kernels?
| Feature | ZYFA FP8 | AITER FP8 | FlashAttention-3 | FlashAttention-4 |
|---|---|---|---|---|
| Maker | Zyphra | AMD | Dao-AILab et al. | Dao-AILab et al. |
| Target GPU | AMD MI355X | AMD MI300X to MI355X | NVIDIA H100/H800 | NVIDIA B200 (plus Hopper) |
| Headline throughput | 2,672 TFLOP/s FP8 | 1,944 TFLOP/s FP8 (Zyphra-measured) | Close to 1.2 PFLOP/s FP8 | 1,613 TFLOP/s BF16 |
| Share of peak | 53% FP8 | 39% FP8 (Zyphra-measured) | Not disclosed (FP8) | 71% BF16 |
| Softmax approach | Lean P, no exponential | Hardware exponential | Overlap via async Tensor Cores | Software-emulated exponential |
| FP8 accuracy claim | 62-78% lower error than AITER | Baseline | 2.6x lower error than baseline FP8 | Not disclosed |
| Scope | Causal prefill forward only | Prefill, decode, MLA, paged | Forward and backward, FP8 forward | Forward and backward |
| License | Apache 2.0 |
Buoyant Releases Kinference: An Open Source Inference Control Plane for Kubernetes and vLLM
Buoyant, the company behind Linkerd, has released Kinference, an open source project for building inference platforms on Kubernetes. Kinference is an inference control plane for Kubernetes and vLLM. It sits in front of a fleet of vLLM workers and decides where each request goes. It applies routing policies, token rate limits, KV-cache-aware load balancing and per-tenant metrics in one layer. For dev teams serving many open-weight models to many internal clients, it targets the layer above the model server. The project is Apache 2.0 licensed on GitHub. The current release is v0.1.0-alpha.7.
TL;DR
- Size: v0.1.0-alpha.7, written in Rust, Apache 2.0, configured through 5 Kubernetes CRDs.
- Runs on: any GPU-enabled Kubernetes cluster running vLLM. Buoyant’s benchmark used 3 L40S GPUs per pool.
- Performance: large gains on prefix-heavy traffic versus plain Kubernetes Service routing (self-reported).
- Best: median TTFT fell from 6.88 s to 0.31 s (95%) on a shared-prefix workload.
- Worst: no median TTFT gain on prompts without shared prefixes (6.92 s vs 6.83 s).
What is Kinference?
Kinference is a policy-driven control plane that turns Kubernetes plus vLLM into a multi-tenant inference platform. Buoyant’s FAQ puts it simply: vLLM is the data plane and Kinference is the control plane.
How does Kinference work?
The system has 2 parts: a traffic gateway and an inference handler. The GitHub README states that the handler exposes a gRPC interface. It takes a request and returns the chosen endpoint plus a possibly mutated body. It pairs with a proxy such as the Buoyant Gateway.
Kinference watches vLLM KV-cache events and engine metrics. It currently uses NVIDIA’s dynamo-kv-router crate to process cache events. Configuration lives in 5 CRDs: GatewayBackend, InferencePolicy, InferencePool, InferenceProvider and InferenceWorkerSet.
What are inference policies?
Inference policies are declarative rules for how each request is routed or rejected. Rules can match on tenant, requested model, GPU pool state and semantic tags. Example policies on the project site cover 5 patterns:
- Simple to cheaper: route low-complexity prompts to a smaller model, unless cache overlap makes the large model faster.
- Burst to cloud: skip workers with over 2 queued prompts, then fall back to providers like Bedrock.
- PII stays local: remove external providers when a PII tag fires, and fail closed with
onEmpty: Reject. - Batch on idle GPUs: send batch requests only to workers under 70% KV-cache usage.
- Model aliasing: publish one stable name, such as
standard-model, backed by several models.
Most rules end with minimize: PredictedTTFT. Kinference predicts time-to-first-token for each candidate endpoint, using cache overlap and queue length. Policies live in git and can be validated offline with the kinfctl CLI.
How fast is Kinference in benchmarks?
Buoyant published a benchmark against plain Kubernetes load balancing. Each arm used 3 vLLM 0.31.0 pods, each on 1 L40S GPU. The model was Qwen3.8-27B-FP8. Load came from GuideLLM 0.8.1. The baseline was a ClusterIP Service, where kube-proxy picks a random pod per connection.
Unloaded latency results (median TTFT):
| Workload | Kubernetes Service | Kinference | Change |
|---|---|---|---|
| Control (no shared prefix) | 6.92 s | 6.83 s | No significant difference |
| Shared-prefix | 6.88 s | 0.31 s | about -95% |
| Multiturn | 1.70 s | 0.59 s | about -65% |
Median end-to-end latency fell 45% on shared-prefix and 32% on multiturn. On control traffic, p95 TTFT still dropped from 21.46 s to 12.33 s. Buoyant attributes this to queue-aware balancing.
The capacity test measured goodput: requests per minute meeting a TTFT SLO. Peak goodput was 103.0 vs 14.0 req/min on shared-prefix, about 7.4x. On multiturn it was 82.7 vs 23.8, about 3.5x. The Service baseline never met the SLO at any tested concurrency.
These numbers are self-reported. The baseline is random routing, not another cache-aware router like llm-d or Dynamo. Buoyant also notes its SLOs (8 s and 4 s) suit offline agents, not chat.
How does Kinference compare with llm-d, Dynamo and Production Stack?
| Feature | Kinference | llm-d | NVIDIA Dynamo | vLLM Production Stack |
|---|---|---|---|---|
| Backer | Buoyant | CNCF sandbox (Red Hat, Google Cloud, IBM, CoreWeave, NVIDIA) | NVIDIA | vLLM project |
| License | Apache 2.0 | Apache 2.0 | Apache 2.0 | Apache 2.0 |
| Maturity | v0.1.0-alpha.7 | v0.7 (May 2026) | 1.x (1.5.1 containers) | Reference stack |
| Engines | vLLM (SGLang, TensorRT-LLM planned) | vLLM, SGLang | vLLM, SGLang, TensorRT-LLM | vLLM |
| KV-cache-aware routing | Yes, predicted TTFT | Yes, prefix-cache and predicted latency | Yes, KV-aware router | Session-based; prefix-aware listed as WIP |
| Declarative routing policy CRD | Yes (InferencePolicy) | Not documented in README | Not documented in README | Not documented in README |
| Burst to external providers | Yes (InferenceProvider) | Not documented in README | Not documented in README | Not document |
ToyBlocks: A controlled world for robot learning and evaluation

Give everyone on your team lifetime access to dozens of AI models for a one-time price of $69.97
TL;DR: Give up to 20 people GPT, Claude, and more with a 1min.AI lifetime subscription on sale for $69.97 (reg. $540).
Paying for an AI account for one person is manageable. Paying for your whole team is not, especially if you need more than basic models. If you’d rather pay one time for everyone, try a 1min.AI Advanced Business Plan lifetime subscription. A single account holds up to 20 members, gives each one access to dozens of major AI models, and only costs $69.97 (reg. $540) right now.
Everyone on the account gets the same flagship models, including GPT-5.5 Pro, Claude 4.6 Sonnet, and Gemini 3.1 Pro, and can switch between them for each task. Member management controls who has access, and sharing tools let people pass drafts back and forth. Writing tools include a blog article generator, rewriter, summarizer, grammar checker, and brand voice generator.
Your team splits 4 million credits a month however it likes. That much is enough for roughly 1.1 million words, 1,186 images, or 37 videos. Daily visits to the web app add 15,000 free credits each, up to 450,000 more a month. Beyond writing, 1min.AI can edit images, chat with PDFs, translate documents, and turn text into speech, with apps for Windows, Mac, Chrome, iPhone, iPad, and Android. AI output still needs a person to review it before it goes out.
Pay once for AI tools your whole team can use.
Through November 8, you can get a 1min.AI Advanced Business Plan lifetime subscription on sale for $69.97.

1min.AI Advanced Business Plan Lifetime SubscriptionSee Deal
StackSocial prices subject to change.